保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Science
How To Perform Feature Selection for Regression Problems
In this article I explain what feature selection is and how to perform it before training a regression model in Python.
Serafeim Loukas, PhD
August 8, 20206 min read
1. Introduction
What is feature selection ?
Feature selection is the procedure of selecting a subset (some out of all available) of the input variables that are most relevant to the target variable (that we wish to predict).
Target variable here **** refers to the** variable that we wish to predic**t.
For this article we will assume that we only have numerical input variables and a numerical target for regression predictive modeling. Assuming that, we can easily estimate the relationship between each input variable and the target variable. This relationship can be established by calculating a metric such as the correlation value for example.
- NEW : After a great deal of hard work and staying behind the scenes for quite a while, we're excited to now offer our expertise through a platform, the "Data Science Hub" on Patreon (https://www.patreon.com/TheDataScienceHub). This hub is our way of providing you with bespoke consulting services and comprehensive responses to all your inquiries , ranging from Machine Learning to strategic data analytics planning.
Learn this step by step with the interactive AI and Data Scientist and Machine Learning roadmaps.
2. The main numerical feature selection methods
The 2 most famous feature selection techniques that can be used for numerical input data and a numerical target variable are the following:
- Correlation (Pearson, spearman)
- Mutual Information (MI, normalized MI)
Correlation is a measure of how two variables change together. The most widely used correlation measure is the Pearson's correlation that assumes a Gaussian distribution of each variable and detects linear relationship between numerical variables.
This is done in 2 steps:
- The correlation between each regressor and the target is computed, that is, ((X[:, i] - mean(X[:, i])) (y - mean_y)) / (std(X[:, i]) std(y)).
- It is converted to an F score then to a p-value.
Mutual information originates from the field of information theory. The idea is that the information gain (typically used in the construction of decision trees) is applied in order to perform the feature selection. Mutual information is calculated between two variables and measures as the reduction in uncertainty for one variable given a known value of the other variable.
3. The dataset
We will use the boston house -prices dataset. This dataset contains information collected by the U.S Census Service concerning housing in the area of Boston Mass. The dataset consists of the following variables:
- CRIM - per capita crime rate by town
- ZN - proportion of residential land zoned for lots over 25,000 sq.ft.
- INDUS - proportion of non-retail business acres per town.
- CHAS - Charles River dummy variable (1 if tract bounds river; 0 otherwise)
- NOX - nitric oxides concentration (parts per 10 million)
- RM - average number of rooms per dwelling
- AGE - proportion of owner-occupied units built prior to 1940
- DIS - weighted distances to five Boston employment centres
- RAD - index of accessibility to radial highways
- TAX - full-value property-tax rate per $10,000
- PTRATIO - pupil-teacher ratio by town
- B - 1000(Bk - 0.63)² where Bk is the proportion of blacks by town
- LSTAT - % lower status of the population
- MEDV - Median value of owner-occupied homes in $1000's
4. Python Code & Working Example
Let's load and split the dataset into training (70%) and test (30%) sets.
text
from sklearn.datasets import load_boston
from sklearn.model_selection import train_test_split
from sklearn.feature_selection import SelectKBest
from sklearn.feature_selection import f_regression
import matplotlib.pyplot as plt
from sklearn.feature_selection import mutual_info_regression
text
# load the data
X, y = load_boston(return_X_y=True)
text
# split into train and test sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.30, random_state=0)
We will use the well known scikit-learn machine library.
Case 1: Feature selection using the Correlation metric
For the correlation statistic we will use the f_regression() function. This function can be used in a feature selection strategy, such as selecting the top k most relevant features (largest values) via the SelectKBest class.
text
# feature selection
f_selector = SelectKBest(score_func=f_regression, k='all')
text
# learn relationship from training data
f_selector.fit(X_train, y_train)
text
# transform train input data
X_train_fs = f_selector.transform(X_train)
text
# transform test input data
X_test_fs = f_selector.transform(X_test)
text
# Plot the scores for the features
plt.bar([i for i in range(len(f_selector.scores_))], f_selector.scores_)
text
plt.xlabel("feature index")
plt.ylabel("F-value (transformed from the correlation values)")
plt.show()
Reminder : For the correlation statistic case:
- The correlation between each regressor and the target is computed, that is, ((X[:, i] - mean(X[:, i])) (y - mean_y)) / (std(X[:, i]) std(y)).
- It is converted to an F score then to a p-value.
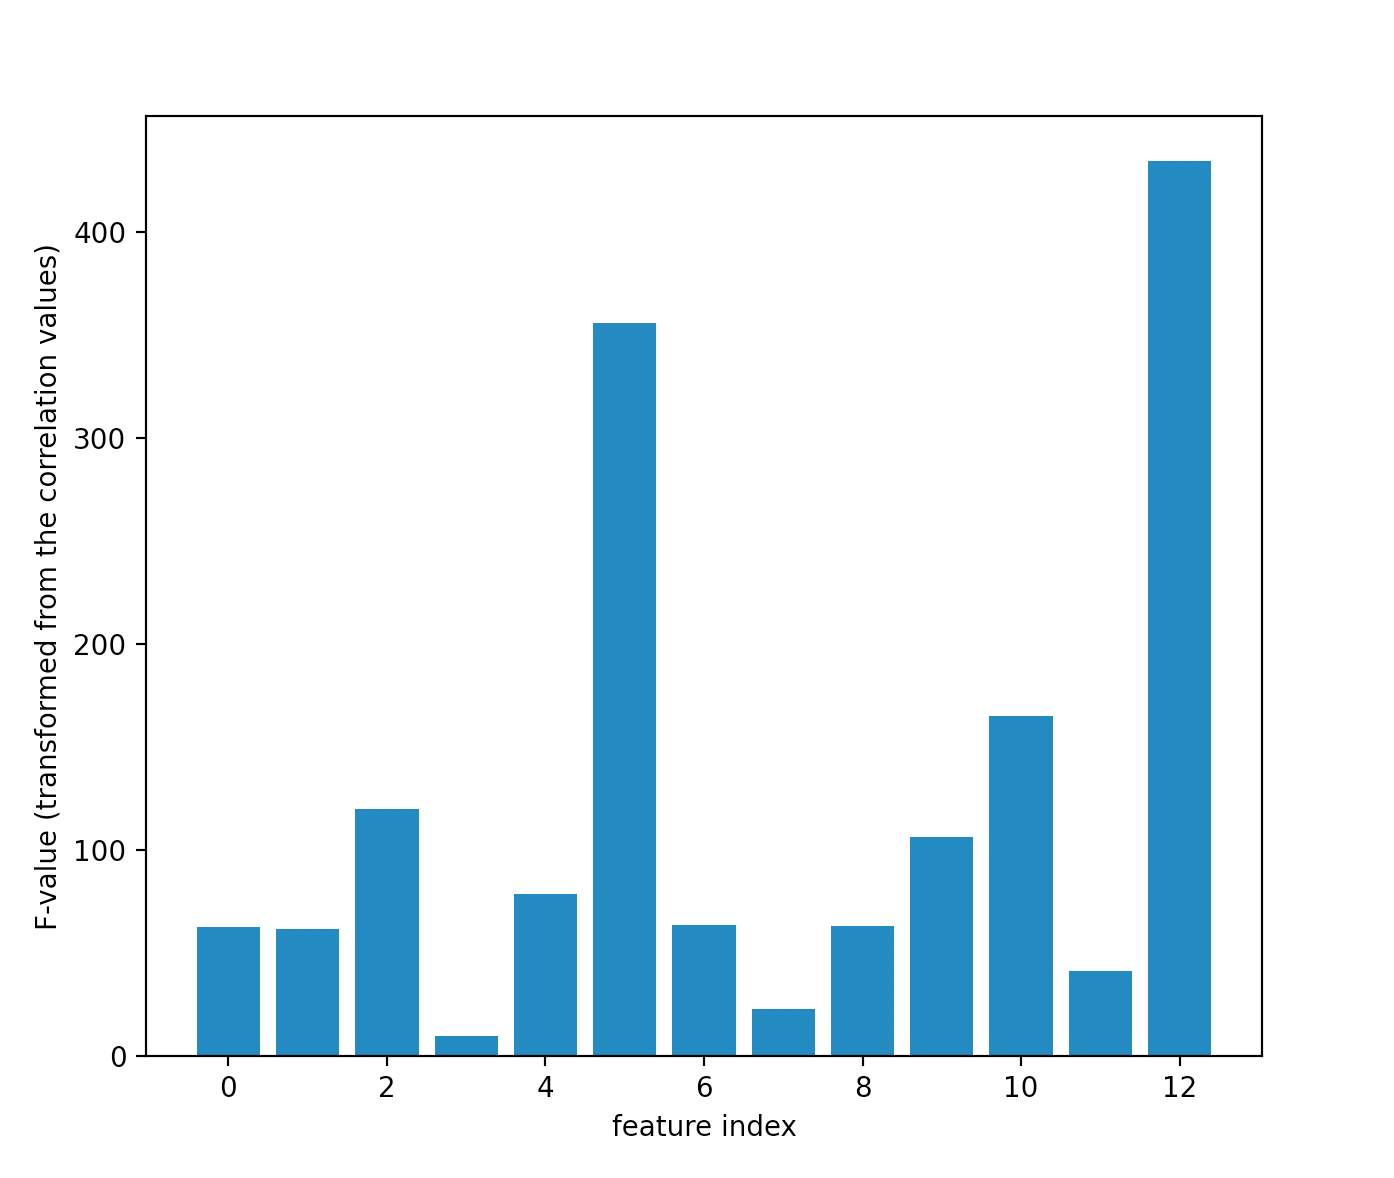 Feature Importance plot
The plot above shows that feature 6 and 13 are more important than the other features. The y-axis represents the F-values that were estimated from the correlation values.
Case 2: Feature selection using the Mutual Information metric
The scikit-learn machine learning library provides an implementation of mutual information for feature selection with numeric input and output variables via the mutual_info_regression() function.
text
# feature selection
f_selector = SelectKBest(score_func=mutual_info_regression, k='all')
text
# learn relationship from training data
f_selector.fit(X_train, y_train)
text
# transform train input data
X_train_fs = f_selector.transform(X_train)
text
# transform test input data
X_test_fs = f_selector.transform(X_test)
text
# Plot the scores for the features
plt.bar([i for i in range(len(f_selector.scores_))], f_selector.scores_)
text
plt.xlabel("feature index")
plt.ylabel("Estimated MI value")
plt.show()
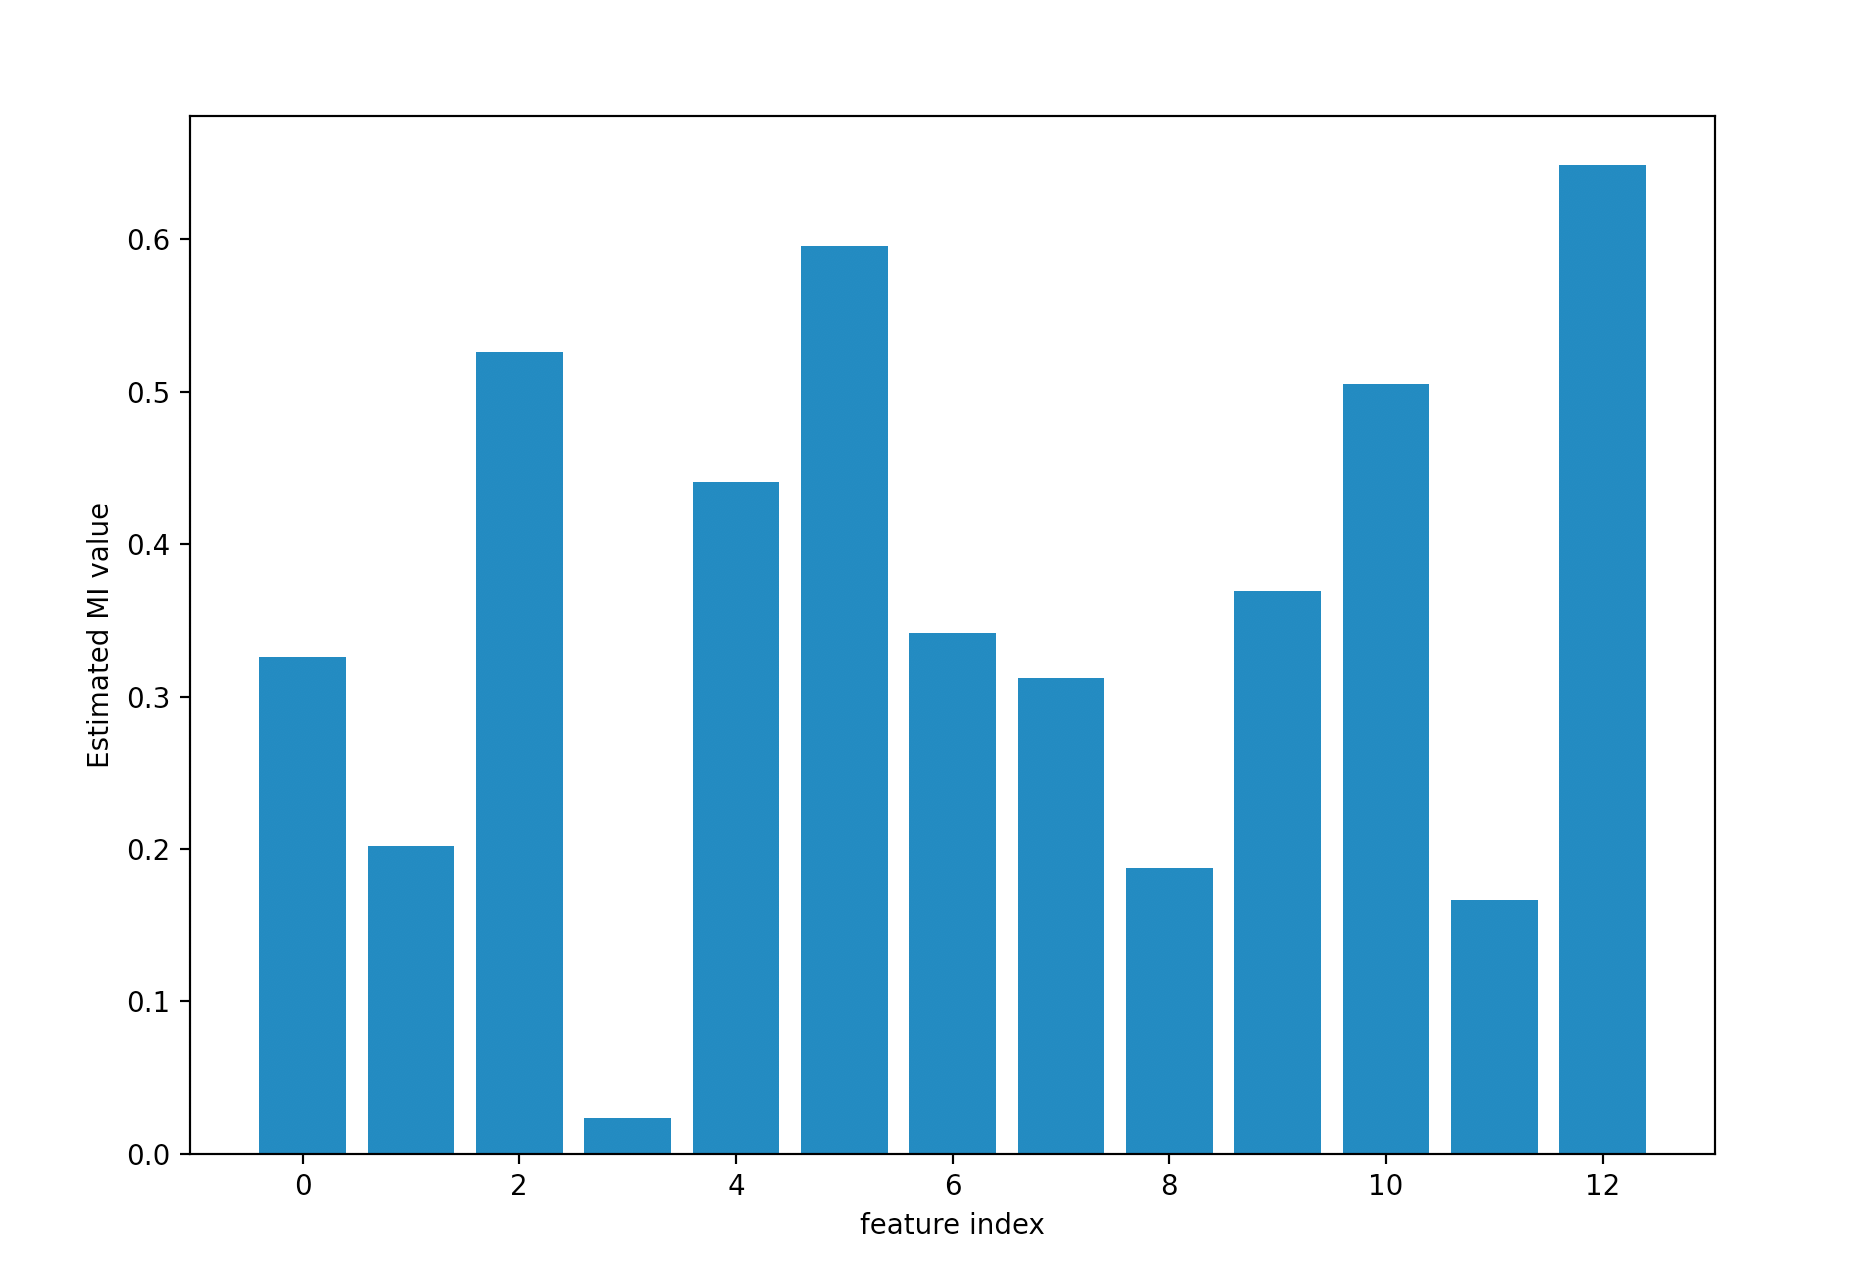 Feature Importance plot
The y-axis represents the estimated mutual information between each feature and the target variable. Compared to the correlation feature selection method we can clearly see many more features scored as being relevant. This may be because of the statistical noise that might exists in the dataset.
5. Conclusion
In this article I have provided two ways in order to perform feature selection. Feature selection is the procedure of selecting a subset (some out of all available) of the input variables that are most relevant to the target variable. Target variable here **** refers to the** variable that we wish to predic**t.
Using either the Correlation metric or the Mutual Information metric , we can easily estimate the relationship between each input variable and the target variable.
Correlation vs Mutual Information: Compared to the correlation feature selection method we can clearly see many more features scored as being relevant. This may be because of the statistical noise that might exists in the dataset.
You might also like:
LSTM Time-Series Forecasting: Predicting Stock Prices Using An LSTM Model
Time-Series Forecasting: Predicting Stock Prices Using An ARIMA Model
Stay tuned & support this effort
If you liked and found this article useful, follow me to be able to see all my new posts.
Questions? Post them as a comment and I will reply as soon as possible.
Latest posts
The Best FREE Data Science Resources: FREE Books & Online Courses
ROC Curve Explained using a COVID-19 hypothetical example: Binary & Multi-Class Classification...
Support Vector Machines (SVM) clearly explained: A python tutorial for classification problems...
PCA clearly explained - How, when, why to use it and feature importance: A guide in Python
Everything you need to know about Min-Max normalization in Python
How Scikit-Learn's StandardScaler works
Get in touch with me
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Serafeim Loukas, PhD
Data ScienceFeature SelectionMachine LearningPythonRegression
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
An overview of the production grade ways to iterate on prompts with Hamilton.
Stefan Krawczyk
September 13, 202314 min read
Machine Learning
The stories that resonated the most with our community in the past month
TDS Editors
October 3, 20243 min read
Artificial Intelligence
This is the final project of Term 1 of the Udacity Self-Driving Car Engineer Nanodegree. You can find all code related to this project on...
Eddie Forson
October 25, 201711 min read
Machine Learning
Why econometrics should be part of your skills
Alexandre Warembourg
September 8, 20197 min read
Machine Learning
Your daily dose of data science
TDS Editors
February 24, 20211 min read
Machine Learning
Master the basics before taking on computer vision projects
Aashish Nair
January 10, 20225 min read
Machine Learning
Starting from using matrix and vector for data representation
Destin Gong
December 30, 20228 min read
Switch from Pandas to Polars and forget about indexes
Carl Kadie
January 6, 20236 min read
Machine Learning
Examine augmentations right in your browser
Pascal Janetzky
June 13, 20213 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close