保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Artificial Intelligence
Courage to Learn ML: Tackling Vanishing and Exploding Gradients (Part 1)
Melting Away DNN's Gradient Challenges: A Scoop of Solutions and Insights
Amy Ma
February 5, 202414 min read
 In the last installment of the 'Courage to Learn ML' series, our learner and mentor focus on learning two essential theories of DNN training, gradient descent and backpropagation.
Their journey began with a look at how gradient descent is pivotal in minimizing the loss function. Curious about the complexities of computing gradients in deep neural networks across multiple hidden layers, the learner then turned to backpropagation. By decompose the backpropagation into 3 components, the learner learned about backpropagation and its use of the chain rule to calculate gradients efficiently across these layers. During this Q&A session, the learner questioned the importance of understanding these complex processes in an era of automated advanced deep learning frameworks, such as PyTorch and Tensorflow.
This is the first post of our deep dive into Deep Learning, guided by the interactions between a learner and a mentor. To keep things digestible, I've decided to break down my DNN series into more manageable pieces. This way, I can explore each concept thoroughly without overwhelming you.
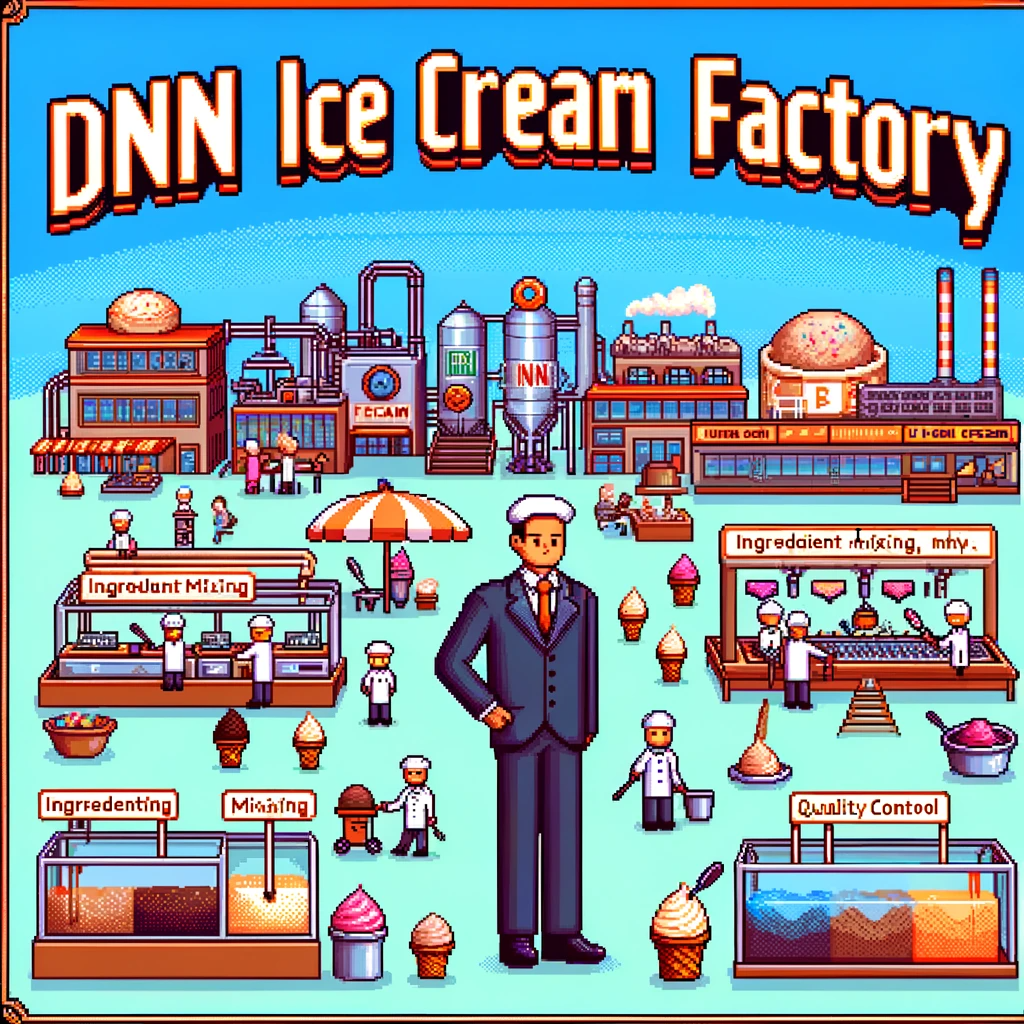
Today's discussion promises to address this question by focusing on the challenge of unstable gradients, a major factor making DNN training difficult. We'll explore various strategies to address this issue, using an analogy of running a miniature ice cream factory, aptly named DNN (short for Delicious Nutritious Nibbles), to illustrate effective solutions. In subsequent posts, the mentor will talk about each solution in detail, showing how these solutions are implemented within the PyTorch framework.
Learn this step by step with the interactive AI Engineer, AI and Data Scientist and Machine Learning roadmaps.
Diving into the world of DNNs, we're going to use a unique analogy that I've been fond of - envisioning DNN as an ice cream factory. Curiously, I once asked ChatGPT what 'DNN' might stand for in the realm of ice cream, and after 5 minutes of thinking, it suggested "Delicious Nutritious Nibbles." I loved it! So, I've decided to embrace this playful analogy to help demystify those daunting DNN concepts with a dash of sweetness and fun. As we delve into the depths of deep learning, imagine we're managers running a mini ice cream factory called DNN. Who knows, maybe one day, DNN ice cream will become a reality. It would be a real treat for ML/DL enthusiasts to enjoy!
Let's begin this journey by learning the basic structure of using PyTorch to train a NN. Always, let's rephrase it to a fundamental question -
Can you illustrate the backpropgation and gradient descent in PyTorch?
The basic code of training a NN in PyTorch helps understand the relationship and role of gradient descent and backrpropgation.
text
import torch
# Define the model
model = CustomizedModel()
# Define the loss function
loss_fn = torch.nn.L1Loss()
# Define optimizer
optimizer = torch.optim.SGD(params = model.parameters(),
lr = 0.01, momentum = 0.9)
epoches = 10
for epoch in range(epoches):
# Step 1: Setting the Model to Training Mode:
model.train()
# Step 2: Forward Pass - Making Predictions
y_pred = model(X_train)
# Step 3: Calculating the Loss
loss = loss_fn(y_pred, y_train)
# Step 4: Backpropagation - Calculating Gradients
optimizer.zero_grad() # clears old gradients
loss.backward() # performs backpropagation to compute the gradients of the loss w.r.t model parameters
# Step 5: Gradient Descent - Updating Parameters
optimizer.step()
In this code snippet, loss.backward() is utilized to execute backpropagation. This process begins from the loss, not the optimizer, because backpropagation's purpose is to compute the gradients of the loss with respect to each parameter. Once these gradients are determined, the optimizer uses these gradients to update each parameter with a gradient descent step. The optimizer.step() method, as I view it, is appropriately named 'step' to indicate a single update of all the model parameters. This can be thought of as taking a step along the loss surface during the optimization process.
For a better understanding of what "a step along the loss surface" means, I strongly suggest reading my post on gradient descent. In it, I use a video game analogy to vividly demonstrate how we navigate the loss surface. Also, you will love the title picture draw by ChatGPT.
Can you explain the concepts of vanishing and exploding gradients in neural networks? What are the primary causes of these issues?
Computing gradients in a deep neural network (DNN) is complex, primarily due to the extensive number of parameters spread across many hidden layers. Backpropagation simplified this calculation by computing the gradient of the loss regard to each parameter, applying the chain rule. This process, due to the chain rule, involves derivatives calculated through successive multiplications , where values can drastically change. It results gradients that might become extremely small or large as we move to the lower layers (layers that are close to the input layer). It's akin to tracing back through a series of intricate water filters to enhance water quality, layer by layer. The early layers' influence is hard to evaluate as it gets altered by subsequent layers. Such unstable gradients introduce significant challenges when training deep neural networks, leading to the phenomena known as "vanishing" (extremely small gradients) and "exploding" (excessively large gradients) gradient problems. This instability makes DNN training challenging and restricts the architecture to fewer layers. In other words, without addressing this issue, DNNs cannot achieve the desired depth.
If you wonder about why backpropagation involves successive multiplications, I suggest checking out my earlier article on backpropagation. In the post, I explained the calculations by breaking it down into 3 components and use code examples to make it easier to understand. I also explored why researchers generally favor deeper and narrower DNNs over wider and shallower ones.
I get that vanishing gradients can be an issue because the lower layers' parameters barely update, making learning difficult with such small gradients. But why are exploding gradients problematic too? Wouldn't they provide substantial updates for the later layers?
You're correct in noting that large gradients can lead to significant updates in parameters. However, this isn't always the case and large update is not always beneficial. Let me explain why exploding gradients prevent effective training in deep neural networks:
- Exploding gradients doesn't always means large updates, it can results in numerical instability and overflow. Exploding gradients don't always lead to large, meaningful updates. When training with computers, excessively large gradients can cause numerical overflow. For example, consider a network where the gradient at a certain layer is 10⁷, a large but feasible number. During backpropagation, this value, multiplied by other large values due to the chain rule, can exceed the limits of standard floating-point representation, resulting in overflow and the gradients becoming
NaN (presents Not a Number). When updating parameters using parameter = parameter - learning_rate * gradient, if the gradient is NaN, the parameters also become NaN. This corrupts the forward pass of the network, making it incapable of generate useful predictions.
- Large updates aren't always beneficial. Large gradient values can lead to dramatic changes in parameters, causing oscillations and instability in the parameter updates. This can result in longer training times, difficulty in converging, and the potential to overshoot the global minimal of the loss function. Coupled with a relatively larger learning rate, these oscillations can significantly slow down the training process.
- Large gradients aren't necessarily informative. It's a misunderstanding that larger gradients are always more informative and lead to meaningful updates. In fact, if gradients become excessively large, they can overshadow the contributions of smaller, yet more meaningful, gradients. Imagine navigating the loss landscape, where large gradients, often influenced by outliers or noise, can misguide us in choosing our next step. Additionally, large gradients may benefit some layers but not others, resulting in imbalanced learning. For instance, large gradients in upper layers might lead to extreme small derivatives in layers using sigmoid activation functions. This can result in an imbalanced learning process within the network.
Why is it that the oscillation in weight updates caused by exploding gradients turns out to be harmful? I understand that Stochastic Gradient Descent (SGD) with small batch sizes also leads to oscillation, but why doesn't that cause similar issues?
You're right in noting that Stochastic Gradient Descent (SGD) with small batch sizes introduces some instability in the weight updates. However, this type of oscillation is both controllable and relatively minor, primarily because it originates from the data itself. Utilizing a small subset of training data typically won't deviate too far from the behavior of the full dataset, meaning the noise is manageable. Additionally, this manageable level of noise can enhance the model's generalizability by improving its insensitivity to minor data variations. Essentially, while navigating the loss surface, SGD might make decisions that slightly deviate from the most optimal path to the global minimum. However, these suboptimal steps aren't drastically far from the ideal ones. This approach reduces the likelihood of getting stuck in plateaus and saddle points, enabling movement away from these areas towards potentially better local minima or even the global minimum in the complex landscape of DNN.
On the other hand, the oscillation caused by exploding gradients is of a different behavior. Due to exploding gradients, we might make substantially large updates to parameters, leading to significant movements on the loss surface. These updates can be so large that they catapult the model to a position quite distant from where it was initially, or even farther from the global minimum. Unlike with SGD, where the steps are small and keep us close to our original position, exploding gradients can negate our previous progress, forcing us to redo all the hard work to find the global minimum.
To visualize it, think of it like playing an RPG video game, where we use magic (akin to an optimizer) to guide our movements towards the treasure located at the lowest point of the map. With the magic of SGD, we might stray from the best route, but we generally head towards the treasure. Thus, moving fast enough, we'll likely reach and get the treasure. But with exploding gradients, it's like being thrown randomly to a new, unfamiliar place on the map, requiring us to restart our exploration. In the worst-case scenario, we might end up at the farthest point from the treasure, making it nearly impossible to reach our goal with limited time and computational sources.
So how do we know whether a gradient is too large or too small? How'd we detect those problems?
Detecting unstable gradients is important for ensuring the effective learning of different layers at a consistent pace. If you suspect your model is suffering exploding or vanishing gradients, consider those methods to effective identify those problems:
- Tracking training loss. Observing the training loss across epochs is a straightforward and valuable method. A sudden spike in loss or its transition to NaN might indicate that some weights have been updated too aggressively, potentially due to large gradients causing numerical overflow. This scenario often points to exploding gradients. Conversely, a plateau in the loss graph or minuscule decreases over several epochs could be a sign of vanishing gradients, suggesting that the weights are barely updating due to very small gradients. However, interpreting these signs isn't always straightforward and requires ongoing evaluation to determine whether the training process is progress or not.
- Monitoring gradient directly. A more direct approach involves keeping an eye on the gradients themselves. However, inspecting each gradient individually can be impractical in large, deep networks, calculating the gradient norm offers a simplified yet effective alternative. The norm, which can be computed for all layers collectively or individually, focuses on the magnitude of the gradients, providing a single metric for comparison over time. This method is particularly useful for identifying exploding gradients, as excessively large values will always stand out. For vanishing gradients, small norms might hint at an issue, but they're less definitive. Visualizing gradient distributions through histograms can also highlight outliers and extreme values, and can be easily captured.
- Monitoring weight updates and activation output. Since unstable gradients directly impact weight updates, tracking changes in weights is a logical step. Sudden significant large changes or shifts to NaN in weights indicate exploding gradients. If weights remain static over time, vanishing gradients could be the reason. Similarly, analyzing the activation outputs of each layer can offer additional insights into how weights and gradients are behaving.
For practical implementation, TensorBoard stands out as a popular tool for visualizing training progress. It supports both TensorFlow and PyTorch and allows for detailed tracking of losses, gradients and more. It can be a great tool to identify gradient-related issues.
Are you suggesting that, in DNNs, we aim for all layers to learn at an same pace?
We don't actually expect every layer in a DNN to learn at the same rate. Our goal is to have a consistent and balanced weight update across the entire network. Vanishing gradients, for instance, pose a problem because they lead to the upper layers (those closer to the output) learning more quickly and converging earlier due to larger gradients, while the lower layers (those closer to the input) lag behind with almost random weight adjustments due to small gradients. This can result in the network converging to a less-than-ideal local minimum, with only the upper layers properly trained and the lower layers nearly unchanged. In general, we want make sure each layer's updating rate align with its impact on the final model prediction. The problem with both vanishing and exploding gradients is that they break this balance, and unstable gradients cause layers get updated disproportionately. It's similar to trying to walk left by only turning your body without moving your feet, you won't get very far.
The objective, then, is to achieve stable and uniform weight updates across the network throughout the network. This is where adaptive learning rate optimizers come into play, offering significant benefits. They dynamically adjust the learning rate based on historical gradients, aiding in more efficient loss reduction.
Practically, frameworks like PyTorch and TensorFlow allow for the specification of different learning rates for each layer. This capability is particularly beneficial when fine-tuning pretrained models or during transfer learning. It allows customized learning rate adjustments per layer to suit specific requirements. Here are some useful discussion on Stack Overflow and PyTorch forums.
How do we generally address the issue of unstable gradients when training DNNs?
Imagine our DNN model as a mini-ice cream factory, where ingredients flow through various departments to produce ice cream that's then rated by customers at the end of the production line. Each department in this mini-factory represents a layer in the DNN, and the customer feedback on the ice cream's taste represents the loss gradient used to improve the recipe through backpropagation.
However, our factory faces a challenge: the customers feedback isn't being effectively communicated back through the departments. Some departments overreact to the feedback, making drastic changes (akin to exploding gradients), while others overlooked, barely making any adjustments (akin to vanishing gradients).
As the factory managers, our goal is to ensure that feedback is processed appropriately at each stage to consistently produce ice cream that delights our customers. Here are the strategies we can employ:
- Set up factory properly (Weight Initialization). The first step is ensuring the factory operates smoothly and produces quality ice cream. Setting up the factory correctly is quick important. We need to ensure that the initial setting of our production line (akin to weights in a DNN) is set just right, not too strong nor too weak, to produce a base flavor that meets general customer preference. This is like choosing proper weight initialization in DNNs to avoid excessively small or large gradients, ensuring a stable flow of adjustments based on feedback.
- Quality control at the beginning and during production (Batch Normalization). As the ingredients mix and progress through the production line (layers in a DNN), we'd introduce quality checkpoints to standardize the mix at various stages. This ensures that each batch of semi-finished product remains consistent, preventing any layer from producing ice creams that are too varied, which could make our customer feedback become misleading and make our adjustment less effective. This mirrors batch normalization in DNNs, where outputs of layers are normalized to maintain a stable distribution of activations, aiding in a smoother gradient flow.
- Adjust feedback system to avoid overreactions (Gradient Clipping). When customer feedback arrives, it's crucial that no department overreacts and makes drastic changes based on one batch of feedback, which could throw off the entire production line. By implementing a system where extreme feedback (either too positive or too negative) is moderated or clipped, you ensure that changes are gradual and controlled, akin to gradient clipping in DNNs, which prevents gradients from exploding. The similar idea is using some special network architecture like ResNet with skip connections can also mitigate vanishing gradients.
- Optimizing Workflow and Feedback Paths (Activation Functions). In our DNN ice cream factory, some departments act as messengers, shuttling semi-finished products forward and customer feedback backward. They're the key for ensuring the final product turns out correctly. If they don't transfer the intermediate products accurately, the end result could be a batch of ice cream that misses the mark. Similarly, the way they handle customer feedback and pass between departments is also important. If feedbacks are overlooked, important information might be missed, while overly amplified feedback can cause overreactions and dramatic changes in the factory. So, choosing the right communicators (activation functions) ensure the smooth transfer of both products and feedback and keep the production line efficient and responsive. Just like in our factory, choosing the right activation functions in a DNN ensures that we get accurate predictions and maintain stable gradients, avoiding the extremes of vanishing or exploding during backpropagation and ensure effective updates for different parameters.
- Tailor feedback response intensity by department (Adaptive Learning Rates). Finally, not all departments should react to feedback with the same intensity. For example, the flavor department might need to be more sensitive to taste feedback than the packaging department. By adjusting how much each department learns from feedback (akin to setting adaptive learning rates in different layers of a DNN), you can fine-tune the factory's response to customer preferences, ensuring more targeted and efficient improvements.
Next time, I'll cover the topic of activation functions and weight initialization methods in detail. Rather than simply running through the formulas and listing their pros and cons, I plan to share the essential questions that have shaped my understanding - questions that frequently go unasked but are vital for grasping why each method and function is shaped the way it is. These discussions might even empower us to innovate our own functions and weight initialization methods.
For those keen to journey with me through this series, feel free to follow along. Your engagement - through claps, comments, and follows - fuels this endeavor. It's not just encouragement; it's the very heartbeat of this educational series. As I continue to refine my grasp on these topics, I often revisit and update my past posts, enriching them with new insights. So, stay tuned for more!
(Unless otherwise noted, all images are by the author)
Other posts in this series:
If you liked the article, you can find me on LinkedIn .
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Amy Ma
Deep DivesArtificial IntelligenceCourage To Learn MlData ScienceMachine Learning
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Machine Learning
Applying a Machine Learning model to actively test and classify transactions as valid or not
Thales Meier
January 5, 20227 min read
Feminism
Data in data science are abstracted for analysis. This raises a problem if they become disconnected from reality. Could diversity help?
Ismael Kherroubi Garcia
April 10, 202116 min read
Data Science
A simple way to segment your customer profile
Chi Nguyen
March 2, 20214 min read
Artificial Intelligence
A C++ implementation
Filippo Valle
February 9, 20216 min read
NLP
Using pretrained transformer language models and part of speech for state-of-the-art keyphrase extraction
Tim Schopf
October 19, 20226 min read
Programming
A short and simple guide on how to pip install your custom made package
Mike Huls
July 18, 20215 min read
Data Science
P-values below a certain threshold are often used as a method to select relevant features. Advice below suggests how to use them correctly.
Igor Šegota
May 5, 20239 min read
Artificial Intelligence
Understanding how DeiT works via knowledge distillation —and how to implement it with PyTorch
Muhammad Ardi Putra
June 2, 202520 min read
Artificial Intelligence
With this method, you'll never have to manually cluster survey answers ever again
James Asher
December 1, 20215 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close