保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Machine Learning
Optimizing Your Strategies with Approaches Beyond A/B Testing
An in-depth explanation in layman on optimising classic A/B testing: Epsilon-greedy, Thompson Sampling, Contextual Bandits and more
John Leung
July 24, 20237 min read
An in-depth explanation in layman on optimizing classic A/B testing: Epsilon-greedy, Thompson Sampling, Contextual Bandits, and more
In the world of digital marketing, the competition is fierce. Every company wants to create a marketing strategy with the highest value – increasing customer retention, enhancing customer satisfaction, or archiving other business objectives. However, there is no perfect marketing strategy that fits all customers. Instead, we can strive to figure out an improved version of our marketing strategy. That's why A/B testing comes into play.
In a nutshell, A/B testing is an experiment that involves randomly splitting your audiences into two groups, and comparing two versions of a strategy to see which one performs better. It is the traditional and statistically proven method for making data-driven decisions.
Learn this step by step with the interactive Machine Learning roadmap.
When to use A/B Testing
Imagine you and your partner have been running a toy e-shop for a while. One day, your partner raises concerns about the background color of the landing page. He believes that the current color does not effectively drive the conversion rate of visitors (i.e. % of visitors purchasing items).
- Currently in use (Strategy A): Orange
- Your partner's suggestion (Strategy B): Yellow
You immediately identify that A/B testing is a good experimental design. Because this is relatively straightforward to determine the "winner" or "loser" based on the measurement results (i.e. the conversion rate of each strategy), showcasing which version of the website visitors find most engaging.
The following figure demonstrates the example situation.
What's the problem with A/B Testing
The result of A/B testing confirms that website visitors on the yellow landing page (strategy B) have a higher conversion rate in the e-shop. As a result, you decide to roll out the yellow landing page instead to the entire visitor population. However, you soon realize that this testing approach incurs a cost: With the strictly defined start and endpoint of the A/B testing, half of the traffic is allocated to the poorer strategy A for the entire period.
The cost difference between choosing the poorer strategy A and the most ideal option (strategy B in this case) can be represented in terms of regret.
This A/B testing can be summarised with the following characteristics:
- It emphasizes the value of exploration: gathering sufficient information to determine whether strategy A or B is optimal throughout the whole test.
- It overrides the value of exploitation : not striving to achieve a higher conversion rate by reducing traffic to strategy A during the test, even with the collected information that strategy B appears to perform better.
After hearing the result of the A/B testing, your partner gets excited about his success in suggesting a better strategy. He is interested to know further if other background colors, including green, red, and purple, can drive the conversion rate. You can already imagine that the scenario would get worse using the current testing method, as the regret of A/B testing will likely be even higher when more strategies are involved in the test.
Go beyond A/B Testing
We welcome new strategies, as they may bring us closer to our business goals. However, we usually doubt if we waste a significant amount of our limited time and resources on poor strategies during the test.
In classic A/B testing, we remain in the exploration mode, disregarding whether a strategy seems to be outperforming or underperforming. What if we took the opposite approach and solely focused on exploitation? Here's how it would work: The strategy that seems to be optimal is quickly chosen by our guess when only a few visitors make purchases in the e-shop, and then all visitors are directed to this strategy for the remaining time of the test. This approach carries a high level of risk since the sample size is likely not representative enough to draw the correct conclusions based on the performance of strategies.
Now, we understand neither sole exploration nor sole exploitation are good ideas. We need to balance between exploration and exploitation. Besides, it is unarguably that we should continuously allocate more traffic to the current optimal strategy during the test.
In other words, we prefer taking actions that maximize the estimated reward in the midst.
Epsilon-Greedy
The Epsilon-Greedy algorithm works with similar ideas by randomly selecting between exploration and exploitation for each visitor's traffic. Let's say we want to have 90% of the traffic focus on exploitation and 10% on exploration. The algorithm follows these steps:
When a visitor arrives at the e-shop,
- Identify the current optimal strategy
- There is a 90% chance of exploitation: direct the visitor to the current optimal strategy. Alternatively, there is a 10% chance of exploration: direct the visitor to one of the remaining strategies.
Over time, we greedily choose among different strategies for exploitation and gradually make a consistent decision of the currently optimal strategy. However, we don't discard the opportunity to experiment with other strategies, even coming close to the final stage of testing. By maximizing the estimated reward in each action, the overall cost of regret with this approach is likely to be smaller than that of classic A/B testing.
Thompson Sampling
Epsilon-Greedy seems promising, but can it be further improved? Let's consider two scenarios:
(A) When only a few visitors have arrived, can we confidently identify the optimal strategy for the entire population?
Probably not. We are concerned that these samples might be outliers. Since there is still high uncertainty, exploration remains necessary.
(B) When thousands of visitors have arrived or we are in the later stages of the test, do we have greater confidence now?
Most likely, because more samples provide higher statistical power, allowing us to identify the strategy that outperforms others in the real population.
Now, let's refine our approach. To choose between exploration and exploitation based on our confidence level, we can implement Thompson Sampling.
This approach selects a strategy with the highest probability of converting a visitor into a buyer, rather than focusing solely on maximizing expected rewards. Each time a visitor comes to the e-shop, this approach tracks the total number of buyers and non-buyers for each strategy and constructs their respective beta distributions. The advantages are:
- When the sample size is small, even a strategy with a lower conversion rate may be selected (prioritizing exploration).
- As evidence becomes more apparent, the strategy with a higher conversion rate will be chosen most of the time (prioritizing exploitation).
Contextual Bandits
Thompson Sampling is an effective approach as it dynamically adjusts the balance between exploration and exploitation throughout the test. While it allows us to make informed decisions about which strategy to apply when a customer arrives, these decisions are not personalized for different customer cohorts.
Let's consider two visitors: Peter and Mary. Peter enjoys watching Minions videos with his child every weekend, while Mary has no interest in them. Even in the early stages of the test, we can predict that Peter would prefer visiting the toy e-shop page in yellow (the main color of Minions!) and have a higher likelihood of making a purchase.
This example highlights the importance of considering the visitor's context data. By utilizing Contextual Bandits, we can apply algorithmic decisions more systematically. In a real-life scenario, the context may include historical data about each customer, such as website clicks, past purchases, frequency of opening personalized emails, and even data from their ongoing session, such as recent search queries. The algorithm can then learn to associate different contexts with the strategies that are most likely to lead to conversions for each visitor.
Any More Novel Ideas
We have gone through various approaches, including classic A/B testing, the Epsilon-Greedy algorithm, Thompson Sampling, and Contextual Bandits.
- Classic A/B testing: Involve remaining in the exploration mode.
- Epsilon-Greedy algorithm: Randomly balances between exploration and exploitation.
- Thompson Sampling: Place more emphasis on exploitation as the sample size for each strategy increases
- Contextual Bandits: Provide personalized and optimal strategies based on the context (side information) of the visitors
These approaches have been further refined and discussed in recent research papers. Here are a few examples:
Before you go
If you enjoy this reading, I invite you to **** follow my Medium page. By doing so, you can stay updated with exciting content related to data science, project management, and self-improvement.
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from John Leung
Ab TestingAlgorithmsMachine LearningReinforcement LearningStatistics
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
An In-Depth Exploration: Open vs Closed Source LLMs, Unpacking Llama 2's Unique Features, Mastering the Art of Prompt Engineering, and...
Luís Roque
July 24, 202316 min read
ChatGPT
Canonical and research-proven techniques to adapt large language models to domain specific tasks and the intuition of their effectiveness.
Eileen Pangu
March 20, 20239 min read
Machine Learning
Learn how to set up and configure the environment for writing your first DAG.
Dario Radečić
May 11, 20216 min read
Machine Learning
Lesson 1: Batch Serving. Feature Stores. Feature Engineering Pipelines.
Paul Iusztin
April 28, 202314 min read
Programming
Being a heavy Sci-fi fan myself, I always wondered: how would those spherical wheels from Tron and I-Robot work in real life? And this...
Tyler Kim
April 2, 20218 min read
Machine Learning
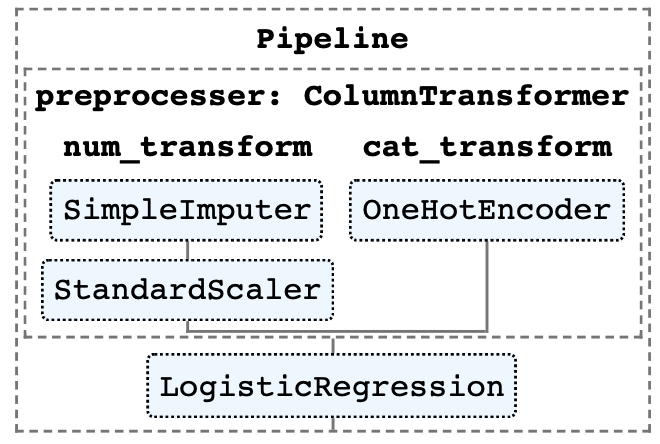
ML Pipeline is an important feature provided by Scikit-Learn and Spark MLlib. It unifies data preprocessing, feature engineering and ML...
Benjamin Wang
January 26, 20217 min read
Machine Learning
7 actionable steps that can benefit your team and the intern
Arunn Thevapalan
September 21, 20217 min read
Machine Learning
In conversation with Rohan Rao: A Data Scientist, Kaggle Grandmaster, and India's reigning Sudoku Champion.
Parul Pandey
July 24, 20198 min read
Computer Vision
A practical exploration focusing on performance and speed
Aimira Baitieva
July 24, 20256 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close