保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Science
How to Catch Data Drift When Every Feature Looks Normal
Detect hidden shifts in feature relationships with adversarial validation and scikit-learn
Benjamin Nweke
September 28, 202610 min read
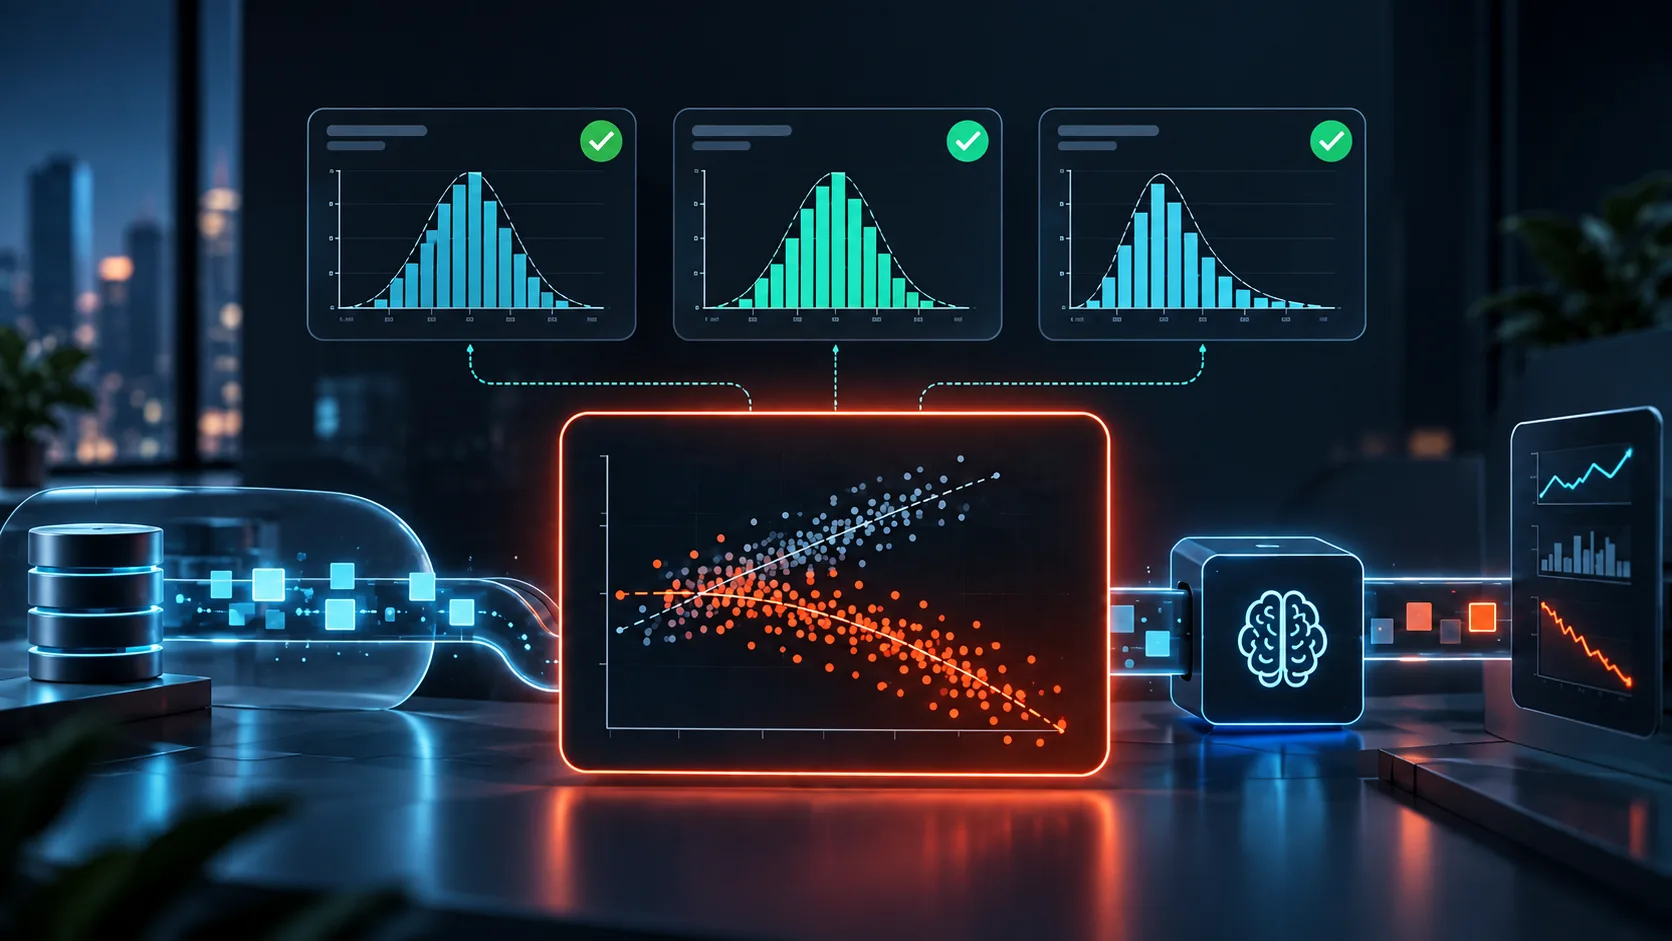 Image by author (Generated with ChatGPT)
A conceptual cover image illustrating hidden data drift in machine learning, where individual feature checks pass but changing relationships between features cause model performance to degrade in production.
A specific kind of quiet follows a good validation run. Numbers on the screen, AUC at 0.91, and everyone nodding along in the morning meeting because, for once, nobody had a reason to ask a follow-up question.
Trust me, it's a good feeling. But It's also one I've learned not to hold on to or trust so much.
The model finally went live that Friday. Nothing dramatic about it, no war room, no late night. Just a deploy that looked exactly like the dozen before it.
By Tuesday, something had gone wrong in a way that took a while to even notice. Precision on flagged cases had quietly gotten worse, and nothing about that showed up as an error.
No crash, no alert, no red line on any dashboard anyone was actually watching.
It just sat there getting worse, until a downstream team got tired of a review queue full of garbage flags and asked why. That's how it got found. Not a system catching itself. A person, annoyed enough to go looking.
And here's the part that still bugs me a little: nothing in the code had changed. The model and the pipeline were exactly what they'd been the day before.
What changed was the world underneath them. A new pricing tier had launched a few days earlier, and customers on it were transacting more often, at lower amounts each time.
I checked one feature at a time, and none of it looked wrong: transaction value sat in a normal range, and so did transaction frequency. It was only when I looked at the two together that the data clearly became something else, and there was no check anywhere in the pipeline built to catch that.
I had already set up drift monitoring before this and I genuinely thought I was covered.
Well, it turned out I wasn't.
The check I had was doing exactly what I'd asked it to do, watching every feature individually, just as I'd built it to, and it would have sat there reporting green through the entire thing.
Which is a strange thing to sit with, honestly. The monitoring wasn't broken. And it wasn't lazy or half-built either. It was just answering a narrower question than the one that actually mattered.
The part that goes wrong quietly
That narrower question is the one most drift monitoring asks, mine included at the time. Has any single feature's distribution shifted? Take this week's values and training-time values, line them up as histograms, and get a number out.
On paper, that's not a bad idea.
It's just an incomplete one.
It works right up until the failure isn't in any single feature, but in how two features move together , and that's a much easier way for real data to break than most write-ups admit.
The pricing tier thing is a clean example because nothing about it looks wrong in isolation. Run PSI on avg_transaction_value alone, fine. Run it on num_transactions_30d alone, also fine. The relationship between the two flipped, and PSI, by design, never looks at two columns at once. It can't. That's not a flaw in the metric so much as a boundary it was never built to cross.
So the question becomes: how do you check a relationship instead of a distribution? Turns out the answer isn't some exotic statistics you have to go learn. It's just asking a model to do the noticing for you.
Let a classifier do the noticing
The trick has a name, adversarial validation, and it makes it sound fancier than it is.
Label your training rows 0, label a fresh batch of production rows 1, and train a classifier to tell them apart.
If the two batches are really drawn from the same distribution, it can't do better than guessing, AUC near 0.5. If it can separate them, something moved, and because the classifier gets every feature at once, it picks up exactly the kind of joint shift a column-by-column check walks straight past.
Here's the setup, with a synthetic dataset so you can run it yourself instead of trusting me on faith:
python
import numpy as np
import pandas as pd
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestClassifier
from sklearn.base import BaseEstimator, TransformerMixin
from sklearn.feature_selection import mutual_info_classif

np.random.seed(42)

n = 5000
df = pd.DataFrame({
    "avg_transaction_value": np.random.normal(150, 40, n),
    "num_transactions_30d": np.random.poisson(12, n),
    "account_age_days": np.random.exponential(400, n),
    "device_risk_score": np.random.beta(2, 5, n),
})

df["target"] = (df["device_risk_score"] * 3 + np.random.normal(0, 0.3, n) > 1.2).astype(int)
# this is the kind of feature that sneaks into real datasets constantly -
# a flag count that got backfilled after the outcome was already known
df["post_hoc_flag_count"] = df["target"] * np.random.poisson(2, n)

X = df.drop(columns=["target"])
y = df["target"]
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42, stratify=y)
Before drift even matters, check for leakage
If you skip this part, you're monitoring drift on a model that was never trustworthy to begin with, so it goes first, even though it's less interesting.
A feature with suspiciously high mutual information against the target is usually a feature that got computed using information that wouldn't have existed yet at prediction time. post_hoc_flag_count above is exactly that, the kind of column that looks predictive because it's cheating.
The first version of this guard I wrote just hard-raised on anything past a threshold, full stop, no exceptions. That lasted about one retrain. device_risk_score kept tripping it, and it's genuinely just a strong feature, not a leaky one.
I'd go back and forth arguing with my own code every single run, until I got annoyed enough to fix it properly instead of just lowering the threshold, which was the lazy fix I almost shipped.
python
import logging

logger = logging.getLogger("pipeline.guards")


class LeakageGuard(BaseEstimator, TransformerMixin):
    """
    Hard-fails on features that look too good to be true. Deliberately
    aggressive - the point is to make leakage annoying to ignore, not to
    be a polite linter.
    """

    def __init__(self, mi_threshold=0.5, corr_threshold=0.85, allowlist=None):
        self.mi_threshold = mi_threshold
        self.corr_threshold = corr_threshold
        # columns already investigated and confirmed strong-not-leaky -
        # without this every retrain re-triggers the same argument
        self.allowlist = allowlist or []

    def fit(self, X, y=None):
        if y is None:
            raise ValueError("LeakageGuard needs y - can't check leakage against nothing")

        numeric_cols = X.select_dtypes(include=np.number).columns.tolist()
        skipped = set(X.columns) - set(numeric_cols)
        if skipped:
            # mutual_info_classif on object columns just gives you garbage
            # scores, not an error, which is worse - loud > silent
            logger.warning("LeakageGuard skipping non-numeric columns: %s", skipped)

        checkable = [c for c in numeric_cols if c not in self.allowlist]
        if not checkable:
            self.mi_scores_, self.corr_scores_ = {}, {}
            return self

        mi = mutual_info_classif(X[checkable], y, random_state=42)
        self.mi_scores_ = dict(zip(checkable, mi))
        self.corr_scores_ = {
            c: abs(np.corrcoef(X[c], y)[0, 1]) for c in checkable
        }

        flagged = [
            c for c in checkable
            if self.mi_scores_[c] > self.mi_threshold or self.corr_scores_[c] > self.corr_threshold
        ]
        if flagged:
            raise ValueError(
                f"Possible leakage in {flagged}. If any of these are legit strong "
                f"predictors, add them to `allowlist` after you've actually checked."
            )
        return self

    def transform(self, X):
        return X
LeakageGuard().fit(X_train, y_train) raises on post_hoc_flag_count immediately, before anything gets trained. Good, that's the whole point. A model trained on that column reports a validation score that looks great and means nothing, because the leakage survives the split intact.
It only shows up once the feature stops existing in production, and by then it's not a code review comment anymore; it's someone asking uncomfortable questions in a retro.
Now the actual drift check
I'll admit that the first draft of this detector didn't handle small batches at all. It just always ran cross-validated AUC, no matter how much data came in.
That's fine against a full day of production traffic, but it falls over against a thin canary batch, where a fold can end up with almost no positive examples and either throws an error or spits back a number that's really just noise wearing a lab coat.
So below a row threshold, it drops to a single train/test split instead. Less rigorous, and I'd rather admit that outright than pretend the tradeoff isn't there.
python
from sklearn.model_selection import cross_val_score
from sklearn.metrics import roc_auc_score


class AdversarialDriftDetector(BaseEstimator, TransformerMixin):
    """
    Trains a classifier to tell reference data apart from new data. If it
    can, something about the joint distribution moved - not necessarily
    any single feature.
    """

    def __init__(self, auc_threshold=0.65, cv_folds=5, min_rows_for_cv=200, random_state=42):
        self.auc_threshold = auc_threshold
        self.cv_folds = cv_folds
        # below this, cross_val_score is more likely to error on a thin
        # fold than tell you anything useful - learned that against a
        # 90-row canary batch that kept failing for no obvious reason
        self.min_rows_for_cv = min_rows_for_cv
        self.random_state = random_state

    def fit(self, X, y=None):
        self.ref_df_ = X.select_dtypes(include=np.number).copy()
        self.ref_cols_ = self.ref_df_.columns.tolist()
        return self

    def check(self, X_new):
        missing = set(self.ref_cols_) - set(X_new.columns)
        if missing:
            raise ValueError(f"X_new is missing columns the detector was fit on: {missing}")

        new_df = X_new[self.ref_cols_].copy()
        if new_df.isna().any().any():
            # don't silently drop rows here - a batch that's suddenly full
            # of nulls is itself a drift signal worth knowing about
            logger.warning(
                "check() got %d rows with NaNs, filling with column medians",
                new_df.isna().any(axis=1).sum(),
            )
            new_df = new_df.fillna(self.ref_df_.median())

        combined = pd.concat([self.ref_df_, new_df], ignore_index=True)
        labels = np.r_[np.zeros(len(self.ref_df_)), np.ones(len(new_df))]

        rf = RandomForestClassifier(n_estimators=100, n_jobs=-1, random_state=self.random_state)

        if len(new_df) < self.min_rows_for_cv:
            Xtr, Xte, ytr, yte = train_test_split(
                combined, labels, test_size=0.3, random_state=self.random_state, stratify=labels
            )
            rf.fit(Xtr, ytr)
            auc = roc_auc_score(yte, rf.predict_proba(Xte)[:, 1])
        else:
            auc = cross_val_score(rf, combined, labels, cv=self.cv_folds, scoring="roc_auc").mean()

        drifted = auc > self.auc_threshold
        top_features = None
        if drifted:
            rf.fit(combined, labels)
            top_features = pd.Series(rf.feature_importances_, index=self.ref_cols_) \
                .sort_values(ascending=False).head(3)
            logger.warning("Drift detected, auc=%.3f, top features: %s", auc, top_features.index.tolist())

        return {"auc": auc, "drift_detected": drifted, "top_drift_features": top_features}

    def transform(self, X):
        return X
AUC near 0.5, the classifier's guessing; nothing's changed. AUC past roughly 0.65, it found real structure telling the batches apart, and top_drift_features names the columns it leaned on, usually not the ones whose histograms moved the most, but the ones whose relationship to everything else quietly flipped.
Reproducing the pricing-tier scenario from the top:
python
X_train_clean = X_train.drop(columns=["post_hoc_flag_count"])

detector = AdversarialDriftDetector(auc_threshold=0.65)
detector.fit(X_train_clean)

X_production = X_train_clean.sample(1000, random_state=1).reset_index(drop=True)
# each column's own range stays plausible on its own - it's the relationship
# between them that flips, which is exactly what a per-feature check misses
shift_mask = X_production["num_transactions_30d"] > X_production["num_transactions_30d"].median()
X_production.loc[shift_mask, "avg_transaction_value"] *= 0.6
X_production.loc[~shift_mask, "num_transactions_30d"] = (
    X_production.loc[~shift_mask, "num_transactions_30d"] * 1.8
).astype(int)

result = detector.check(X_production)
print(result["auc"], result["drift_detected"])
print(result["top_drift_features"])
That prints an AUC comfortably past the threshold, drift_detected: True, and the two shifted columns sitting right at the top. Not because either one moved dramatically alone. Because together, they told on themselves.
What this actually costs you
I don't love pieces that sell a technique as a strict upgrade with zero downside, so here's where this one bites.
Compute is the first thing you'll feel: A cross-validated classifier on every batch is a lot heavier than comparing two histograms, fine running daily or hourly.
But a genuinely bad idea the moment you're tempted to fire it per-request, and I'd bet money someone's already made that mistake somewhere.
The threshold isn't settled science: 0.65 isn't handed down from a textbook the way PSI's 0.1/0.2 bands basically are.
I picked it by trial and error, watched it flag too much at first, walked it up, and I still don't fully trust it on a dataset I haven't run it against. Budget real time here, not five minutes.
It's not a replacement for PSI, and I wouldn't want it to be: Keep something cheap that only checks one feature at a time running as your baseline.
Reach for this the moment that baseline keeps coming back clean while performance keeps slipping anyway, because that specific combination, quiet dashboards paired with results that are quietly getting worse, is usually where a relationship, not a distribution, has shifted underneath you.
The leakage guard has its own blind spot too: High mutual information isn't automatically leakage.
Sometimes it's just a good feature, and the guard genuinely can't tell those apart on its own.
That's what the allowlist is for, and it's less a workaround than an admission that this needs a human checking in occasionally, not a fire-and-forget rule.
None of this makes the technique not worth using. It just means going in with eyes open about what you're trading, compute and calibration time, for a check that catches something PSI structurally can't.
···
Where this leaves you
Per-feature drift checks answer one question, and they answer it well: did any single input move. They were never built to answer the harder one: whether the relationships between inputs still hold up.
That second question is usually the one that actually breaks something in production, and it breaks it quietly, with every individual dashboard sitting there reporting green the entire time.
You don't need to tear out what you've already got. Keep PSI running, keep trusting it for what it's good at. Just stop assuming "all clear" means what you think it means, and add this as the thing you reach for the next time it says everything's fine and you don't quite believe it.
···
Before you go!
I write about the engineering decisions that decide whether a model holds up once it leaves validation. You can subscribe to my newsletter if you'd like more of that.
Connect With Me
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
Benjamin Nweke is a Computer Science graduate and technical writer exploring AI, machine learning, and data science. He writes about building reliable AI systems, model evaluation, agentic architectures, and the practical challenges that appear when machine learning moves beyond experiments. His work focuses on making technically complex ideas clear, useful, and grounded in real implementation.
See all from Benjamin Nweke
Data DriftMachine LearningMlopsModel MonitoringPython
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
How does Machine Learning (ML) fit into the wonderful world of Artificial Intelligence (AI)?
John Mackie
January 9, 20215 min read
Data Science
The QUALIFY clause is pure syntactic sugar
Matt Chapman
March 29, 20235 min read
Data Science
Make data work for your organization
Mike Huls
April 20, 202610 min read
Data Science
A statistical tool to use when the results are not significant (with example in R)
Rafael Valdece Sousa Bastos
January 24, 20215 min read
Machine Learning
Your daily dose of data science
TDS Editors
February 9, 20211 min read
Artificial Intelligence
The Hows and Whys behind the Generalization Gap and How to Minimize it
Andy Wang
November 12, 202210 min read
Data Science
Visualizations are very powerful tools for any data science project. It helps the reader to understand what is happening. For some dataset...
Tamjid Ahsan
October 11, 20212 min read
Improving your Python Code Through Documentation, Type Hinting and Proper Variable Names
Andy McDonald
July 22, 20227 min read
Programming
Introduction
Sreekiran A R
November 15, 20207 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close