保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Agentic AI
What SHAP Can't Explain About Agentic AI Fraud
Why autonomous agents expose a new explainability problem in fraud detection
Benjamin Nweke
September 10, 20268 min read
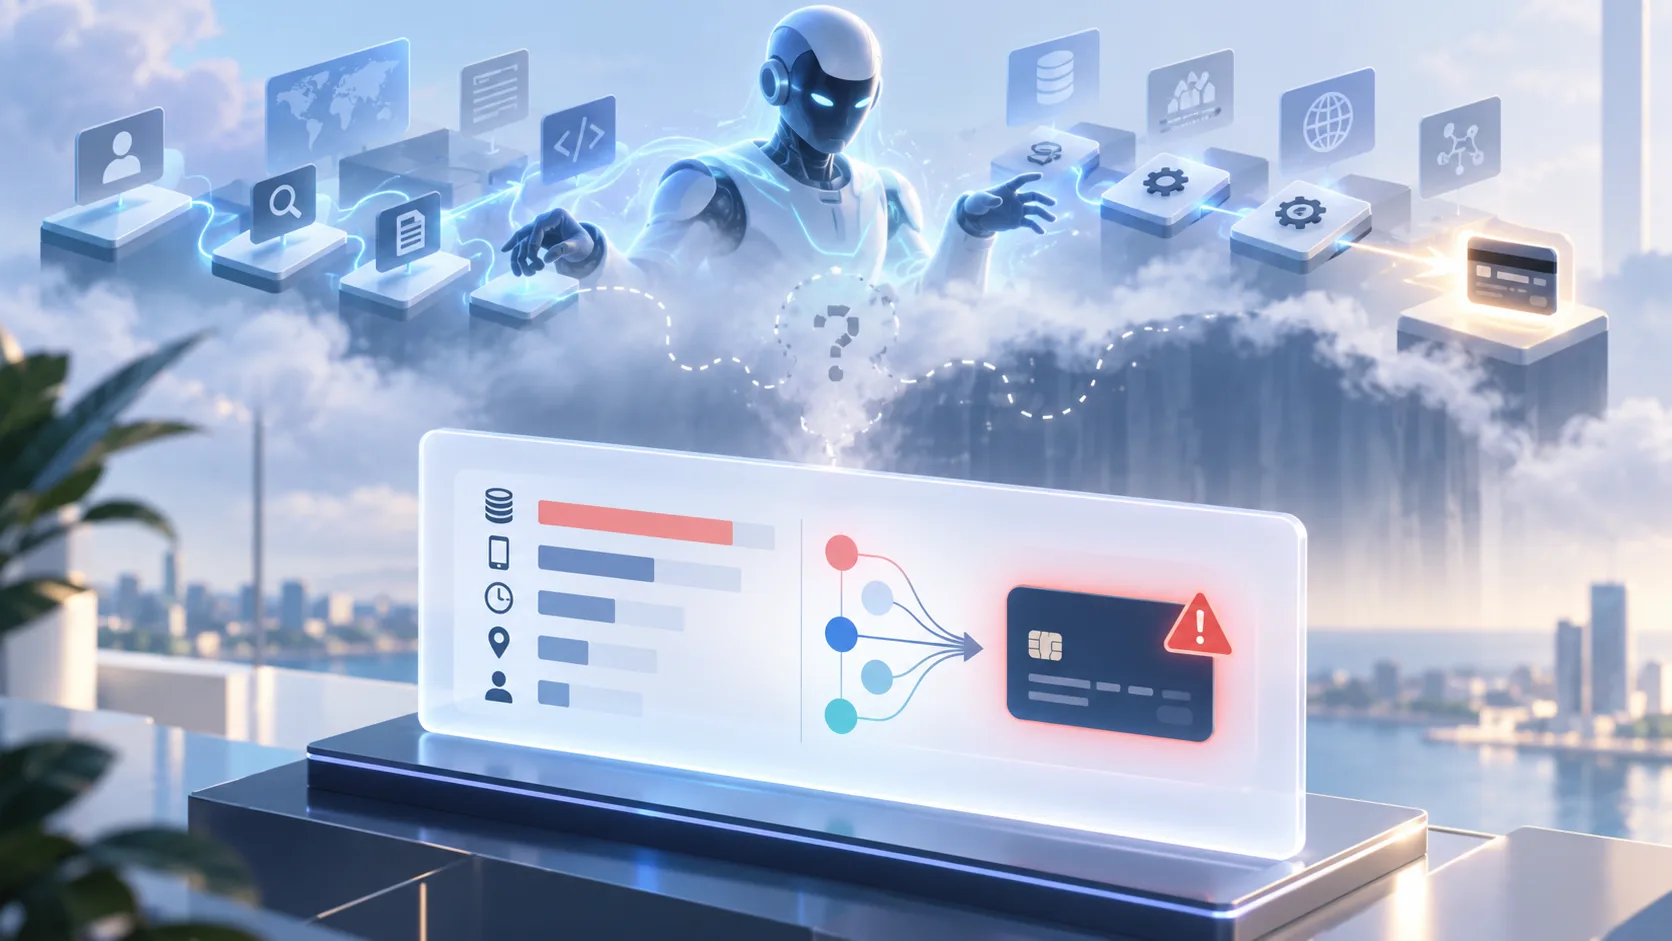 Image by author (Generated with ChatGPT)
A futuristic AI agent operates across a connected financial transaction system while a fraud detection interface analyzes suspicious activity using feature-level explanations. The illustration represents the explainability gap in agentic AI fraud, where models such as SHAP can explain why a transaction appears risky but not the agent decisions and actions that produced it.
Fraud stopped being a purely human activity sometime in the last year. Not all of it, obviously; I mean, most fraud is still someone typing on a phone somewhere trying to move money that isn't theirs.
But enough of it has shifted that Experian's 2026 Future of Fraud Forecast put a name on it. AI agents transacting and shopping on people's behalf are now a real driver of financial fraud.
The report calls it "machine-to-machine mayhem," which sounds like a headline written to get clicks, and honestly, it worked.
Because a legitimate shopping agent and a fraudulent bot can show up in a transaction log looking basically identical. Nobody's figured out the tell yet.
I want to sit with why that's a bigger deal than it sounds. Most fraud detection, at every scale, from a local fintech to a Fortune 500 bank, has quietly rested on the same assumption for a decade or more.
Which is that there's a human on the other end of the transaction, and humans leave fingerprints.
Things like how they type, when they switch devices, basically the way someone behaves when they're anxious or in a hurry.
Every fraud model, whether anyone building it says so out loud, is trained to notice when a human stops acting like themselves.
I ran into a smaller, dumber version of this exact problem while building a fraud detection system, one that leaned hard on SHAP to explain itself.
It's worth telling because the thing that got me out of trouble at the time is the exact thing I now think is running out of road.
Learn this step by step with the interactive AI Agents roadmap.
The question that wasn't really about the model
At my presentation, one of the panelists leaned back in his chair and asked a question that had nothing to do with precision or recall.
If a CEO makes a one-million-dollar transaction, and a university student makes the same transaction, does your system flag them the same way?
I remember the room going quiet, and I remember taking longer to answer than I wanted to.
My model, a Random Forest classifier I'd trained on the PaySim dataset after benchmarking it against XGBoost and LightGBM, didn't know or care who was transacting.
It looked at the transaction: amount, timing, device, velocity.
Basically the same features for a CEO's account as for a broke undergrad's.
On paper, that's what fairness in ML is supposed to look like. In front of a panel whose entire job is finding holes in risk models, it looked like I'd missed something obvious.
Here's what actually saved me, and it wasn't a smarter model.
I'd wired SHAP into the pipeline sitting on top of the classifier, mostly because a supervisor earlier in the year had pushed back on treating the model as a black box, and it turned out to be the reason I survived that question.
I could pull up the specific transaction, show the ranked SHAP values, and say: here's what actually drove this prediction, in order, and with numbers attached.
That question has stayed with me longer than almost anything else from that presentation. Not because of what it exposed about my model specifically, but because of the assumption sitting underneath the whole field: that the thing making a transaction has a life outside the transaction, a job, a history, a reason to be moving that particular amount of money.
In simpler words, context.
If you want the full build, the model comparisons, the PaySim dataset quirks, and what my supervisor actually said when he saw the SHAP output for the first time, I wrote it all up here: I Trained Six Models for Fraud Detection, and the Best One Isn't in Production. This piece picks up from that one but doesn't require you to have read it.
 I Trained Six Models for Fraud Detection, and the Best One Isn't in ProductionWhat a final-year project taught me about the gap between evaluation metrics and production decisionsBenjamin Nweke · 10 min read
···
Why explainability stopped being optional
Black-box fraud models have always had a trust problem, agentic AI or not.
The models that perform best, deep ensembles, gradient-boosted trees, tend to be the hardest to interpret, and that's a genuinely annoying trade-off if you've ever had to explain a flagged transaction to someone who isn't a data scientist.
If a compliance analyst can't tell whether a flag is a real signal or just noise the model latched onto, they'll either rubber-stamp everything or ignore the model entirely.
I've seen both happen, and neither one is why you built the thing.
SHAP earned its spot in fraud stacks by answering a narrow, unglamorous question, not "is this model good" but "why did it do this, for this one transaction, right now."
It's less exciting than model architecture, which is maybe why it doesn't come up in conversation as much as it probably should.
A risk score with no reasoning attached is close to useless the moment a human has to act on it. That was my exact problem at the presentation.
Instead of "92% fraud probability," you get something like: the amount is high for this account, the account is under 48 hours old, or the merchant has prior flags.
People trust that.
Or at least they trust it more than a number with nothing under it.
The ground is shifting under the fingerprint
Here's the part that bugs me.
Every explainability method built for fraud detection, SHAP included, explains a decision using features that describe a transaction: amount, time, device, velocity.
Now stay with me here.
Those features exist because they correlate with how humans behave when something's wrong.
A student's account suddenly moving CEO-sized money looks strange precisely because we assume a stable human behind it, with a pattern of life the anomaly is breaking from.
An agent doesn't have a pattern of life in any way that maps onto those features.
It doesn't get tired at 2 am. It doesn't fat-finger a transfer or panic-send money to the wrong account.
It can transact at a speed and consistency no human could sustain for five minutes, and that breaks the whole premise fraud detection has quietly run on: that deviation from a human baseline is the signal.
This isn't a someday problem. It's already showing up in the numbers.
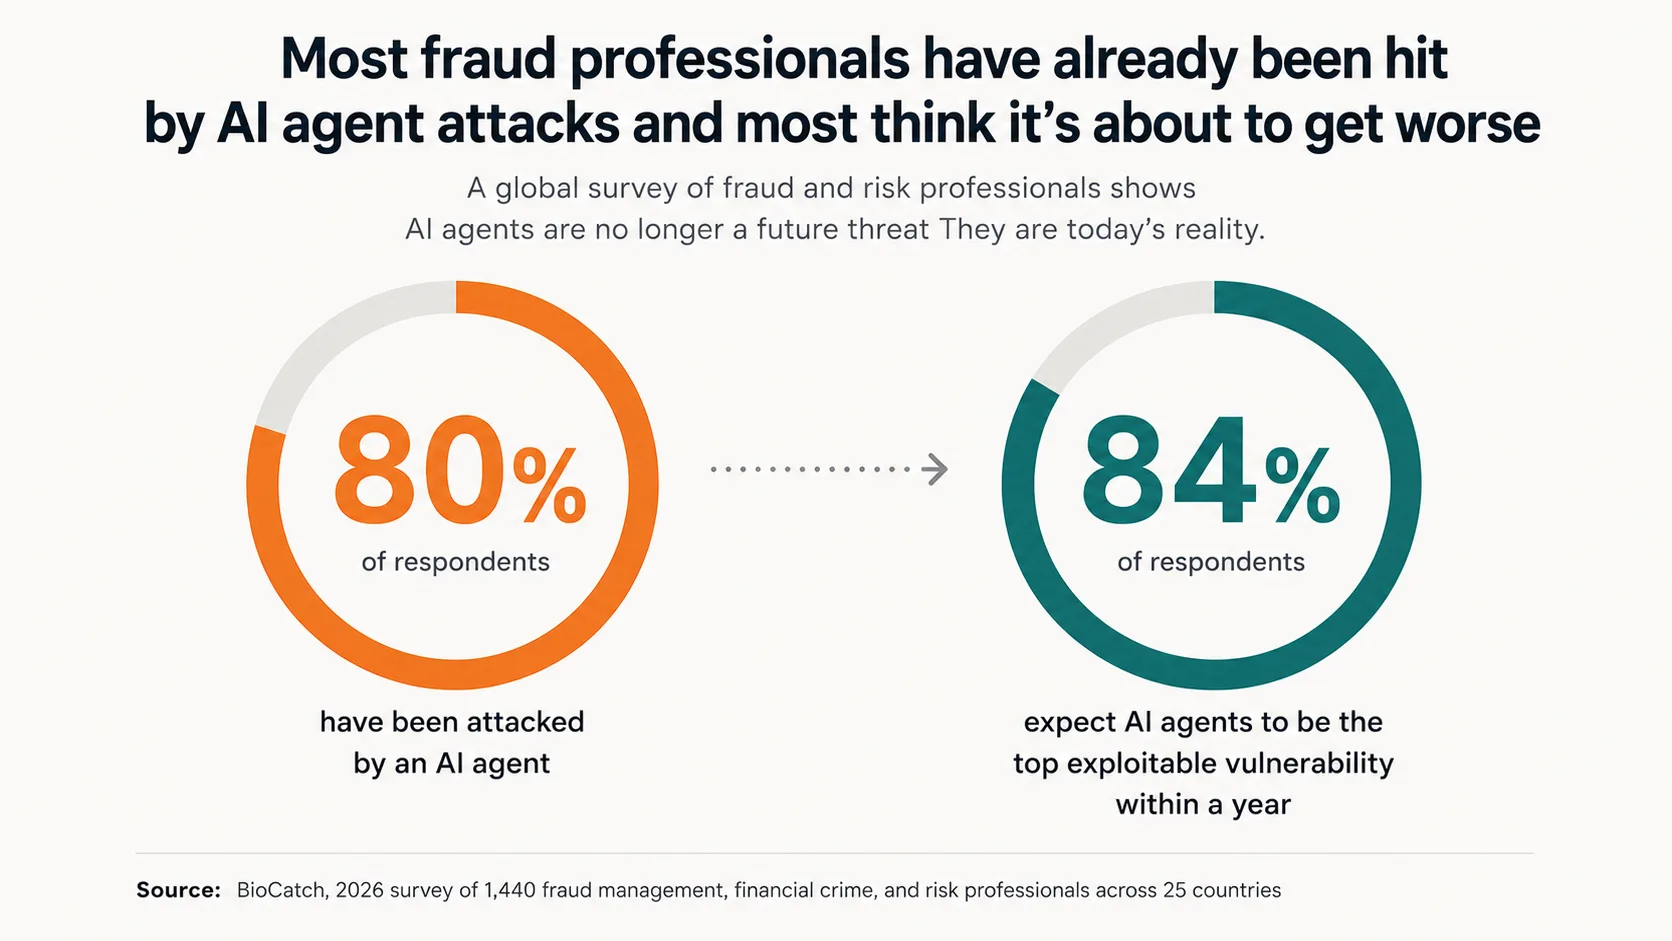 Image by author. Data source: BioCatch, 2026 survey of 1,440 fraud management, financial crime, and risk professionals across 25 countries. https://www.biocatch.com/press-release/world-banking-leaders-see-ai-agents-as-industrys-greatest-vulnerability-in-next-year
The number I find more interesting than the headline 84% is the 60% who expect AI-mediated banking to make traditional fraud defenses less effective.
That points to something deeper than criminals simply getting better tools. The signals those defenses were built around may themselves be changing.
Regulators are already circling this, and not in the usual glacial way.
NIST's AI Agent Standards Initiative, launched in February 2026, treats agents as identifiable non-human principals that need their own credential lifecycles and audit trails, on the reasoning that existing auth frameworks were built for humans and don't stretch to cover autonomous software.
In the US, it's already further along than a standards initiative. Senator Mark Warner's draft AI AGENT Act, floated in mid-2026, would create a federal registry of trusted agents and require them to act transparently in a user's interest on major platforms.
I don't know if this exact bill survives contact with Congress; most don't in their first draft.
But the instinct behind it is the thing worth noticing: lawmakers have landed on identity and accountability as the load-bearing question, before the industry has agreed on how to even log an agent's reasoning in a way a human could audit later.
What breaks, and what doesn't
I want to be clear: I don't think SHAP is dead or dying, trust me, not even close.
Feature-level explanations still matter for the transaction-shaped slice of fraud, and humans aren't going anywhere as fraud actors, unfortunately.
But feature attribution on transaction fields only ever answered why did this look wrong. Agentic fraud is dragging a different question onto the table.
Why did this actor do this at all?
That second question wants a different kind of trace entirely.
Not transaction features but the agent's actual decision path, what tools it called, what it was authorized to do, and whether the action it took falls inside or three steps outside the scope someone delegated to it.
A system built to explain a Random Forest's verdict on a dollar amount has literally nothing to say about whether an agent went off-script upstream of the transaction it eventually made.
That's closer to auditing a trajectory than scoring a data point.
I've gone looking for someone who's solved this properly and mostly found papers that gesture at the problem without actually closing it, which either means I'm bad at finding things or it's genuinely still open. Possibly both.
(Also, and this is a side thought I can't fully back up: I wonder if part of the reason nobody's cracked this yet is that agent trajectories are logged by the same companies building the agents, and there's not a lot of incentive to make that logging legible to an outside auditor. That's more of a suspicion than an argument, so take it for what it's worth.)
My guess, and it's just a guess, is that this doesn't get fixed by making SHAP more sophisticated.
It probably gets fixed by borrowing from a completely different corner of AI safety, agent monitoring and trajectory evaluation, and then stitching it onto the explainability discipline fraud detection already has.
Or maybe those two fields never really merge and someone builds a third thing from scratch. I go back and forth on which one is more likely.
···
Final thoughts
I built a system to catch a human doing something a human wouldn't normally do, and SHAP was the thing that made it defensible in front of a room of people paid to find its weak points.
That problem is still real, and still not fully solved, so this isn't me saying my fraud detection system or others like it are done for.
But the target has moved somewhere the current toolkit wasn't initially built to follow, and I don't think that's a small footnote.
It's the gap between explaining a score and explaining an actor. Right now most of us, me included, only really know how to do the first one.
If you're building or evaluating fraud detection, the question I'd actually sit with isn't whether your model is accurate.
It's whether your explanations still mean anything once the thing on the other end of the transaction stops being a person.
···
Before you go!
I write about the gap between what a model does and what you can actually prove it did, especially once the thing making decisions stops being obviously human. You can subscribe to my newsletter if you'd like more of that.
Connect With Me
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
Benjamin Nweke is a Computer Science graduate and technical writer exploring AI, machine learning, and data science. He writes about building reliable AI systems, model evaluation, agentic architectures, and the practical challenges that appear when machine learning moves beyond experiments. His work focuses on making technically complex ideas clear, useful, and grounded in real implementation.
See all from Benjamin Nweke
Editor's PicksExplainable AiFraud DetectionMachine LearningShap
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Agentic AI
Claude can now write its own harness on the fly, custom-built for the task at hand.
Chien Vu Minh
June 12, 202624 min read
Agentic AI
hidden cost of asynchronous systems, how tiny CPU tasks quietly became our biggest bottleneck while scaling hundreds of LLM agents.
Uri Peled
July 23, 20269 min read
Artificial Intelligence
Streamlit Sharing is here and is awesome.
Arunn Thevapalan
October 18, 20204 min read
Machine Learning
Often hidden among numbers are patterns and trends that are invisible to the untrained eye. Whether in natural or synthetic processes, if...
Christophe Brown
November 23, 202112 min read
Agentic AI
I tested TypeSafe AI’s Jev on 3,080 classification tasks to see how its accuracy, latency, calibration, and confidence compare with LLMs — and whether it works as a practical decision layer for AI systems.
Nhu Hoang
September 25, 202625 min read
Artificial Intelligence
A human-centric guide to AI automation for product managers
Rahul Vir
July 28, 20255 min read
Artificial Intelligence
For the past few weeks, I have been taking the free and excellent fast.ai online course, which teaches deep learning from a practical...
Eddie Forson
June 10, 20176 min read
Machine Learning
Going over the principles from the MoCo v1 & v2 papers
Leon Sick
January 10, 20226 min read
Artificial Intelligence
Learning to transform categorical data into a format that a machine learning model can understand
Slava Efimov
November 11, 20245 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close