保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Large Language Models
A Comprehensive Guide to Collaborative AI Agents in Practice
the definition, and building a team of agents that refine your CV and Cover Letter for job applications
Hesam Sheikh
July 3, 202414 min read
A look at the definition, and building a team of AI agents that refine your CV and Cover Letter for job applications
 Image created by DALLE3.
Not a member? Read for free!
Agentic AI is one of the hottest subjects of the AI community in 2024 and there is a good reason for that. Foundational Models are becoming more sophisticated in reasoning and planning. With these capabilities in place, we can leverage LLMs to divide a given task into smaller pieces, perform them step by step, and reflect on their results, essentially creating AI Agents.
If you're passionate about AI, or you like playing with Language Models, or you're working in Machine Learning, a comprehensive understanding of AI agents and how they look in action is necessary if you want to keep up with the latest AI achievements.
If you're in the job search process as I am, you know that writing a cover letter for each job you apply to or adjusting the CV to pinpoint job requirements is a tedious step. For my implementation of AI agents, I will develop a team of AI agents that collaborate to:
Learn this step by step with the interactive AI Engineer and Machine Learning roadmaps.
- Extract the key information out of a job description
- Modify your CV and Cover Letter to address the job
- Evaluate the final result from a recruiter's point of view, and give you a score from 0 to 100
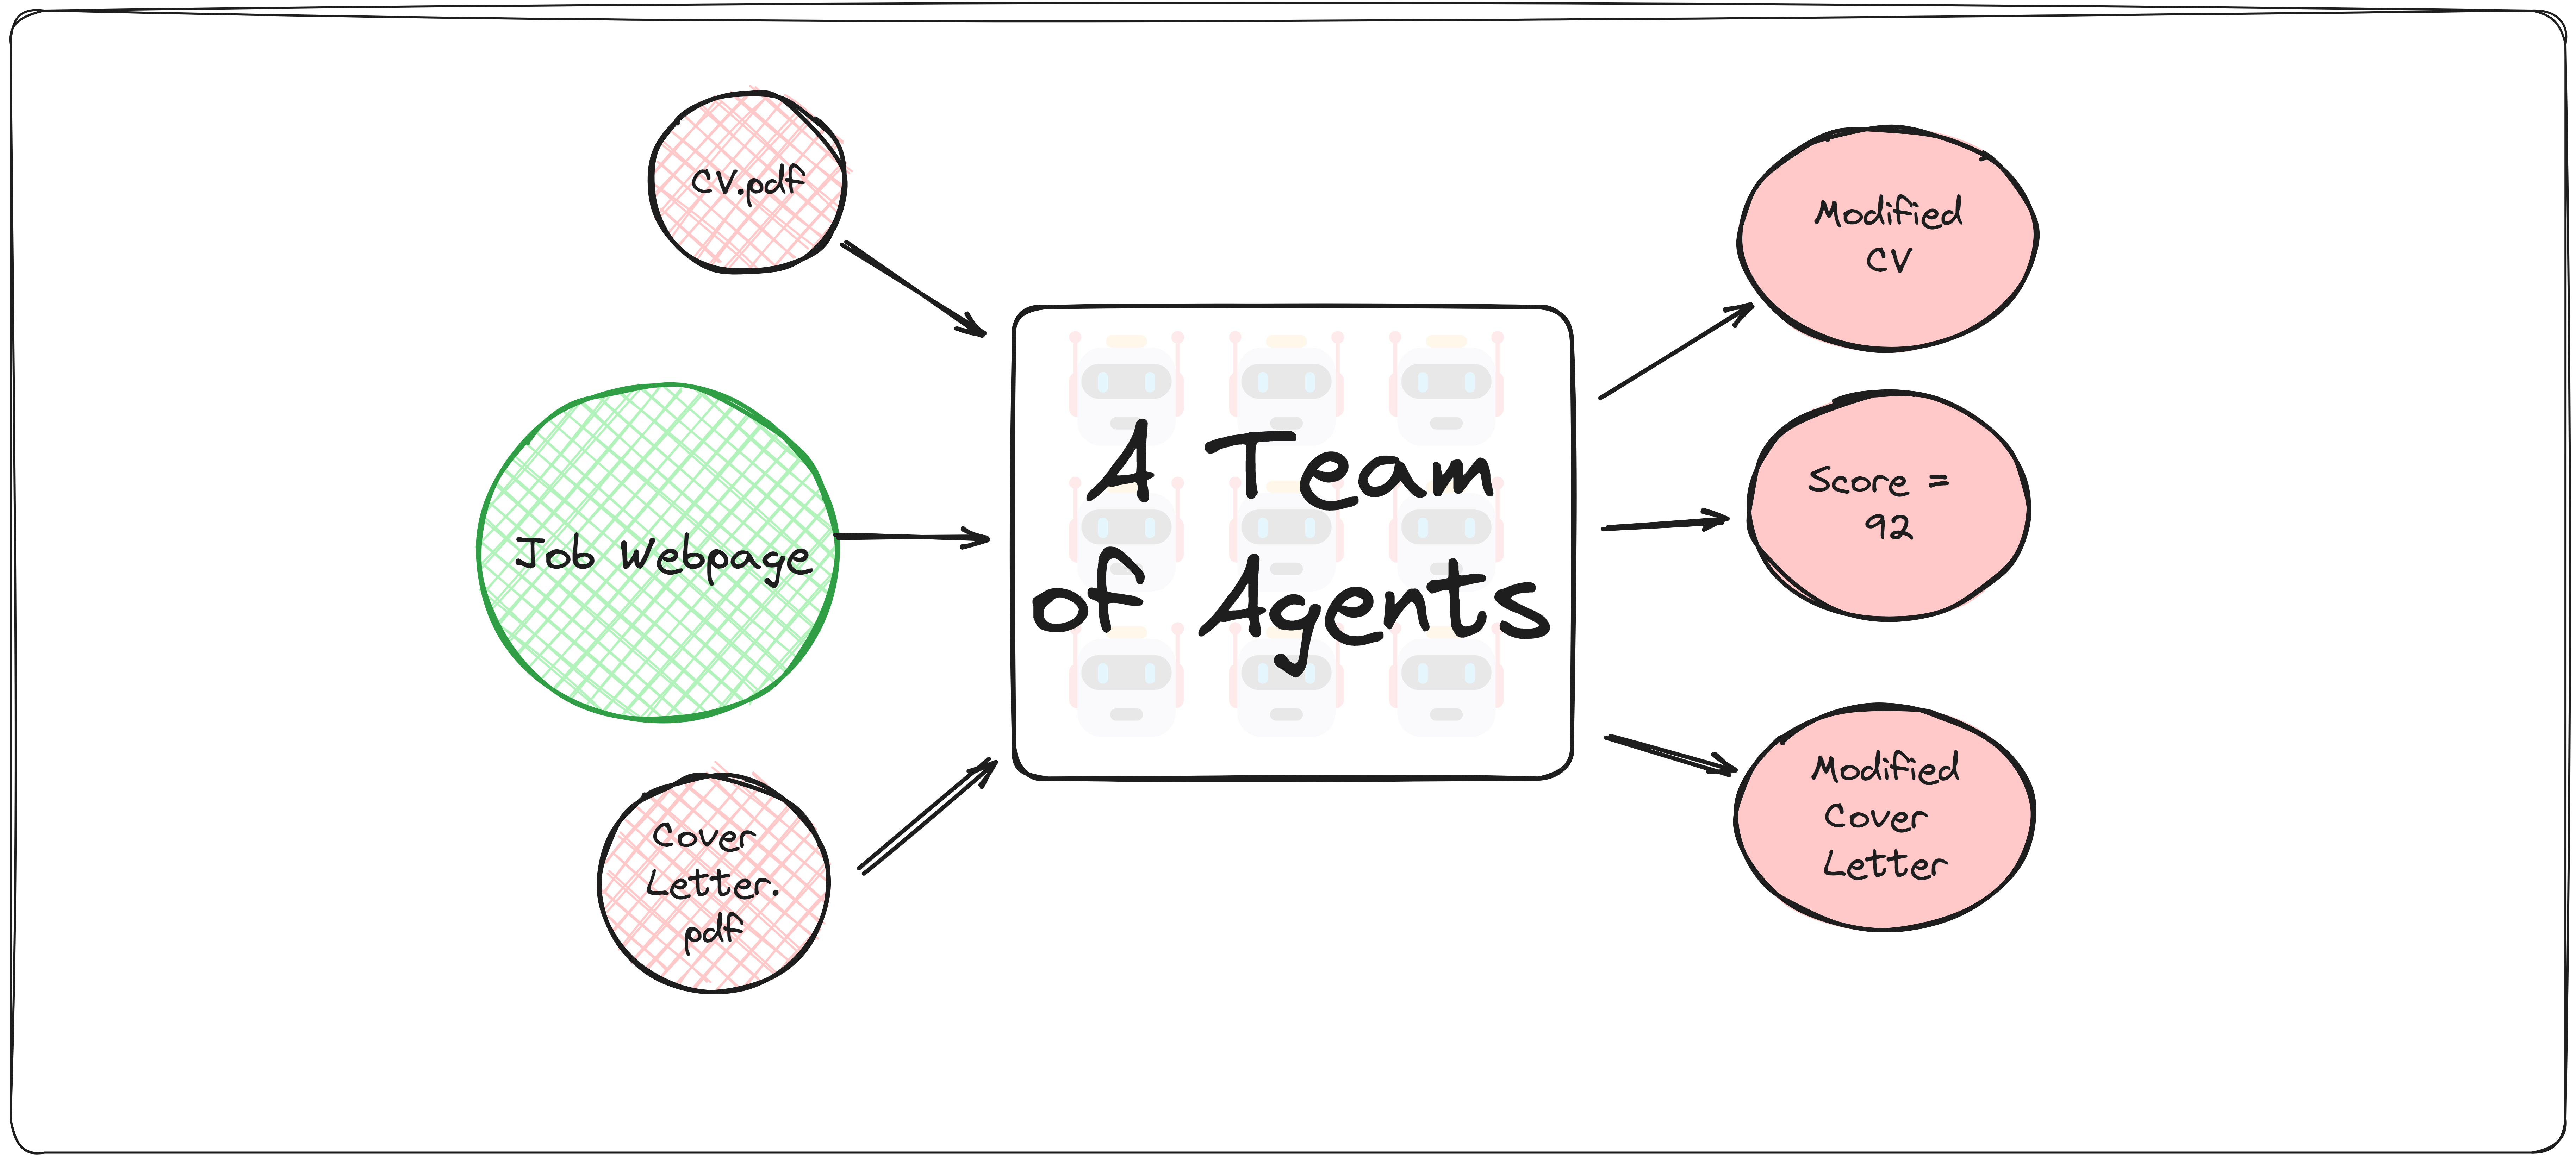 Fig 1. We will create a team of AI agents to modify our CV and Cover Letter and give us a score from 0 to 100. (by Author)
In this article, we will walk through what collaborative AI agents are, what makes agents different from LLMs, and go through a practical implementation to showcase how creating AI agents might be much simpler than you would expect.
· AI Agent Made Simple ∘ LLM-Powered AI Agents · Multi-Agent Collaboration ∘ What Makes an Agent ∘ What We Need With Multi-Agents · Code Implementation: Agents that Help You Apply For Jobs
AI Agent Made Simple
AI agent is a goal-oriented tool crafted to accomplish a specific set of tasks. While AI language models are created to generate responses for specific prompts, AI agents operate on a broader scale by addressing complex problems through decision-making and task execution. They reason upon a mission, and by using their available tools, execute smaller agendas to finish the task.
AI chatbots speak, AI agents act.
Whether in customer service, finance, or software development, AI agents are made for one thing: automation. The hope is that AI agents help individuals and organizations with their mundane routines, with lower costs to solving less creative agendas.
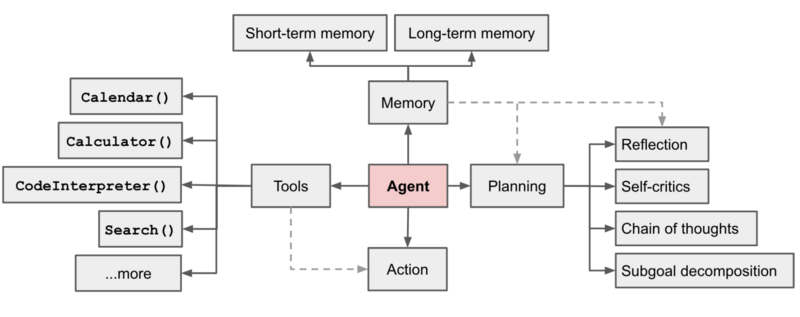 Fig 2. The outline of how a model LLM-based agent is structured. (Source: Wikimedia)
LLM-Powered AI Agents
Even though AI Agents are very different from Large Language Models, LLMs are the brains of our AI agents. Agents need LLMs to do anything intelligently, reason, and plan their next steps. This means that which LLM you use, changes the behavior of the agent completely. This is why the rise of AI agents topic was made possible by the surge of Gen-AI.
Note : The AI agents we hear about today have a somewhat different meaning than the traditional literature and textbooks. This can get confusing if you're simply searching about AI agents, and you get diverse definitions of what they are. The AI agents we use today, and are the trending topic of the AI community, are LLM-based agents that we are discussing in this article.
 Fig 3. (by Author)
At their core, autonomous AI agents benefit from three components:
- Planning: This core function of an agent, allows it to break a goal into smaller steps and work on them one by one. Another aspect of their planning is to self-reflect on their actions and learn from them. The way an agent pulls off self-reflection very much depends on the implementation, but a general outline could be thought of as displayed in Figure 4.
- Memory: To learn from past mistakes, you must remember them. Memory is the component of storing, and later retrieving information by the agent, to refine its actions.
- Tool Use: A key differentiating factor between a simple LLM and an AI agent, is their ability to use tools. Using tools can be as simple as calling an API, or using a Python function to read or write some files.
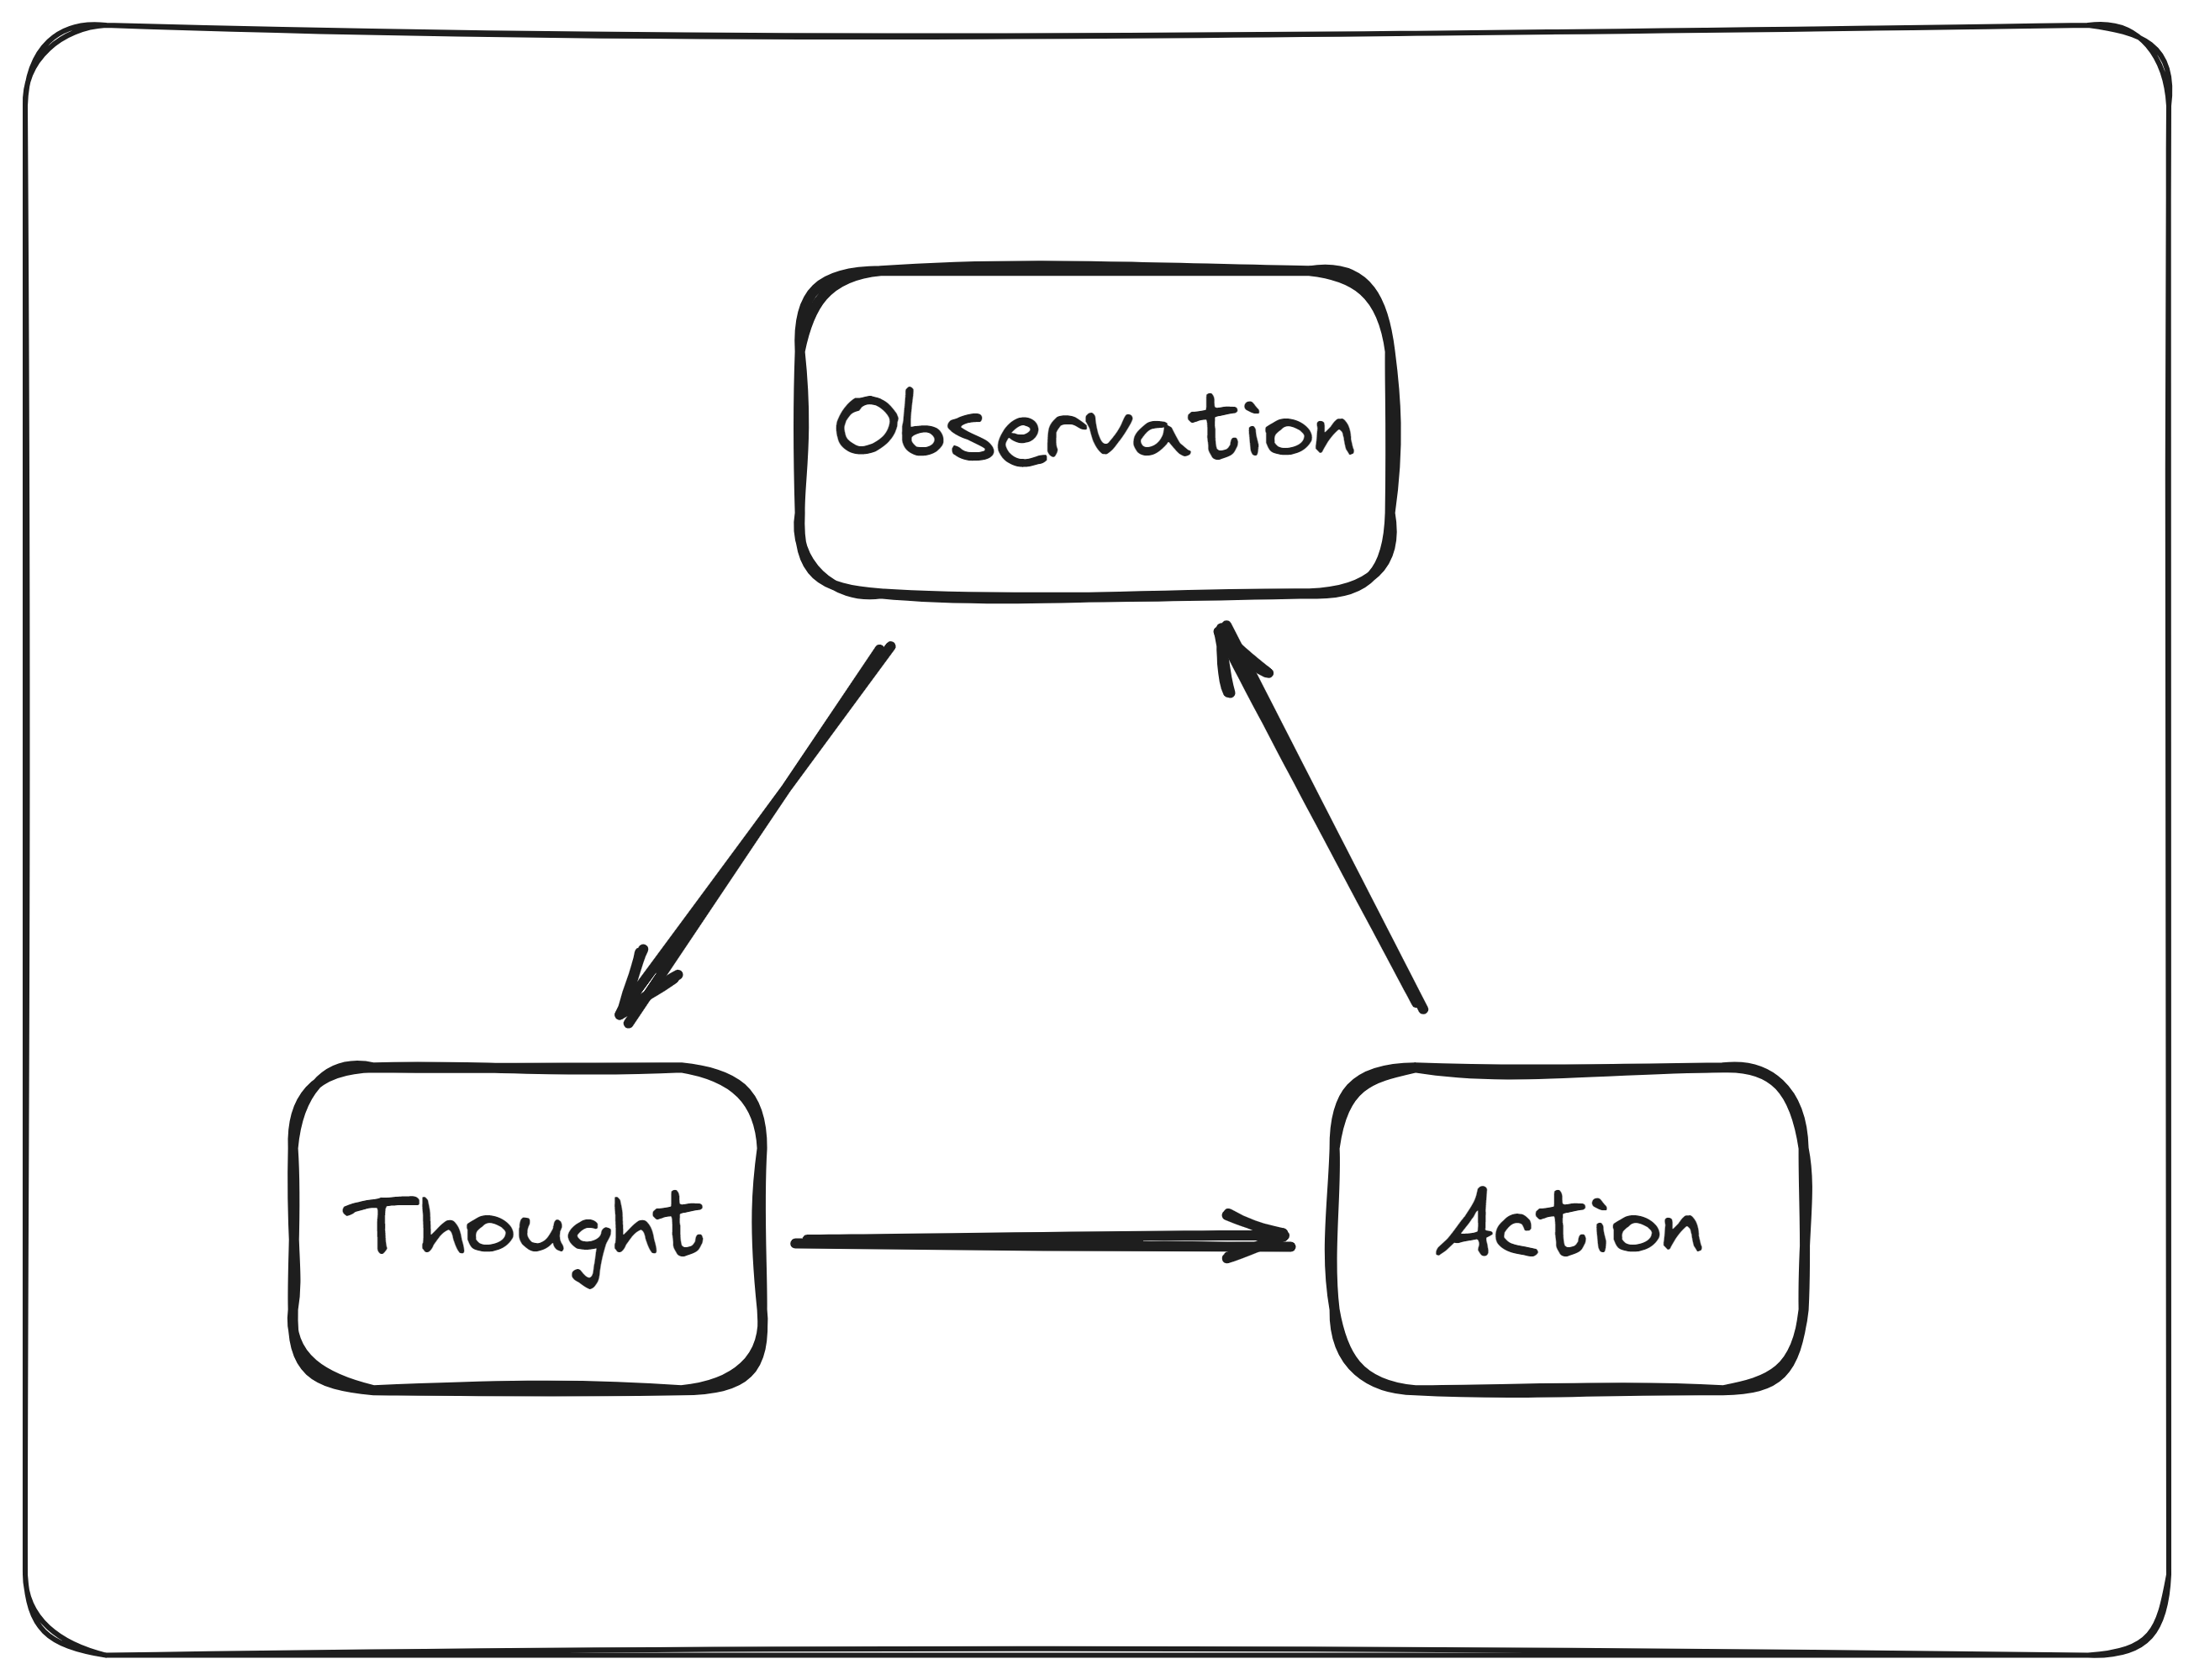 Fig 4. Self-reflection is a finite loop between the agent thinking what to do, acting on it, and observing the results, potentially taking a new approach to the problem. (by Author)
Multi-Agent Collaboration
What is better than a single agent? Many of them!
Having one AI agent is one thing, but having multiple AI agents that collaborate with each other to chop up tasks and act on them is another story.
But why do we NEED multiple agents?
When breaking a goal down into smaller parts, you end up with sub-goals that require different sets of skills. That's where you need multiple agents. A team of agents, with each one of them having a specific role and skillset, ensures that each sub-goal is tackled by its own agent.
You might even need to power each agent with a different LLM that is more sophisticated for the task to which that agent is assigned. An agent created for programming capabilities might need a completely different LLM than an agent who is supposed to write articles.
What Makes an Agent
How you would define an agent very much depends on the implementation or the library you use. In general, an agent boils down to three main elements:
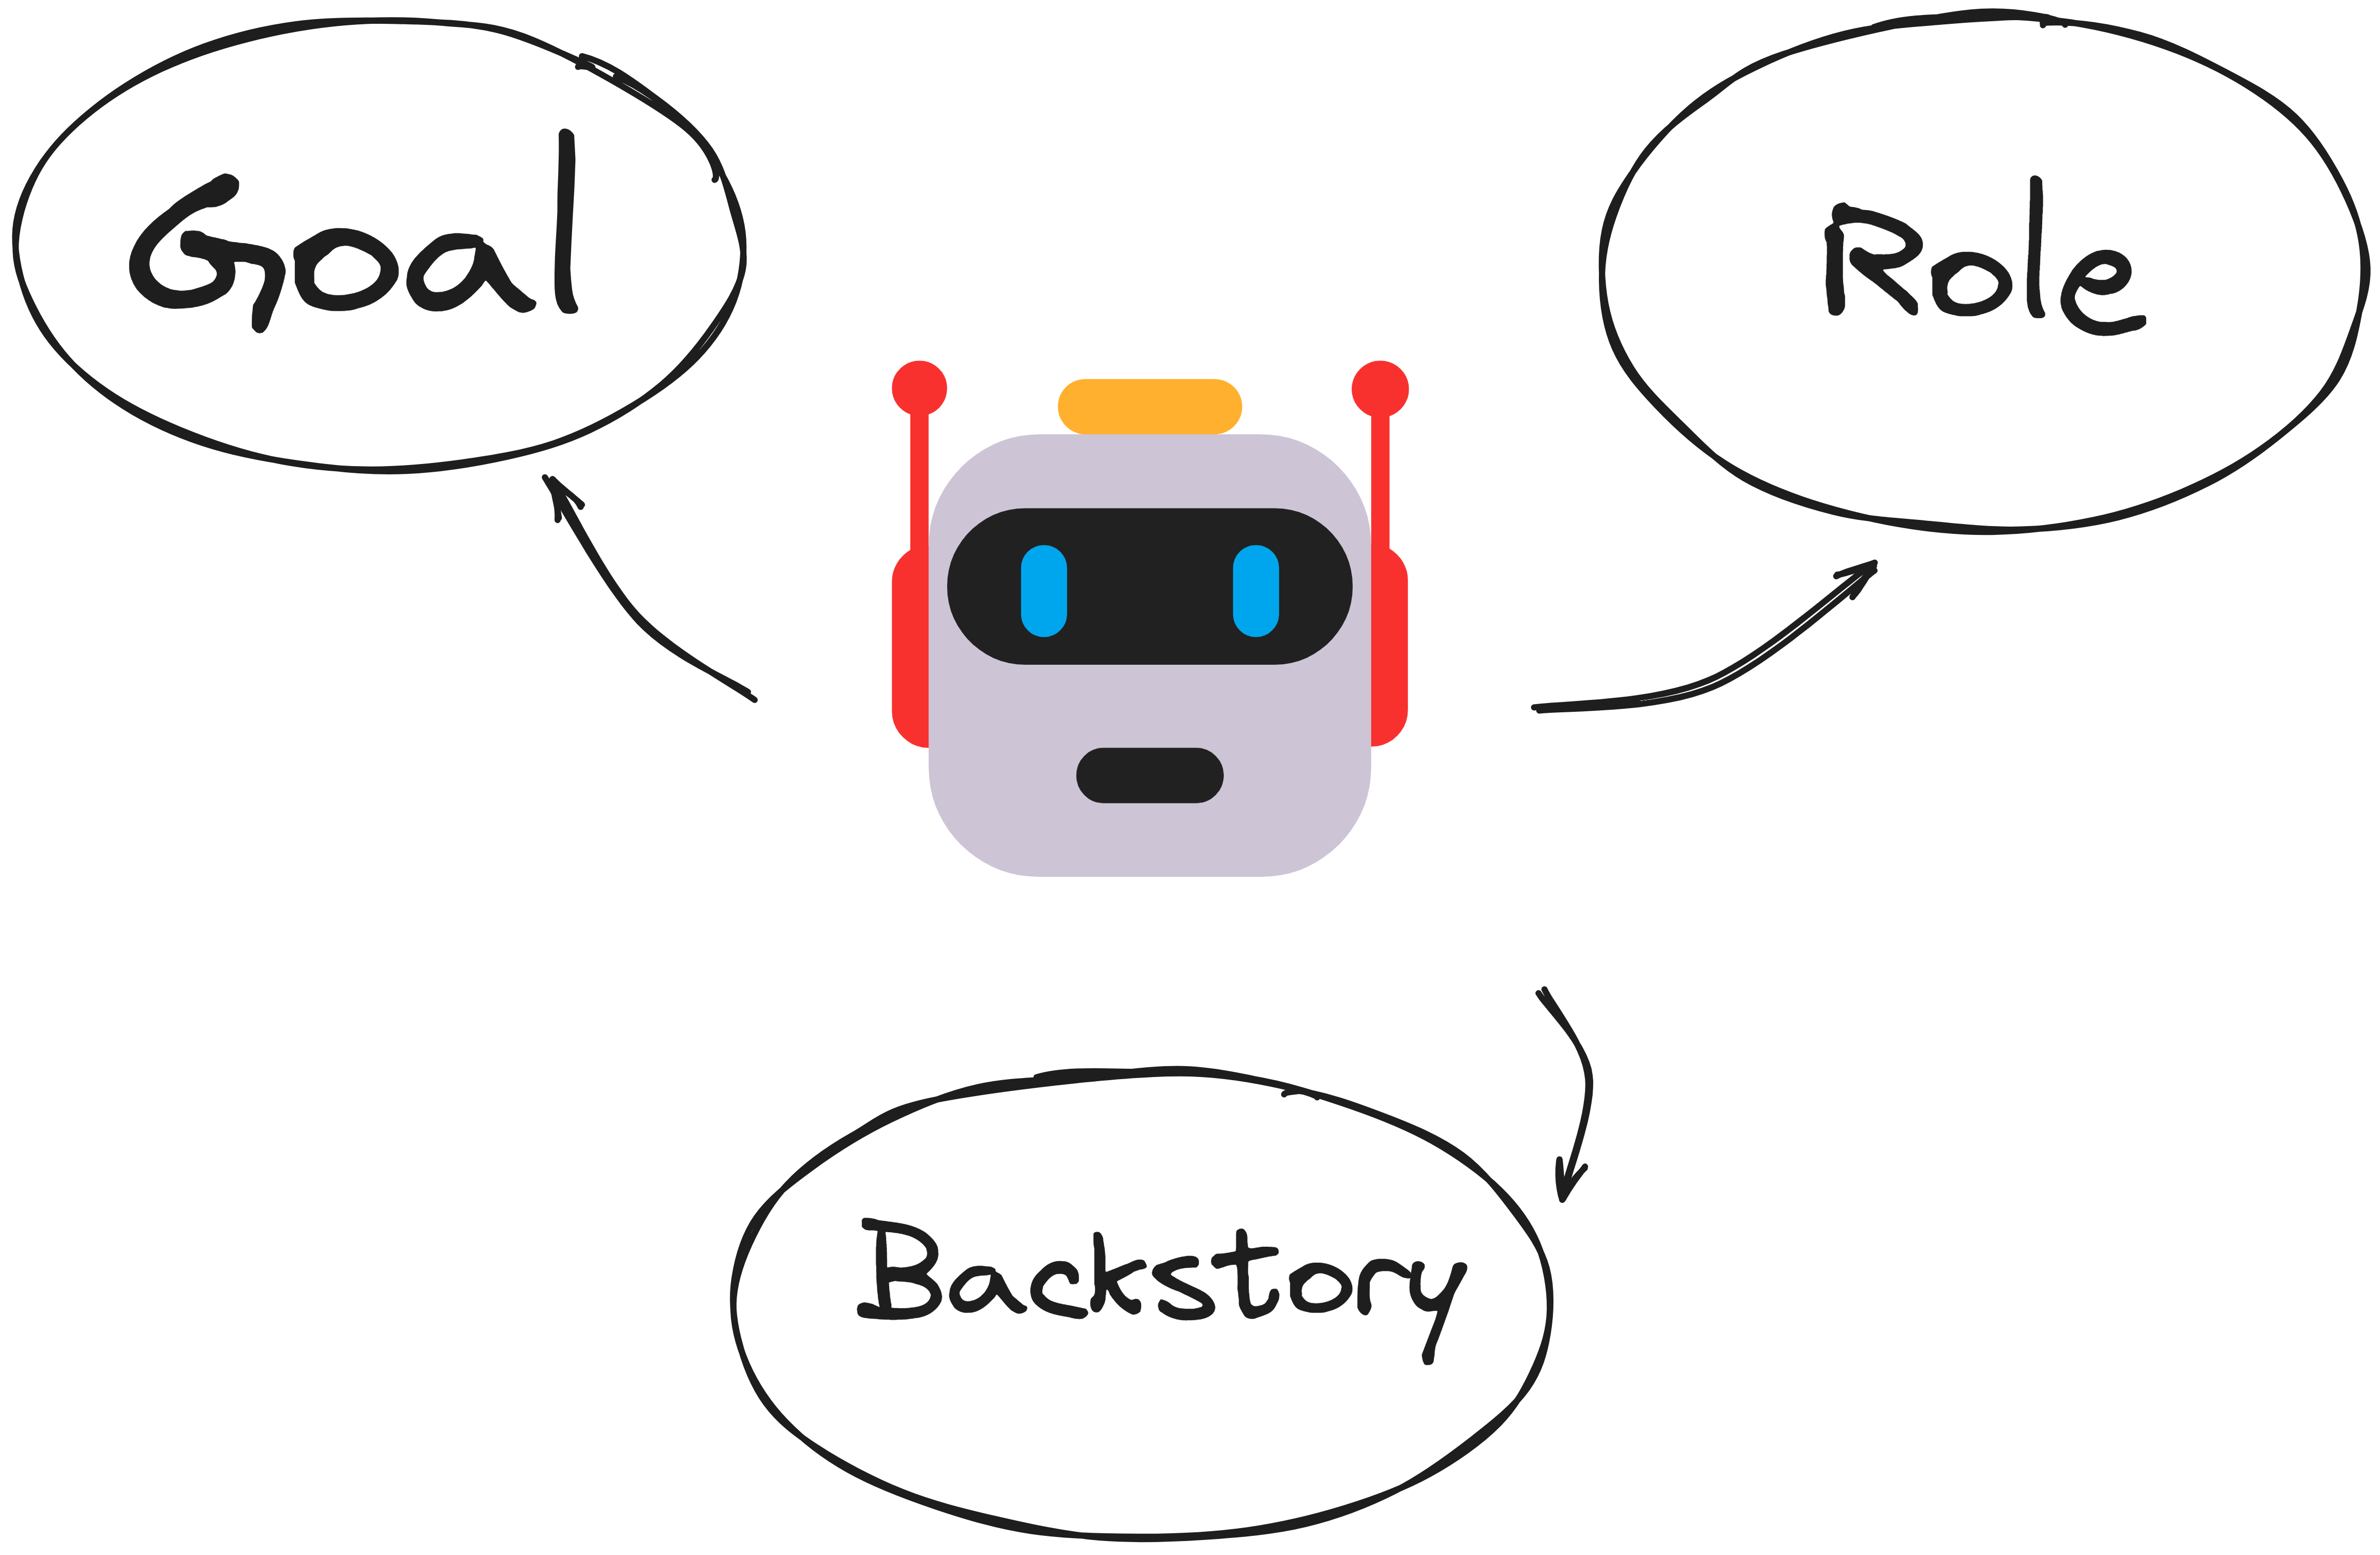 Fig 5. (by Author)
- Goal : The specific objective the agent aims to accomplish. This shapes its decision-making framework. For example, "write easy-to-understand object-oriented Python code."
- Role : The function of an agent. Who is it? A debugger, data scientist, sales marketer, etc.
- Backstory : The context of the agent. Explains the goal, role, and what the agent is good at. An example of a backstory could be, "You are a senior Python programmer with a specialization in writing optimized, well-documented code and its test cases."
What We Need With Multi-Agents
The implementation details of multi-agent have some nuances to consider. Imagine a team of people working towards the same goal, a team of chefs in a restaurant kitchen as an example.
 Image created by DALLE3.
You would need a head chef who leads the team. The team members need to communicate with each other. You need them to be able to send their finished work to the other chefs for the next step of the food preparation. This is just an example of how many things are needed to make multiple agents collaborate toward a shared assignment.
Generally, with multiple agents, you would need:
- Sharing Information : Agents need to pass their results to each other and share their findings. An agent's finished work might be the input of another agent to start their task.
- Collaboration : Agents should be able to use each other's help and delegate parts of their work if needed. This might not be a must in simple scenarios, but in complex processes, it is pretty necessary.
- Manager Agent : Controls the flow of tasks between the agents, keeping them in control.
Code Implementation: Agents that Help You Apply For Jobs
Now let's create our team of agents. There are multiple libraries that enable you to develop AI agents, such as LlamaIndex or LangChain. I will use CrewAI for its easy-to-use workflow and high level of abstraction. It's free to use and while giving you adequate control over your agents, saves you from unnecessary complexity in simple projects.
I will create a team of agents to help me modify my CV and Cover Letter for a given job description to evaluate the final result and see how much I will have the chance of getting an interview. For this purpose, I will create four agents:
- Job Crawler : This agent will receive the URL of the job posting, crawl the webpage, and extract the key information about the job requirements, qualifications, etc.
- CV Modifier : Based on the key information about the job, provided by Job Crawler, this agent reads my CV and enhances it to better fit the job description.
- Cover Letter Modifier: This works the same as CV Modifier, but works on my cover letter instead.
- Recruiter: Acts as the job recruiter and analyzes my modified CV and cover letter. It will give me feedback and also a score in the range [0–100].
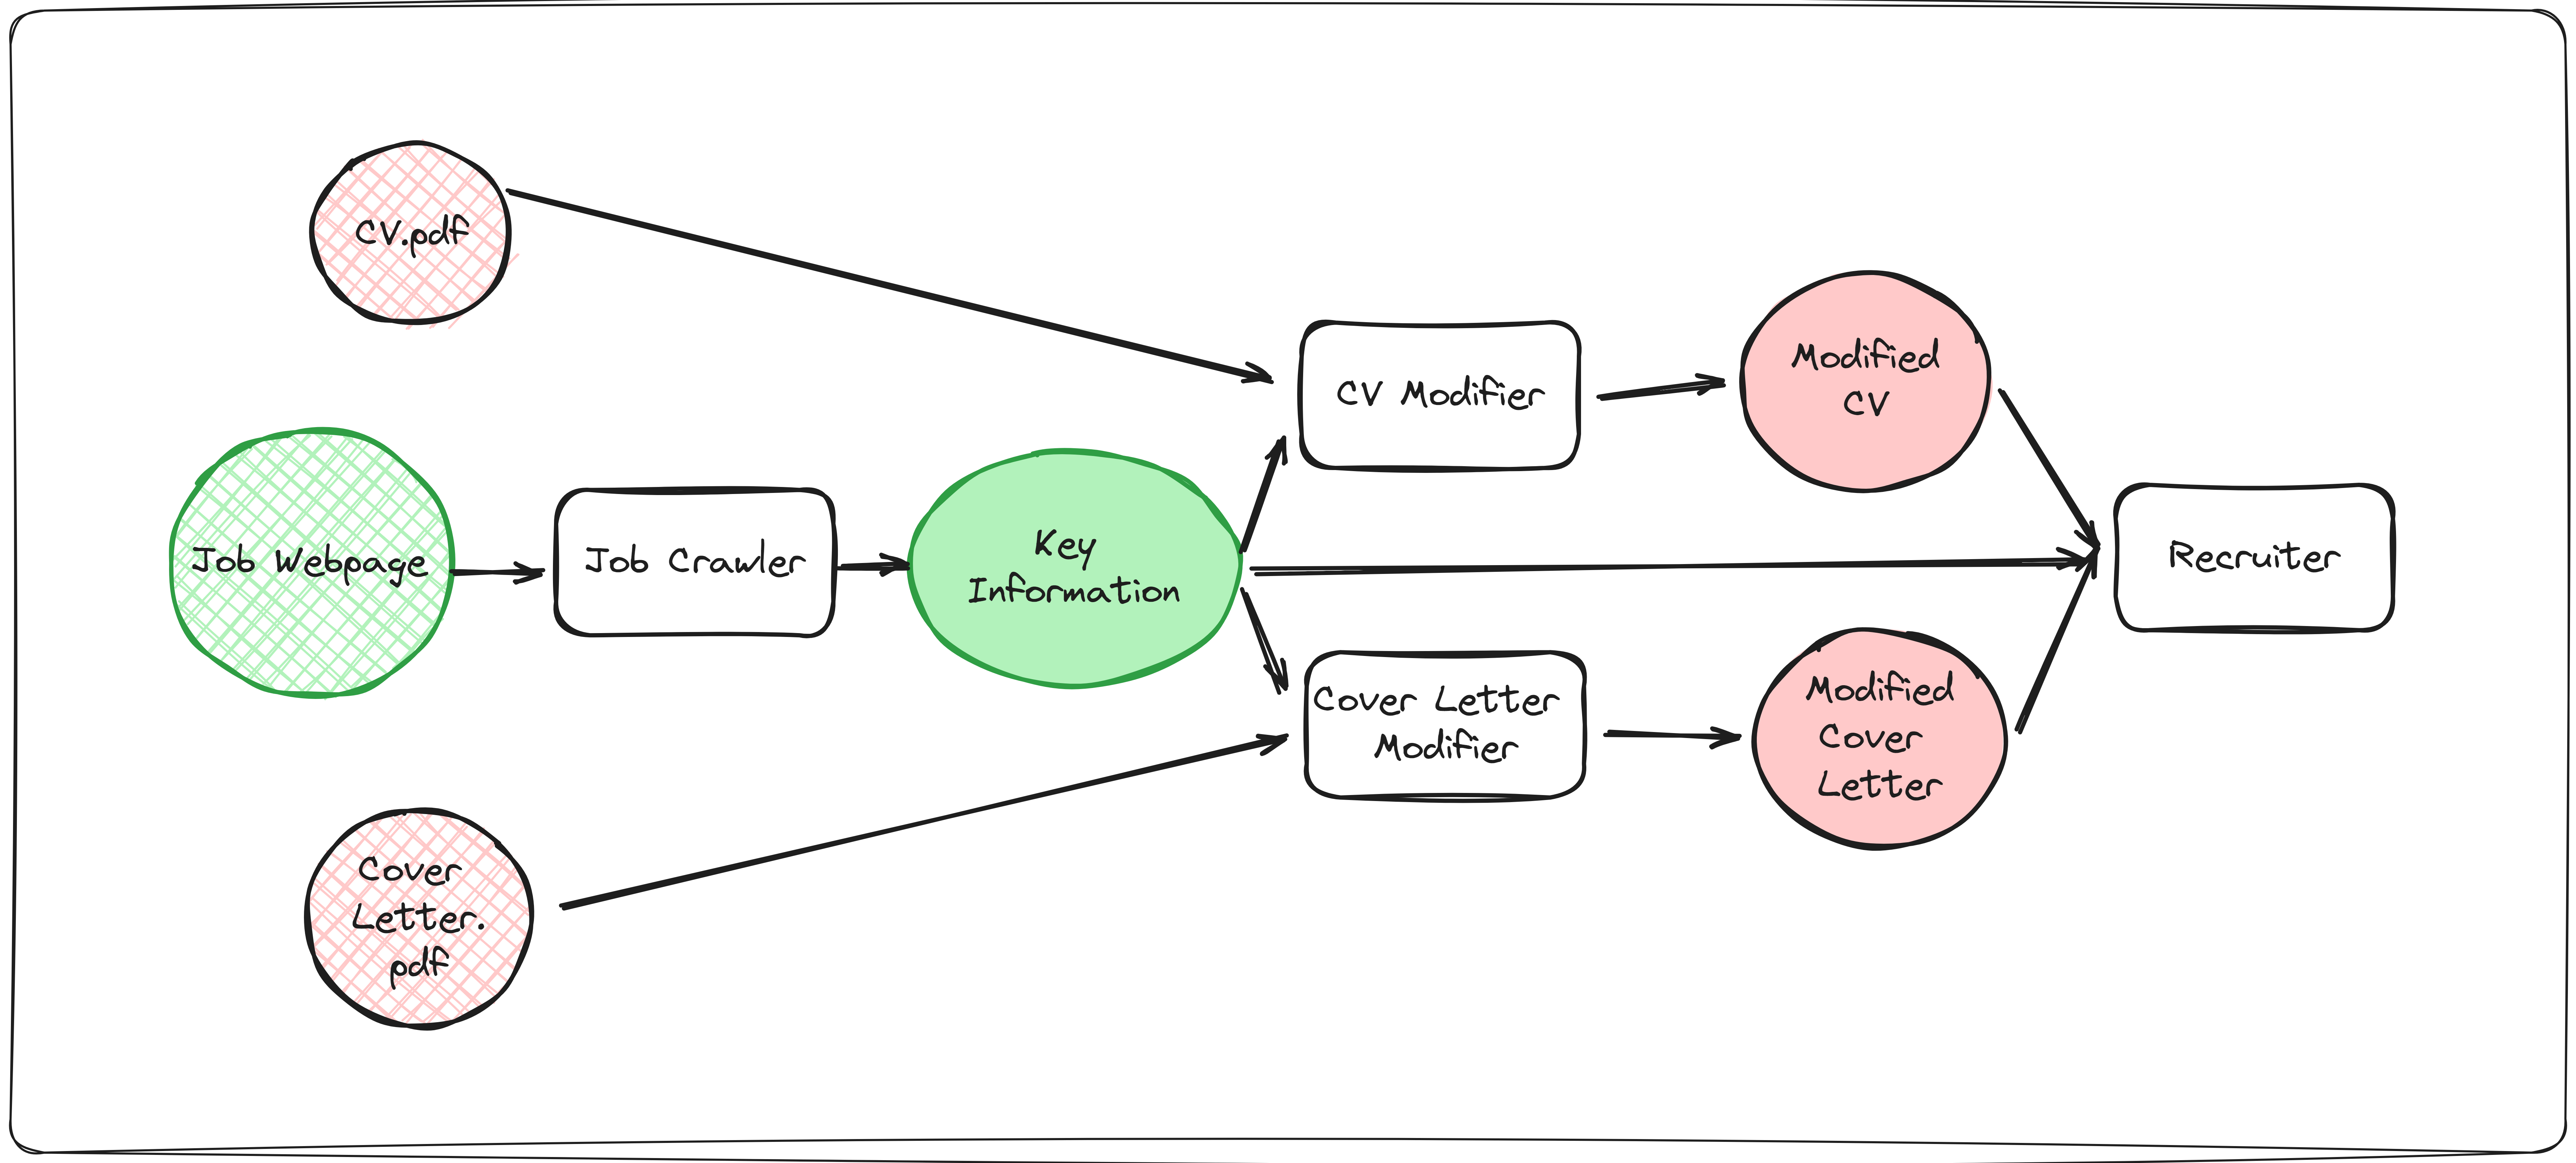 Fig 6. Outline of the agent workflow. (by Author)
For the LLM, we will use
gpt-4-turbo . However, using Ollama, you can run LLMs 100% locally and free. I will not go into details in this article, but to know how you can run LLama-3, Mistral, Phi-3, and many more models locally on your machine, read this article:
🚀 Build Your First AI Agent in 5 Easy Steps (100% local)
Next, I will load my OPENAI_API_KEY and initialize my model. This model is the backbone of our agents' reasoning:
python
from dotenv import load_dotenv
from crewai import Agent, Task, Crew, Process
from langchain_openai import ChatOpenAI
from langchain.tools import tool
import re

# Load your OPENAI_API_KEY from your .env file
load_dotenv()

# The model for the agents
model = ChatOpenAI(model_name="gpt-4-turbo", temperature=0.8)
We will also need to define two tools that our agents need to use. Tools are what agents use to execute certain tasks. Writing custom tools for agents is as simple as a Python function. All you need to do is to wrap it with the langchain's tool decorator. The tools we need for this project are one for getting the page content by a given URL and one for reading the CV.pdf and Cover Letter.pdf content.
python
from langchain_community.document_loaders import PyMuPDFLoader
import requests

# Tool for loading and reading a PDF locally
@tool
def fetch_pdf_content(pdf_path: str):
    """
    Reads a local PDF and returns the content
    """
    loader = PyMuPDFLoader(pdf_path)
    data = loader.load()[0]
    return data.page_content

# Tool for loading a webpage
@tool
def get_webpage_contents(url: str):
    """
    Reads the webpage with a given URL and returns the page content
    """
    try:
        response = requests.get(url)
        response.raise_for_status()  # Check for HTTP errors
        return response.text
    except requests.exceptions.RequestException as e:
        return str(e)
Having my model and the needed tools ready, next is to define my agents. Agents in CrewAI need three main attributes, the role , the goal , and the backstory. For each agent, we will specify a set of needed tools. Agents also have the option to delegate part of their tasks to other agents, but since this project is not that complex, we set allow_delegation to False for all of our agents.
python
job_crawler = Agent(
    role='Job Description Crawler',
    goal='Extract the relevant job description, requirements and qualificiations',
    backstory='Specialized in parsing HTML and retrieving important information from it',
    verbose=True,
    tools=[get_webpage_contents],
    allow_delegation=False,
    llm=model
)

cv_modifier = Agent(
    role='CV/Resume Writer',
    goal='Write a top-notch CV that increases the chance of landing an interview',
    backstory='Expert in writing CV that is best recieved by the recruiting team and HR',
    verbose=True,
    tools=[fetch_pdf_content],
    allow_delegation=False,
    llm=model
)

cover_letter_modifier = Agent(
    role='Cover Letter Writer',
    goal='Write an intriguing cover letter that boosts the chance of landing an interview',
    backstory='Expert in writing Cover Letter that is best recieved by the recruiting team and HR',
    verbose=True,
    tools=[fetch_pdf_content],
    allow_delegation=False,
    llm=model
)

recruiter = Agent(
    role='Hiring Manager',
    goal='Analyze how well a candidate is suited for a job description, given their CV and Cover Letter',
    backstory='Experienced hiring manager with an especialization of giving feedback to job seekers',
    verbose=True,
    allow_delegation=False,
    llm=model
)
Now we need to list our tasks. A task is a specific job you want a particular agent to do. I will assign one task to each agent. I will explain the description of my task, along with specifically how I want the output of the task to be.
python
def extract_job_information(page_url):
    return Task(
        description=f"Given this url: {page_url}, extract the job description, and relative information about the job",
        agent=job_crawler,
        expected_output="Key points of the job description, requirements, and qualifications needed for the job",
    )

def cv_modifying(cv_path):
    return Task(
        description=f"Read the CV at this local path: {cv_path}, then
        modify the keypoints and the order of the skills, to make it emphasize what is needded by the job.
        Do NOT add any extra skill or new information, keep it honest.",
        agent=cv_modifier,
        expected_output="A modified version of CV, tailor-made for the job description",
    )

def cover_letter_modifying(cv_path):
    return Task(
        description=f"Read the cover letter at this local path: {cv_path},
        then baseed on the provided job description by 'job_crawler' agent,
        modify it to make it target the provided job description. Fill in the empty brackets with the company name.
        Do NOT add any extra skill or new information, keep it honest.",
        agent=cover_letter_modifier,
        expected_output="A modified version of cover letter, tailor-made for the job description",
    )

evaluate = Task(
        description=f"Provided the modified CV and Cover Letter, and the key points of the job description,
        give a score to the candidate from 0-100, based on how well suited they are for this job",
        agent=recruiter,
        expected_output="Score in the range [0-100]",
    )
Notice, that some of these tasks depend on the output of another one. For example, I would need both the modified CV and cover letter to evaluate them. And I also won't be able to modify my CV and cover letter, unless the Job Crawler agent has successfully extracted the job information off of the webpage.
You have to be aware though, that ultimately you're extracting key job information from external website content. It would be the best practice to keep the website rights/copyrights in mind when using such tools for personal or commercial use.
This is taken care of by CrewAI automatically, by ensuring agents share the needed information with each other.
What remains is to create my crew of agents, and start them off!
python
# USER INPUTS
cover_letter_path = r'Cover Letter.pdf'
cv_path = r'CV.pdf'
job_url = [www.job.com]

extract_job_information_task = extract_job_information(job_url)
cv_modifying_task = cv_modifying(cv_path)
cover_letter_modifying_task = cover_letter_modifying(cover_letter_path)

# make the crew
crew = Crew(
    agents=[job_crawler, cv_modifier, cover_letter_modifier, recruiter],
    tasks=[
    extract_job_information_task,
    cv_modifying_task,
    cover_letter_modifying_task,
    evaluate
    ],
    verbose=2
)

# Let's start!
result = crew.kickoff()
This block of code takes the user input about the path of needed files and the webpage. Then I would create my crew, using the agents and the tasks I have defined earlier and I kick them off!
The result is a long output of all the thought processes and results of our agents. To keep it short, I will put a sample of the thought process of my Cover Letter Modifier agent:
python
> Entering new CrewAgentExecutor chain...
I need to read the content of the cover letter from the provided PDF file to understand its structure and content. This will help modify it according to the job description.

Action: fetch_pdf_content
Action Input: {"pdf_path": "Cover Letter.pdf"}

Dear Hiring Manager,
[Original cover letter, excluded for brevity]
Sincerely,

Thought:
Now I have the content of the original cover letter. I need to tailor this cover letter to specifically address the job opening at Huawei's AI4Sec Research Team. I will adjust the content to highlight relevant experiences and skills that align with the job description provided.

Final Answer:
Dear Hiring Manager,
[Modified cover letter, excluded for brevity]
Sincerely,
You could see the agent's reasons with itself, identifying what needs to be done and executing using the tools at hand.
After each of our agents has finished their assignments, we can see their output and how they have performed.
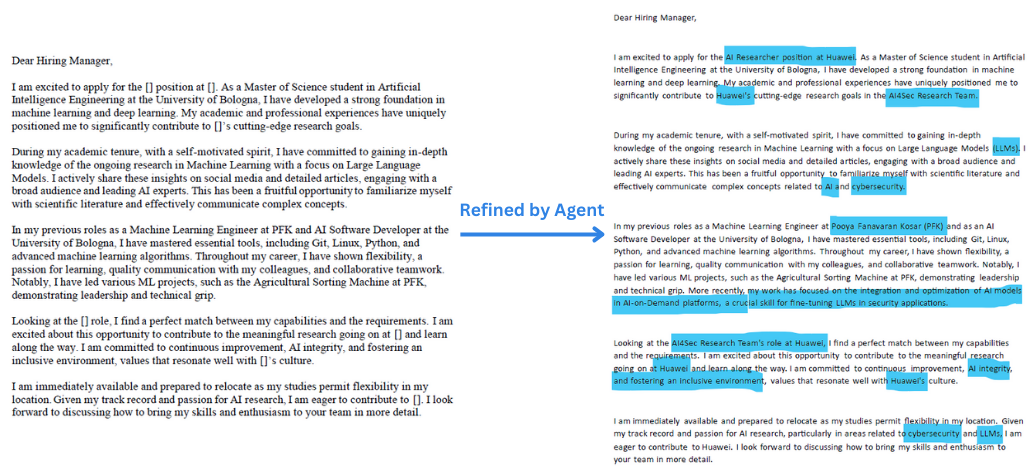 Fig 7. Template Cover Letter vs modified by the agent. (by Author)
You can see that the Cover Letter Modifier agent has successfully refined my cover letter to fit the job description, and even added some points that are emphasized in the job description. However, the CV Modifier agent's output was a bit underwhelming, requiring some adjustments to its agent and task definitions.
The recruiter agent has also gone through my modified CV and cover letter and assigned a score of 92/100:
vbnet
Based on the detailed review of Hesam Sheikh Hassani's CV and Cover Letter in relation to the key points of the job descriptionfor the AI Researcher position at [Excluded Intentionally], I would score the candidatea 92 out of 100. Hesam exhibits a strong academic and professional background in Artificial Intelligence, particularly in machine learningand deep learning, which aligns well with the requirements of the [Excluded Intentionally] Research Team at [Excluded Intentionally].His experience with Large Language Models (LLMs) and his ability to communicate complex AI concepts effectively, as demonstrated through his engagement on social media and articles, are particularly impressiveand directly relevant to the position. His technical proficiency with tools critical for the role, such as Git, Linux, Python, and advanced machine learning algorithms, further strengthens his candidacy.Hesam's previous roles and projects, such as the Agricultural Sorting Machineat PFK and his work on AI-on-Demand platforms, showcase his leadership skillsand his capability to manage and execute AI projects, which is essential forthe role at [Excluded Intentionally]. His expressed eagerness to contribute to and learn from[Excluded Intentionally]'s research initiatives, along with his alignment with [Excluded Intentionally]'s corevalues of continuous improvement, AI integrity, and inclusiveness, make him a strong fit culturally and professionally for the position.His immediate availability and willingness to relocate also add to his suitability for the role, ensuring a smooth transition and immediate contribution to the team. Thus, given Hesam Sheikh Hassani's strong alignment with both the technical and cultural aspects of the AI Researcher position at [Excluded Intentionally], he is highly recommended for this role with a score of 92.
The example use case of AI agents to modify CVs and cover letters is only to emphasize the scope of how we can use AI to automate repetitive tasks and holds as an educational example. If you want to use such tools in practice, it would be best to keep in mind some limitations:
- AI-generated CV or Cover Letter might be considered a red flag by the recruiter. The hiring managers could potentially employ AI detection tools to eliminate such candidate applications.
- AI tools such as ChatGPT still fall into the trap of CV language. Some of the writing styles and word choices of AI in CV are easily detectable. Words such as "delve" or "spearhead" might give off an AI-generated text. This writing style could make your CV sound inauthentic and less relatable.
Why does ChatGPT use "Delve" so much? Mystery Solved.
- AI chatbots and LLMs suffer from hallucinations. In the context of this example, hallucination could mean putting experiences and skills in your cover letter and CV that you don't actually possess but were inspired by the job description. Double-check for any unrealistic modifications to your CV/cover letter.
Holding a firm grip on what could be done with LLMs puts companies and experts in a superior position. One such fascinating capability is AI agents. In this article, we walked through what an AI agent is, how it is different from an LLM, and how we can implement them with a few lines of code to automate our repetitive tasks.
🌟 Join +1000 people learning about Python, ML / MLOps / AI, Data Science, and LLM. follow me and check out my X/Twitter , where I keep you updated Daily**.**
Thanks for reading,
— Hesam
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Hesam Sheikh
Ai AgentHands On TutorialsLarge Language ModelsLlmMachine Learning
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
Train, visualize, evaluate, interpret, and deploy models with minimal code.
Amol Mavuduru
February 25, 202110 min read
Artificial Intelligence
I submitted my first paper on AI in 1990 to a small, local conference - the "Midwest Artificial Intelligence and Cognitive Science...
Douglas Blank
May 27, 20237 min read
Artificial Intelligence
One nice alternative to One-hot encoding your categories
Vinicius Trevisan
March 17, 20227 min read
Machine Learning
Considerations in Favor of Post-Graduate Degrees Specifically for Data Science
Benjamin Schmidt
September 30, 20207 min read
Machine Learning
Discover how Google search engine ranks documents based on their link structure
Slava Efimov
August 9, 202315 min read
Machine Learning
The implementation of 2 active learning algorithms and their usage in SuperAnnotate's platform.
Martun Karapetyan
November 18, 20200 min read
Deep Learning
A guide to cross-validation best practices: re-training and nesting
Vitor Cerqueira
February 6, 20236 min read
Deep Learning
A paper walkthrough of the new text-to-speech model by Microsoft Research
Elad Rapaport
April 14, 202316 min read
Machine Learning
Learn what topic modelling entails and its implementation using Python's nltk, gensim, sklearn, and pyLDAvis packages
Seungjun (Josh) Kim
November 3, 202213 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close