保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Science
Building NLP Web Apps With Gradio And Hugging Face Transformers
A web app is essential for demonstrating your NLP/ML solution to colleagues and clients. But building and deploying one can be a nightmare...
Chua Chin Hon
August 11, 20217 min read
A web app is essential for demonstrating your NLP/ML solution to colleagues and clients. But building and deploying one can be a nightmare at times. Enter Gradio.
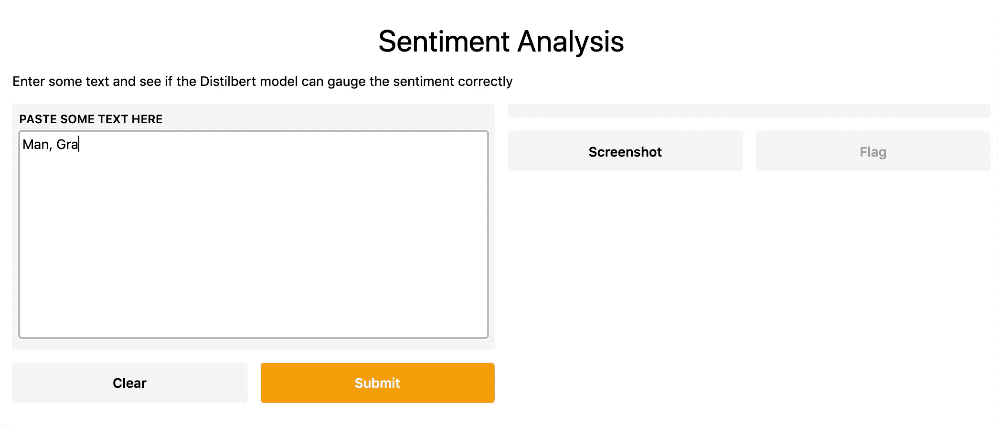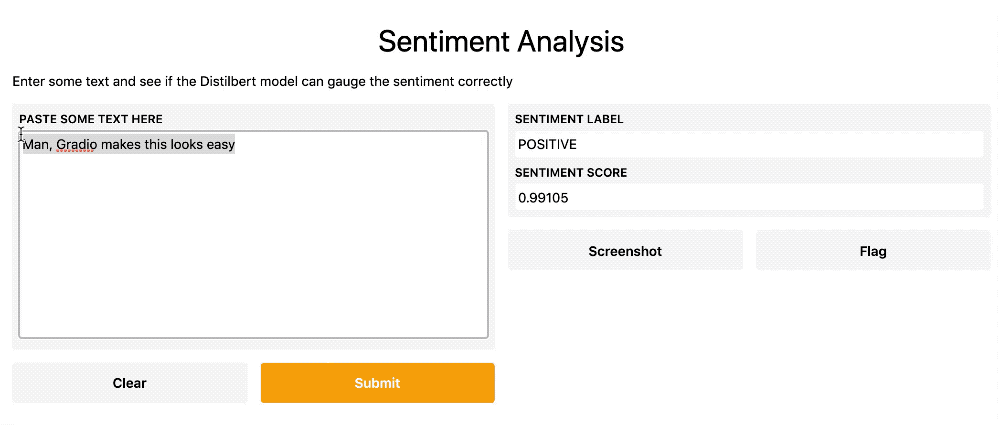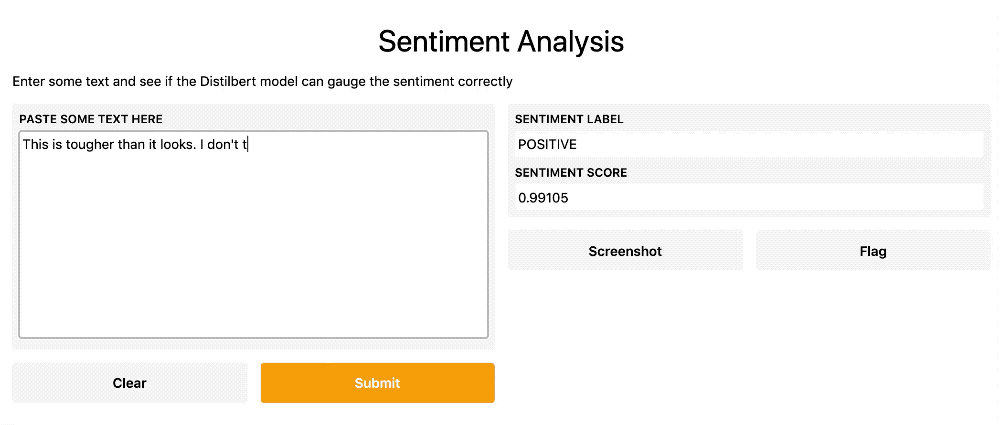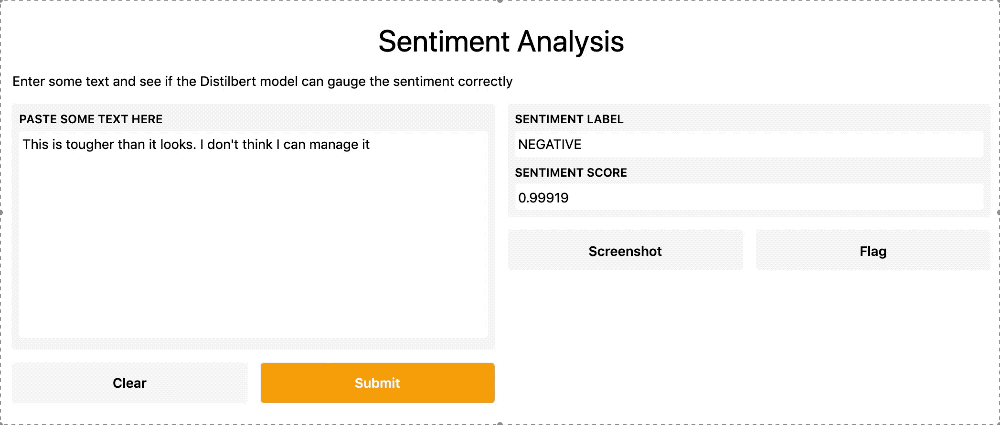 Gif of sentiment analysis web app by Chua Chin Hon.
Web app design and deployment arguably rank among the most neglected skills for data scientists and analysts. Yet, these skills are essential if you need to demonstrate your NLP or machine learning solution to colleagues or clients.
While a good presentation goes a long way, nothing quite beats having a prototype where non-technical users can test the proposed solution for themselves. And if you've tried deploying an ML web app in recent years, you'd know that most hosting services don't make it easy for those with limited front-end development experience.
Enter Gradio, a relatively new library that makes the creation and sharing of ML and NLP web apps a breeze, by comparison. With a few lines of code, you can house your model in a number of standard templates that take the hassle out of having to create separate HTML templates and figuring out the UI, color and size of the buttons etc.
Learn this step by step with the interactive AI and Data Scientist and Machine Learning roadmaps.
To be sure, the Gradio templates are pretty minimalist. But frankly that's all you need in the early stages of testing and development, when the goal is simply to test fast and iterate fast. Gradio's close integration with Hugging Face's transformers library and model hub makes it an even more powerful tool.
Gradio is not the only library you can use for rapid web app development, of course. Streamlit and Plotly are two other prominent names in this space, each with their own strengths. But I'd say Gradio is the most user-friendly by far, and a game changer for early phase NLP/ML solutions development.
Over several Jupyter notebooks, I'll share examples of how I've used Gradio to build standalone and "chain-linked" NLP apps that combine different functionalities and transformer models.
REPO, FILES, AND PROJECT SCOPE
My repo for this project contains all the files needed to run the examples in this post: 5 Jupyter notebooks, 2 audio files and a pickled Logistic Regression model (to demonstrate Gradio's usage beyond transformer models).
The demos here are geared more towards newcomers, as well as those in the early explorative phase of their NLP/ML projects. Gradio offers options for hosting and private deployment, but that's well outside the scope of this post.
It takes just a few lines of code to get a Gradio app up and running, on top of what you need to do to define your NLP/ML model's input and output. The process is even simpler if you use Hugging Face's public Inference API. But I won't take that approach in my examples as I find that Hugging Face's public/free Inference API is relatively slow, and your app could crash if you try to load too many transformer models in one go.
As such, I coded my demos to run off a local machine. To share the app publicly, you just need to change one parameter in the Gradio interface.
1. STANDALONE SENTIMENT ANALYSIS APP
Let's start with one of the simplest examples possible - building a web app for sentiment analysis using Hugging Face's pipeline API. The default Distilbert model in the sentiment analysis pipeline returns two values - a label (positive or negative) and a score (float).
Gradio takes the pain out of having to design the web app from scratch and fiddling with issues like how to label the two outputs correctly. The screen-grab below shows how you can easily adjust the look of the app with a few parameter changes in Gradio:
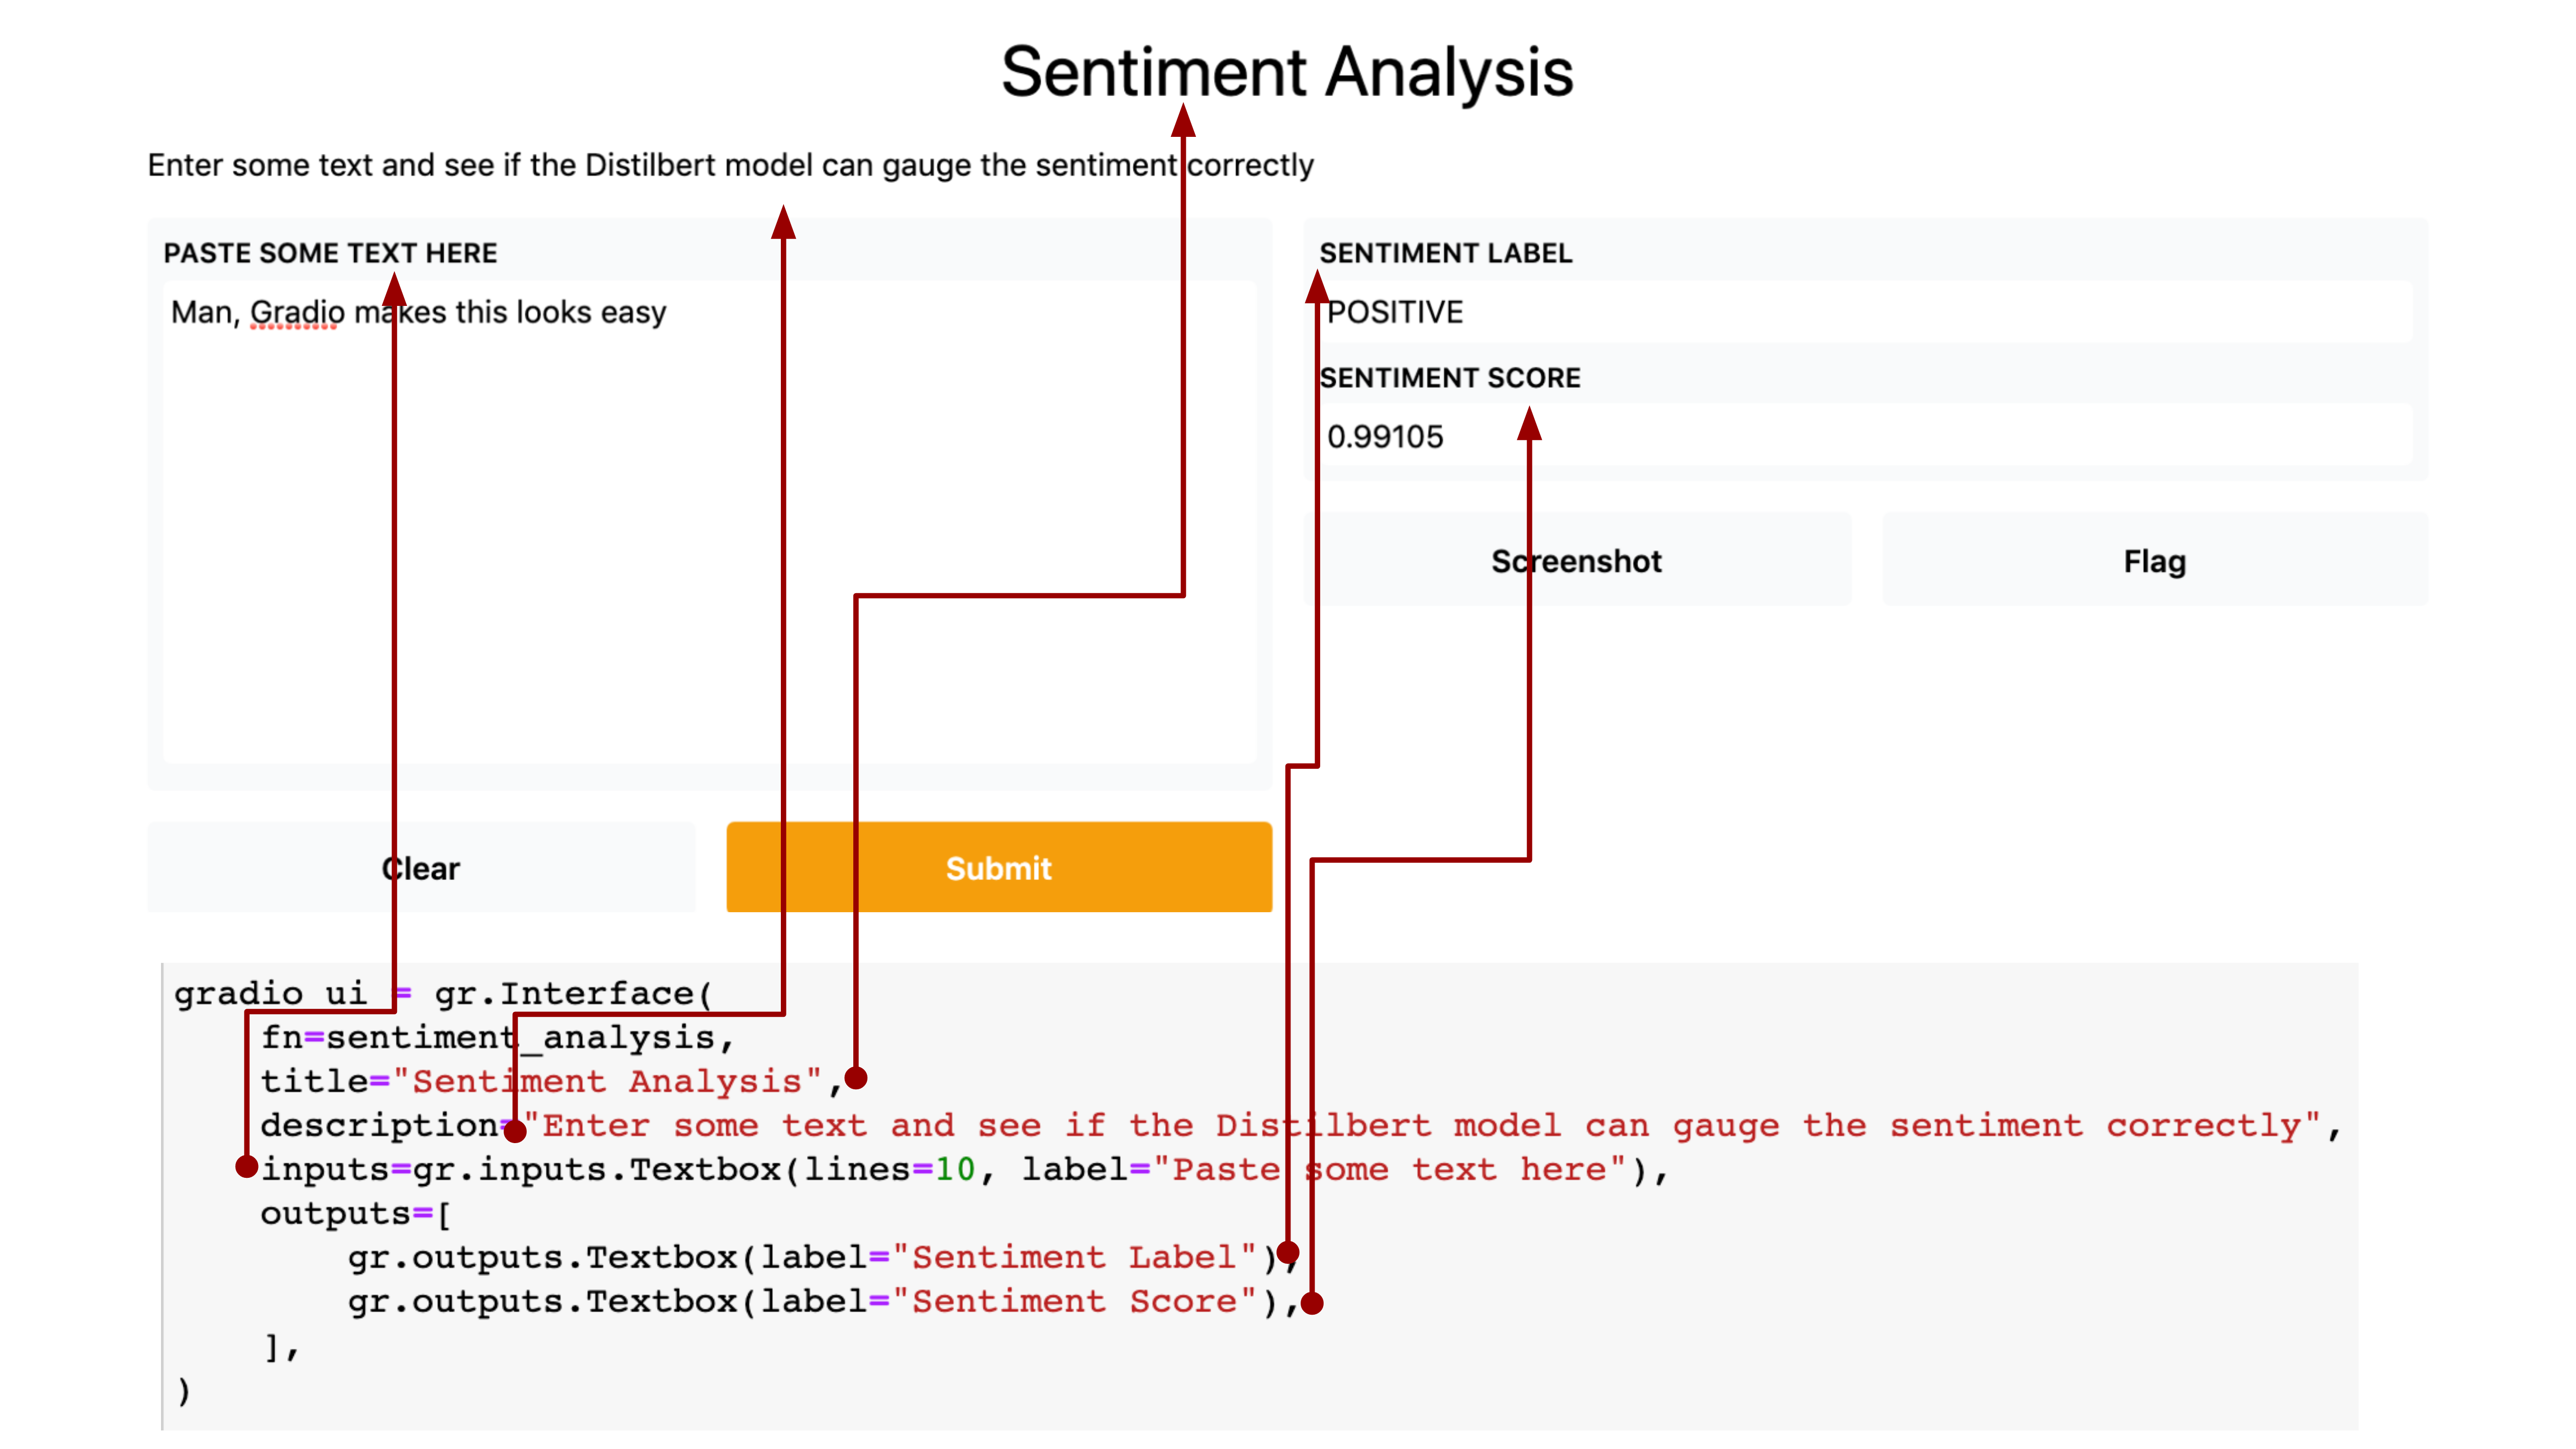 Screen-capture: Chua Chin Hon
And thanks to the close integration between the Gradio and transformers libraries, it won't take more than a few minutes to tweak the code in notebook1.0 to turn the sentiment analysis web app into one for translation, summarization, or zero-shot classification.
2. STANDALONE TROLL TWEET DETECTOR APP
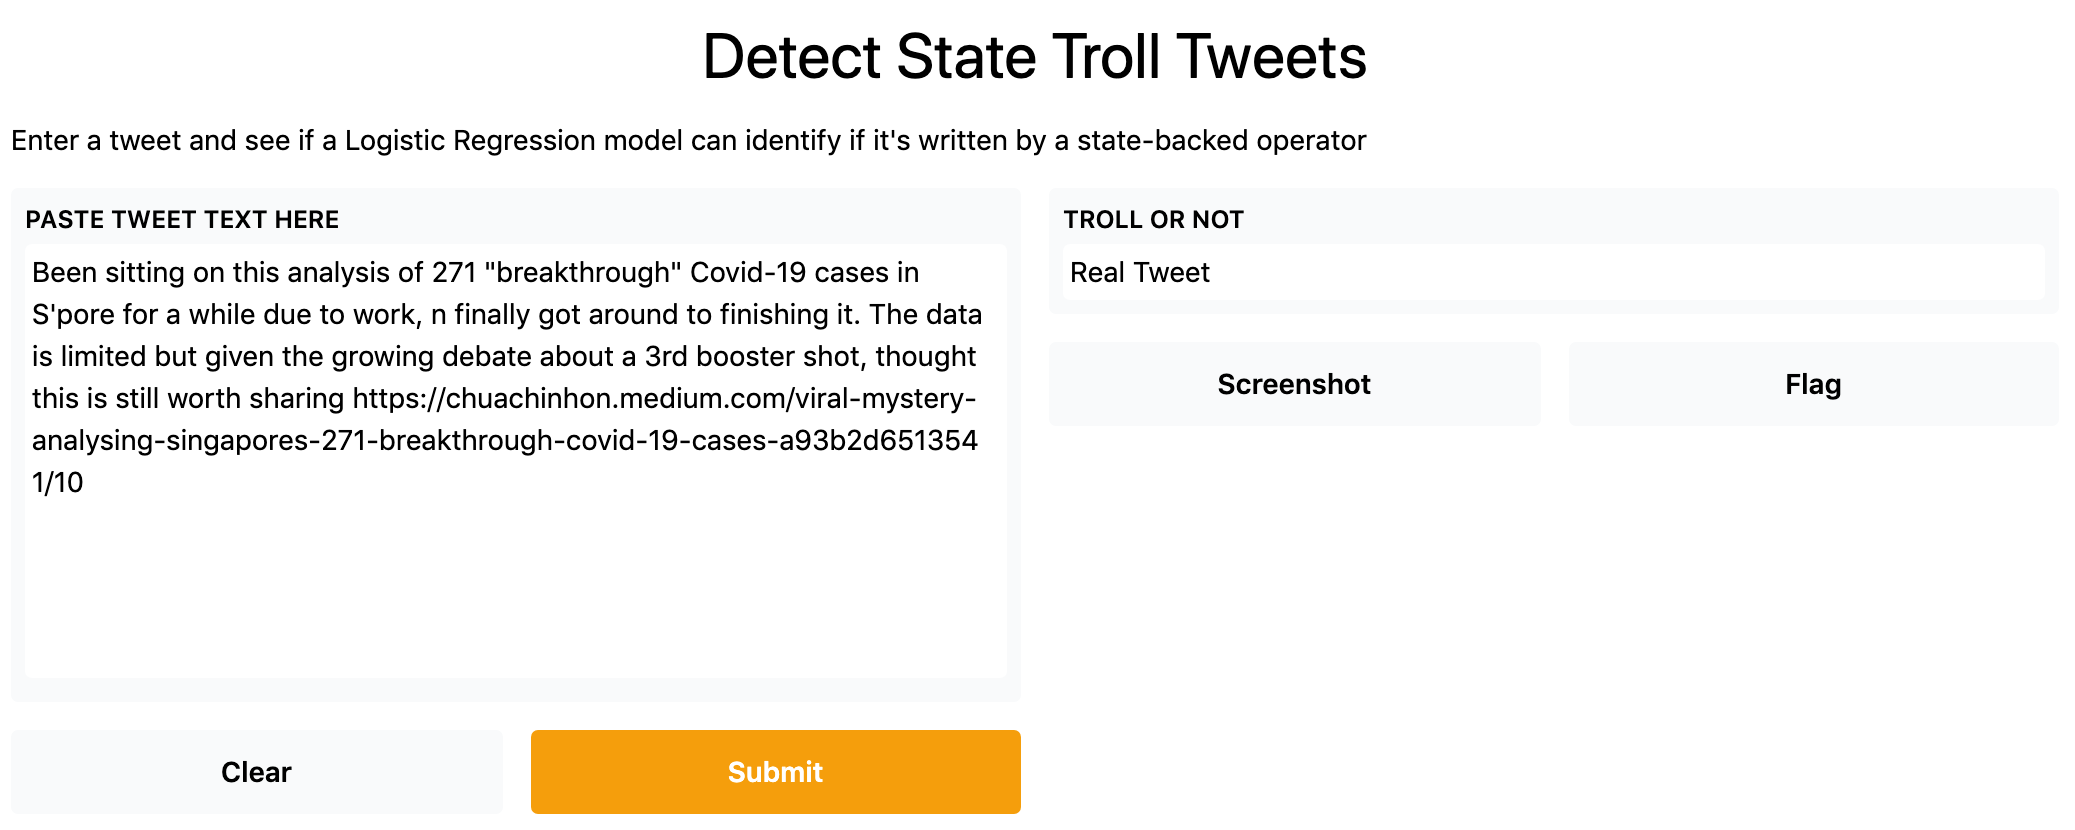
Gradio works just as well with pickled models via standard machine learning libraries like Scikit-learn. In notebook1.1, I loaded a pickled Logistic Regression classifier for trolls tweets that I had built in a previous project, and the Gradio app was up and running in no time:
 Screen-capture: Chua Chin Hon
The Gradio template is barebones, no doubt. But that's all I need at the early stage to see if the model is working as intended, and if the solution is clear to a non-technical audience.
3. GRADIO IN "PARALLEL" - COMPARING 2 SUMMARY MODELS
Of late, it's become practically impossible to keep up with the number of new transformer models available for various NLP tasks. If you are working on a text summarization project, for instance, how do you demonstrate which of the 248 models available on Hugging Face's model hub work better for your use case? Or how would you demonstrate that your own fine-tuned model performs better than another model out there?
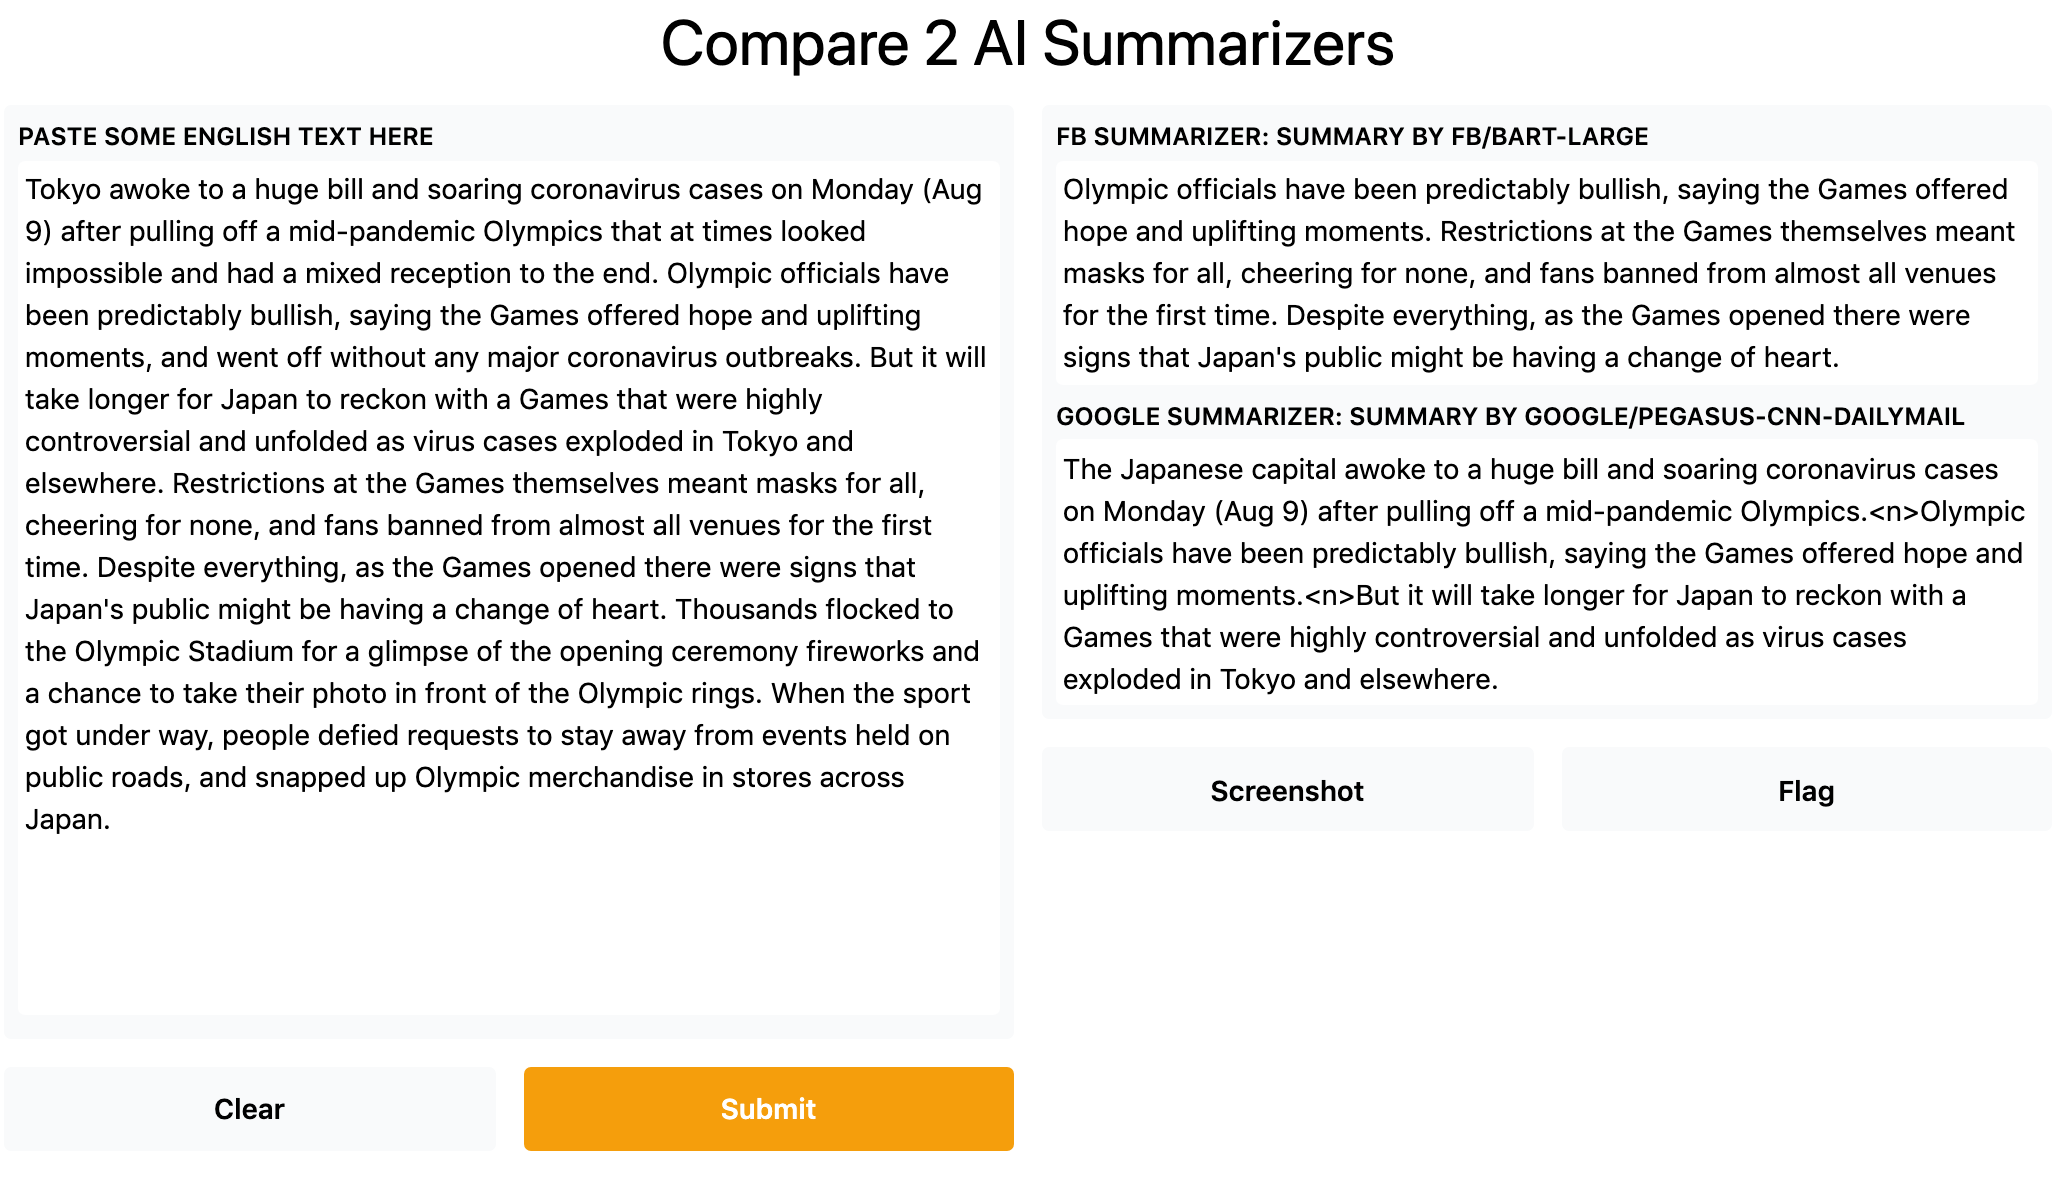
Gradio provides a neat solution by allowing transformer models to be loaded in "parallel" within the same app. This way you can directly compare the different results from one input:
 Screen-capture: Chua Chin Hon
In notebook2.0, I spun up a quick web app to compare the summarization capabilities of two different models: FB's Bart and Google's Pegasus. This is a great way to directly compare the results from multiple models without having to copy out the results from different apps, or switch screens back and forth between two models.
This is also a great way for comparing the performances of text-generation or translation models, where the results from different models can vary quite widely. Gradio doesn't say what's the maximum number of models you can load in parallel at one time, so apply some commonsensical limits as required.
4. GRADIO IN "SERIES" - COMBINING 2 TRANSFORMER MODELS FOR TRANSLATION AND SUMMARIZATION
Another way to leverage the huge number of transformer models out there is by linking them up in "series" - ie, connecting models of different functionalities under one Gradio app.
Notebook3.0 demonstrates how you can build a translator-summarizer that takes in Chinese text and produces a summary of the English translation:
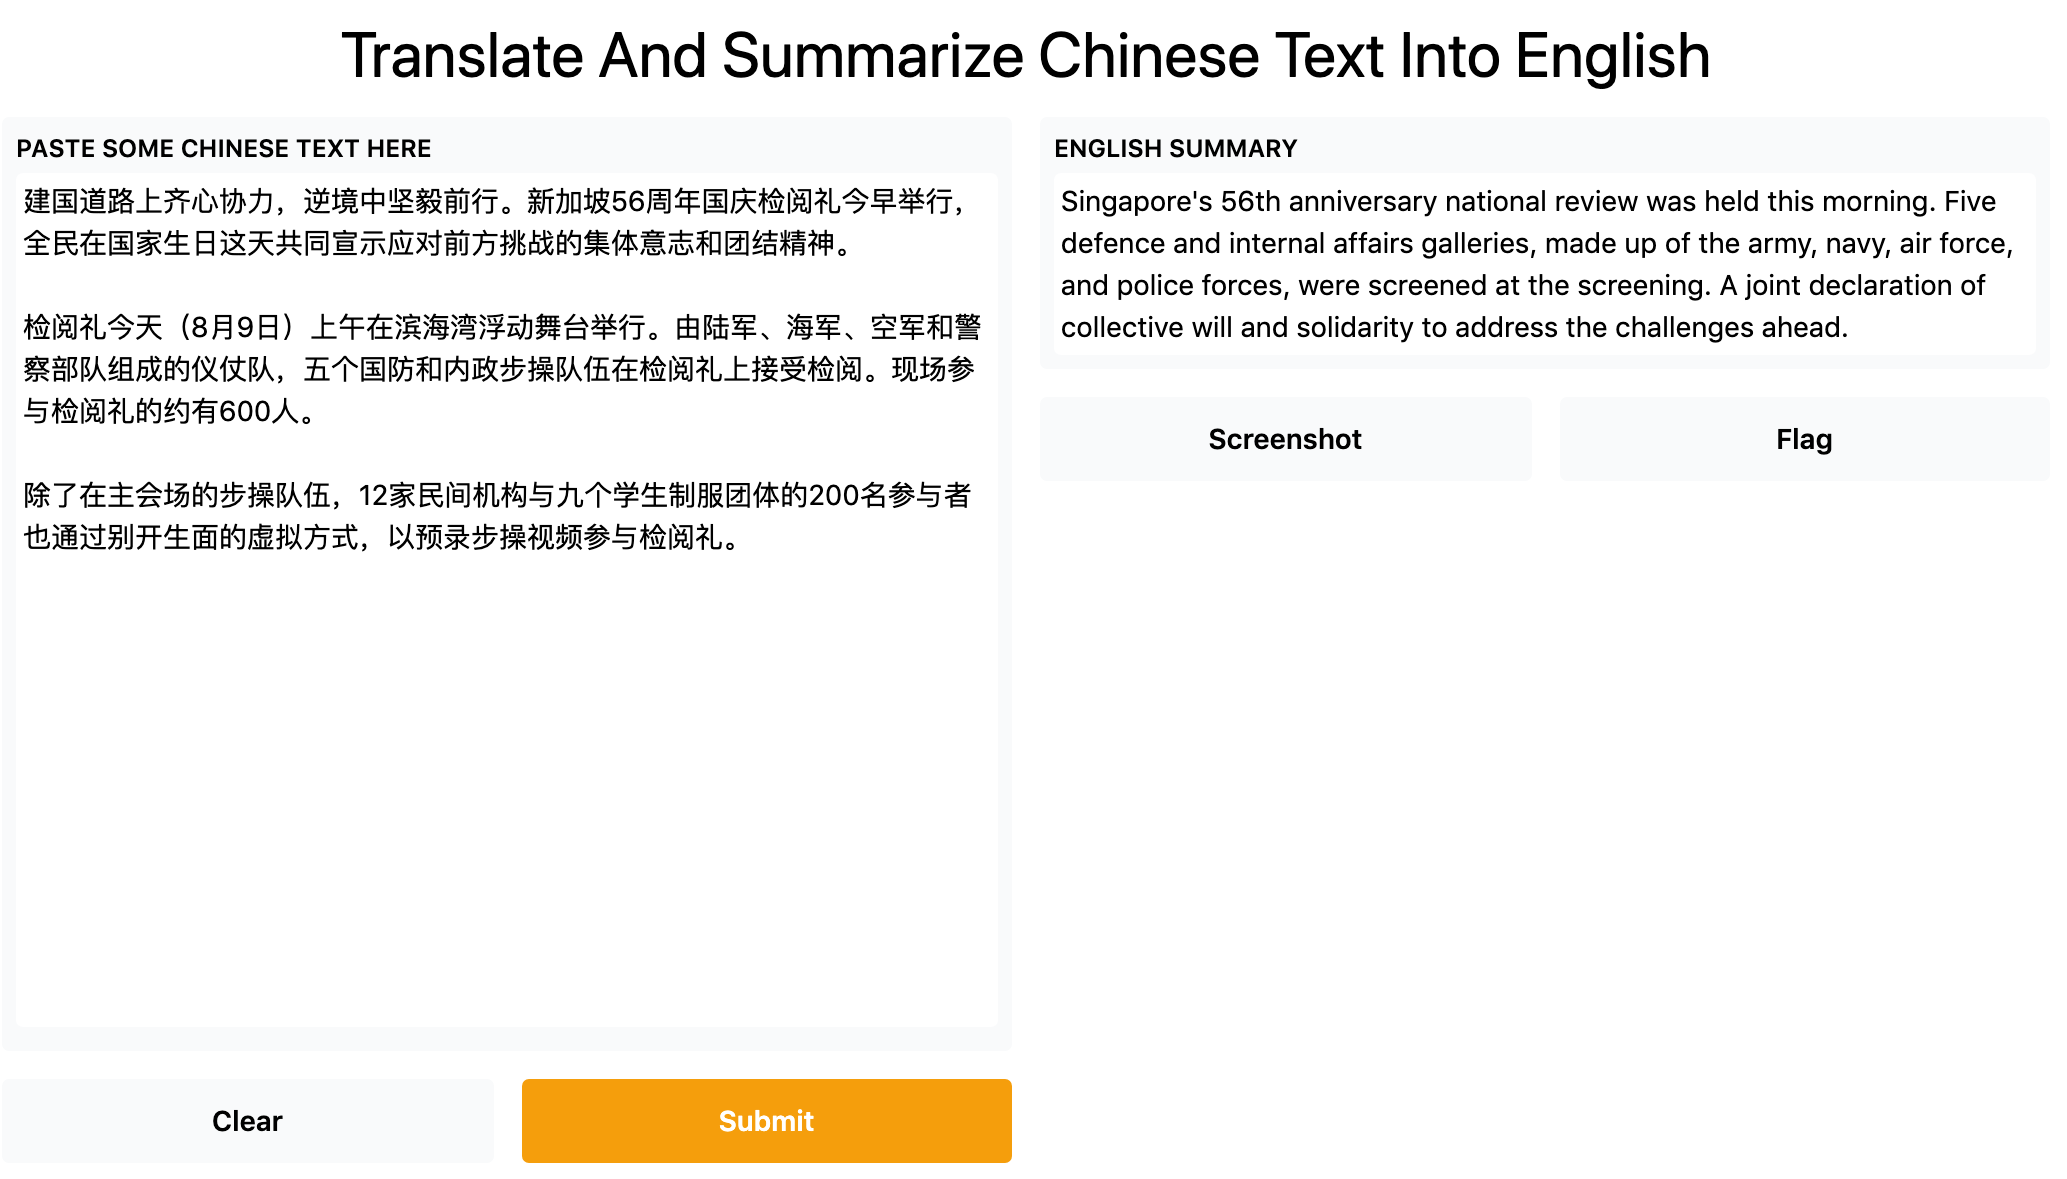 Screen-capture: Chua Chin Hon
The end-result, as the screen-grab above shows, is less than impressive. It is a good reminder of the importance of restraint in these NLP/ML projects - just because something is technically feasible doesn't mean the results will be any good.
While the ability to chain-link multiple transformer models of different functionalities is a very welcomed one, it will take considerably more effort to figure out a combination that works and delivers good results.
5. SPEECH-TO-TEXT "MIXED MEDIA" APP WITH AUDIO INPUT AND TEXT OUTPUT
My final example, in notebook4.0, demos a quick way to build a simple speech-to-text web app using Hugging Face's implementation of Facebook's Wav2Vec2 model.
With the latest version of Gradio, you can easily configure mixed-media apps that take one particular format of inputs, say audio or video, and output them in another format, say, text or numbers. To keep the demo simple, I settled on a speech-to-text app that takes in audio clips and returns a text transcript:
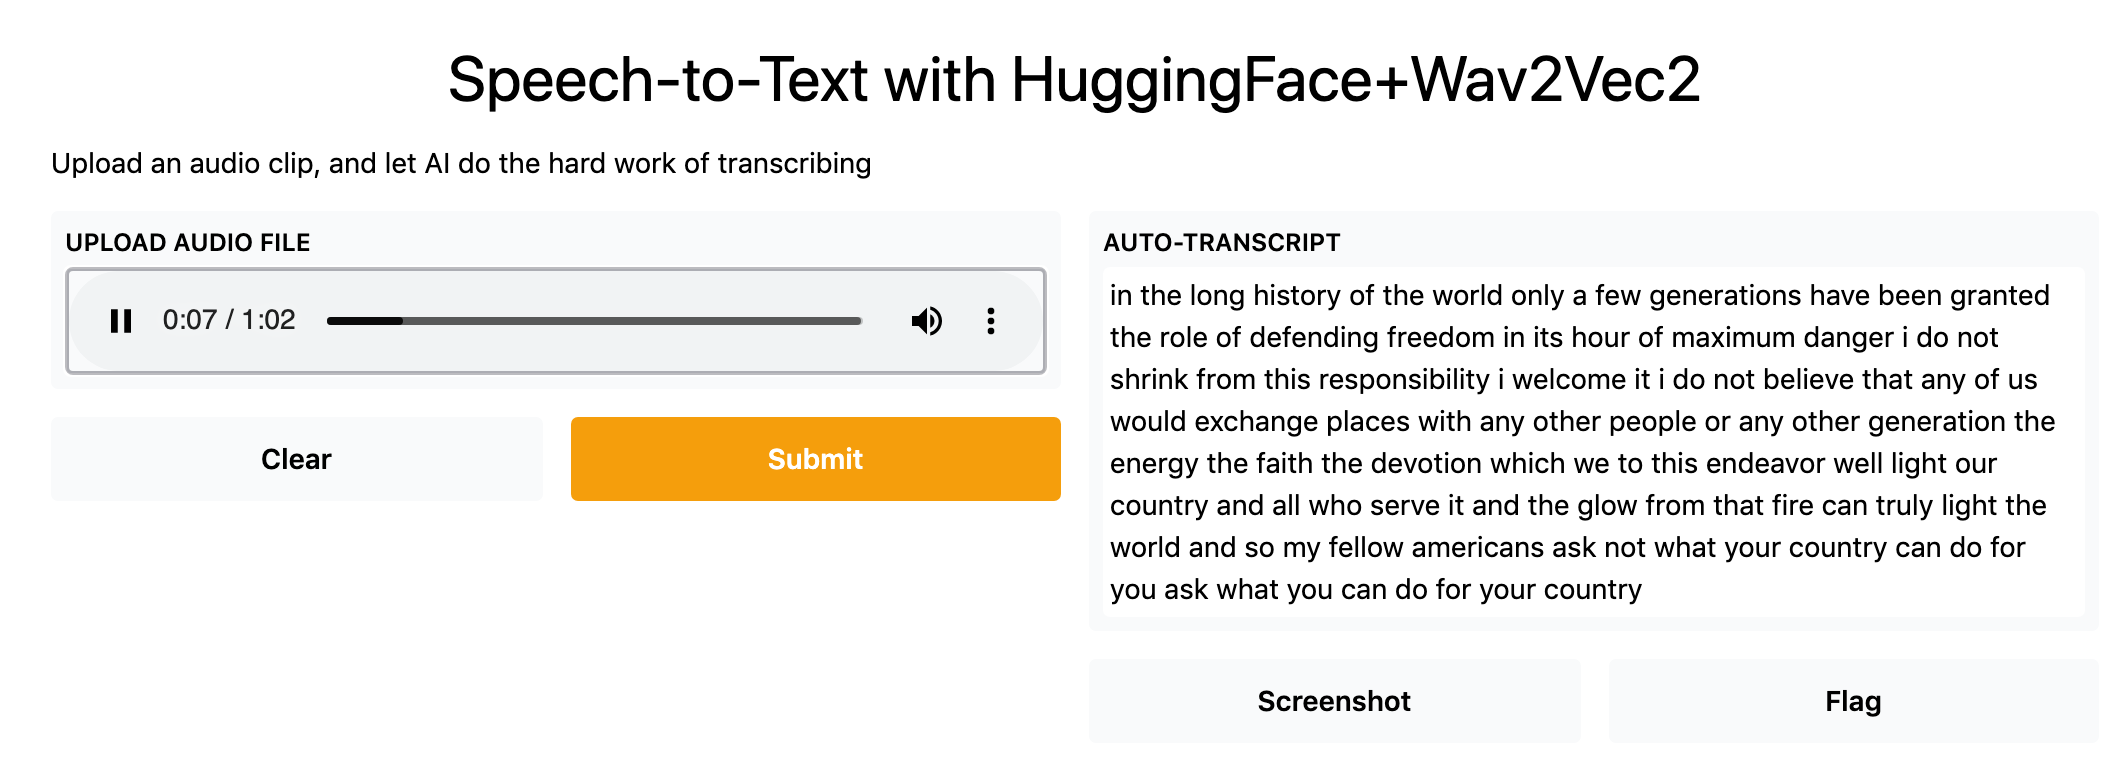 Screen-capture: Chua Chin Hon
It would probably take a newcomer hours, if not days, to create a similar speech-to-text app using Flask and HTML templates, to say nothing of the additional hoops to jump through in deploying correctly to the hosting provider.
With Gradio, the challenge with this particular example lies predominantly in defining a function that would handle longer audio files without out-of-memory issues that would crash the local machine:
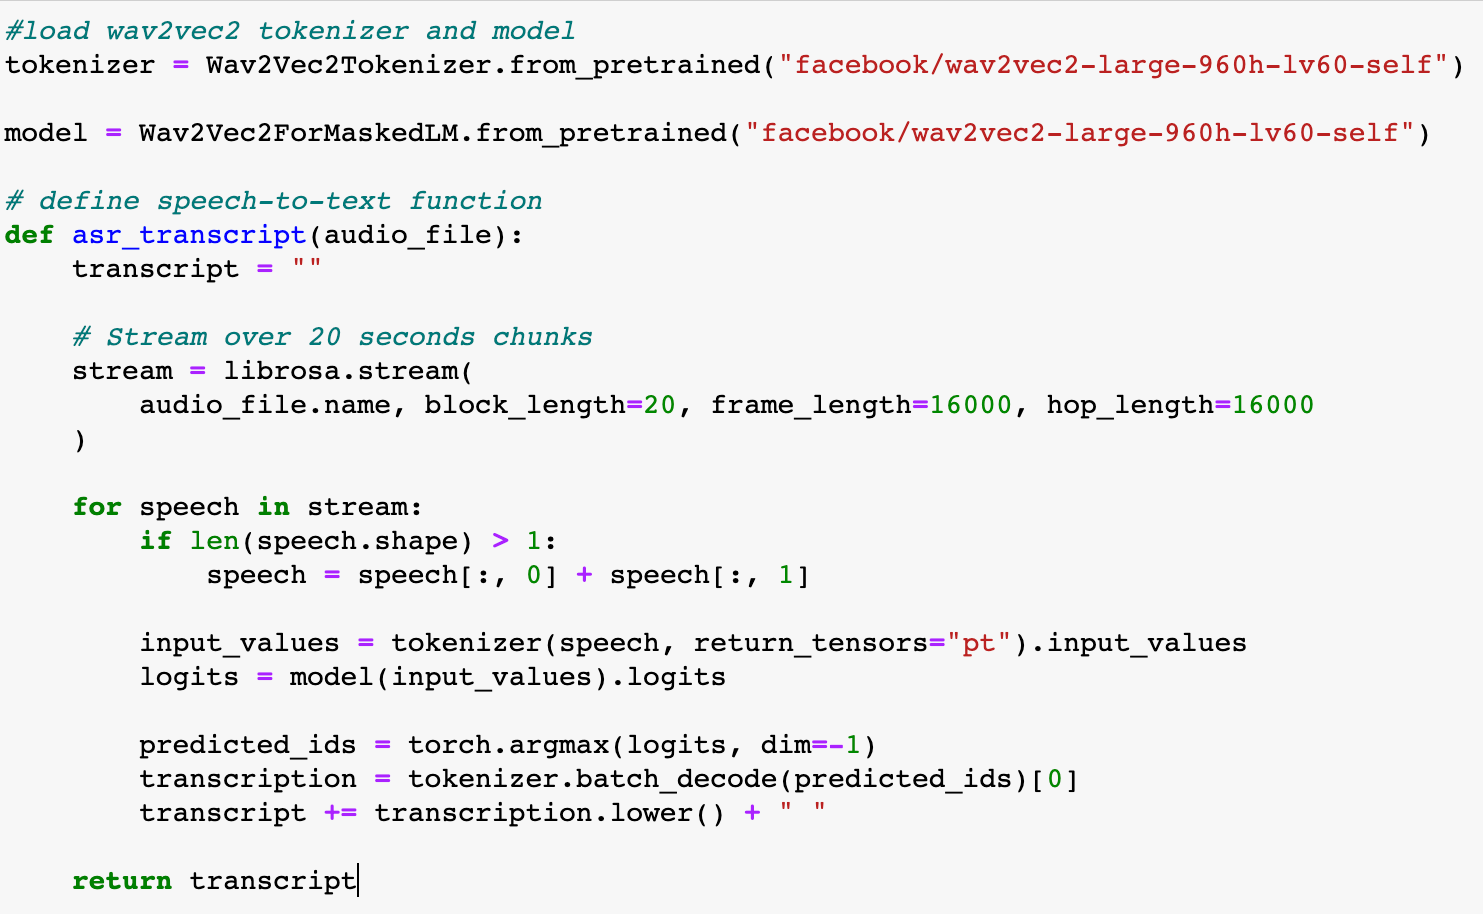 The creation of the app interface practically takes just 1 line of code:
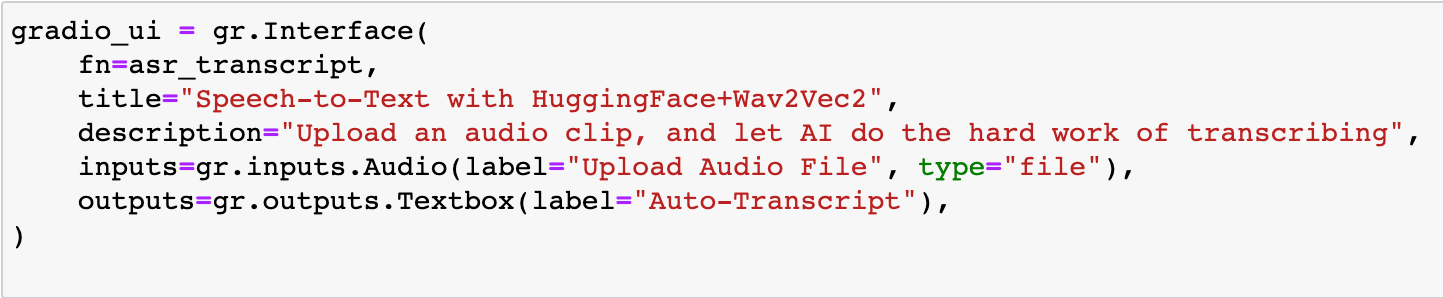 I've included two audio files in the repo that you can try the speech-to-text app with - US President John F Kennedy's famous inauguration speech in 1961, and youth poet Amanda Gorman's poem at the inauguration of US President Joe Biden in 2021.
END NOTES
The growing list of skills that data professionals need in order to be effective is frankly ridiculous. Few, if any, will ever have the time to learn to be as good at data-related coding and analysis skills, as well as front-end development.
Libraries like Gradio help to "compress" that list of desired skills into something more manageable, by freeing up data scientists and analysts from having to spend hours tinkering with Flask and HTML for a simple demo.
In the long run, I think this helps promote greater transparency and accountability in machine learning, as data professionals no longer have any excuse to say that they can't quickly build apps to let others try out the proposed solutions.
And as more people get to test such apps in the early stages, hopefully the biases and ethical issues buried deep in a particular solution's training data and design will be easier to spot.
As always, if you spot mistakes in this or any of my earlier posts, ping me at:
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Chua Chin Hon
AIData ScienceGradioMachine LearningPython
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Machine Learning
Simple + Tested Code = Less Problems
Ern Chow
March 11, 20225 min read
Deep Learning
A possible implementation of IBM's FreaAI
Michael Berk
January 19, 20227 min read
Programming
The window function is a must know in SQL interviews now, though it has just been available on, for example, MySQL 8.0 since its release on
Sherwin Zheng
September 25, 20206 min read
Data Engineering
The exact tools I'm learning, the projects I'm building, and the mistakes I'm already expecting to make
Ibrahim Salami
May 16, 20269 min read
Machine Learning
How To Get High Performing Models In Competitions
Louise Ferbach
October 2, 20207 min read
Machine Learning
Introduction of SMOTE
Jeremy Zhang
February 8, 20203 min read
Artificial Intelligence
Including hands-on calculations using the cosine similarity formula
Vinicius Monteiro
October 13, 20214 min read
Data Science
Hands-on tutorial for converting daily data to weekly
Diana Rozenshteyn
March 12, 20217 min read
Machine Learning
Understand basic principles of underfitting and overfitting and why you should use particular techniques to deal with them
Dmytro Nikolaiev (Dimid)
November 2, 202110 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close