保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Machine Learning
Are Your ML Experiments a Mess? Here’s the Fix
A hands-on guide to tracking experiments, logging models, and reproducing results with ML Flow.
Alex Davis
July 21, 20267 min read
 Photo by Stephen Dawson via Unsplash
Imagine you are building a new model. You get decent baseline results with a simple model, but try to improve performance with more advanced models. During development, your PM acquires some additional data that could prove useful, and can now revert to a simpler model. After extensive hyperparameter tuning, you consult your team and they advise you to optimize for a different performance metric. After you finally deliver a model, your stakeholder changes the direction of the project, requiring a complete overhaul.
This is a common situation for data scientists, especially those with cross-collaborative teams, stakeholders, and changing priorities. Model development can quickly become a wild goose chase of figuring out requirements, data sources, performance metrics, etc. Through all of this chaos, it is critical that teams are able to not only keep track of all phases of model development, but are also able to reproduce results quickly. You need to model governance.
Model Governance
Model governance refers to the framework by which a team maintains controls around its use of models, including experiment tracking, version control, reproducibility, etc. It is a critical capability that many teams do not consider until their models are already in production. It is important to have a process to effectively track development efforts, models in production, and data leveraged so that organizations can ensure quality, compliance, and monitor machine learning integration.
Learn this step by step with the interactive Machine Learning roadmap.
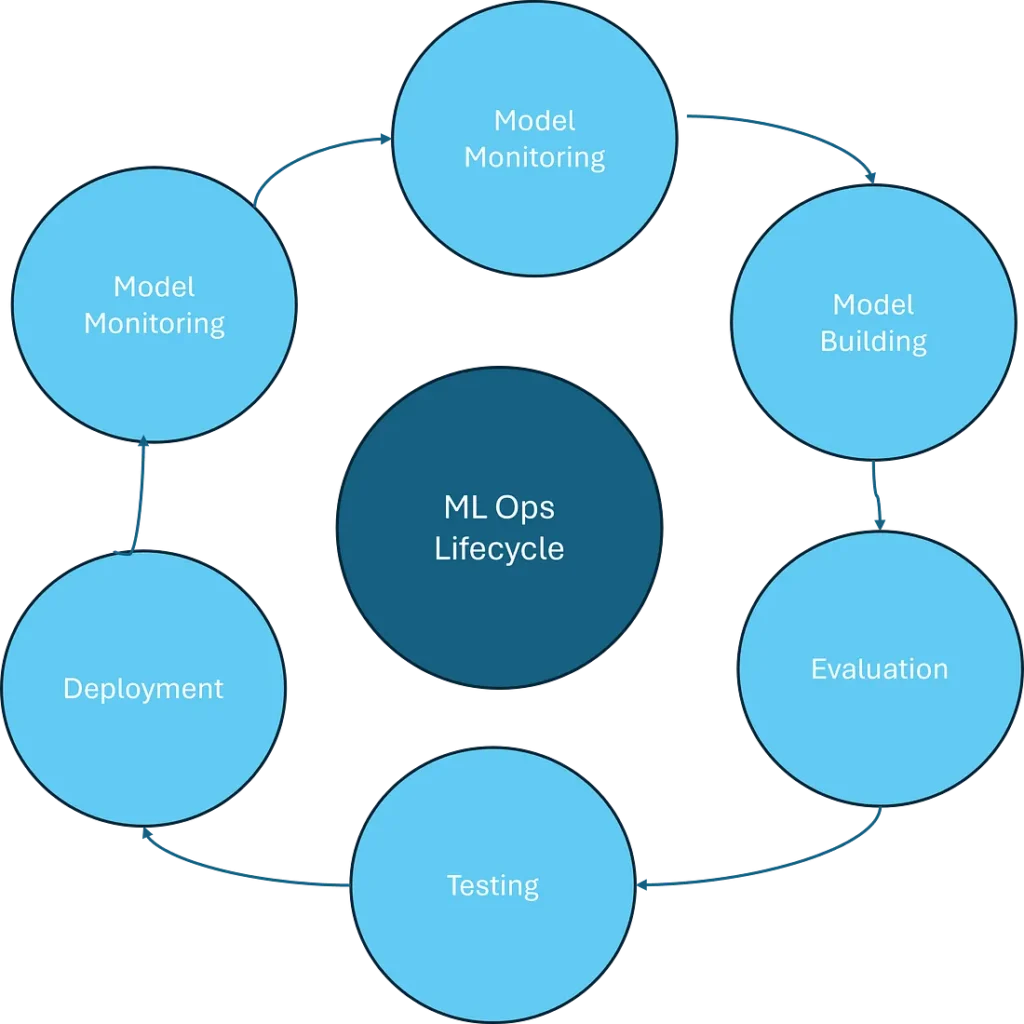 Image by Author
To ensure that the right models are in production, we need a way to manage various models and versions, track performance metrics, and reproduce results. This is where ML Flow comes in. ML Flow is an open-source ML Ops platform that allows flexible model development, deployment, and management by streamlining logging and tracking of models, metrics, and more.
This article will give an introduction into how to install ML Flow, create experiments, log models and more.
···
ML Flow Tutorial
Model Development
For our model, we will construct a basic linear regression model. This is a model to predict the annual salary of data professionals using inputs that include job title, company size, etc.
See data here:https://www.kaggle.com/datasets/ruchi798/data-science-job-salaries (CC0: Public Domain). I slightly modified the data to reduce the number of options for certain features. Please note that this is a very poor model. We are using it only to demonstrate ML Flow.
python
#define independent and dependent features
X = salary_data.drop(columns = 'salary_in_usd')
y = salary_data['salary_in_usd']

#split between training and testing sets
X_train, X_test, y_train, y_test = train_test_split(
  X, y, random_state = 104, test_size = 0.2, shuffle = True)

#define parameters separately to log
params = {"fit_intercept": True,
         "positive": False}

#fit linear regression model
regr = linear_model.LinearRegression(**params)
regr.fit(X_train, y_train)

#make predictions
y_pred = regr.predict(X_test)
Note that we define the model parameters separately. This will be important when we incorporate ML Flow.
Logging Model with ML Flow
To start using ML Flow, you can navigate to the terminal and pip install it as a module. Next, run the server command to host a local server on your machine and leverage the ML Flow user interface.
powershell
pip install mlflow
powershell
mlflow server --host 127.0.0.1 --port 8080
Now that we have ML Flow installed and our local server running, we can log our model. Before logging a model, we need to start a new ‘experiment’. Think of this as a project, a bin where we will log and store all related models, metrics, data. etc. In the code below, we start a new experiment titled “Logging Example”.
An experiment consists of runs, which contain the model used, its parameters, metrics, artifacts, and anything else that you choose to log. As you log more runs, we can track our progress and compare the performance of the various models developed.
Using the code below, we:
- Start the experiment
- Start a run titled “salary_baseline_regression”
- Log the adjusted R2 as a metric
- Log the model’s parameters
- Set a tag for the model
- Log the actual model
python
import mlflow
from mlflow.models import infer_signature

#set tracking uri
mlflow.set_tracking_uri(uri = "http://127.0.0.1:8080")

#create a new MLflow Experiment
mlflow.set_experiment("Logging Example")

#start an MLflow run
with mlflow.start_run(run_name = "salary_baseline_regression") as run:

    # Log the loss metric
    mlflow.log_metric("Adjusted R2", r2_score(y_test, y_pred))

    #log the hyperparameters
    mlflow.log_params(params)

    #set a tag that we can use to remind ourselves what this run was for
    mlflow.set_tag("Model Type", "Baseline")

    #log the model
    model_info = mlflow.sklearn.log_model(
        sk_model = regr,
        artifact_path = 'model',
        signature = infer_signature(X_train, regr.predict(X_train)),
        input_example = X_train,
        registered_model_name = "salary_baseline_regression")
After running, you can navigate to the ML Flow UI using the following link:http://localhost:8080/
Navigating ML Flow UI
The ML Flow UI will open on the ‘Experiments’ tab. Here, we can see the experiment we created, the run for our baseline model, the model used, as well as metrics and parameters we logged.
Note that the metrics and parameters may not be displayed at first. You can add them to the table using the ‘Columns’ drop down.
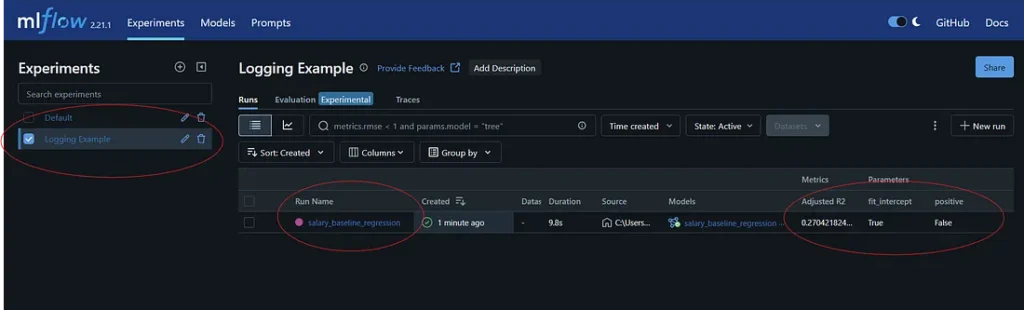 Image by Author
Next, click on the run name to navigate to the run view. This brings us to the overview tab where we can clearly see everything we have logged (model, R2 metric, model parameters).
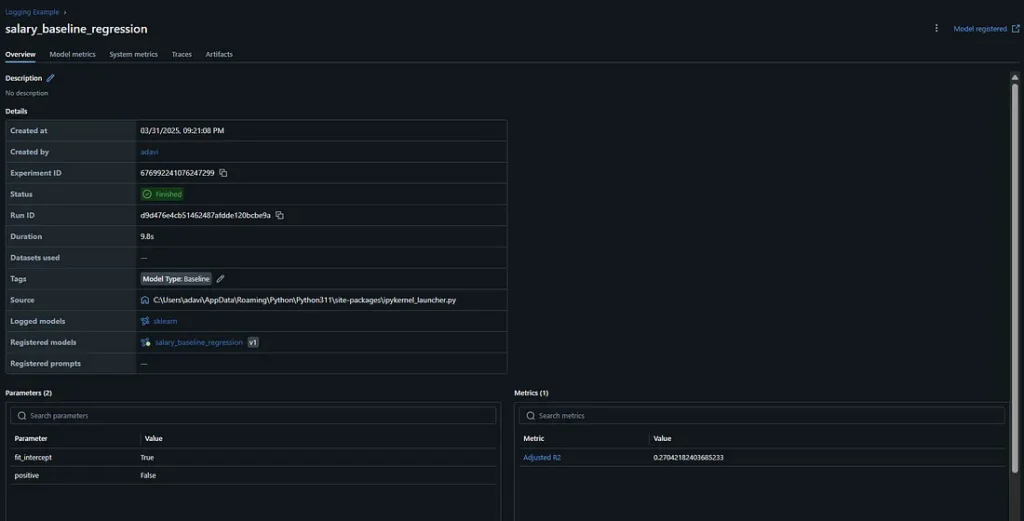 Image by Author
Next, click on the model name or navigate to the model view. Here we can view our model, add descriptions and/or tags, and keep track of it’s versions. The version number will increase every time we create a run using this model.
The tags and descriptions are helpful for overall documentation and to tag models in development vs. under review vs. in production.
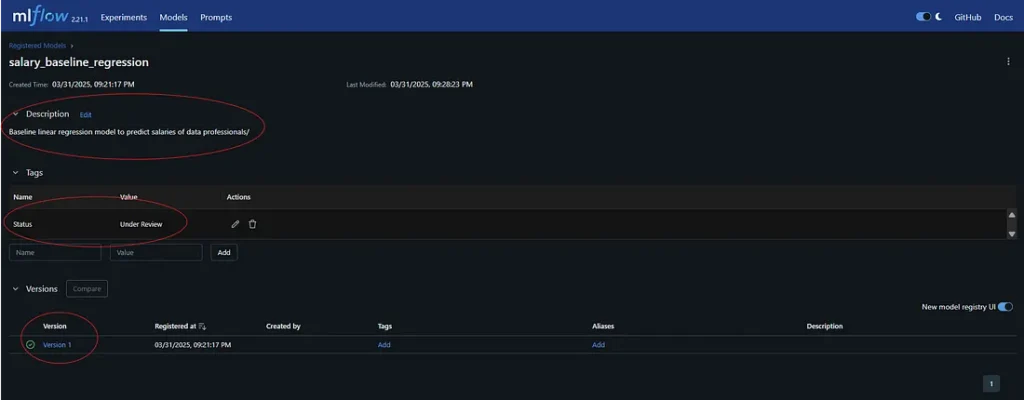 Image by Author
So far, we’ve seen how to create experiments and runs, as well as log models, metrics, parameters, etc. These are the very basics of ML Flow. Now let’s explore more options to automate some of the process and make best use out of ML Flow.
Advanced Logging Options
There are likely many metrics we would like to track, which will vary depending on the model and approach. Adding and removing metrics every time we change our approach can be laborious. However, we can feed ML Flow our test data and results to automate the logging of metrics and streamline our process.
First, let’s save a copy of our test data and the results of our model.
python
#merge salaries and predictions for mlfow
eval_data = X_test.copy()
eval_data["salary"] = y_test
Next, we give ML Flow our data and tell it what our target variable is (salary). Now we can add a few things to our ML Flow process:
- Log our data to keep track of model inputs
- Use mlflow.evaluate() to automate logging the model metrics
We can also log ‘artifacts’, which can be many things. During development and evaluation, it may be helpful to develop visualizations that reflect model performance. We can log those as well using mlflow.log_artifact().
python
#set tracking uri
mlflow.set_tracking_uri(uri = "http://127.0.0.1:8080")

#create an instance of a PandasDataset
dataset = mlflow.data.from_pandas(
    eval_data, source = 'kaggle', name = "ds_salaries", targets = "salary")

#create a new MLflow Experiment
mlflow.set_experiment("Salary Prediction")

#start an MLflow run
with mlflow.start_run(run_name = "salary_baseline_regression") as run:

    #log the dataset
    mlflow.log_input(dataset, context = "training")

    #log the hyperparameters
    mlflow.log_params(params)

    #log pngs
    mlflow.log_artifact('Result.png')

    #set a tag that we can use to remind ourselves what this run was for
    mlflow.set_tag("Model Type", "Baseline")

    #log the model
    model_info = mlflow.sklearn.log_model(
        sk_model = regr,
        artifact_path = 'model',
        signature = infer_signature(X_train, regr.predict(X_train)),
        input_example = X_train,
        registered_model_name = "salary_baseline_regression")
    model_uri = mlflow.get_artifact_uri("model")

    #create the model uri and evalute the model
    result = mlflow.evaluate(model = model_uri, data = dataset, model_type = "regressor", evaluators=["default"])
Now, if we navigate back to the ML Flow UI and click on the run, we can see that there are several metrics we are tracking.
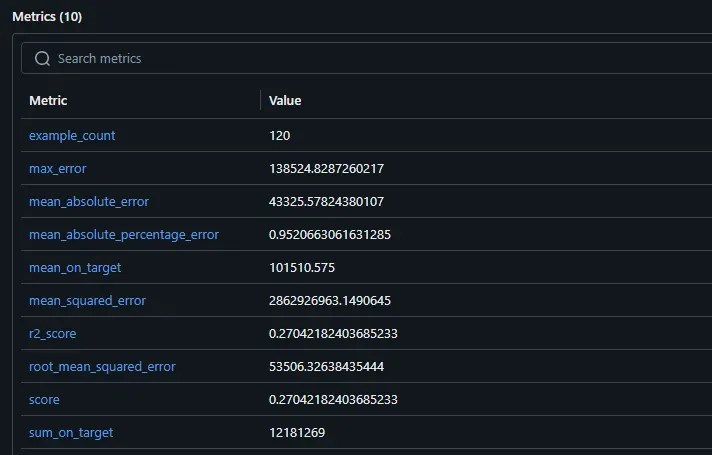 Image by Author
And if we want to evaluate multiple models in a run, we can compare their performance side-by-side using the automated visualizations below.
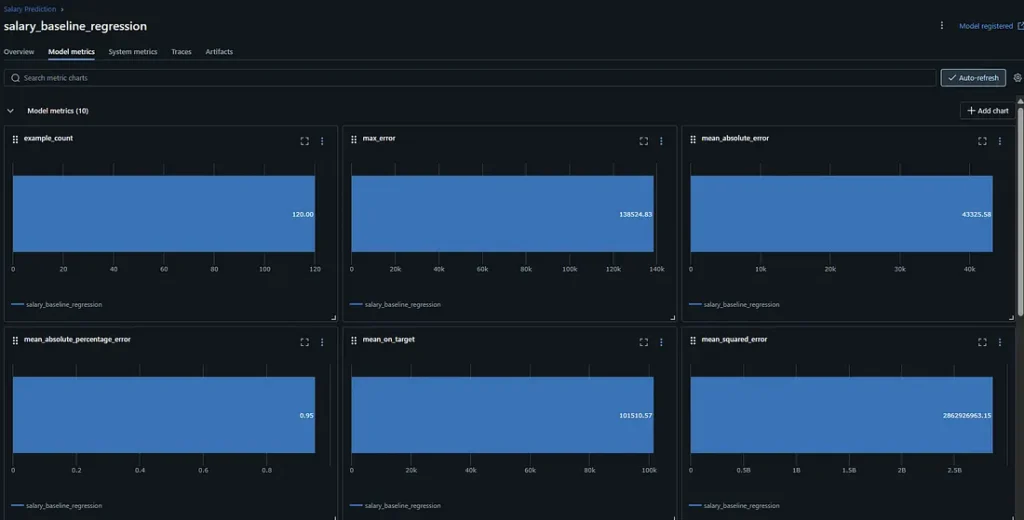 Image by Author
To view the visualizations you logged, navigate to the artifacts view.
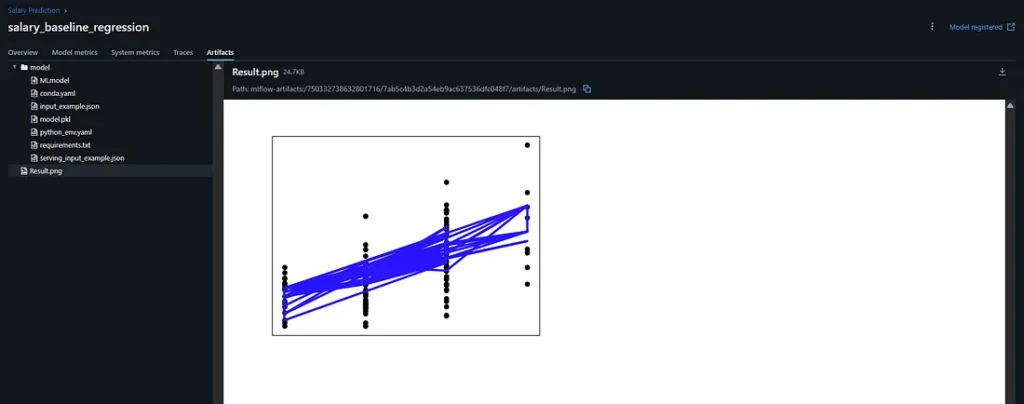 Image by Author
Lastly, we can now view our our data inputs and their types. It is best to log datasets as we drop or add new features, sources, etc.
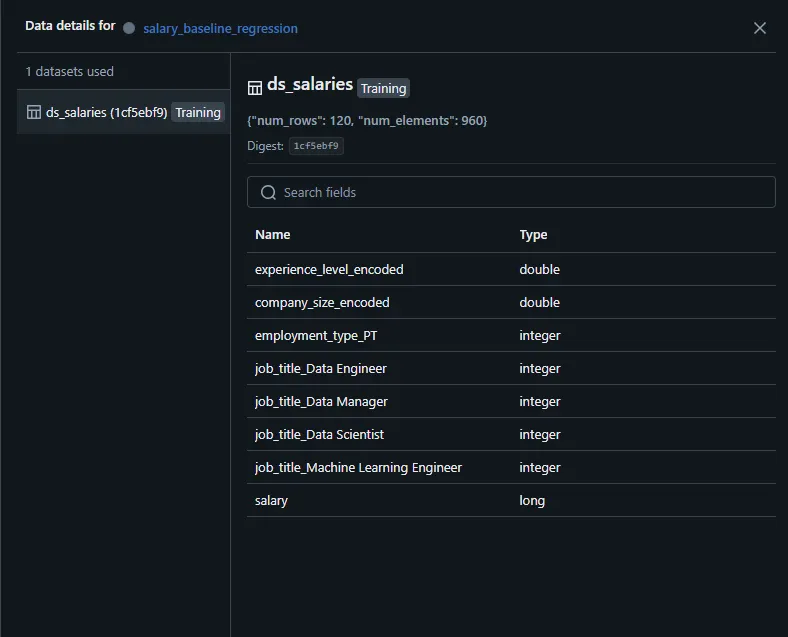 Image by Author
Recalling ML Flow Models
To reproduce a model that we have logged, we can easily recall models from ML Flow using the model name and version. This can also be used to retrain models that are currently in production.
python
model_name = "salary_baseline_regression"
model_version = "latest"

# Load the model from the Model Registry
model_uri = f"models:/{model_name}/{model_version}"
model = mlflow.sklearn.load_model(model_uri)
Databricks Integration
If you are (like me) a fan of Databricks, ML Flow is fully integrated within the platform. No need to run ML Flow locally, as Databricks integrates the ML Flow UI within their 'Experiments' view. It also includes additional features like tracking for generative AI applications, agents, and integrates AutoML for model optimization. See full documentation here: https://docs.databricks.com/aws/en/mlflow/
···
Conclusion
In conclusion, model governance is a must-have capability for any organization to ensure quality and compliance. Tracking and monitoring tools like ML Flow offer solutions to streamline model governance processes and fully manage model development and deployment.
···
I hope you have enjoyed my article! Please feel free to comment, ask questions, or request other topics.
Connect with me on LinkedIn:https://www.linkedin.com/in/alexdavis2020/
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Alex Davis
Data ScienceML FlowMlopsModel DevelopmentModel Governance
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Data Science
The Dos and Don'ts of data engineering
Nam Nguyen
August 6, 20216 min read
Machine Learning
A deep dive into multi-threading and multi-processing with Python and how they are related to concurrency and parallelism
Giorgos Myrianthous
January 21, 202210 min read
Artificial Intelligence
So, you know you need some machine learning/AI development. Why not just do it yourself? Well, the short answer is that specialists have...
Daniel Shapiro, PhD
June 27, 201711 min read
Artificial Intelligence
How to use recurrent neural networks to predict stock prices.
Soner Yıldırım
July 9, 20207 min read
Data Science
Non-linear dimensionality reduction using kernel PCA
Rukshan Pramoditha
December 20, 20226 min read
Deep Learning
I translated a scientific paper into python to check whether it can help in reducing space and time consumption
Prashant Mudgal
December 29, 202010 min read
Deep Learning
Use online courses to create your curriculum
Pascal Janetzky
June 14, 20217 min read
Machine Learning
From casinos to AI: unveiling the power of Monte Carlo methods in complex environments
Slava Efimov
May 23, 202413 min read
Artificial Intelligence
A comprehensive practical guide
Soner Yıldırım
March 9, 20215 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close