保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Artificial Intelligence
Image Captioning Paper Walkthrough: Show and Tell
Implementing one of the earliest neural image caption generator models with PyTorch.
Muhammad Ardi Putra
February 3, 202517 min read
 Photo by Ståle Grut on Unsplash
Introduction
Natural Language Processing and Computer Vision used to be two completely different fields. Well, at least back when I started to learn machine learning and deep learning, I feel like there are multiple paths to follow, and each of them, including NLP and Computer Vision, directs me to a completely different world. Over time, we can now observe that AI becomes more and more advanced, with the intersection between multiple fields of study getting more common, including the two I just mentioned.
Today, many language models have capability to generate images based on the given prompt. That's one example of the bridge between NLP and Computer Vision. But I guess I'll save it for my upcoming article as it is a bit more complex. Instead, in this article I am going to discuss the simpler one: image captioning. As the name suggests, this is essentially a technique where a specific model accepts an image and returns a text that describes the input image.
One of the earliest papers in this topic is the one titled "Show and Tell: A Neural Image Caption Generator " written by Vinyals et al. back in 2015 [1]. In this article, I will focus on implementing the deep learning model proposed in the paper using PyTorch. Note that I won't actually demonstrate the training process here as that's a topic on its own. Let me know in the comments if you want a separate tutorial on that.
Image Captioning Framework
Generally speaking, image captioning can be done by combining two types of models: the one specialized to process images and another one capable of processing sequences. I believe you already know what kind of models work best for the two tasks - yes, you're right, those are CNN and RNN, respectively. The idea here is that the CNN is utilized to encode the input image (hence this part is called encoder), whereas the RNN is used for generating a sequence of words based on the features encoded by the CNN (hence the RNN part is called decoder).
It is discussed in the paper that the authors attempted to do so using GoogLeNet (a.k.a., Inception V1) for the encoder and LSTM for the decoder. In fact, the use of GoogLeNet is not explicitly mentioned, yet based on the illustration provided in the paper it seems like the architecture used in the encoder is adopted from the original GoogLeNet paper [2]. The figure below shows what the proposed architecture looks like.
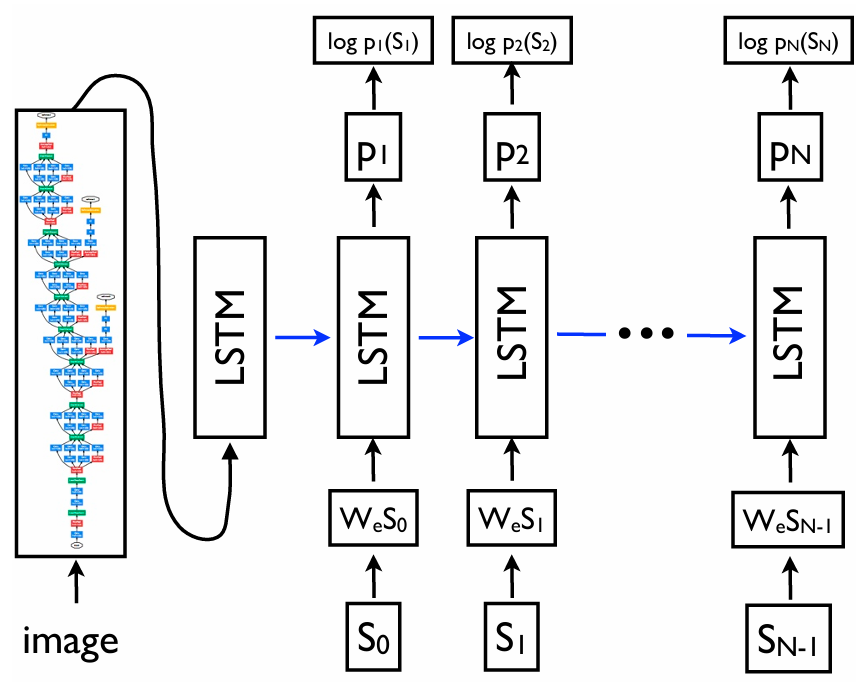 Figure 1. The image captioning model proposed in [1], where the encoder part (the leftmost block) implements the GoogLeNet model [2].
Talking more specifically about the connection between the encoder and the decoder, there are several methods available for connecting the two, namely init-inject , pre-inject , par-inject and merge , as mentioned in [3]. In the case of the Show and Tell paper, authors used pre-inject , a method where the features extracted by the encoder are perceived as the 0th word in the caption. Later in the inference phase, we expect the decoder to generate a caption based solely on these image features.
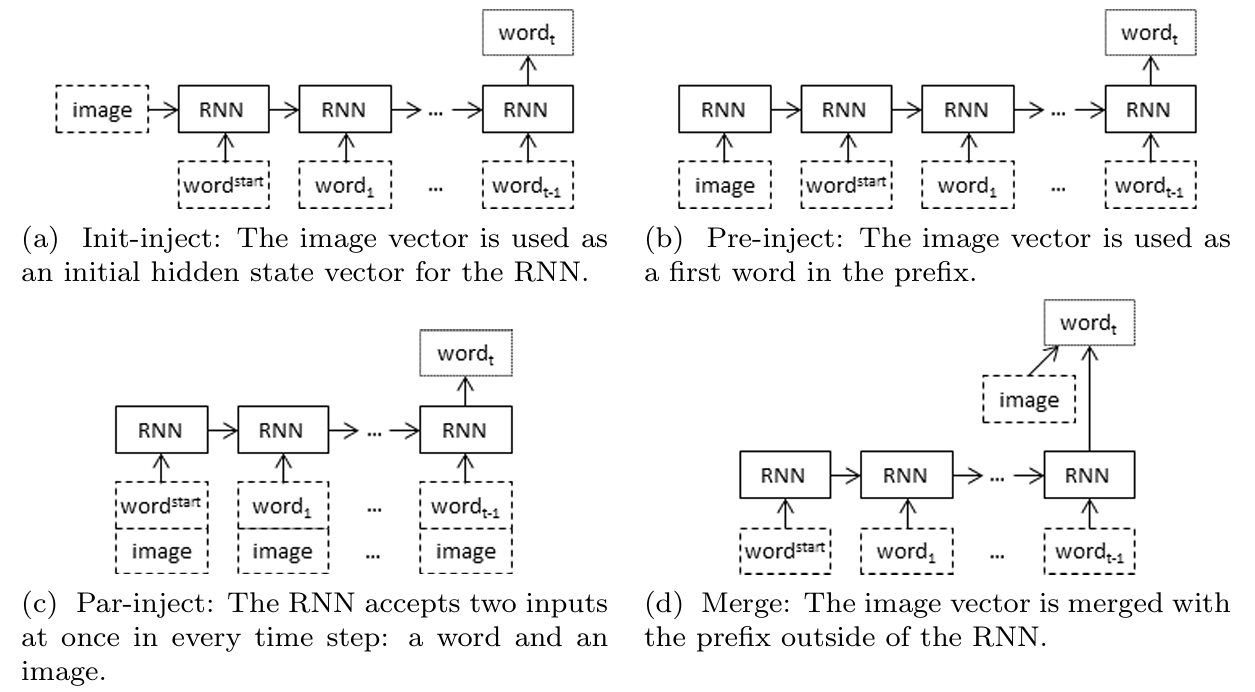 Figure 2. The four methods possible to be used to connect the encoder and the decoder part of an image captioning model [3]. In our case we are going to use the pre-inject method (b).
As we already understood the theory behind the image captioning model, we can now jump into the code!
Implementation
I'll break the implementation part into three sections: the Encoder, the Decoder, and the combination of the two. Before we actually get into them, we need to import the modules and initialize the required parameters in advance. Look at the Codeblock 1 below to see the modules I use.
python
# Codeblock 1
import torch  #(1)
import torch.nn as nn  #(2)
import torchvision.models as models  #(3)
from torchvision.models import GoogLeNet_Weights  #(4)
Let's break down these imports quickly: the line marked with #(1) is used for basic operations, line #(2) is for initializing neural network layers, line #(3) is for loading various deep learning models, and #(4) is the pretrained weights for the GoogLeNet model.
Talking about the parameter configuration, EMBED_DIM and LSTM_HIDDEN_DIM are the only two parameters mentioned in the paper, which are both set to 512 as shown at line #(1) and #(2) in the Codeblock 2 below. The EMBED_DIM variable essentially indicates the feature vector size representing a single token in the caption. In this case, we can simply think of a single token as an individual word. Meanwhile, LSTM_HIDDEN_DIM is a variable representing the hidden state size inside the LSTM cell. This paper does not mention how many times this RNN-based layer is repeated, but based on the diagram in Figure 1, it seems like it only implements a single LSTM cell. Thus, at line #(3) I set the NUM_LSTM_LAYERS variable to 1.
python
# Codeblock 2
EMBED_DIM       = 512    #(1)
LSTM_HIDDEN_DIM = 512    #(2)
NUM_LSTM_LAYERS = 1      #(3)

IMAGE_SIZE      = 224    #(4)
IN_CHANNELS     = 3      #(5)

SEQ_LENGTH      = 30     #(6)
VOCAB_SIZE      = 10000  #(7)

BATCH_SIZE      = 1
The next two parameters are related to the input image, namely IMAGE_SIZE (#(4)) and IN_CHANNELS (#(5)). Since we are about to use GoogLeNet for the encoder, we need to match it with its original input shape (3×224×224). Not only for the image, but we also need to configure the parameters for the caption. Here we assume that the caption length is no more than 30 words (#(6)) and the number of unique words in the dictionary is 10000 (#(7)). Lastly, the BATCH_SIZE parameter is used because by default PyTorch processes tensors in a batch. Just to make things simple, the number of image-caption pair within a single batch is set to 1.
GoogLeNet Encoder
It is actually possible to use any kind of CNN-based model for the encoder. I found on the internet that [4] uses DenseNet, [5] uses Inception V3, and [6] utilizes ResNet for the similar tasks. However, since my goal is to reproduce the model proposed in the paper as closely as possible, I am using the pretrained GoogLeNet model instead. Before we get into the encoder implementation, let's see what the GoogLeNet architecture looks like using the following code.
python
# Codeblock 3
models.googlenet()
The resulting output is very long as it lists literally all layers inside the architecture. Here I truncate the output since I only want you to focus on the last layer (the fc layer marked with #(1) in the Codeblock 3 Output below). You can see that this linear layer maps a feature vector of size 1024 into 1000. Normally, in a standard image classification task, each of these 1000 neurons corresponds to a specific class. So, for example, if you want to perform a 5-class classification task, you would need to modify this layer such that it projects the outputs to 5 neurons only. In our case, we need to make this layer produce a feature vector of length 512 (EMBED_DIM). With this, the input image will later be represented as a 512-dimensional vector after being processed by the GoogLeNet model. This feature vector size will exactly match with the token embedding dimension, allowing it to be treated as a part of our word sequence.
csharp
# Codeblock 3 Output
GoogLeNet(
  (conv1): BasicConv2d(
    (conv): Conv2d(3, 64, kernel_size=(7, 7), stride=(2, 2), padding=(3, 3), bias=False)
    (bn): BatchNorm2d(64, eps=0.001, momentum=0.1, affine=True, track_running_stats=True)
  )
  (maxpool1): MaxPool2d(kernel_size=3, stride=2, padding=0, dilation=1, ceil_mode=True)
  (conv2): BasicConv2d(
    (conv): Conv2d(64, 64, kernel_size=(1, 1), stride=(1, 1), bias=False)
    (bn): BatchNorm2d(64, eps=0.001, momentum=0.1, affine=True, track_running_stats=True)
  )

  .
  .
  .
  .

  (avgpool): AdaptiveAvgPool2d(output_size=(1, 1))
  (dropout): Dropout(p=0.2, inplace=False)
  (fc): Linear(in_features=1024, out_features=1000, bias=True)  #(1)
)
Now let's actually load and modify the GoogLeNet model, which I do in the InceptionEncoder class below.
python
# Codeblock 4a
class InceptionEncoder(nn.Module):
    def __init__(self, fine_tune):  #(1)
        super().__init__()
        self.googlenet = models.googlenet(weights=GoogLeNet_Weights.IMAGENET1K_V1)  #(2)
        self.googlenet.fc = nn.Linear(in_features=self.googlenet.fc.in_features,  #(3)
                                      out_features=EMBED_DIM)  #(4)

        if fine_tune == True:       #(5)
            for param in self.googlenet.parameters():
                param.requires_grad = True
        else:
            for param in self.googlenet.parameters():
                param.requires_grad = False

        for param in self.googlenet.fc.parameters():
            param.requires_grad = True
The first thing we do in the above code is to load the model using models.googlenet(). It is mentioned in the paper that the model is already pretrained on the ImageNet dataset. Thus, we need to pass GoogLeNet_Weights.IMAGENET1K_V1 into the weights parameter, as shown at line #(2) in Codeblock 4a. Next, at line #(3) we access the classification head through the fc attribute, where we replace the existing linear layer with a new one having the output dimension of 512 (EMBED_DIM) (#(4)). Since this GoogLeNet model is already trained, we don't need to train it from scratch. Instead, we can either perform fine-tuning or transfer learning in order to adapt it to the image captioning task.
In case you're not yet familiar with the two terms, fine-tuning is a method where we update the weights of the entire model. On the other hand, transfer learning is a technique where we only update the weights of the layers we replaced (in this case it's the last fully-connected layer), while setting the weights of the existing layers non-trainable. To do so, I implement a flag named fine_tune at line #(1) which will let the model to perform fine-tuning whenever it is set to True (#(5)).
The forward() method is pretty straightforward since what we do here is simply passing the input image through the modified GoogLeNet model. See the Codeblock 4b below for the details. Additionally, here I also print out the tensor dimension before and after processing so that you can better understand how the InceptionEncoder model works.
python
# Codeblock 4b
    def forward(self, images):
        print(f'originalt: {images.size()}')
        features = self.googlenet(images)
        print(f'after googlenett: {features.size()}')

        return features
To test whether our decoder works properly, we can pass a dummy tensor of size 1×3×224×224 through the network as demonstrated in Codeblock 5. This tensor dimension simulates a single RGB image of size 224×224. You can see in the resulting output that our image now becomes a single-dimensional feature vector with the length of 512.
python
# Codeblock 5
inception_encoder = InceptionEncoder(fine_tune=True)

images = torch.randn(BATCH_SIZE, IN_CHANNELS, IMAGE_SIZE, IMAGE_SIZE)
features = inception_encoder(images)
csharp
# Codeblock 5 Output
original         : torch.Size([1, 3, 224, 224])
after googlenet  : torch.Size([1, 512])
LSTM Decoder
As we have successfully implemented the encoder, now that we are going to create the LSTM decoder, which I demonstrate in Codeblock 6a and 6b. What we need to do first is to initialize the required layers, namely an embedding layer (#(1)), the LSTM layer itself (#(2)), and a standard linear layer (#(3)). The first one (nn.Embedding) is responsible for mapping every single token into a 512 (EMBED_DIM)-dimensional vector. Meanwhile, the LSTM layer is going to generate a sequence of embedded tokens, where each of these tokens will be mapped into a 10000 (VOCAB_SIZE)-dimensional vector by the linear layer. Later on, the values contained in this vector will represent the likelihood of each word in the dictionary being chosen.
python
# Codeblock 6a
class LSTMDecoder(nn.Module):
    def __init__(self):
        super().__init__()

        #(1)
        self.embedding = nn.Embedding(num_embeddings=VOCAB_SIZE,
                                      embedding_dim=EMBED_DIM)
        #(2)
        self.lstm = nn.LSTM(input_size=EMBED_DIM,
                            hidden_size=LSTM_HIDDEN_DIM,
                            num_layers=NUM_LSTM_LAYERS,
                            batch_first=True)
        #(3)
        self.linear = nn.Linear(in_features=LSTM_HIDDEN_DIM,
                                out_features=VOCAB_SIZE)
Next, let's define the flow of the network using the following code.
python
# Codeblock 6b
    def forward(self, features, captions):                 #(1)
        print(f'features originalt: {features.size()}')
        features = features.unsqueeze(1)                   #(2)
        print(f"after unsqueezett: {features.shape}")

        print(f'captions originalt: {captions.size()}')
        captions = self.embedding(captions)                #(3)
        print(f"after embeddingtt: {captions.shape}")

        captions = torch.cat([features, captions], dim=1)  #(4)
        print(f"after concattt: {captions.shape}")

        captions, _ = self.lstm(captions)                  #(5)
        print(f"after lstmtt: {captions.shape}")

        captions = self.linear(captions)                   #(6)
        print(f"after lineartt: {captions.shape}")

        return captions
You can see in the above code that the forward() method of the LSTMDecoder class accepts two inputs: features and captions, where the former is the image that has been processed by the InceptionEncoder, while the latter is the caption of the corresponding image serving as the ground truth (#(1)). The idea here is that we are going to perform pre-inject operation by prepending the features tensor into captions using the code at line #(4). However, keep in mind that we need to adjust the shape of both tensors beforehand. To do so, we have to insert a single dimension at the 1st axis of the image features (#(2)). Meanwhile, the shape of the captions tensor will align with our requirement right after being processed by the embedding layer (#(3)). As the features and captions have been concatenated, we then pass this tensor through the LSTM layer (#(5)) before it is eventually processed by the linear layer (#(6)). Look at the testing code below to better understand the flow of the two tensors.
python
# Codeblock 7
lstm_decoder = LSTMDecoder()

features = torch.randn(BATCH_SIZE, EMBED_DIM)  #(1)
captions = torch.randint(0, VOCAB_SIZE, (BATCH_SIZE, SEQ_LENGTH))  #(2)

captions = lstm_decoder(features, captions)
In Codeblock 7, I assume that features is a dummy tensor that represents the output of the InceptionEncoder model (#(1)). Meanwhile, captions is the tensor representing a sequence of tokenized words, where in this case I initialize it as random numbers ranging between 0 to 10000 (VOCAB_SIZE) with the length of 30 (SEQ_LENGTH) (#(2)).
We can see in the output below that the features tensor initially has the dimension of 1×512 (#(1)). This tensor shape changed to 1×1×512 after being processed with the unsqueeze() operation (#(2)). The additional dimension in the middle (1) allows the tensor to be treated as a feature vector corresponding to a single timestep, which is necessary for compatibility with the LSTM layer. To the captions tensor, its shape changed from 1×30 (#(3)) to 1×30×512 (#(4)), indicating that every single word is now represented as a 512-dimensional vector.
csharp
# Codeblock 7 Output
features original : torch.Size([1, 512])       #(1)
after unsqueeze   : torch.Size([1, 1, 512])    #(2)
captions original : torch.Size([1, 30])        #(3)
after embedding   : torch.Size([1, 30, 512])   #(4)
after concat      : torch.Size([1, 31, 512])   #(5)
after lstm        : torch.Size([1, 31, 512])   #(6)
after linear      : torch.Size([1, 31, 10000]) #(7)
After pre-inject operation is performed, our tensor is now having the dimension of 1×31×512, where the features tensor becomes the token at the 0th timestep in the sequence (#(5)). See the following figure to better illustrate this idea.
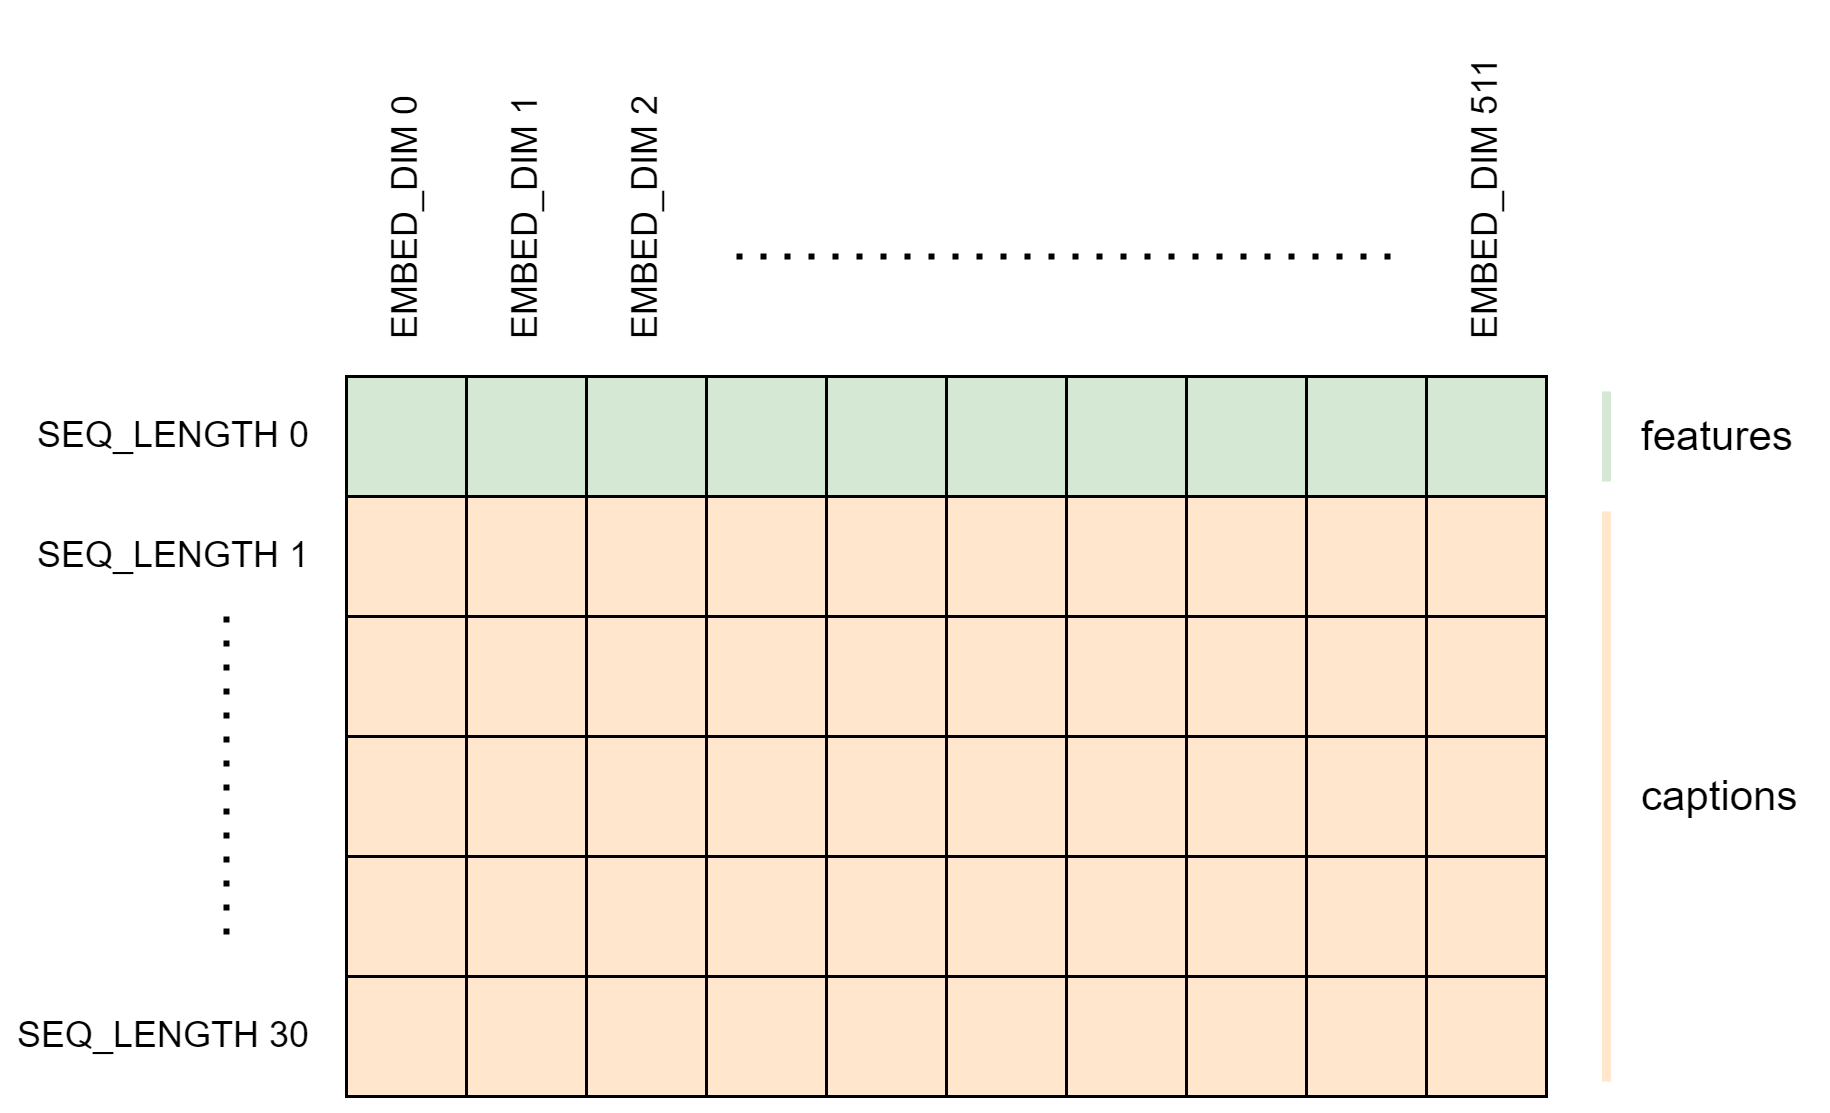 Figure 3. What the resulting tensor looks like after the pre-injection operation. [3].
Next, we pass the tensor through the LSTM layer, which in this particular case the output tensor dimension remains the same. However, it is important to note that the tensor shapes at line
#(5) and #(6) in the above output are actually specified by different parameters. The dimensions appear to match here because EMBED_DIM and LSTM_HIDDEN_DIM were both set to 512. Normally, if we use a different value for LSTM_HIDDEN_DIM, then the output dimension is going to be different as well. Finally, we projected each of the 31 token embeddings to a vector of size 10000, which will later contain the probability of every possible token being predicted (#(7)).
GoogLeNet Encoder + LSTM Decoder
At this point, we have successfully created both the encoder and the decoder parts of the image captioning model. What I am going to do next is to combine them together in the ShowAndTell class below.
python
# Codeblock 8a
class ShowAndTell(nn.Module):
    def __init__(self):
        super().__init__()
        self.encoder = InceptionEncoder(fine_tune=True)  #(1)
        self.decoder = LSTMDecoder()     #(2)

    def forward(self, images, captions):
        features = self.encoder(images)  #(3)
        print(f"after encodert: {features.shape}")

        captions = self.decoder(features, captions)      #(4)
        print(f"after decodert: {captions.shape}")

        return captions
I think the above code is pretty straightforward. In the __init__() method, we only need to initialize the InceptionEncoder as well as the LSTMDecoder models (#(1) and #(2)). Here I assume that we are about to perform fine-tuning rather than transfer learning, so I set the fine_tune parameter to True. Theoretically speaking, fine-tuning is better than transfer learning if you have a relatively large dataset since it works by re-adjusting the weights of the entire model. However, if your dataset is rather small, you should go with transfer learning instead - but that's just the theory. It's definitely a good idea to experiment with both options to see which works best in your case.
Still with the above codeblock, we configure the forward() method to accept image-caption pairs as input. With this configuration, we basically design this method such that it can only be used for training purpose. Here we initially process the raw image with the GoogLeNet inside the encoder block (#(3)). Afterwards, we pass the extracted features as well as the tokenized captions into the decoder block and let it produce another token sequence (#(4)). In the actual training, this caption output will then be compared with the ground truth to compute the error. This error value is going to be used to compute gradients through backpropagation, which determines how the weights in the network are updated.
It is important to know that we cannot use the forward() method to perform inference, so we need a separate one for that. In this case, I am going to implement the code specifically to perform inference in the generate() method below.
python
# Codeblock 8b
    def generate(self, images):  #(1)
        features = self.encoder(images)              #(2)
        print(f"after encodertt: {features.shape}n")

        words = []  #(3)
        for i in range(SEQ_LENGTH):                  #(4)
            print(f"iteration #{i}")
            features = features.unsqueeze(1)
            print(f"after unsqueezett: {features.shape}")

            features, _ = self.decoder.lstm(features)
            print(f"after lstmtt: {features.shape}")

            features = features.squeeze(1)           #(5)
            print(f"after squeezett: {features.shape}")

            probs = self.decoder.linear(features)    #(6)
            print(f"after lineartt: {probs.shape}")

            _, word = probs.max(dim=1)  #(7)
            print(f"after maxtt: {word.shape}")

            words.append(word.item())  #(8)

            if word == 1:  #(9)
                break

            features = self.decoder.embedding(word)  #(10)
            print(f"after embeddingtt: {features.shape}n")

        return words       #(11)
Instead of taking two inputs like the previous one, the generate() method takes raw image as the only input (#(1)). Since we want the features extracted from the image to be the initial input token, we first need to process the raw input image with the encoder block prior to actually generating the subsequent tokens (#(2)). Next, we allocate an empty list for storing the token sequence to be produced later (#(3)). The tokens themselves are generated one by one, so we wrap the entire process inside a for loop, which is going to stop iterating once it reaches at most 30 (SEQ_LENGTH) words (#(4)).
The steps done inside the loop is algorithmically similar to the ones we discussed earlier. However, since the LSTM cell here generates a single token at a time, the process requires the tensor to be treated a bit differently from the one passed through the forward() method of the LSTMDecoder class back in Codeblock 6b. The first difference you might notice is the squeeze() operation (#(5)), which is basically just a technical step to be done such that the subsequent layer does the linear projection correctly (#(6)). Then, we take the index of the feature vector having the highest value, which corresponds to the token most likely to come next (#(7)), and append it to the list we allocated earlier (#(8)). The loop is going to break whenever the predicted index is a stop token , which in this case I assume that this token is at the 1st index of the probs vector. Otherwise, if the model does not find the stop token , then it is going to convert the last predicted word into its 512 (EMBED_DIM)-dimensional vector (#(10)), allowing it to be used as the input features for the next iteration. Lastly, the generated word sequence will be returned once the loop is completed (#(11)).
We are going to simulate the forward pass for the training phase using the Codeblock 9 below. Here I pass two tensors through the show_and_tell model (#(1)), each representing a raw image of size 3×224×224 (#(2)) and a sequence of tokenized words (#(3)). Based on the resulting output, we found that our model works properly as the two input tensors successfully passed through the InceptionEncoder and the LSTMDecoder part of the network.
python
# Codeblock 9
show_and_tell = ShowAndTell()  #(1)

images = torch.randn(BATCH_SIZE, IN_CHANNELS, IMAGE_SIZE, IMAGE_SIZE)  #(2)
captions = torch.randint(0, VOCAB_SIZE, (BATCH_SIZE, SEQ_LENGTH))      #(3)

captions = show_and_tell(images, captions)
csharp
# Codeblock 9 Output
after encoder : torch.Size([1, 512])
after decoder : torch.Size([1, 31, 10000])
Now, let's assume that our show_and_tell model is already trained on an image captioning dataset, and thus ready to be used for inference. Look at the Codeblock 10 below to see how I do it. Here we set the model to eval() mode (#(1)), initialize the input image (#(2)), and pass it through the model using the generate() method (#(3)).
python
# Codeblock 10
show_and_tell.eval()  #(1)

images = torch.randn(BATCH_SIZE, IN_CHANNELS, IMAGE_SIZE, IMAGE_SIZE)  #(2)

with torch.no_grad():
    generated_tokens = show_and_tell.generate(images)  #(3)
The flow of the tensor can be seen in the output below. Here I truncate the resulting outputs because it only shows the same token generation process 30 times.
csharp
# Codeblock 10 Output
after encoder    : torch.Size([1, 512])

iteration #0
after unsqueeze  : torch.Size([1, 1, 512])
after lstm       : torch.Size([1, 1, 512])
after squeeze    : torch.Size([1, 512])
after linear     : torch.Size([1, 10000])
after max        : torch.Size([1])
after embedding  : torch.Size([1, 512])

iteration #1
after unsqueeze  : torch.Size([1, 1, 512])
after lstm       : torch.Size([1, 1, 512])
after squeeze    : torch.Size([1, 512])
after linear     : torch.Size([1, 10000])
after max        : torch.Size([1])
after embedding  : torch.Size([1, 512])

.
.
.
.
To see what the resulting caption looks like, we can just print out the generated_tokens list as shown below. Keep in mind that this sequence is still in the form of tokenized words. Later, in the post-processing stage, we will need to convert them back to the words corresponding to these numbers.
python
# Codeblock 11
generated_tokens
csharp
# Codeblock 11 Output
[5627,
 3906,
 2370,
 2299,
 4952,
 9933,
 402,
 7775,
 602,
 4414,
 8667,
 6774,
 9345,
 8750,
 3680,
 4458,
 1677,
 5998,
 8572,
 9556,
 7347,
 6780,
 9672,
 2596,
 9218,
 1880,
 4396,
 6168,
 7999,
 454]
Ending
With the above output, we've reached the end of our discussion on image captioning. Over time, many other researchers attempted to make improvements to accomplish this task. So, I think in the upcoming article I will discuss the state-of-the-art method on this topic.
Thanks for reading, I hope you learn something new today!
By the way you can also find the code used in this article here.
References
[1] Oriol Vinyals et al. Show and Tell: A Neural Image Caption Generator. Arxiv. https://arxiv.org/pdf/1411.4555 [Accessed November 13, 2024].
[2] Christian Szegedy et al. Going Deeper with Convolutions. Arxiv. https://arxiv.org/pdf/1409.4842 [Accessed November 13, 2024].
[3] Marc Tanti et al. Where to put the Image in an Image Caption Generator. Arxiv. https://arxiv.org/pdf/1703.09137 [Accessed November 13, 2024].
[4] Stepan Ulyanin. Captioning Images with CNN and RNN, using PyTorch. Medium. https://medium.com/@stepanulyanin/captioning-images-with-pytorch-bc592e5fd1a3 [Accessed November 16, 2024].
[5] Saketh Kotamraju. How to Build an Image-Captioning Model in Pytorch. Towards Data Science. https://contributor.insightmediagroup.io/how-to-build-an-image-captioning-model-in-pytorch-29b9d8fe2f8c [Accessed November 16, 2024].
[6] Code with Aarohi. Image Captioning using CNN and RNN | Image Captioning using Deep Learning. YouTube. https://www.youtube.com/watch?v=htNmFL2BG34 [Accessed November 16, 2024].
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
Deep learning storyteller
See all from Muhammad Ardi Putra
Artificial IntelligenceComputer VisionDeep LearningHands On TutorialsNLP
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
In this article, we will see how we can use Streamlit with Image Processing Techniques and Object Detection Algorithms. I am assuming that...
Aniket Wattamwar
November 1, 20205 min read
Machine Learning
Siri, Please watch my 1-hour long University lecture video and make a summary for me
Alex Aman
September 11, 20203 min read
Deep Learning
Deep Learning with Class Imbalanced Data
Saptashwa Bhattacharyya
February 15, 20219 min read
Deep Learning
Practical implementation
Ziad SALLOUM
January 19, 20196 min read
Deep Learning
Take a peek into the world of Teacher Student networks
Prakhar Ganesh
August 12, 20194 min read
Artificial Intelligence
How Azure ML can be leveraged to support medical imaging use cases in areas like data, model management, deployment and MLOps
Harmke Alkemade
December 20, 202113 min read
Artificial Intelligence
What I would have done differently
Soner Yıldırım
March 15, 20214 min read
Artificial Intelligence
Overview and Python Implementation of Node, Edge and Graph Embedding Methods
Vatsal
November 7, 20227 min read
Artificial Intelligence
At AI Music, where our back catalogue of content grows every day, it is becoming increasingly necessary for us to create more intelligent...
Thomas Vassallo
August 28, 20206 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close