保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Science
5 Data Similarity Metrics
Understanding similarity metrics in data analysis and machine learning: A comprehensive guide
Shashank Kapadia
December 27, 20227 min read
 Photo by Alexander Grey on Unsplash
Preface: This article presents a summary of information about the given topic. It should not be considered original research. The information and code included in this article may be influenced by things I have read or seen in the past from various online articles, research papers, books, and open-source code.
Introduction
Similarity metrics are a vital tool in many data analysis and machine learning tasks, allowing us to compare and evaluate the similarity between different pieces of data. Many different metrics are available, each with pros and cons and suitable for different data types and tasks.
This article will explore some of the most common similarity metrics and compare their strengths and weaknesses. By understanding the characteristics and limitations of these metrics, we can choose the most appropriate one for our specific needs and ensure the accuracy and relevance of our results.
Euclidean distance
This metric calculates the straight-line distance between two points in n-dimensional space. It is often used for continuous numerical data and is easy to understand and implement. However, it can be sensitive to outliers and does not account for the relative importance of different features.
Learn this step by step with the interactive AI and Data Scientist roadmap.
python
from scipy.spatial import distance

# Calculate Euclidean distance between two points
point1 = [1, 2, 3]
point2 = [4, 5, 6]

# Use the euclidean function from scipy's distance module to calculate the Euclidean distance
euclidean_distance = distance.euclidean(point1, point2)
Manhattan distance
This metric calculates the distance between two points by considering the absolute differences of their coordinates in each dimension and summing them. It is less sensitive to outliers than Euclidean distance, but it may not accurately reflect the actual distance between points in some cases.
python
from scipy.spatial import distance

# Calculate Manhattan distance between two points
point1 = [1, 2, 3]
point2 = [4, 5, 6]

# Use the cityblock function from scipy's distance module to calculate the Manhattan distance
manhattan_distance = distance.cityblock(point1, point2)

# Print the result
print("Manhattan Distance between the given two points: " + \
      str(manhattan_distance))
Cosine similarity
This metric calculates the similarity between two vectors by considering their angle. It is often used for text data and is resistant to changes in the magnitude of the vectors. However, it does not consider the relative importance of different features.
python
from sklearn.metrics.pairwise import cosine_similarity

# Calculate cosine similarity between two vectors
vector1 = [1, 2, 3]
vector2 = [4, 5, 6]

# Use the cosine_similarity function from scikit-learn to calculate the similarity
cosine_sim = cosine_similarity([vector1], [vector2])[0][0]

# Print the result
print("Cosine Similarity between the given two vectors: " + \
      str(cosine_sim))
Jaccard similarity
This metric calculates the similarity between two sets by considering the size of their intersection and union. It is often used for categorical data and is resistant to changes in the size of the sets. However, it does not consider the sets' order or frequency of elements.
python
def jaccard_similarity(list1, list2):
    """
    Calculates the Jaccard similarity between two lists.

    Parameters:
    list1 (list): The first list to compare.
    list2 (list): The second list to compare.

    Returns:
    float: The Jaccard similarity between the two lists.
    """
    # Convert the lists to sets for easier comparison
    s1 = set(list1)
    s2 = set(list2)

    # Calculate the Jaccard similarity by taking the length of the intersection of the sets
    # and dividing it by the length of the union of the sets
    return float(len(s1.intersection(s2)) / len(s1.union(s2)))

# Calculate Jaccard similarity between two sets
set1 = [1, 2, 3]
set2 = [2, 3, 4]
jaccard_sim = jaccard_similarity(set1, set2)

# Print the result
print("Jaccard Similarity between the given two sets: " + \
      str(jaccard_sim))
Pearson correlation coefficient
This metric calculates the linear correlation between two variables. It is often used for continuous numerical data and considers the relative importance of different features. However, it may not accurately reflect non-linear relationships.
python
import numpy as np

# Calculate Pearson correlation coefficient between two variables
x = [1, 2, 3, 4]
y = [2, 3, 4, 5]

# Numpy corrcoef function to calculate the Pearson correlation coefficient and p-value
pearson_corr = np.corrcoef(x, y)[0][1]

# Print the result
print("Pearson Correlation between the given two variables: " + \
      str(pearson_corr))
Now that we have reviewed the basics of these distance metrics, let’s consider a practical scenario and apply them to compare the results.
Scenario
Suppose we have 5 items with numerical attributes and we want to compare the similarities between these products in order to facilitate applications such as clustering, classification, or perhaps, recommendations.
The following code computes the similarity metrics for the given products and their attributes using various distance metrics and then plots the results in a heat map for evaluation.
python
import numpy as np
import seaborn as sns
import random
import matplotlib.pyplot as plt
import pprint

def calculate_similarities(products):
    """Calculate the similarity measures between all pairs of products.

    Parameters
    ----------
    products : list
        A list of dictionaries containing the attributes of the products.

    Returns
    -------
    euclidean_similarities : numpy array
        An array containing the Euclidean distance between each pair of products.
    manhattan_distances : numpy array
        An array containing the Manhattan distance between each pair of products.
    cosine_similarities : numpy array
        An array containing the cosine similarity between each pair of products.
    jaccard_similarities : numpy array
        An array containing the Jaccard index between each pair of products.
    pearson_similarities : numpy array
        An array containing the Pearson correlation coefficient between each pair of products.
    """
    # Initialize arrays to store the similarity measures
    euclidean_similarities = np.zeros((len(products), len(products)))
    manhattan_distances = np.zeros((len(products), len(products)))
    cosine_similarities = np.zeros((len(products), len(products)))
    jaccard_similarities = np.zeros((len(products), len(products)))
    pearson_similarities = np.zeros((len(products), len(products)))

    # Calculate all the similarity measures in a single loop
    for i in range(len(products)):
        for j in range(i+1, len(products)):
            p1 = products[i]['attributes']
            p2 = products[j]['attributes']

            # Calculate Euclidean distance
            euclidean_similarities[i][j] = distance.euclidean(p1, p2)
            euclidean_similarities[j][i] = euclidean_similarities[i][j]

            # Calculate Manhattan distance
            manhattan_distances[i][j] = distance.cityblock(p1, p2)
            manhattan_distances[j][i] = manhattan_distances[i][j]

            # Calculate cosine similarity
            cosine_similarities[i][j] = cosine_similarity([p1], [p2])[0][0]
            cosine_similarities[j][i] = cosine_similarities[i][j]

            # Calculate Jaccard index
            jaccard_similarities[i][j] = jaccard_similarity(p1, p2)
            jaccard_similarities[j][i] = jaccard_similarities[i][j]

            # Calculate Pearson correlation coefficient
            pearson_similarities[i][j] = np.corrcoef(p1, p2)[0][1]
            pearson_similarities[j][i] = pearson_similarities[i][j]

    return euclidean_similarities, manhattan_distances, cosine_similarities, jaccard_similarities, pearson_similarities

def plot_similarities(similarities_list, labels, titles):
    """Plot the given similarities as heatmaps in subplots.

    Parameters
    ----------
    similarities_list : list of numpy arrays
        A list of arrays containing the similarities between the products.
    labels : list
        A list of strings containing the labels for the products.
    titles : list
        A list of strings containing the titles for each plot.

    Returns
    -------
    None
        This function does not return any values. It only plots the heatmaps.
    """
    # Set up the plot
    fig, ax = plt.subplots(nrows=1,
                           ncols=len(similarities_list), figsize=(6*len(similarities_list), 6/1.680))

    for i, similarities in enumerate(similarities_list):
        # Plot the heatmap
        sns.heatmap(similarities, xticklabels=labels, yticklabels=labels, ax=ax[i])
        ax[i].set_title(titles[i])
        ax[i].set_xlabel("Product")
        ax[i].set_ylabel("Product")

    # Show the plot
    plt.show()

# Define the products and their attributes
products = [
    {'name': 'Product 1', 'attributes': random.sample(range(1, 11), 5)},
    {'name': 'Product 2', 'attributes': random.sample(range(1, 11), 5)},
    {'name': 'Product 3', 'attributes': random.sample(range(1, 11), 5)},
    {'name': 'Product 4', 'attributes': random.sample(range(1, 11), 5)},
    {'name': 'Product 5', 'attributes': random.sample(range(1, 11), 5)}
]

pprint.pprint(products)

euclidean_similarities, manhattan_distances, \
cosine_similarities, jaccard_similarities, \
pearson_similarities = calculate_similarities(products)

# Set the labels for the x-axis and y-axis
product_labels = [product['name'] for product in products]

# List of similarity measures and their titles
similarities_list = [euclidean_similarities, cosine_similarities, pearson_similarities,
                     jaccard_similarities, manhattan_distances]
titles = ["Euclidean Distance", "Cosine Similarity", "Pearson Correlation Coefficient",
          "Jaccard Index", "Manhattan Distance"]

# Plot the heatmaps
plot_similarities(similarities_list, product_labels, titles)
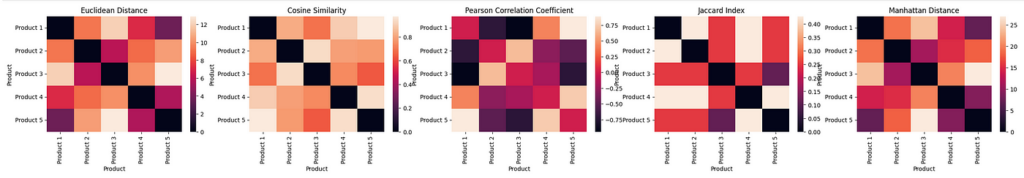 As we can see from the charts, each similarity metric produces a heat map that represents different similarities between the products, and on a different scale. While each similarity metric can be used to interpret whether two products are similar or not based on the metric’s value, it is difficult to determine a true measure of similarity when comparing the results across different distance metrics.
How to choose the correct metric
There is no single “true” answer when it comes to choosing a similarity metric, as different metrics are better suited for different types of data and different analysis goals. However, there are some factors that can help narrow down the possible metrics that might be appropriate for a given situation. Some things to consider when choosing a similarity metric include:
- The type of data : Some metrics are more appropriate for continuous data, while others are better suited for categorical or binary data.
- The characteristics of the data : Different metrics are sensitive to different aspects of the data, such as the magnitudes of differences between attributes or the angles between attributes. Consider which characteristics of the data are most important to your analysis and choose a similarity metric that is sensitive to these characteristics.
- The goals of your analysis : Different metrics can highlight different patterns or relationships in the data, so consider what you are trying to learn from your analysis and choose a distance metric that is well-suited to this purpose.
Personally, I often use the following chart as a starting point when choosing a similarity metric.
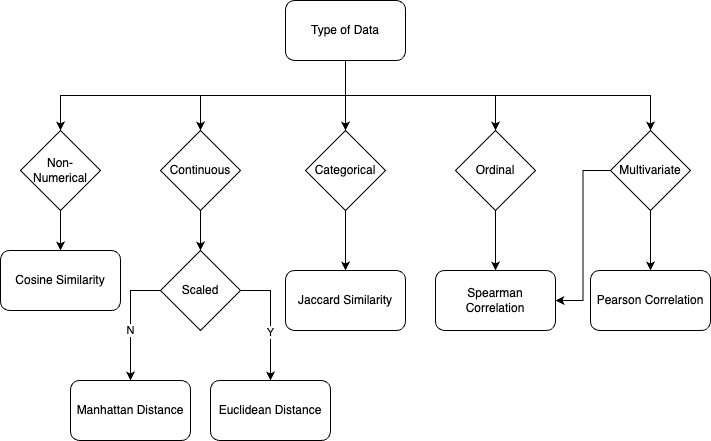 Again, it is important to carefully consider the data type and characteristics when selecting a similarity metric, as well as the specific goals of the analysis.
All of the code used in this article can be found at Jupyter Notebook.
Thanks for reading. If you have any feedback, please feel to reach out by messaging me on LinkedIn or shooting me an email (shmkapadia[at]gmail[dot]com).
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
SK
Written By
See all from Shashank Kapadia
Distance MetricsMachine LearningSimilarity MetricsStatistics
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Software Engineering
A step-by-step illustration of how to use SOLID to solve a refactoring challenge
Tomer Gabay
February 5, 20249 min read
Artificial Intelligence
A guide for employing dimensionality reduction to improve an AI model's efficacy
Matthew Connelly
June 13, 202110 min read
Programming
Which UK city has the safest drivers?
Thomas Reid
December 15, 202513 min read
Machine Learning
Better Understand Probability By Tackling This Data Science Interview Question (With Python)
Tony Yiu
May 31, 20208 min read
Machine Learning
College Statistics with Python
Luís Roque
August 3, 20215 min read
Artificial Intelligence
Here are the lessons I learned and how I am writing llm.rust and tackling the matrix multiplication problem
Stefano Bosisio
November 14, 202415 min read
Machine Learning
Exploring and comparing distinct approaches to text chunking.
Solano Todeschini
July 20, 202318 min read
Artificial Intelligence
Data is the fuel to creating value for your customers and its application is far...
Chanade Hemming
May 19, 20219 min read
Large Language Models
A beginner's guide to state-of-the-art supervised fine-tuning
Maxime Labonne
July 29, 202412 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close