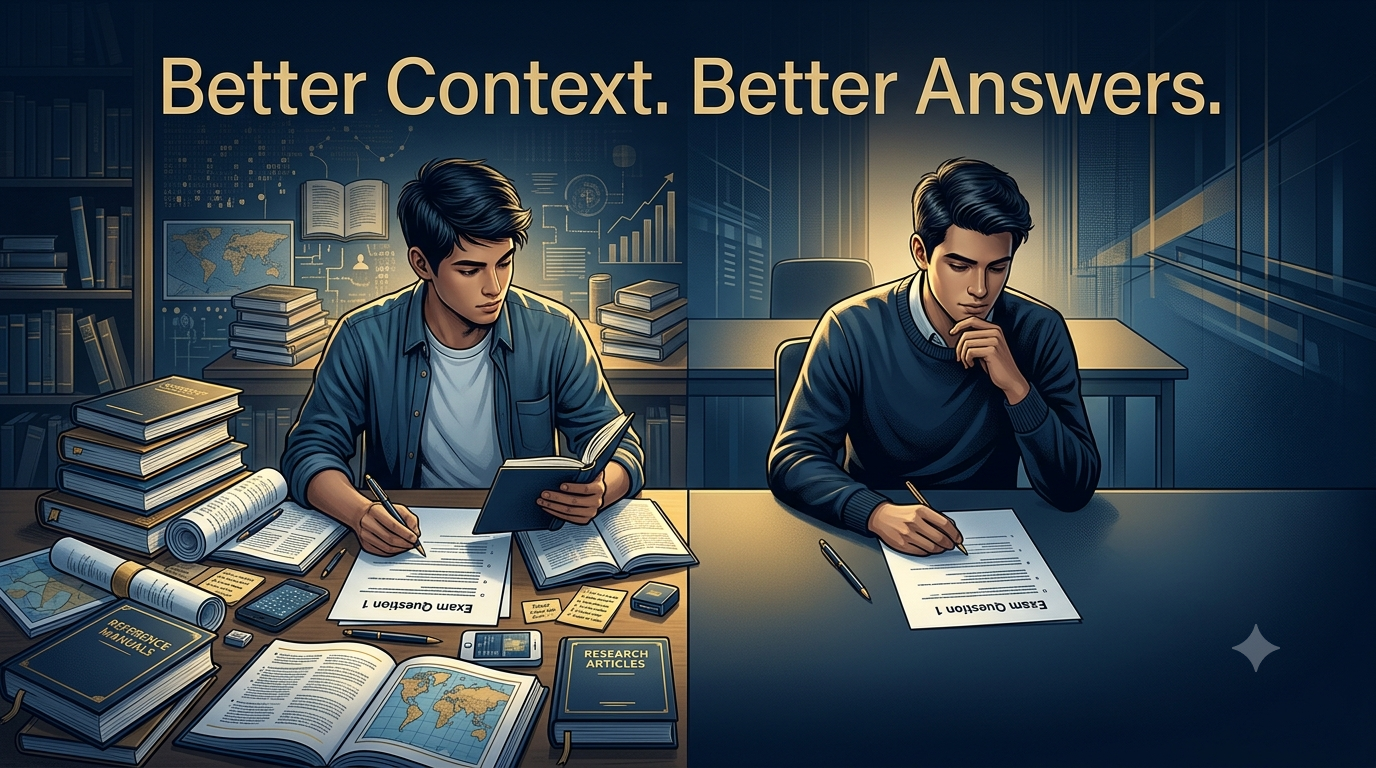
As AI models become smarter, the challenge is no longer what to ask. It's deciding what the model should know before it answers.
As AI models become smarter, the challenge is no longer what to ask. The challenge is deciding what the model should know before it answers.
For the past few years, prompt engineering has occupied a special place in the AI conversation.
Entire courses have been built around it. Social media feeds have been filled with prompt libraries. Countless discussions have focused on discovering the perfect prompt structure, the perfect role assignment, or the perfect set of instructions that could unlock better responses from increasingly capable AI models.
The excitement was understandable.
For many people, prompts were the first lever they could control.
As AI systems became accessible through conversational interfaces, users quickly discovered that the way they asked a question often influenced the quality of the answer. A carefully structured prompt could transform a mediocre response into an excellent one. Naturally, prompt engineering became one of the most discussed skills in the industry.
But over time, I've noticed something interesting.
The more AI systems move from demonstrations to production environments, the less I find myself thinking about prompts.
And the more I find myself thinking about context.
That doesn't mean prompt engineering is unimportant. Good prompts still matter. They help define tasks, establish expectations, and guide model behavior.
What has changed is their relative importance.
As models become increasingly capable, the difference between an average prompt and a great prompt often matters less than the difference between poor context and rich context.
The industry spent years learning how to ask better questions.
It may spend the next decade learning how to provide better information.
To understand why context engineering is emerging as a critical skill, it is worth understanding why prompt engineering became so popular in the first place.
When ChatGPT became mainstream, most users had access to the same model. They couldn't retrain it. They couldn't modify its architecture. They couldn't increase its knowledge.
The only thing they could control was the interaction itself.
As a result, people began experimenting.
They discovered that subtle changes in phrasing could significantly influence outputs. Asking the same model to act as a teacher, an architect, a software engineer, or a business analyst often produced noticeably different responses. Providing examples improved consistency. Structured instructions improved formatting. Explicit reasoning requests often improved results.
These discoveries were real.
Prompt engineering created genuine value because it helped people communicate more effectively with AI systems.
In many ways, prompt engineering solved a problem humans have always faced: expressing intent clearly.
The better we explained what we wanted, the better the results became.
The lesson was correct.
The conclusion, however, was incomplete.
Imagine interviewing two candidates for the same role.
You ask both candidates an identical question.
The first candidate has spent years working at your company. They understand the products, customers, internal systems, historical decisions, team priorities, and business constraints.
The second candidate walks into the room knowing nothing beyond the job description.
Everything else remains identical.
The question is the same.
The candidates are equally intelligent.
The only difference is the information available to them.
Most people intuitively understand what happens next.
The first candidate provides a richer, more accurate, and more useful answer because they possess relevant context.
The second candidate may still be intelligent, but intelligence alone cannot compensate for missing information.
Modern AI systems behave in a surprisingly similar way.
Engineers often spend enormous amounts of energy refining questions while paying comparatively little attention to the information available when the model generates its answer.
Yet the quality of an answer depends on both.
The prompt is the question.
Context is everything the model knows before answering.
One of the most important lessons organizations learn when deploying AI systems is that models rarely fail for the reasons people expect.
When users receive poor answers, the immediate assumption is often that the model is not intelligent enough.
Perhaps a stronger model will solve the problem. Perhaps a larger context window will solve the problem. Perhaps a different vendor will solve the problem.
Sometimes that assumption is correct. Many times, it isn't.
The model may be generating poor answers simply because it lacks access to the right information.
An employee asks a question about company policy. The policy isn't included in the context.
A customer asks about a product specification. The specification is missing from the retrieved documents.
A support agent requests information from a knowledge base. The relevant document was never indexed.
In each case, the model is attempting to answer with incomplete information.
The problem isn't intelligence; the problem is context.
This distinction becomes increasingly important as organizations move from experimentation to production systems.
AI applications operating in enterprise environments are rarely judged by the sophistication of their models.
They are judged by the usefulness of their answers.
And useful answers depend heavily on information access.
For much of the early GenAI era, the industry focused on prompting because it was the most visible layer.
Prompts sat directly in front of the user.
They were easy to modify. They were easy to discuss. They were easy to demonstrate.
Context, by comparison, lived behind the scenes.
Users rarely saw retrieval pipelines.
They rarely saw metadata structures. They rarely saw search indexes. They rarely saw memory systems.
Yet many of those hidden components were quietly becoming more important.
As models improved, organizations began discovering a counterintuitive reality.
Improving the prompt often produced incremental gains. Improving the information available to the model often produced transformational gains.
This was not always obvious from the outside, but it became increasingly clear inside production systems.
The bottleneck was moving.
Not away from intelligence entirely, but toward information.
Few developments accelerated this realization more than Retrieval-Augmented Generation.
Before RAG became popular, many people viewed language models primarily as standalone systems. The model received a prompt and generated a response based on the information learned during training.
RAG introduced a different idea.
Instead of relying exclusively on training data, the model could receive relevant external information at inference time.
At first glance, this appeared to be merely a technical improvement.
In reality, it represented a shift in how many people thought about AI systems.
The quality of the response was no longer determined solely by the model; it became increasingly dependent on the quality of retrieved information.
A perfectly capable model fed irrelevant documents produced poor answers.
A well-designed retrieval system feeding highly relevant information often produced excellent answers.
The implications were profound.
Organizations realized they could create significant improvements without changing the model at all.
They simply had to improve the information reaching it.
The conversation began shifting from:
Which model should we use?
to:
What information should the model see?
That may sound like a small change.
It isn't.
One common misconception is that context engineering is simply another term for retrieval.
Retrieval is an important component.
It is not the whole story.
Context includes every piece of information that influences the model's response.
That may include documents from a knowledge base. It may include previous messages in a conversation. It may include user preferences. It may include outputs from external tools. It may include database queries. It may include memory systems. It may include organizational policies. It may include real-time business data.
Viewed broadly, context is the environment in which reasoning occurs.
Just as human decisions are shaped by available information, AI responses are shaped by available context.
Understanding this relationship changes how we think about system design.
The challenge is no longer simply generating responses.
The challenge is constructing the right informational environment before those responses are generated.
The rise of AI agents further reinforced the importance of context.
Traditional prompting assumes a relatively simple interaction.
A user asks a question.
The model provides an answer.
Modern agents operate differently.
They retrieve information. They invoke tools. They access databases. They maintain memory. They execute workflows. They gather evidence before responding.
In many cases, the intelligence of the underlying model matters less than the quality of the surrounding system.
Two agents using the same model can perform dramatically differently depending on the tools, memory mechanisms, retrieval strategies, and information architecture supporting them.
This observation should sound familiar.
It mirrors a broader pattern throughout computing.
Powerful software is rarely created by algorithms alone.
It emerges from systems.
The same principle increasingly applies to AI.
One thing I have consistently observed in enterprise projects is that organizations often underestimate the complexity of information itself.
Everyone wants the intelligent assistant.
Few people initially think about the information infrastructure required to support it.
Questions begin appearing almost immediately.
Which documents should be indexed?
How should they be chunked?
How should permissions be enforced?
How will metadata be maintained?
How will conflicting information be handled?
How will outdated information be detected?
How should information be retrieved?
How should memory be stored?
How should user context be managed?
None of these are prompt engineering questions.
All of them influence answer quality.
And collectively, they determine whether an AI system remains useful at scale.
This is one reason I increasingly view enterprise AI as an information architecture challenge.
The model may generate the response.
The surrounding infrastructure determines whether that response is trustworthy.
If prompt engineering is the art of asking better questions, context engineering is the art of providing better information.
It involves deciding:
What information should be retrieved.
What information should be excluded.
What information should be prioritized.
What information should persist across interactions.
What information should be grounded in real-world systems.
These decisions have enormous consequences.
A model provided with precise, relevant, current information often produces remarkably useful outputs.
The same model operating with incomplete or irrelevant information often struggles.
The architecture remains unchanged.
The context changes.
The outcomes change with it.
This is why I believe context engineering is becoming one of the most valuable skills in modern AI development.
Not because prompts no longer matter.
But because information increasingly matters more.
As foundation models continue improving, it becomes increasingly difficult for organizations to differentiate themselves through model access alone.
Most organizations can access similar frontier models.
The gap between competitors is rarely determined solely by who has the smartest model.
Instead, differentiation increasingly comes from unique information assets.
Unique data.
Unique workflows.
Unique retrieval mechanisms.
Unique memory systems.
Unique business knowledge.
Unique context.
The model becomes the engine.
The information becomes the fuel.
A powerful engine remains important.
But engines are surprisingly similar when compared to the value of a unique fuel source.
This shift has important implications for engineering teams.
The future may belong less to organizations that ask the best questions and more to those that build the best information systems.
The rise of prompt engineering taught the industry an important lesson.
The way we communicate with AI matters.
The rise of context engineering is teaching a different lesson.
The information available to AI matters even more.
For years, the AI conversation focused primarily on intelligence. Could models reason? Could they write? Could they solve complex problems?
Those questions remain important.
But increasingly, organizations face a different challenge.
How do we ensure the model has access to the right information at the right time?
That question touches retrieval, memory, governance, information architecture, data quality, workflows, permissions, and system design.
In other words, it touches the broader ecosystem surrounding intelligence.
And that ecosystem is becoming increasingly important as the technology matures.
Prompt engineering deserves the attention it received.
It helped millions of people learn how to interact effectively with AI systems. It revealed that the quality of our instructions often influences the quality of the outcome.
But prompt engineering solved only part of the problem.
As models become more capable, the bottleneck is moving.
The question is no longer simply:
What should we ask?
The more important question is becoming:
What should the model know before answering?
That shift may seem subtle.
Yet it has profound implications for how AI systems are designed.
The industry spent years learning how to talk to models.
It may spend the next decade learning how to feed them better context.
Because even the smartest model in the world can only reason with the information available to it.
As AI systems continue improving, do you think prompt engineering will remain a major differentiator, or will context engineering become the more valuable skill?
I'd love to hear your thoughts.
Lewis, P., et al. (2020). Retrieval-Augmented Generation for Knowledge-Intensive NLP Tasks.
https://arxiv.org/abs/2005.11401
Anthropic. Building Effective AI Agents.
https://www.anthropic.com/engineering
Microsoft Learn. Retrieval-Augmented Generation (RAG) in Enterprise AI Systems.
https://learn.microsoft.com/
OpenAI. Best Practices for Building with Large Language Models.
https://platform.openai.com/docs
LangChain Documentation. Memory, Retrieval, and Agent Architectures.
https://python.langchain.com/
I'm an AI Engineer building enterprise AI systems and documenting what works, what breaks, and what I've learned along the way.
If you're interested in AI agents, GenAI, RAG systems, and practical AI engineering, consider following for future articles.