保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Engineering
I Built My First ETL Pipeline as a Complete Beginner. Here’s How.
A beginner's honest walkthrough of Extract, Transform, Load using the GitHub API
Ibrahim Salami
May 25, 20266 min read
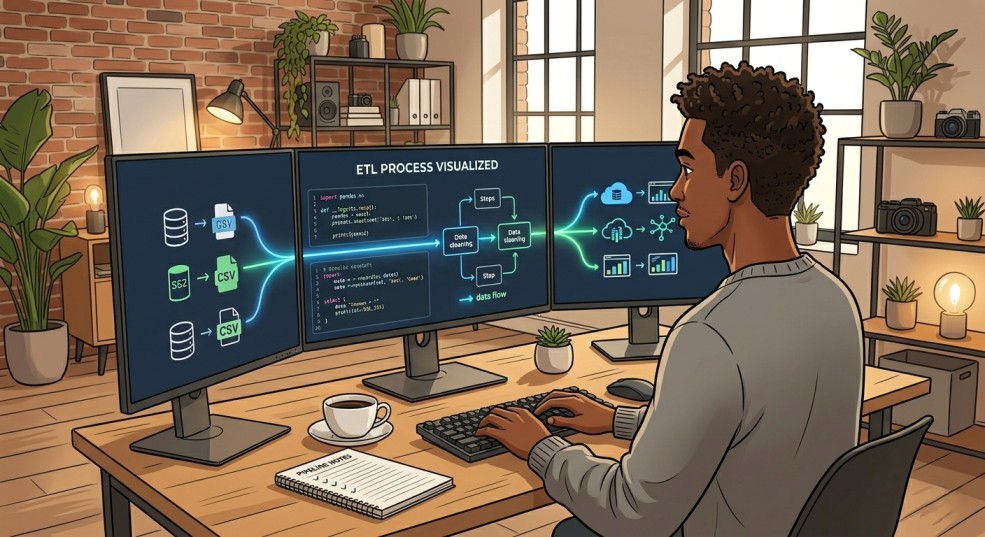 Generated with Gemini
This is part two of my data engineering journey series. In part one, I shared my 12-month roadmap for transitioning from data analyst to data engineer . This is where the actual building begins.
When I published my first article documenting my data engineering journey, something unexpected happened. People resonated with it. I had strangers reaching out saying they were excited to follow along. That felt good.
But it also came with pressure.
Suddenly this wasn't just a personal goal I could quietly abandon if things got hard. People were watching. People were in the same boat. And that accountability, honestly, is part of why you're reading this right now.
So I had to move. And like anyone starting a new skill, the first thing I did was look for resources. There are countless tutorials on the internet for data engineering. YouTube videos, courses, written guides. More than you could ever finish.
But I couldn't bring myself to just consume theory. I needed to build something. Something real, with real data, that actually worked at the end.
So I closed the tutorials and opened a Google Colab notebook instead. I found the GitHub API documentation and decided I was going to build my first ETL pipeline from scratch. No hand-holding. Just me, some Python, and a goal.
This article is that experience documented in full. The code, the confusion, the small wins, and what I actually learned by doing it.
Learn this step by step with the interactive Data Engineer roadmap.
First, what is ETL?
Before I get into what I built, let me quickly explain what ETL actually means because I had to look this up myself not too long ago.
ETL stands for Extract, Transform, Load. It's one of the most fundamental concepts in data engineering.
- Extract means going somewhere to get data. An API, a database, a website, a file. You're pulling raw information from a source.
- Transform means cleaning and shaping that data. Removing bad rows, adding new columns, restructuring it so it's actually useful.
- Load means saving the cleaned data somewhere. A database, a data warehouse, a simple CSV file.
That's it. Those three steps, done in sequence, are what a data pipeline is. Everything else in data engineering, Airflow, Spark, Databricks, is just more sophisticated ways of doing those same three things at scale.
I'm at the beginning of my roadmap, so I kept it simple. Pure Python, no orchestration tools yet. But the shape of the problem is the same.
What I built
I extracted data from the GitHub API, specifically the most starred Python repositories created in the last 30 days. I then cleaned it, added a new column, and saved the output as a CSV file.
Simple. Real. Entirely mine.
Here's how it went.
Step 1: Extract
The first thing I had to do was figure out how to talk to the GitHub API. An API is basically a door that a company or platform opens so that developers can request data from it programmatically, without having to manually copy and paste anything.
GitHub has a free, public API. No account or paid plan needed for basic searches.
Here's the code I wrote to extract the data:
python
import requests

url = "https://api.github.com/search/repositories"

params = {
    "q": "language:python created:>2025-04-22",
    "sort": "stars",
    "order": "desc",
    "per_page": 30
}

response = requests.get(url, params=params)
data = response.json()

print(response.status_code)
print(data.keys())
I'll be honest. This block confused me at first. The requests library was new to me. The params dictionary with that q syntax felt alien. I didn't immediately know what .json() was doing or why I needed it.
Let me break it down simply.
requests.get() is how you knock on GitHub's door and ask for something. The url is the address of what you're asking for. Theparams dictionary is the specific question you're asking. In this case: "give me Python repos, sorted by stars, created after April 22, show me 30 results.".json() converts GitHub's response from raw text into a Python dictionary that you can actually work with.
When I ran it, I got this:
pascal
200
dict_keys(['total_count', 'incomplete_results', 'items'])
The 200 means success. That's the internet's way of saying "your request worked." If you see 403 or 404, something went wrong.
The dictionary has three keys. total_count tells you how many repos matched the search. incomplete_results tells you if GitHub had to cut anything short. And items is where the actual data lives.
I then ran a second block to peek inside:
python
print("Total matches on GitHub:", data['total_count'])
print("Repos returned:", len(data['items']))

first_repo = data['items'][0]
print("\nFirst repo name:", first_repo['name'])
print("Stars:", first_repo['stargazers_count'])
print("Language:", first_repo['language'])
print("URL:", first_repo['html_url'])
Output:
markup
Total matches on GitHub: 9228201Repos returned: 30First repo name: skillsStars: 139136Language: PythonURL: https://github.com/anthropics/skills
The first result was an Anthropic repo with 139k stars. Real data. Live. Pulled by code I wrote.
That's Extract done.
Step 2: Transform
Now I had 30 repos sitting in a Python list, each one a nested dictionary with dozens of fields. Most of which I didn't need. The Transform step is where you take that raw, messy data and shape it into something clean and purposeful.
First I pulled out only the fields I cared about and loaded them into a Pandas dataframe:
python
import pandas as pd

repos = []

for repo in data['items']:
    repos.append({
        "name": repo['name'],
        "owner": repo['owner']['login'],
        "stars": repo['stargazers_count'],
        "forks": repo['forks_count'],
        "language": repo['language'],
        "description": repo['description'],
        "url": repo['html_url'],
        "created_at": repo['created_at']
    })

df = pd.DataFrame(repos)
df.head()
Seeing that dataframe appear was a proper "wow" moment. I went from a wall of JSON to a clean, readable table with labelled columns in a few lines.
Then I did three transformations:
python
# Drop rows where description is missing
df_clean = df.dropna(subset=['description'])

# Add a viral flag for repos with over 50k stars
df_clean = df_clean.copy()
df_clean['viral'] = df_clean['stars'].apply(lambda x: 'Yes' if x > 50000 else 'No')

# Sort by stars descending
df_clean = df_clean.sort_values('stars', ascending=False).reset_index(drop=True)

print("Before cleaning:", len(df))
print("After cleaning:", len(df_clean))
Output:
markup
Before cleaning: 30 After cleaning: 29
One repo had no description and got dropped. The viral column showed up cleanly. The data was now sorted and structured.
That's Transform done.
Step 3: Load
The final step. Take the clean data and save it somewhere. I kept this simple and loaded it into a CSV file:
python
df_clean.to_csv('github_trending_repos.csv', index=False)

print("Pipeline complete. File saved.")
print(f"{len(df_clean)} repos loaded into github_trending_repos.csv")
Output:
markup
Pipeline complete. File saved.29 repos loaded into github_trending_repos.csv
I downloaded the file and opened it. A clean spreadsheet with 29 rows and 9 columns. Real GitHub data, shaped and saved by a pipeline I built from scratch.
That's Load done.
What this actually felt like
Before this, whenever I wanted data to work with, I'd go looking for a public dataset someone had already cleaned and uploaded. Kaggle, Google Dataset Search, wherever. I was always a consumer of data that someone else had prepared.
This changed something for me.
The moment I realised I could just point Python at an API I was curious about and extract live data myself, the possibilities felt completely different. I'm not limited to datasets that already exist. I can build the pipeline that creates the dataset.
That's a different kind of power. And it's one of the things that drew me toward data engineering in the first place.
What's next
This pipeline is simple by design. I'm at the start of my roadmap and I'm not going to pretend I'm using Airflow or Spark yet. But the foundation is real. Extract, Transform, Load. It works. I built it. I understand it.
The next step is to make it more robust. Schedule it to run daily. Store the output in a SQLite database instead of a flat CSV. Start tracking how repos trend over time.
And eventually, orchestrate the whole thing with Airflow. But that's a future article.
For now, the most important thing I proved to myself is that building teaches you things that watching never will. I spent weeks in tutorial land and barely moved. I spent one afternoon actually building, and I understand ETL better than any video made it feel.
Stop watching. Start building.
This is part two of my ongoing data engineering series. Follow along as I document every step of the journey, including the parts that don't go smoothly. Feel free to check out my more in-depth ETL take on my YouTube channel below.
Connect with me on LinkedIn ,YouTube , and Twitter .
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Ibrahim Salami
Data PipelineData ScienceEtlExtract Transform LoadGithub
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Data Science
Fireballs are brighter-than-usual meteors that become visible at about 100 km above sea level
Randy Runtsch
April 16, 20225 min read
Programming
A complete career guide covering the roles and responsibilities, technical skills, general salary range, and relevant certifications
Arunn Thevapalan
June 28, 20217 min read
Machine Learning
Understanding the fundamentals of this classification model
Peter Grant
July 21, 20194 min read
Tired of accessing multiple systems for your analytics? This architecture cleanses and merges real-time and historical data in one place
Philip Singer
December 16, 202110 min read
Data Science
Best Practices to Rank on Kaggle with PyTorch Lightning and Grid Spot Instances (Part 1/5)
イルカ Borovec
August 25, 20215 min read
Machine Learning
Introduction
Xinyu Chen (陈新宇)
October 16, 20215 min read
Data Science
Unlocking the power of large language models
Mike Shakhomirov
August 18, 202412 min read
Programming
How to create, store, and manipulate data using Python's Pandas library
Sam Starkman
October 1, 202110 min read
Data Science
Automate Pinecone Daily Upsert Task with Celery and Slack monitoring
Wen Yang
April 15, 20249 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close