保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Ensemble Learning for Anomaly Detection
A dive into the isolation forest model to detect anomalies in time-series data.
Alex Davis
October 30, 20247 min read
A dive into the isolation forest model to detect anomalies in time-series data
Anomaly detection is a must-have capability for any organization. By detecting anomalies and outliers, we not only identify data that seems suspicious (or possibly wrong), but can also establish what 'normal' data looks like. Anomaly detection can prove to be a vital capability for a strong data governance system by identifying data errors. And for analysis, outliers can be a point of interest in certain cases such as fraud detection and predictive maintenance.
However, as data grows, anomaly detection can prove more and more difficult. High-dimensional data comes with noise and makes it difficult to use for analysis and insights. Large datasets are also likely to have errors and/or special cases. Thankfully, ensemble learning brings speed and efficiency to help us wrangle high-dimensional data and detect anomalies.
What is ensemble learning?
Ensemble learning is a machine learning technique that combines the predictions from multiple individual models to obtain a better predictive performance than any single model. Each model is considered a "weak learner" and is trained on a small subset of the data to make a prediction. Then it goes to a vote. Each weak learner is surveyed and the majority vote wins for the final prediction.
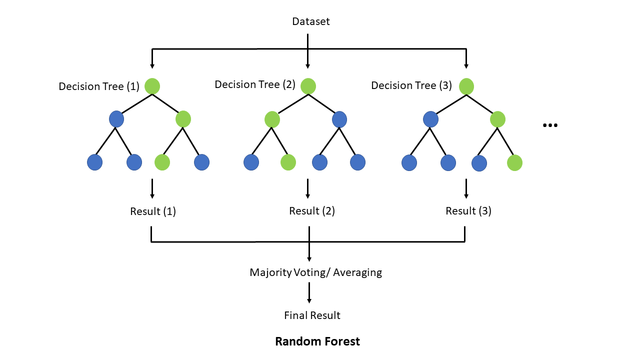 Image by Wikimedia Commons (https://commons.wikimedia.org/wiki/File:Random_forest_explain.png)
Ensemble models (trained on high-quality data) are robust, accurate, efficient, and are good at avoiding overfitting. They have many use cases such as classification, optimization, and in our case, anomaly detection.
The Isolation Forest Model
The isolation forest model is an ensemble of trees that isolates observations that are few and far between. It is very similar to the popular 'Random Forest' model, but instead of a forest of decision trees, the isolation forest produces a forest of 'isolation trees'.
So how does it work? Let's look at one isolation tree.
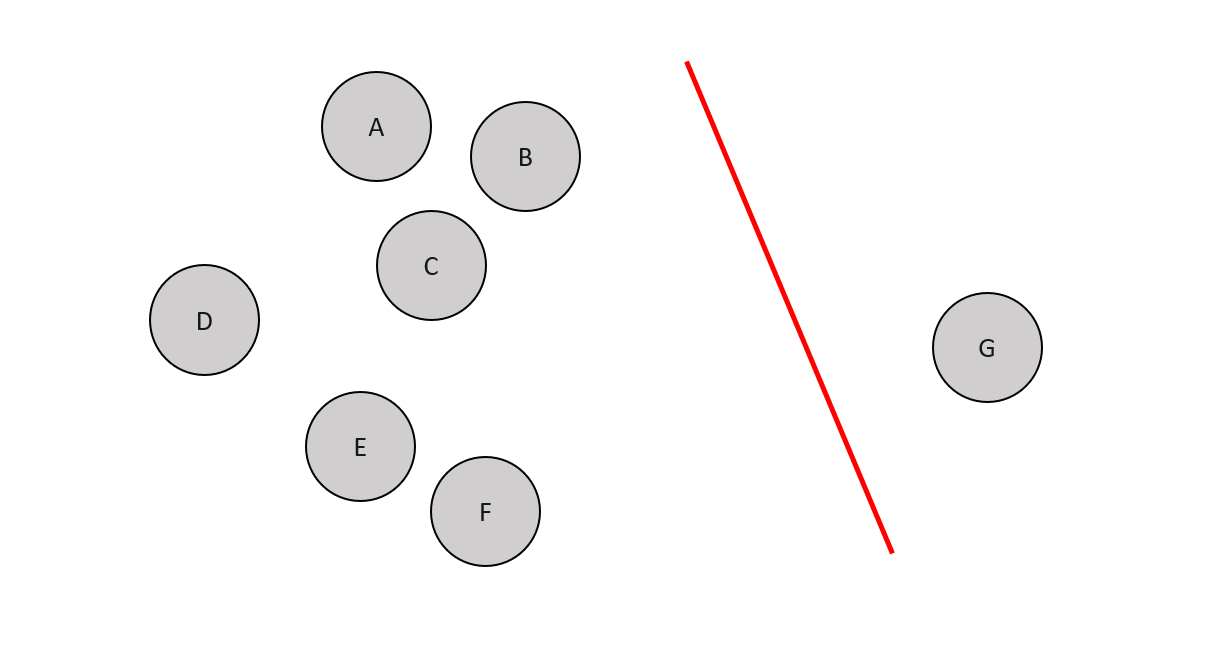 Image by the author
Consider the data above. We can see that one data point is farther away from the rest of the data (our suspected anomaly). Each isolation tree randomly chooses a 'split value' to begin to isolate observations. In this case, the suspected outlier is immediately isolated. This would be the case for most of the isolation trees due to its distance from the rest of the data.
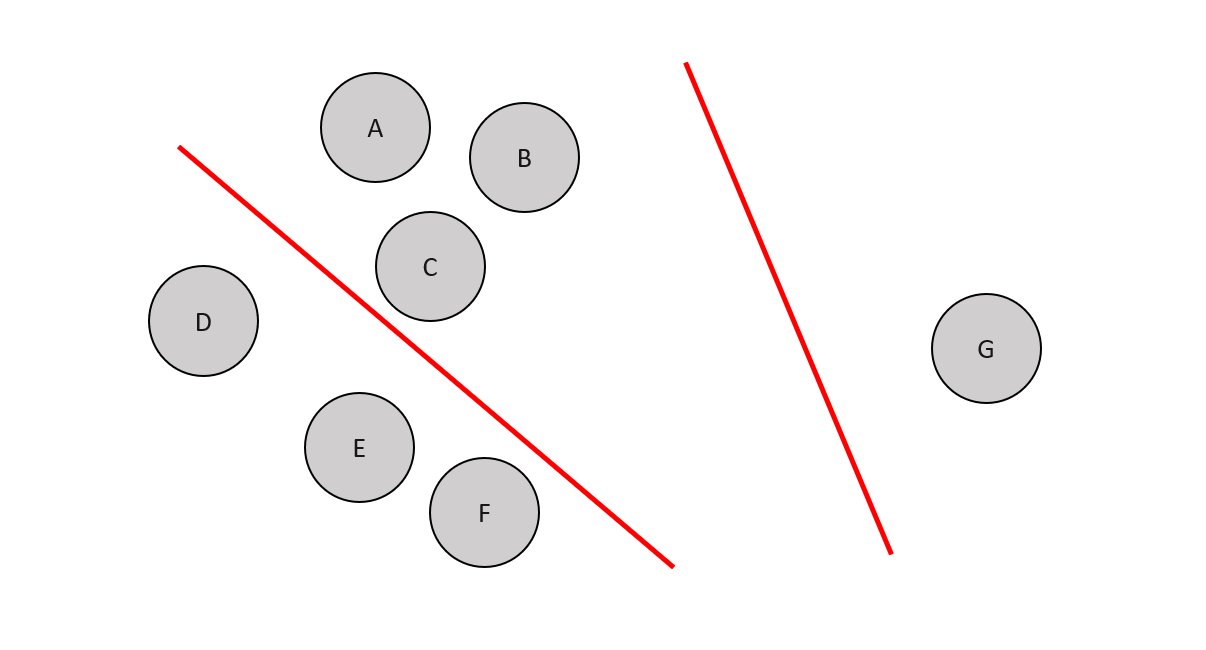 Image by the author
Next, it chooses another split. This time, the suspected 'normal' data begins to get cut up. This process repeats until each observation is isolated. Ultimately, the model 'isolates' observations by randomly selecting a feature and then randomly selecting a split value between the maximum and minimum values of the selected feature.
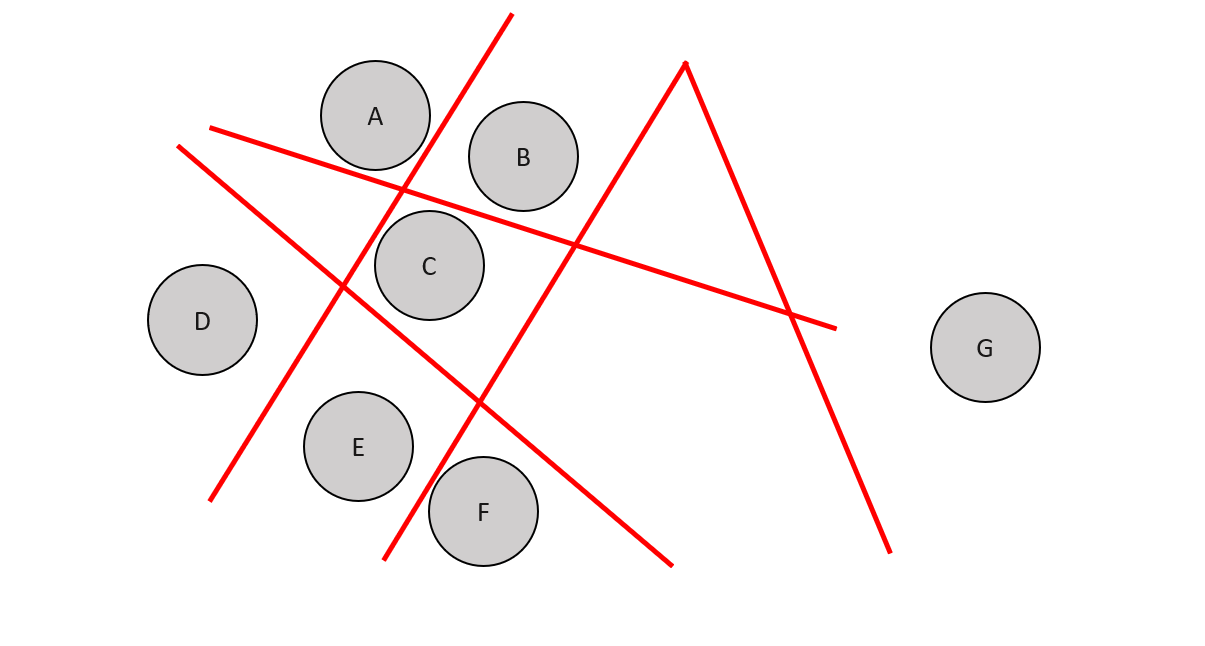 Image by the author
Now that each observation is isolated, we need to ask: How many splits did it take for each observation to be isolated? In other words, how long is the partition path for each data point? Let's say the results are the following:
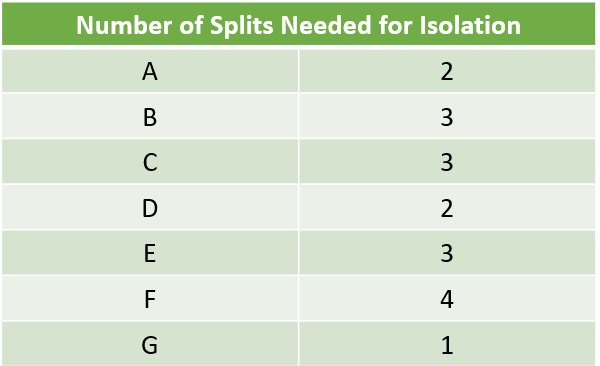 Image by the author
Now that we know how many splits it took to isolate each observation, we calculate the mean number of splits. In our example, on average, it takes 2.6 splits to isolate an observation. Observations that have a noticeably shorter partition path, or took noticeably less splits to be isolated, are highly likely to be anomalies or outliers. The degree to which they differ from the mean number of splits is a parameter in the model. Finally, the isolation tree determines the observation G is an anomaly.
The last step of the isolation forest model is for each isolation tree to 'vote' on which observations are anomalies. If a majority of them think that observation G is an anomaly, then the model determines that it is.
Detecting Anomalies in Time Series Data
Lets see a simple example using the isolation forest model to detect anomalies in time-series data. Below, we have imported a sales data set that contains the day of an order, information about the product, geographical information about the customer, and the amount of the sale. To keep this example simple, lets just look at one feature (sales) over time.
See data here:https://www.kaggle.com/datasets/rohitsahoo/sales-forecasting (GPL 2.0)
python
#packages for data manipulation
import pandas as pd
from datetime import datetime

#packages for modeling
from sklearn.ensemble import IsolationForest

#packages for data visualization
import matplotlib.pyplot as plt
python
#import sales data
sales = pd.read_excel("Data/Sales Data.xlsx")

#subset to date and sales
revenue = sales[['Order Date', 'Sales']]
revenue.head()
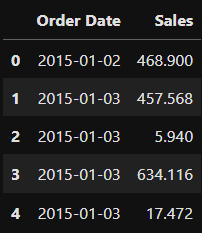 Image by the author
As you can see above, we have the total sale amount for every order on a particular day. Since we have a sufficient amount of data (4 years worth), let's try to detect months where the total sales is either noticeably higher or lower than the expected total sales.
First, we need to conduct some preprocessing, and sum the sales for every month. Then, visualize monthly sales.
python
#format the order date to datetime month and year
revenue['Order Date'] = pd.to_datetime(revenue['Order Date'],format='%Y-%m').dt.to_period('M')

#sum sales by month and year
revenue = revenue.groupby(revenue['Order Date']).sum()

#set date as index
revenue.index = revenue.index.strftime('%m-%Y')
python
#set the fig size
plt.figure(figsize=(8, 5))

#create the line chart
plt.plot(revenue['Order Date'],
         revenue['Sales'])

#add labels and a title
plt.xlabel('Moth')
plt.ylabel('Total Sales')
plt.title('Monthly Sales')

#rotate x-axis labels by 45 degrees for better visibility
plt.xticks(rotation = 90)

#display the chart
plt.show()
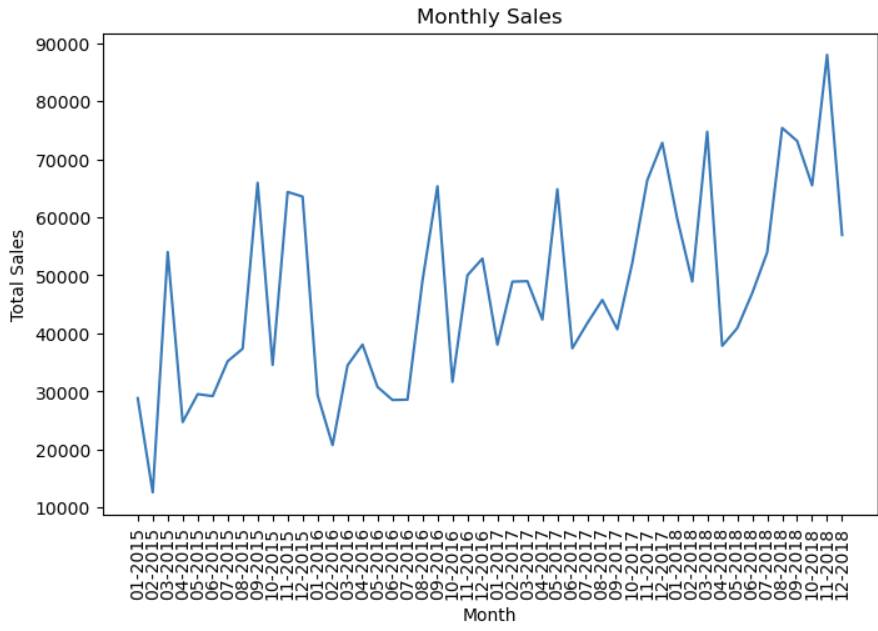 Image by the author
Using the line chart above, we can see that while sales fluctuates from month-to-month, total sales trends upward over time. Ideally, our model will identify months where total sales fluctuates more that expected and is highly influential to our overall trend.
Now we need to initialize and fit our model. The model below uses the default parameters. I have highlighted these parameters as they are the most important to the model's performance.
- n_estimators : The number of base estimators in the ensemble.
- max_samples : The number of samples to draw from X to train each base estimator (if "auto", then
max_samples = min(256, n_samples)).
- contamination : The amount of contamination of the data set, i.e. the proportion of outliers in the data set. Used when fitting to define the threshold on the scores of the samples.
- max_features : The number of features to draw from X to train each base estimator.
python
#set isolation forest model and fit to the sales
model = IsolationForest(n_estimators = 100, max_samples = 'auto', contamination = float(0.1), max_features = 1.0)
model.fit(revenue[['Sales']])
Next, lets use the model to display the anomalies and their anomaly score. The anomaly score is the mean measure of normality of an observation among the base estimators. The lower the score, the more abnormal the observation. Negative scores represent outliers, positive scores represent inliers.
python
#add anomaly scores and prediction
revenue['scores'] = model.decision_function(revenue[['Sales']])
revenue['anomaly'] = model.predict(revenue[['Sales']])
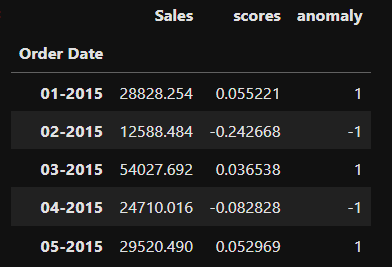 Image by the author
Lastly, lets bring up the same line chart from before, but highlighting the anomalies with plt.scatter.
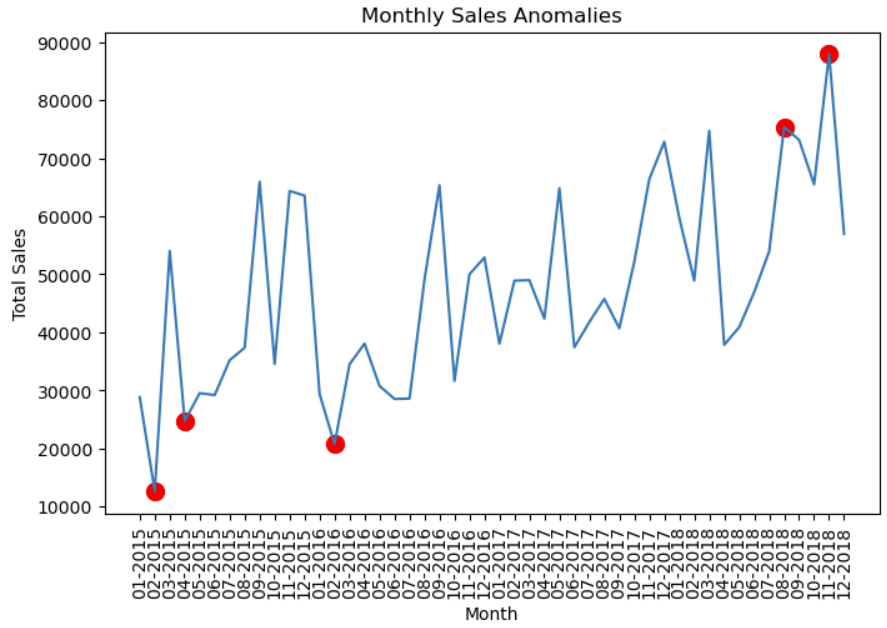 Image by the author
The model appears to do well. Since the data fluctuates so much month-to-month, a worry could be that inliers would get marked as anomalies, but this is not the case due to the bootstrap sampling of the model. The anomalies appear to be the larger fluctuations where sales deviated from the trend a 'significant' amount.
However, knowing the data is important here as some of the anomalies should come with a caveat. Let's look at the first (February 2015) and last (November 2018) anomaly detected. At first, we see that they both are large fluctuations from the mean.
However, the first anomaly (February 2015) is only our second month of recording sales and the business may have just started operating. Sales are definitely low, and we see a large spike the next month. But is it fair to mark the second month of business an anomaly because sales were low? Or is this the norm for a new business?
For our last anomaly (November 2018), we see a huge spike in sales that appears to deviate from the overall trend. However, we have run out of data. As data continues to be recorded, it may not have been an anomaly, but perhaps an identifier of a steeper upwards trend.
Conclusion
In conclusion, anomaly detection is a must-have capability for both strong data governance and rigorous analysis. While detecting outliers and anomalies in large data can be difficult, ensemble learning methods can help as they are robust and efficient with large, tabular data.
The isolation forest model detects these anomalies by for using a forest of 'weak learners' to isolate observations that are few and far between.
I hope you have enjoyed my article! Please feel free to comment, ask questions, or request other topics.
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Alex Davis
Anomaly DetectionEnsemble LearningGetting StartedOutliersPython
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Data Science
CRASH COURSE ON EXPLORATORY DATA ANALYSIS IN PYTHON
TheDataProf
February 15, 20218 min read
Machine Learning
using Python, TensorFlow/Keras and OpenCV
Dmytro Nikolaiev (Dimid)
September 20, 202115 min read
Data Visualization
We will be building a Streamlit Web App to showcase a word cloud of Trending Google Keywords and Twitter Hashtags in 2020
Rahul Banerjee
December 30, 20207 min read
Data Science
Best practices for asyncio.Lock, asyncio.Semaphore, asyncio.Event and asyncio.Condition
Peng Qian
May 29, 20237 min read
Artificial Intelligence
An advanced explanation (Classification tasks) - Part 1
Christos Theodoropoulos
December 21, 20209 min read
Data Science
Exploring the Nuances of Simple Moving Averages and Exponentially Weighted Moving Averages
Eryk Lewinson
October 30, 20239 min read
Programming
Pandas, data.table and SQL
Soner Yıldırım
October 13, 20225 min read
Machine Learning
Writing test cases to verify that functions raise Exceptions with the expected messages
Giorgos Myrianthous
October 11, 20223 min read
Machine Learning
Improve your grid search with this small change
Eryk Lewinson
March 14, 20226 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close