保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Machine Learning
The Machine Learning “Advent Calendar” Day 20: Gradient Boosted Linear Regression in Excel
From random ensembles to optimization: gradient boosting explained
Angela and Kezhan Shi
December 22, 20259 min read
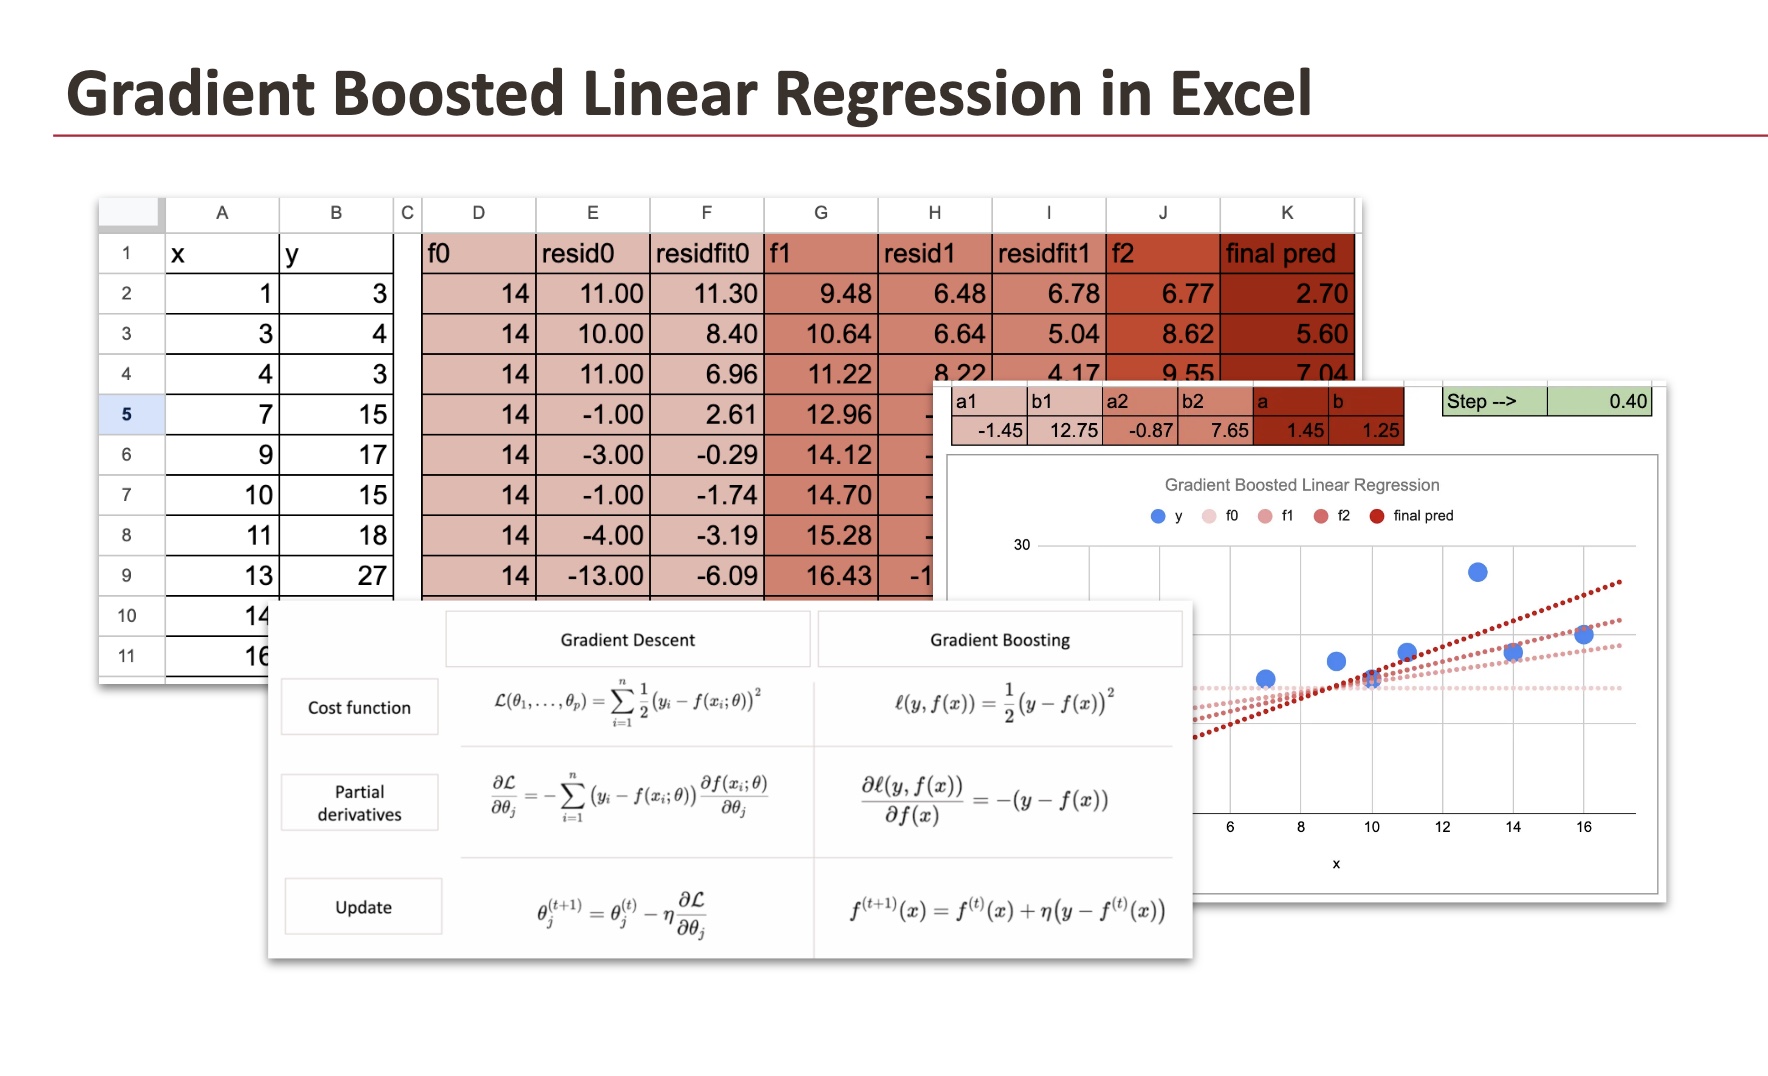 Gradient Boosted Linear Regression in excel
In the previous article, we introduced ensemble learning with voting, bagging and Random Forest.
Voting itself is only an aggregation mechanism. It does not create diversity, but combines predictions from already different models.
Bagging, on the other hand, explicitly creates diversity by training the same base model on multiple bootstrapped versions of the training dataset.
Random Forest extends bagging by additionally restricting the set of features considered at each split.
From a statistical point of view, the idea is simple and intuitive: diversity is created through randomness, without introducing any fundamentally new modeling concept.
But ensemble learning does not stop there.
There exists another family of ensemble methods that does not rely on randomness at all, but on optimization. Gradient Boosting belongs to this family. And to truly understand it, we will start with a deliberately strange idea:
We will apply Gradient Boosting to Linear Regression.
Yes, I know. This is probably the first time you have heard about applying Gradient Boosted Linear Regression.
(We will see Gradient Boosted Decision Trees, tomorrow).
In this article, here is the plan:
- First, we will step back and revisit the three fundamental steps of machine learning.
- Then, we will introduce the Gradient Boosting algorithm.
- Next, we will apply Gradient Boosting to linear regression.
- Finally, we will reflect on the relationship between Gradient Boosting and Gradient Descent.
Learn this step by step with the interactive Machine Learning roadmap.
1. Machine Learning in Three steps
To make machine learning easier to learn, I always separate it into three clear steps. Let us apply this framework to Gradient Boosted Linear Regression.
Because unlike bagging, each step reveals something interesting.
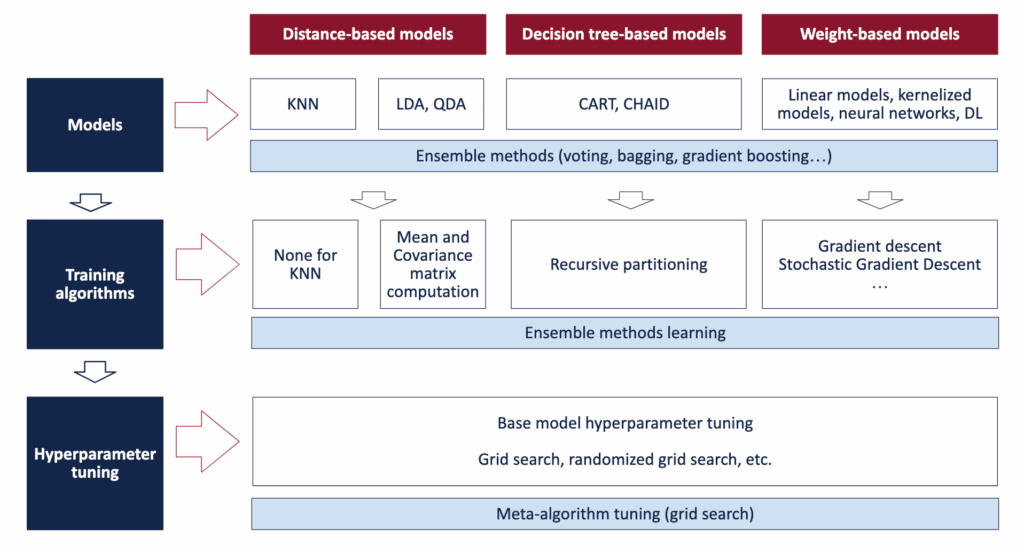 Trois learning steps in Machine Learning - all images by author
1. Model
A model is something that takes input features and produces an output prediction.
In this article, the base model will be Linear Regression.
1 bis. Ensemble Method Model
Gradient Boosting is not a model itself. It is an ensemble method that aggregates several base models into a single meta-model. On its own, it does not map inputs to outputs. It must be applied to a base model.
Here, Gradient Boosting will be used to aggregate linear regression models.
2. Model fitting
Each base model must be fitted to the training data.
For Linear Regression, fitting means estimating the coefficients. This can be done numerically using Gradient Descent, but also analytically. In Google Sheets or Excel, we can directly use the
LINEST function to estimate these coefficients.
2 bis. Ensemble model learning
At first, Gradient Boosting may look like a simple aggregation of models. But it is still a learning process. As we will see, it relies on a loss function, exactly like classical models that learn weights.
3. Model tuning
Model tuning consists of optimizing hyperparameters.
In our case, the base model Linear Regression itself has no hyperparameters (unless we use regularized variants such as Ridge or Lasso).
Gradient Boosting, however, introduces two important hyperparameters: the number of boosting steps and the learning rate. We will see this in the next section.
In a nutshell, that is machine learning, made easy, in three steps!
2. Gradient Boosting Regressor algorithm
2.1 Algorithm principle
Here are the main steps of the Gradient Boosting algorithm, applied to regression.
- Initialization : We start with a very simple model. For regression, this is usually the average value of the target variable.
- Residual Errors Calculation : We compute residuals, defined as the difference between the actual values and the current predictions.
- Fitting Linear Regression to Residuals : We fit a new base model (here, a linear regression) to these residuals.
- Update the ensemble : We add this new model to the ensemble, scaled by a learning rate (also called shrinkage).
- Repeating the process : We repeat steps 2 to 4 until we reach the desired number of boosting iterations or until the error converges.
That’s it! This is the basic procedure for performing a Gradient Boosting applied to Linear Regression.
2.2 Algorithm expressed with formulas
Now we can write the formulas explicitly, it helps make each step concrete.
Step 1 - Initialization
We start with a constant model equal to the average of the target variable:
f0 = average(y)
Step 2 – Residual computation
We compute the residuals, defined as the difference between the actual values and the current predictions:
r1 = y − f0
Step 3 – Fit a base model to the residuals
We fit a linear regression model to these residuals:
r̂1 = a0 · x + b0
Step 4 – Update the ensemble
We update the model by adding the fitted regression, scaled by the learning rate:
f1 = f0 − learning_rate · (a0 · x + b0)
Next iteration
We repeat the same procedure:
r2 = y − f1
r̂2 = a1 · x + b1
f2 = f1 − learning_rate · (a1 · x + b1)
By expanding this expression, we obtain:
f2 = f0 − learning_rate · (a0 · x + b0) − learning_rate · (a1 · x + b1)
The same process continues at each iteration. Residuals are recomputed, a new model is fitted, and the ensemble is updated by adding this model with a learning rate.
This formulation makes it clear that Gradient Boosting builds the final model as a sum of successive correction models.
3. Gradient Boosted Linear Regression
3.1 Base model training
We start with a simple linear regression as our base model, using a small dataset of ten observations that I generated.
For the fitting of the base model, we will use a function in Google Sheet (it also works in Excel): LINEST to estimate the coefficients of the linear regression.
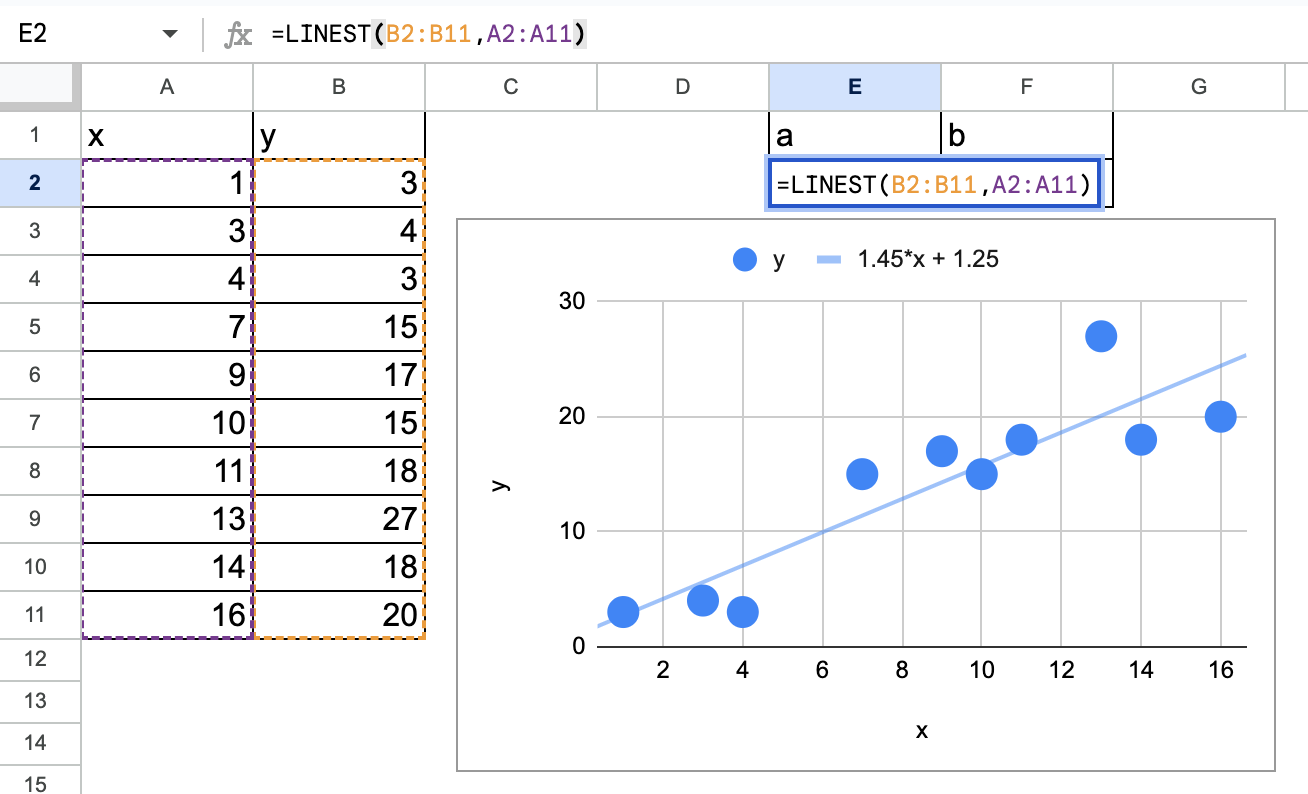 Gradient Boosted Linear Regression \ Simple dataset with linear regression — Image by author
3.2 Gradient Boosting algorithm
The implementation of these formulas is straightforward in Google Sheet or Excel.
The table below shows the training dataset along with the different steps of the gradient boosting steps:
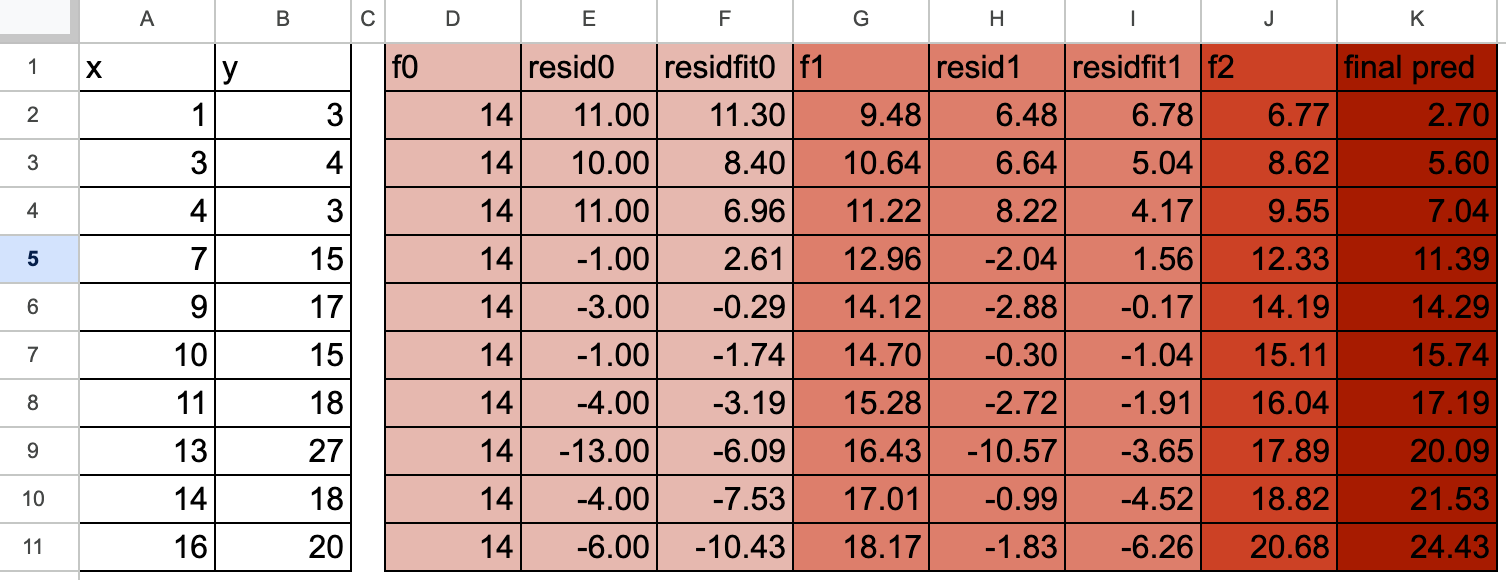 Gradient Boosted Linear Regression with all steps in Excel — Image by author
For each fitting step, we use the Excel function LINEST:
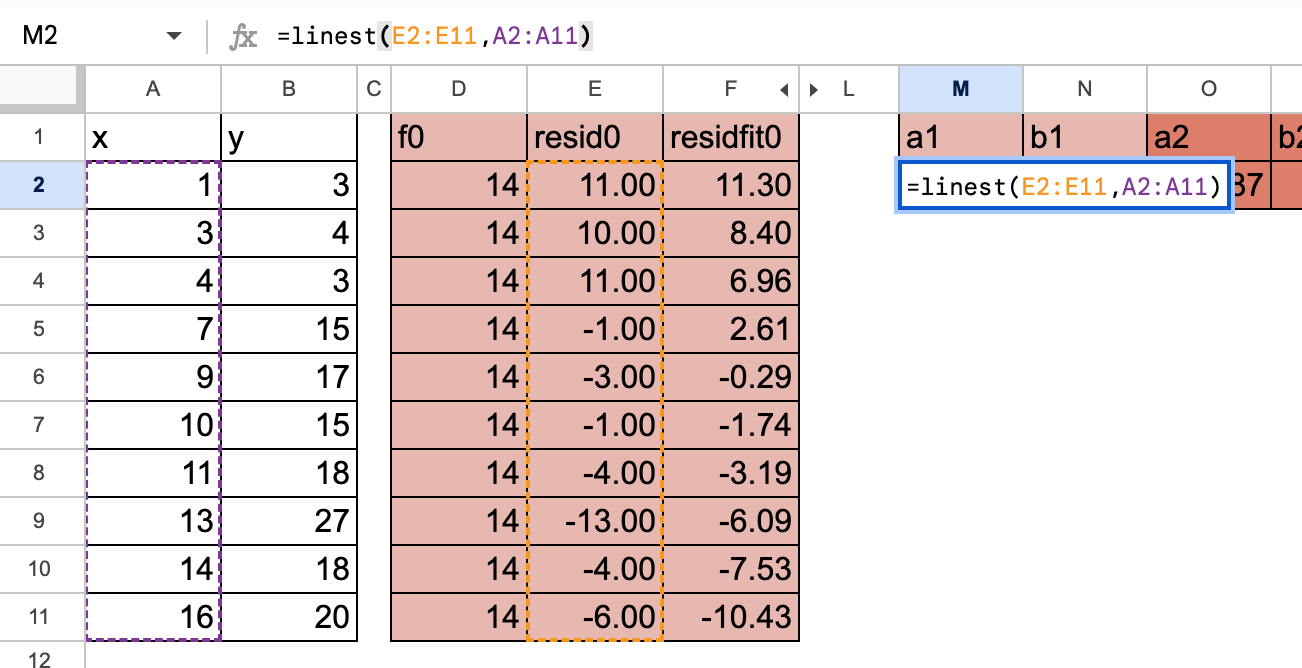 Gradient Boosted Linear Regression with formula for coefficient estimation — Image by author
We will only do 2 iterations, and we can guess how it goes for more iterations. Here below is a graphic to show the models at each iteration. The different shades of red illustrate the convergence of the model and we also show the final model that is directly found with gradient descent applied directly to y.
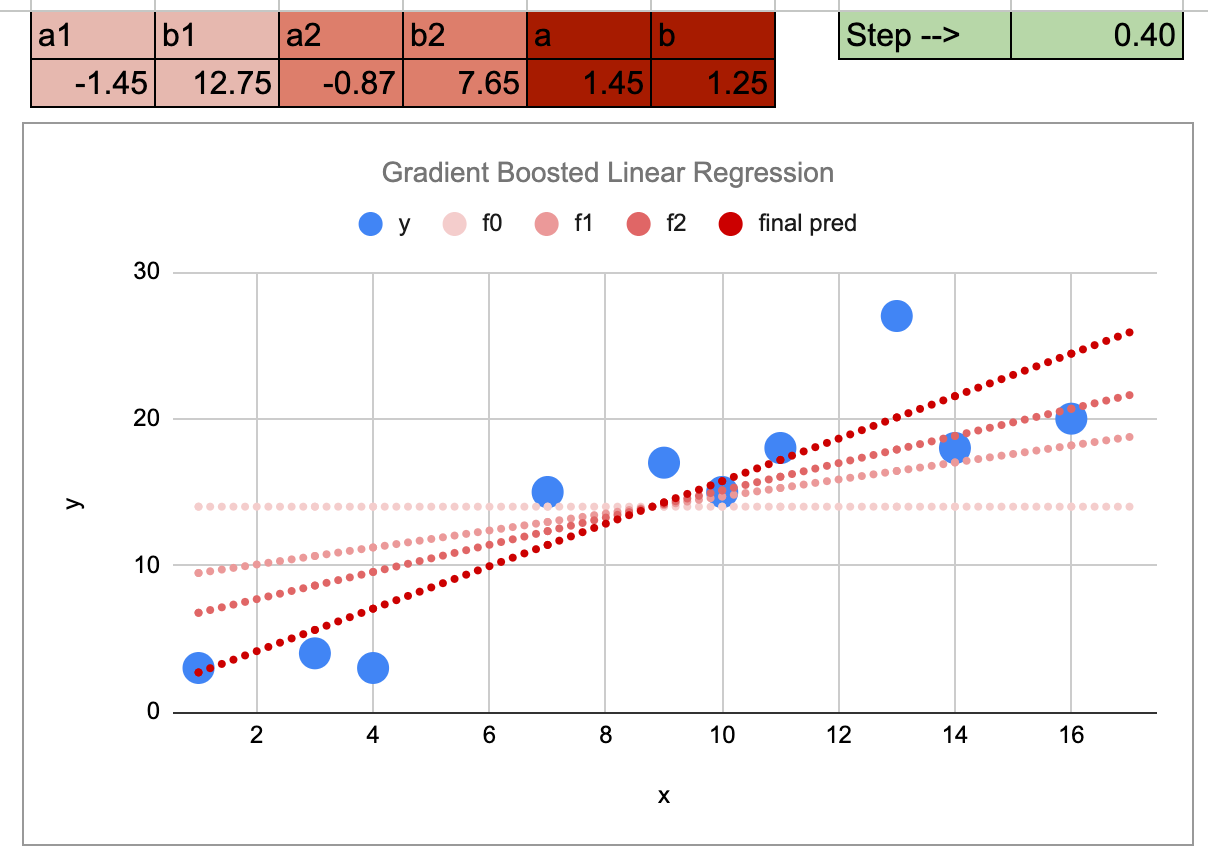 Gradient Boosted Linear Regression — Image by author
3.3 Why Boosting Linear Regression is purely pedagogical
If you look carefully at the algorithm, two important observations emerge.
First, in step 2, we fit a linear regression to residuals, it will take time and algorithmic steps to achieve the model fitting steps, instead of fitting a linear regression to residuals, we can directly fit a linear regression to the actual values of y, and we already would find the final optimal model!
Secondly, when adding a linear regression to another linear regression, it is still a linear regression.
For example, we can rewrite f2 as:
f2 = f0 - learning_rate *(b0+b1) - learning_rate * (a0+a1) x
This is still a linear function of x.
This explains why Gradient Boosted Linear Regression does not bring any practical benefit. Its value is purely pedagogical: it helps us understand how the Gradient Boosting algorithm works, but it does not improve predictive performance.
In fact, it is even less useful than bagging applied to linear regression. With bagging, the variability between bootstrapped models allows us to estimate prediction uncertainty and construct confidence intervals. Gradient Boosted Linear Regression, on the other hand, collapses back to a single linear model and provides no additional information about uncertainty.
As we will see tomorrow, the situation is very different when the base model is a decision tree.
3.4 Tuning hyperparameters
There are two hyperparameters we can tune: the number of iterations and the learning rate.
For the number of iterations, we only implemented two, but it is easy to imagine more, and we can stop by examining the magnitude of the residuals.
For the learning rate, we can change it in Google Sheet and see what happens. When the learning rate is small, the “learning process” will be slow. And if the learning rate is 1, we can see that the convergence is achieved at iteration 1.
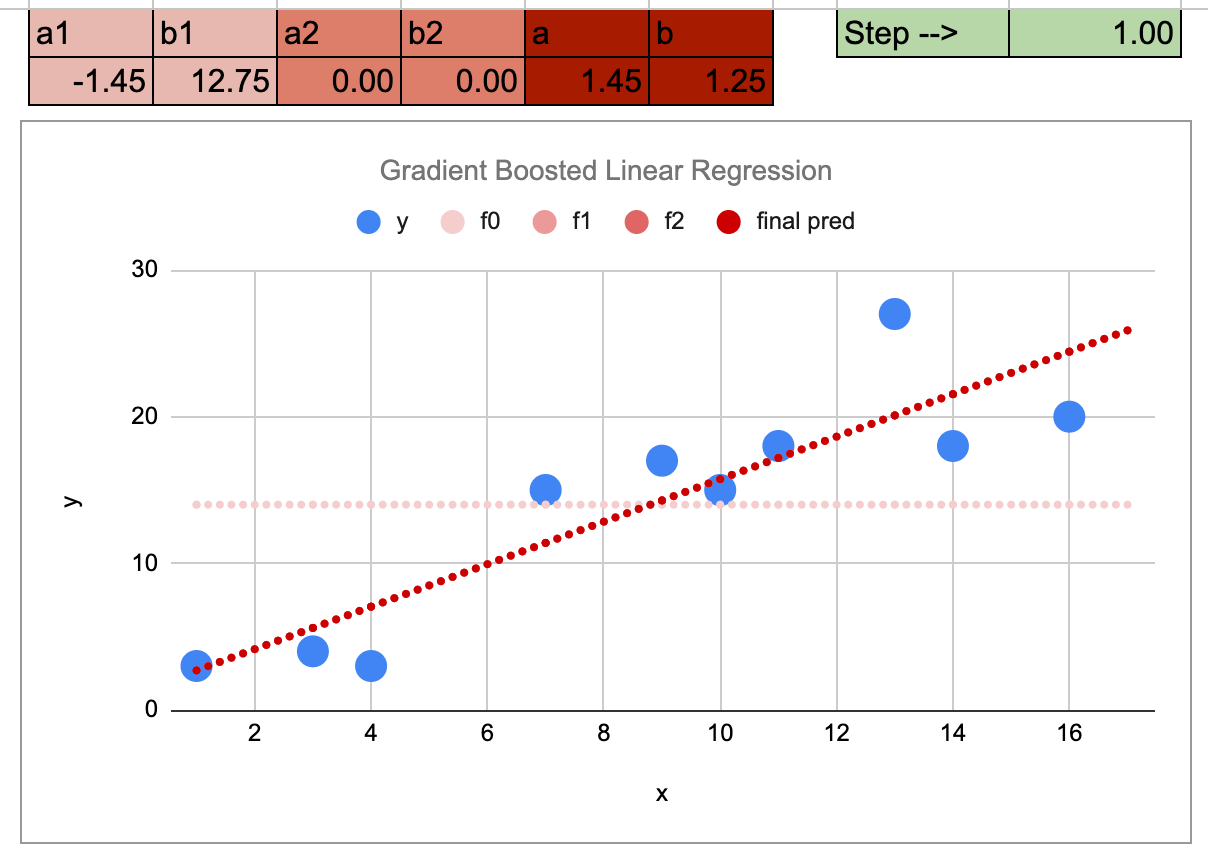 Gradient Boosted Linear Regression with learning rate =1— Image by author
And the residuals of iteration 1 are already zeros.
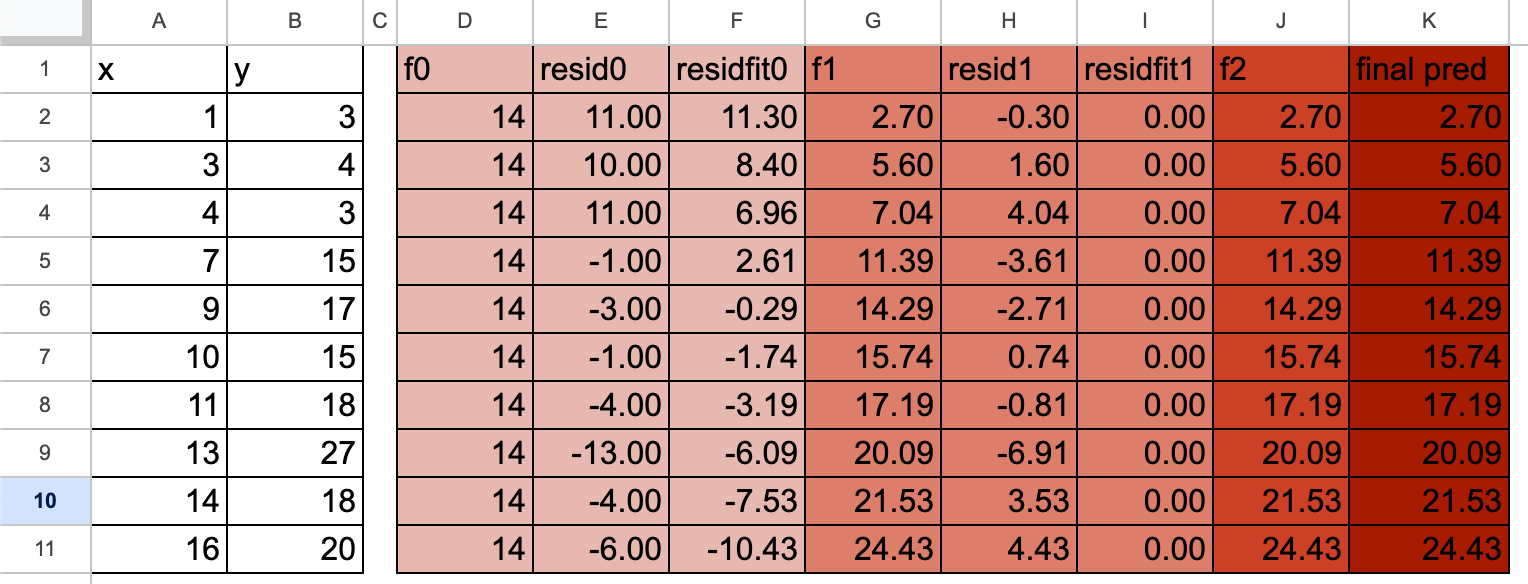 Gradient Boosted Linear Regression with learning rate =1— Image by author
If the learning rate is higher than 1, then the model will diverge.
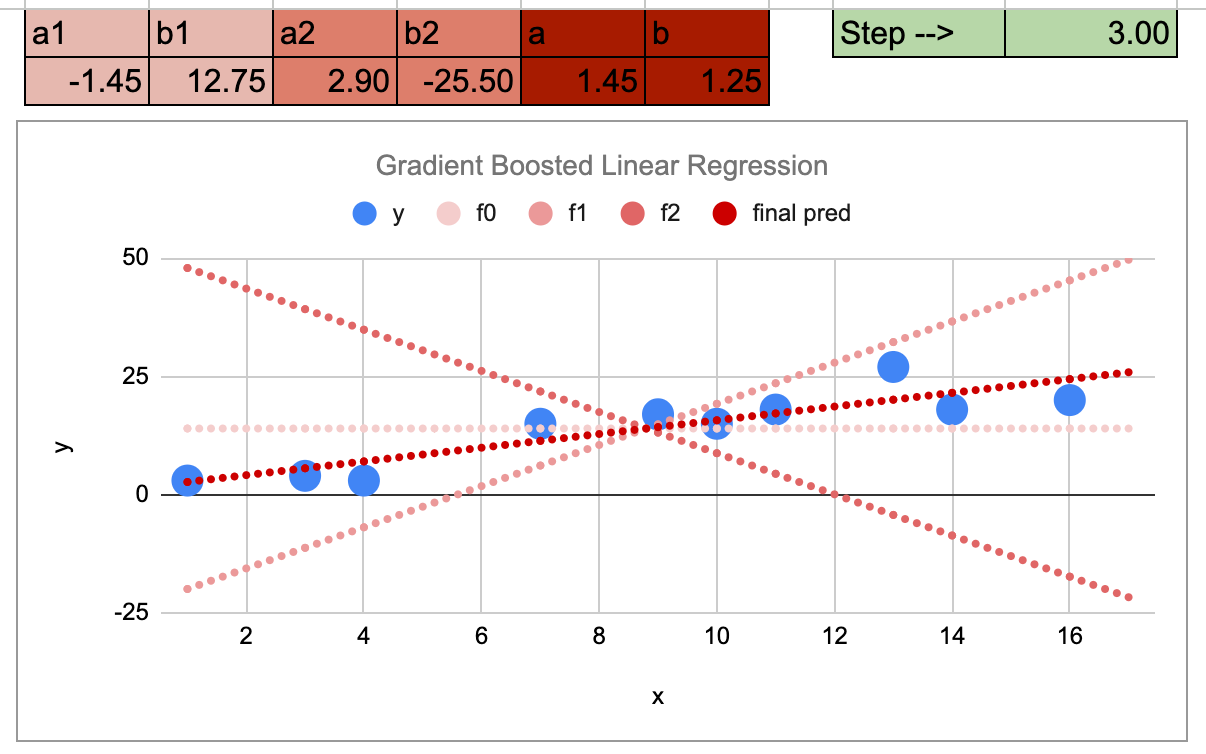 Gradient Boosted Linear Regression Divergence— Image by author
4. Boosting as Gradient Descent in Function Space
4.1 Comparison with Gradient Descent Algorithm
At first glance, the role of the learning rate and the number of iterations in Gradient Boosting looks very similar to what we see in Gradient Descent. This naturally leads to confusion.
- Beginners often notice that both algorithms contain the word "gradient " and follow an iterative procedure. It is therefore tempting to assume that Gradient Descent and Gradient Boosting are closely related, without really knowing why.
- Experienced practitioners usually react differently. From their perspective, the two methods appear unrelated. Gradient Descent is used to fit weight-based models by optimizing their parameters, while Gradient Boosting is an ensemble method that combines multiple models fitted with the residuals. The use cases, the implementations, and the intuition seem completely different.
- At a deeper level , however, experts will say that these two algorithms are in fact the same optimization idea. The difference does not lie in the learning rule, but in the space where this rule is applied. Or we can say that the variable of interest is different.
Gradient Descent performs gradient-based updates in parameter space. Gradient Boosting performs gradient-based updates in function space.
That is the only difference in this mathematical numerical optimization. Let's see the equations in the case of regression and in the general case below.
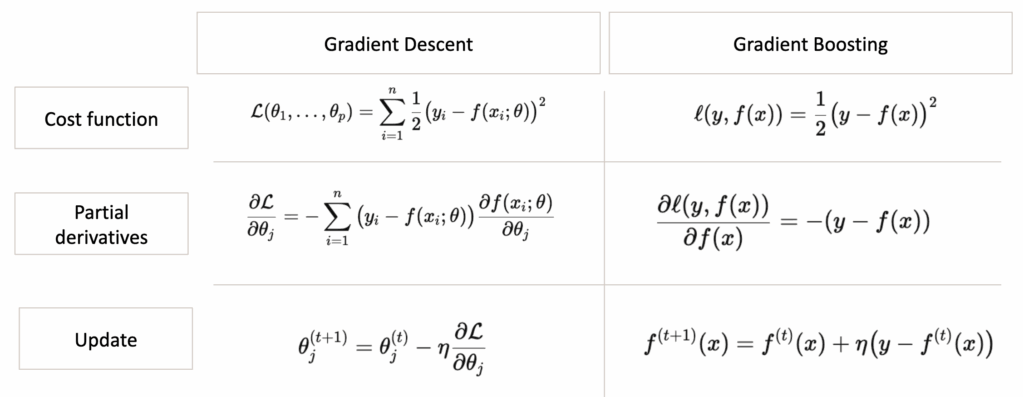
4.2 The Mean Squared Error Case: Same Algorithm, Different Space
With the Mean Squared Error, Gradient Descent and Gradient Boosting minimize the same objective and are driven by the same quantity: the residual.
In Gradient Descent, residuals influence the updates of the model parameters.
In Gradient Boosting, residuals directly update the prediction function.
In both cases, the learning rate and the number of iterations play the same role. The difference lies only in where the update is applied: parameter space versus function space.
Once this distinction is clear, it becomes evident that Gradient Boosting with MSE is simply Gradient Descent expressed at the level of functions.
4.3 Gradient Boosting with any loss function
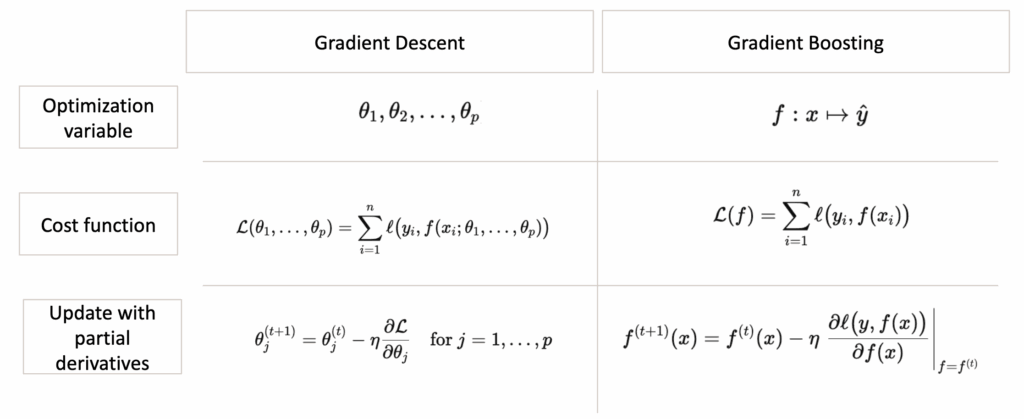
The comparison above is not limited to the Mean Squared Error. Both Gradient Descent and Gradient Boosting can be defined with respect to different loss functions.
In Gradient Descent, the loss is defined in parameter space. This requires the model to be differentiable with respect to its parameters, which naturally restricts the method to weight-based models.
In Gradient Boosting, the loss is defined in prediction space. Only the loss must be differentiable with respect to the predictions. The base model itself does not need to be differentiable, and of course, it does not need to have its own loss function.
This explains why Gradient Boosting can combine arbitrary loss functions with non–weight-based models such as decision trees.
Conclusion
Gradient Boosting is not just a naive ensemble technique but an optimization algorithm. It follows the same learning logic as Gradient Descent, differing only in the space where the optimization is performed: parameters versus functions. Using linear regression allowed us to isolate this mechanism in its simplest form.
In the next article, we will see how this framework becomes truly powerful when the base model is a decision tree, leading to Gradient Boosted Decision Tree Regressors.
A note on learning order
Gradient Boosting is often presented as the most powerful ensemble method, and it is indeed very popular in practice.
However, understanding ensemble learning does not start with Boosting.
Bagging remains a simpler and more fundamental approach, especially from a statistical point of view.
It makes variance reduction explicit and offers useful insight into prediction uncertainty, which complements the optimization perspective of Gradient Boosting.
···
All the Excel files are available through this Kofi link. Your support means a lot to me. The price will increase during the month, so early supporters get the best value.
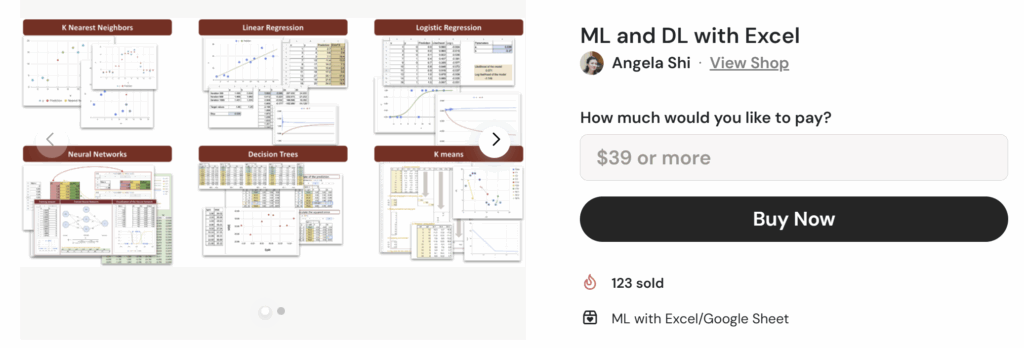 All Excel/Google sheet files for ML and DL
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Angela and Kezhan Shi
Deep DivesArtificial IntelligenceData ScienceGradient BoostingStatistics
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Machine Learning
Using Python and the mindee API to automate expense reports It used to be that...
Lucas Soares
December 2, 20226 min read
Machine Learning
Adapting CLIP to YouTube Data (with Python Code)
Shaw Talebi
January 31, 202510 min read
Data Science
A simple trick for improving model performance when labels are ordered.
Mathias Gruber
July 10, 20217 min read
Machine Learning
For this article, I will be using the following academic paper as a reference...
Ana Preciado
November 8, 20204 min read
Machine Learning
With simple words and few formulas, you will get fully proficency in Bayes, the Maximum Likelihood Estimation and the Maximum A Posteriori.
Adrian PD
July 23, 20217 min read
Artificial Intelligence
A quick guide to deploying an ML model with FastAPI and easily containerizing it within VSCode itself.
Yash Prakash
December 19, 20215 min read
Project Management
How data science can help project managers anticipate risks and save time
Yassin Zehar
October 17, 202510 min read
Data Science
Our weekly selection of must-read Editors' Picks and original features
TDS Editors
April 4, 20243 min read
Machine Learning
A description in simple terms for the motivation and approach for sampling using simple or Markov Chain Monte Carlo methods
Gabriela Morgenshtern
April 15, 20217 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close