保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Data Science
Spearman coefficient: Tool for a generalized correlation analysis
Linear relationships are not all a correlation analysis can reveal. We discuss rank-based correlation that is more generalized and...
Tirthajyoti Sarkar
November 1, 20214 min read
Linear relationships are not all a correlation analysis can reveal. We discuss rank-based correlation that is more generalized and powerful.
Beyond linear relationship
It's a common data science interview question.
Say, y = _x_² + noise, you plot y vs. x and try to determine the correlation coefficient. What will it be?
Most interviewers won't give you credit if you say anything other than zero. The word correlation, in most circumstances, invokes the concept of linearity or linear relationship between variables.
Here is a visual illustration of what I meant.
Learn this step by step with the interactive AI and Data Scientist, Computer Science, Machine Learning and Data Analyst roadmaps.
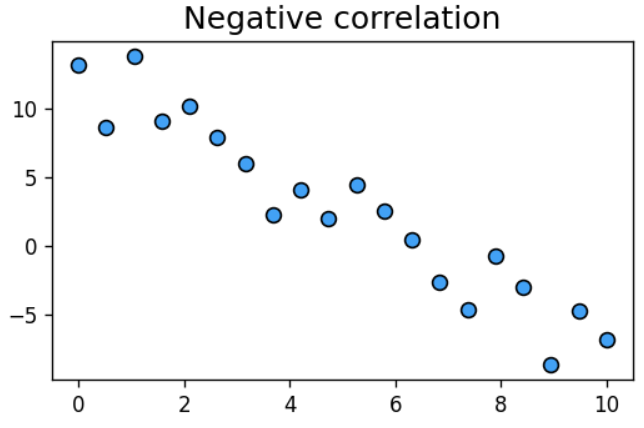
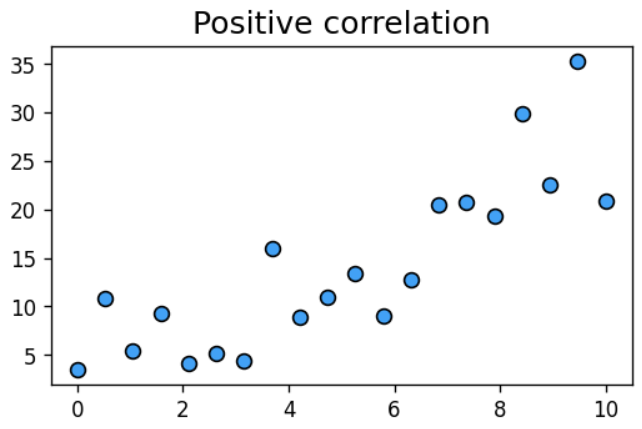
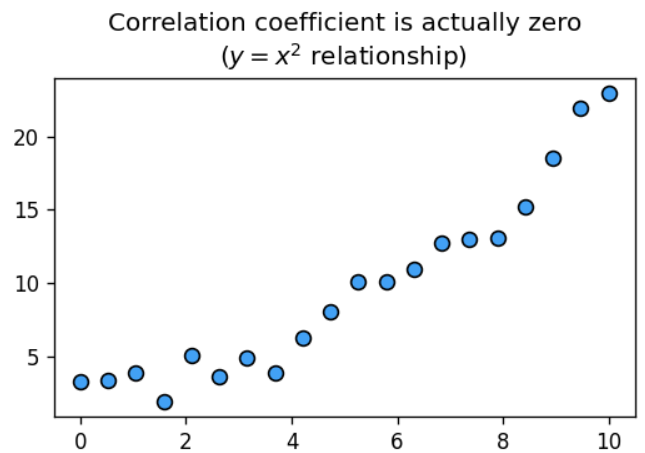 Image source: Created by the author
This notion of linearity is coming from the definition of a particular correlation coefficient that is most widely used in statistical analysis or in data science - Pearson's coefficient.
It is named after the famous English statistician Karl Pearson and is given by,
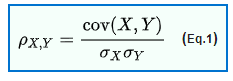 where cov(X ,Y) is the covariance of two random variables X and Y and the denominator consists of the product of their standard deviations.
 Karl Pearson, Image source:Wikimedia, Free media to use
Pearson's coefficient suffices for a first-order analysis but suffers from outliers and cannot handle nonlinearity by definition. Therefore, there is a need to look beyond the linear correlation analysis.
For such generalized correlation analysis, there are a few more tools. Among them, Spearman's coefficient is the most straightforward to understand and calculate. In this article, we will discuss that.
Spearman's coefficient
Spearman's coefficient is a rank correlation (a measure of statistical dependence between the rankings of two random variables). It is named after Charles Spearman, an English psychologist, famous for factor analysis among other contributions.
So, how is this different from the regular correlation coefficient we are familiar with? Spearman coefficient is different in the sense that it is not just about the raw numerical values, but about rankings.
What's a rank?
So, what is a rank? Here is the Wikipedia definition,
"A ranking is a relationship between a set of items such that, for any two items, the first is either "ranked higher than", "ranked lower than" or "ranked equal to" the second. "
Take two sets of numbers - 1,2,3 and 10,24,102. The exact numerical relationship between these sets may look odd, but they are very similar in a "one-to-one" sense if we consider their ranking only. The second number in each set is greater than the first one and it is lesser than the third number. Two sets are identical from that point of view. The relative order matters and not the actual numerical values.
The Pearson (linear) correlation coefficient of these two sets can be quite different than 1. But the Spearman's coefficient will be a perfect 1.
Following a similar formula like the Pearson coefficient, it is given by,
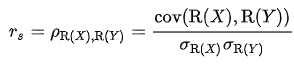 The only difference is that all the raw numerical values are replaced by their rank values (i.e., order values 1st, 2nd, 3rd, 50th percentile, etc.).
An example with Python
Using the Scipy library, it is quite simple to evaluate the Spearman coefficient of two sets of 1-D or 2-D arrays.
Let's show the stark difference between the two types of correlation with a canonical example,
text
import numpy as np, matplotlib.pyplot as plt
import scipy.stats as stat
text
x = np.linspace(0,10,20)
y = np.log(1+1/(x+0.1))
text
pearson = stat.pearsonr(x,y)
spearman = stat.spearmanr(x,y)
If we check their values, they will be -0.65 and -1.0 respectively. Here is the visual representation,
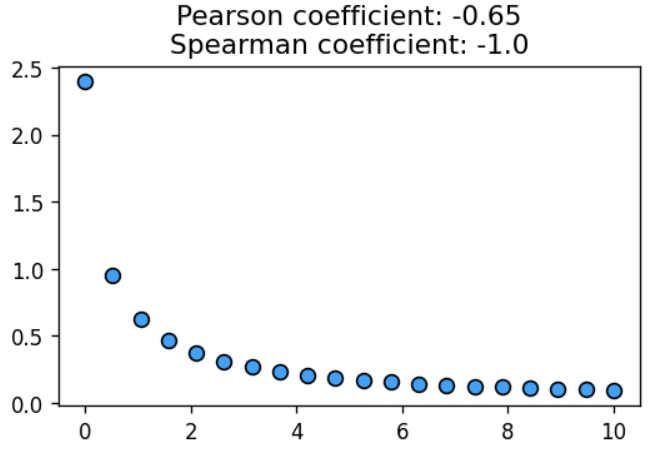 Image source: Created by the author
Why is Spearman's coefficient a perfect -1.0? Because the rank order is exactly identical between the two arrays. As long as the underlying function follows a monotonic (increasing or decreasing) order, this will be true. Obviously, the generating function is a highly nonlinear one (inverse of a logarithm) but that does not impact Spearman's coefficient.
Spearman coefficient is more robust to outliers
If we introduce some random outliers to the same arrays as above, we will see that Spearman's coefficient is more robust to those outliers as the rank order is disturbed much less than the actual numeric values. Here is a sample result with outliers.
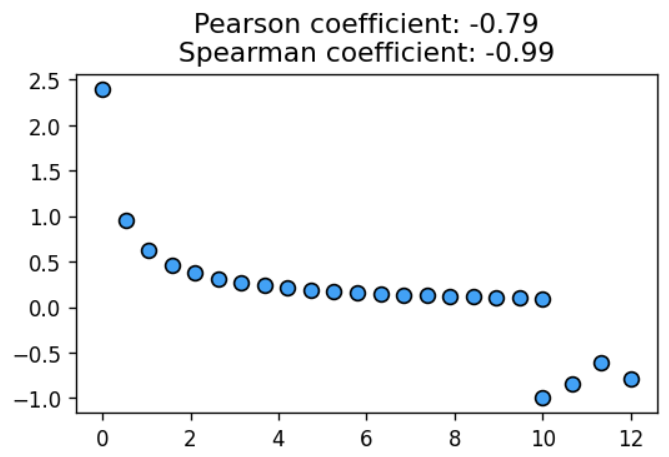 Image source: Created by the author
The Pearson's coefficient is disturbed by the outliers (from -0.65 to -0.79), but the Spearman's coefficient hardly moved (from -1.0 to -0.99).
Summary
In this article, we discussed Spearman's coefficient which is equivalent to the more widely used Pearson's coefficient but for ranked orders of inter-related arrays. It is a special case of more generalized correlation analysis that looks at multiple levels of properties associated with arrays of numbers or sets of values that two random variables can assume.
In many cases, going beyond the linear Pearson coefficient can be used such as in the presence of outliers or when rank ordering is more interesting to analyze than raw numerical values. Concepts like Spearman's coefficient will come in handy for data scientists in such scenarios.
Loved the article? Become a Medium member to continue learning without limits . I'll receive a portion of your membership fee if you use the following link,__with no extra cost to you .
Join Medium with my referral link - Tirthajyoti Sarkar
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from Tirthajyoti Sarkar
AnalyticsData ScienceMachine LearningTechnology
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
Read to learn about the back-propagation algorithm in the context of Deep Learning
Manpreet Singh Minhas
December 19, 20205 min read
Artificial Intelligence
A simple demonstration of character-level seq2seq learning applied to a complex task: converting between Hebrew text and Latin...
Morris Alper
June 28, 202311 min read
Data Science
There are at least 101 Examples of Machine Learning Data Scientists can use to Create Valuable Insights. Here they are.
Ron Ozminkowski, PhD
November 30, 202133 min read
Programming
Using Fourier Transform to detect seasonal components
Lorenzo Mezzini
February 3, 20257 min read
Data Science
Metrics frameworks for data scientists to ace product sense interviews
Emma Ding
March 9, 202111 min read
Artificial Intelligence
A practical guide
Soner Yıldırım
February 2, 20227 min read
Statistics
A generalized version of Kaplan-Meier allows to model a continuous value (like money) instead of a binary signal (like survival)
Samuele Mazzanti
May 13, 20259 min read
Machine Learning
Create an experiment, train and use checkpoints for a Transformer model
Eduardo Muñoz
November 19, 20202 min read
Data Science
Evaluating Classifiers with a Custom Function
Darius Fuller
September 25, 20209 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close