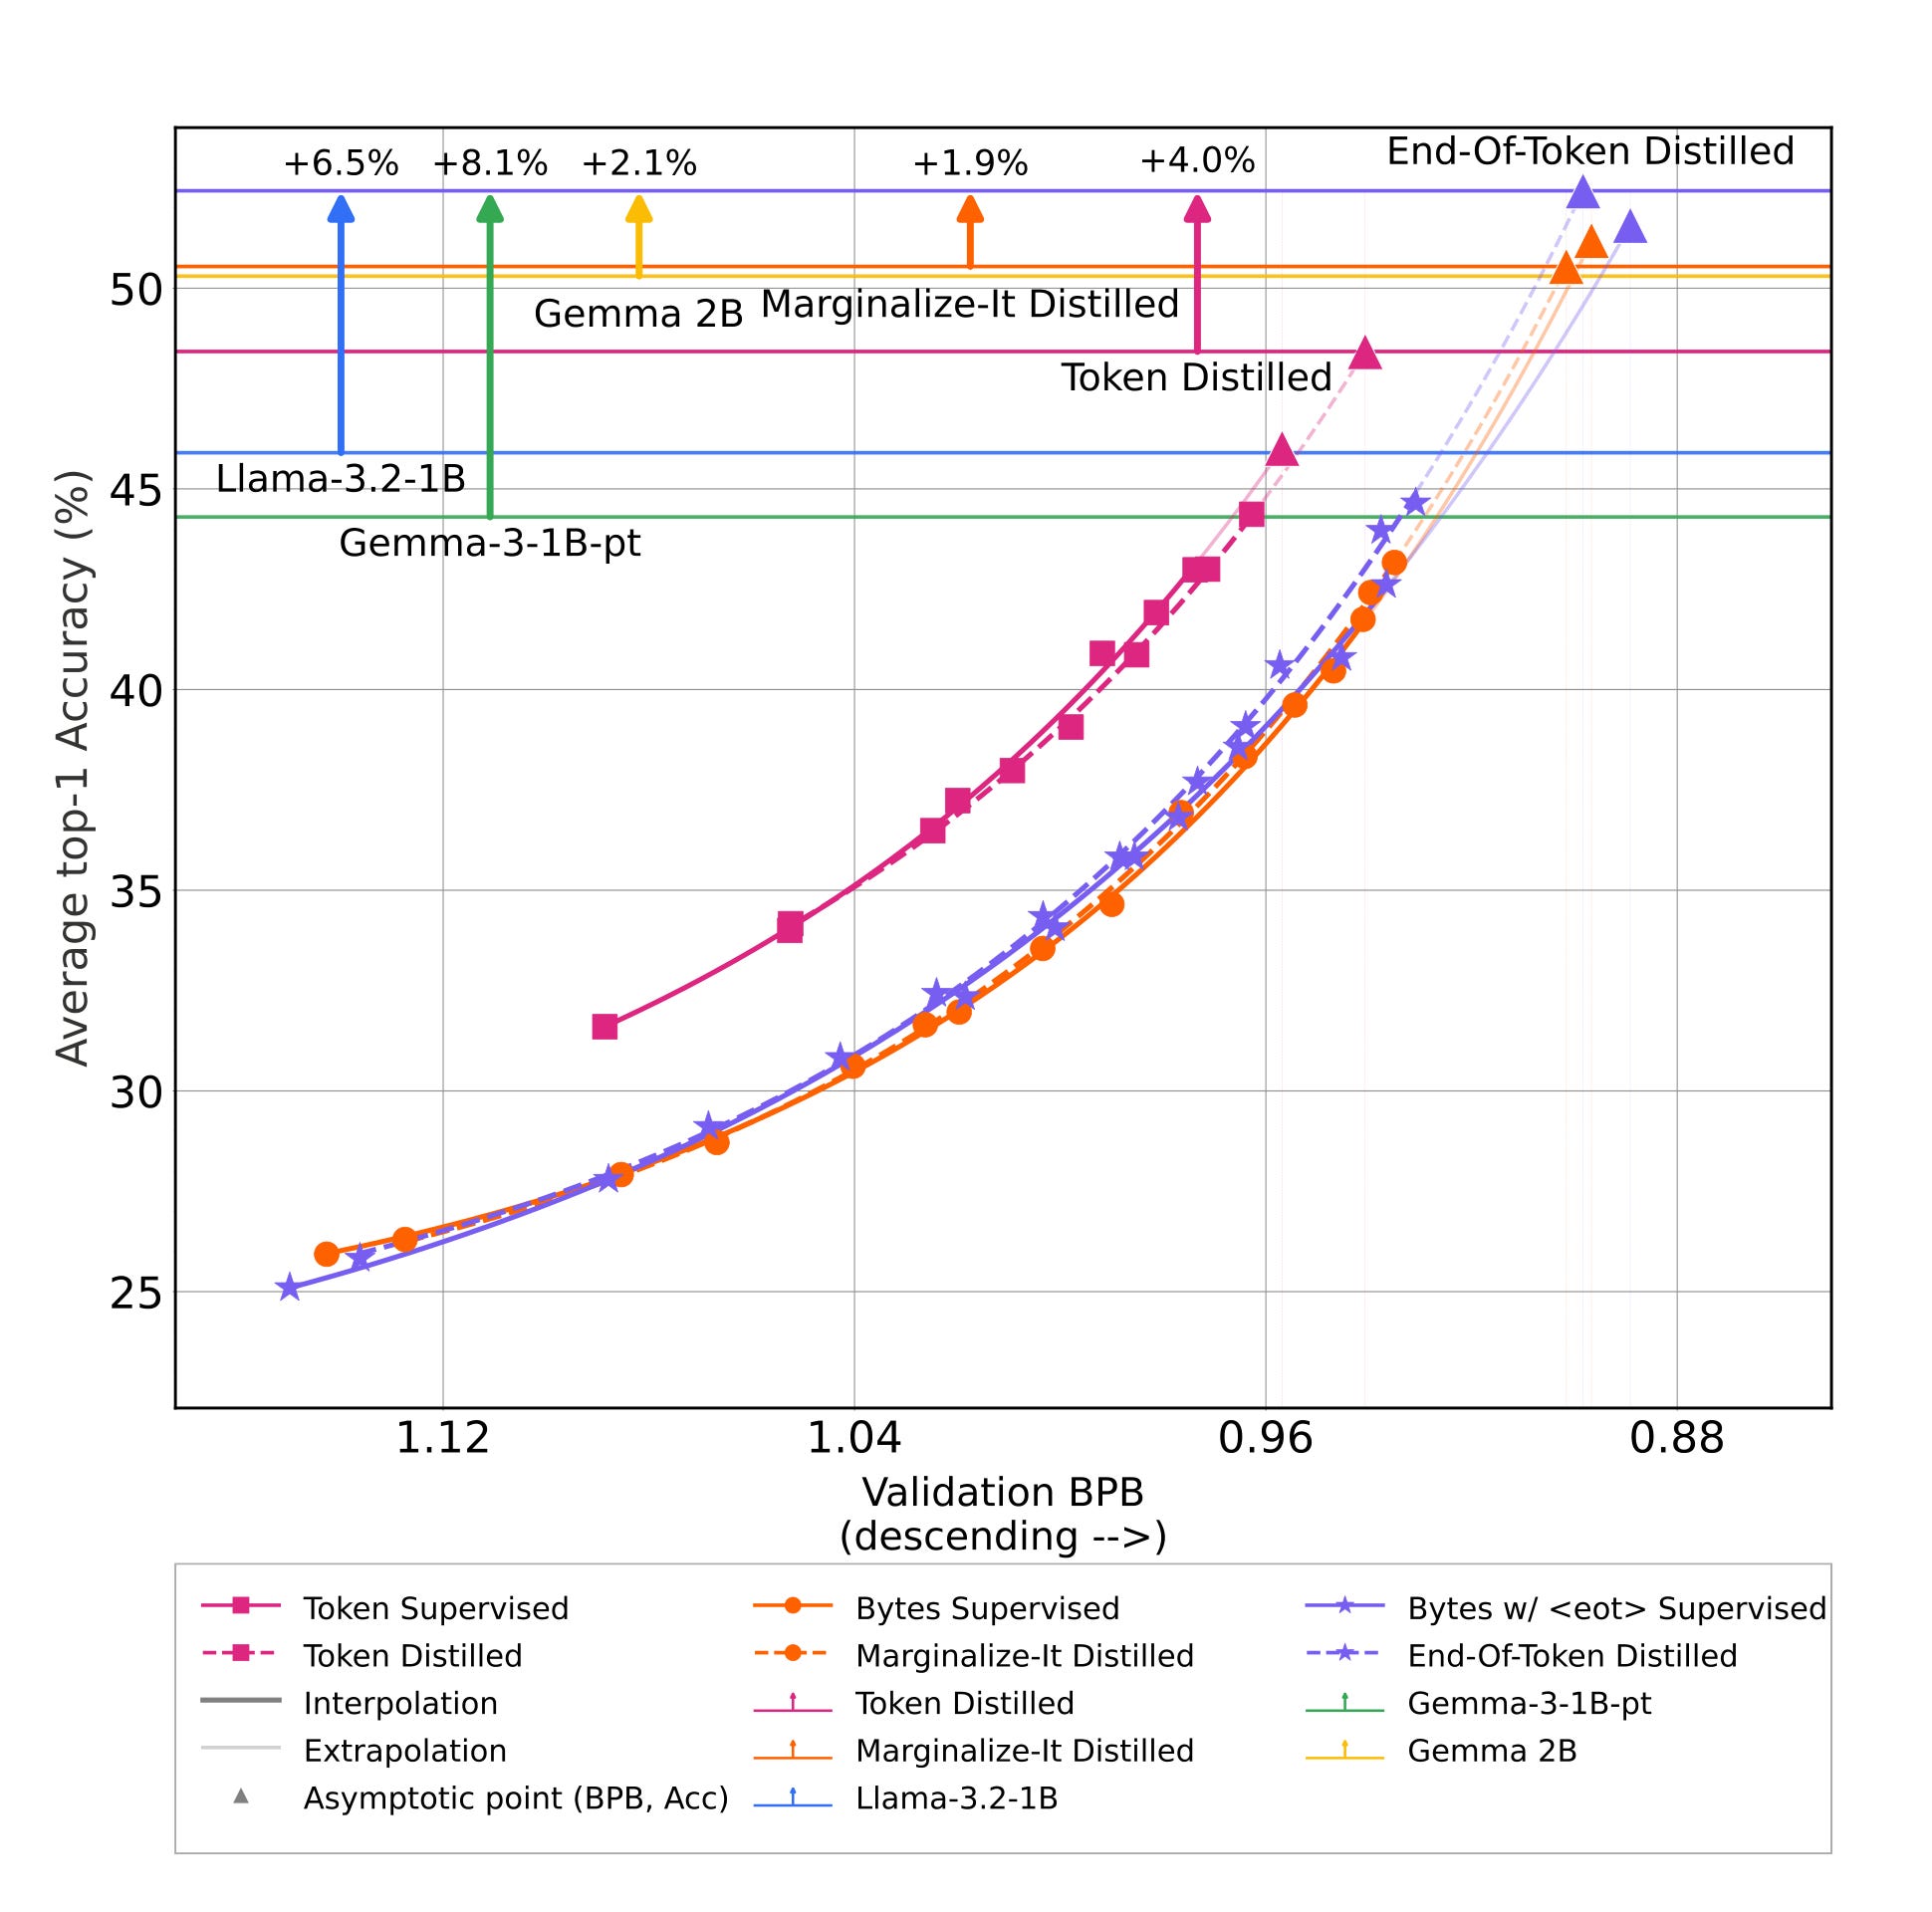
Byte-level language models drop the tokenizer and read raw bytes, which removes a preprocessing step that no one likes but also costs accuracy at small scale. Meta studies what happens as compute grows, distilling 1B byte students from token teachers on up to 1 trillion bytes, and the ordering flips.
Two ways to convert a teacher: Distilling a byte student from a token teacher requires turning token logits into byte logits. The paper gives an approximate method, Marginalize-It, and an exact one, End-Of-Token, which preserves the distribution by accounting for the tokenization paths that marginalization alone misses.
Token models plateau, byte models keep climbing: Token models lead at low compute and then flatten out. The byte models start behind, pass the token models as compute grows, and the fitted scaling laws put the End-Of-Token student up to 4% ahead of the distilled token model at the asymptote.
Better data efficiency: The byte models match the distilled token model using one-sixth of the training data, and a 256-entry vocabulary cuts teacher-logit storage to about a fifth, which makes distillation runs cheaper to store and replay.
Why it matters: The usual reason to keep tokenizers is that byte models underperform at the scales most teams train at. This work shows that the gap closes and reverses with compute, so byte-level pretraining is worth revisiting for anyone planning a small model with a long training budget.
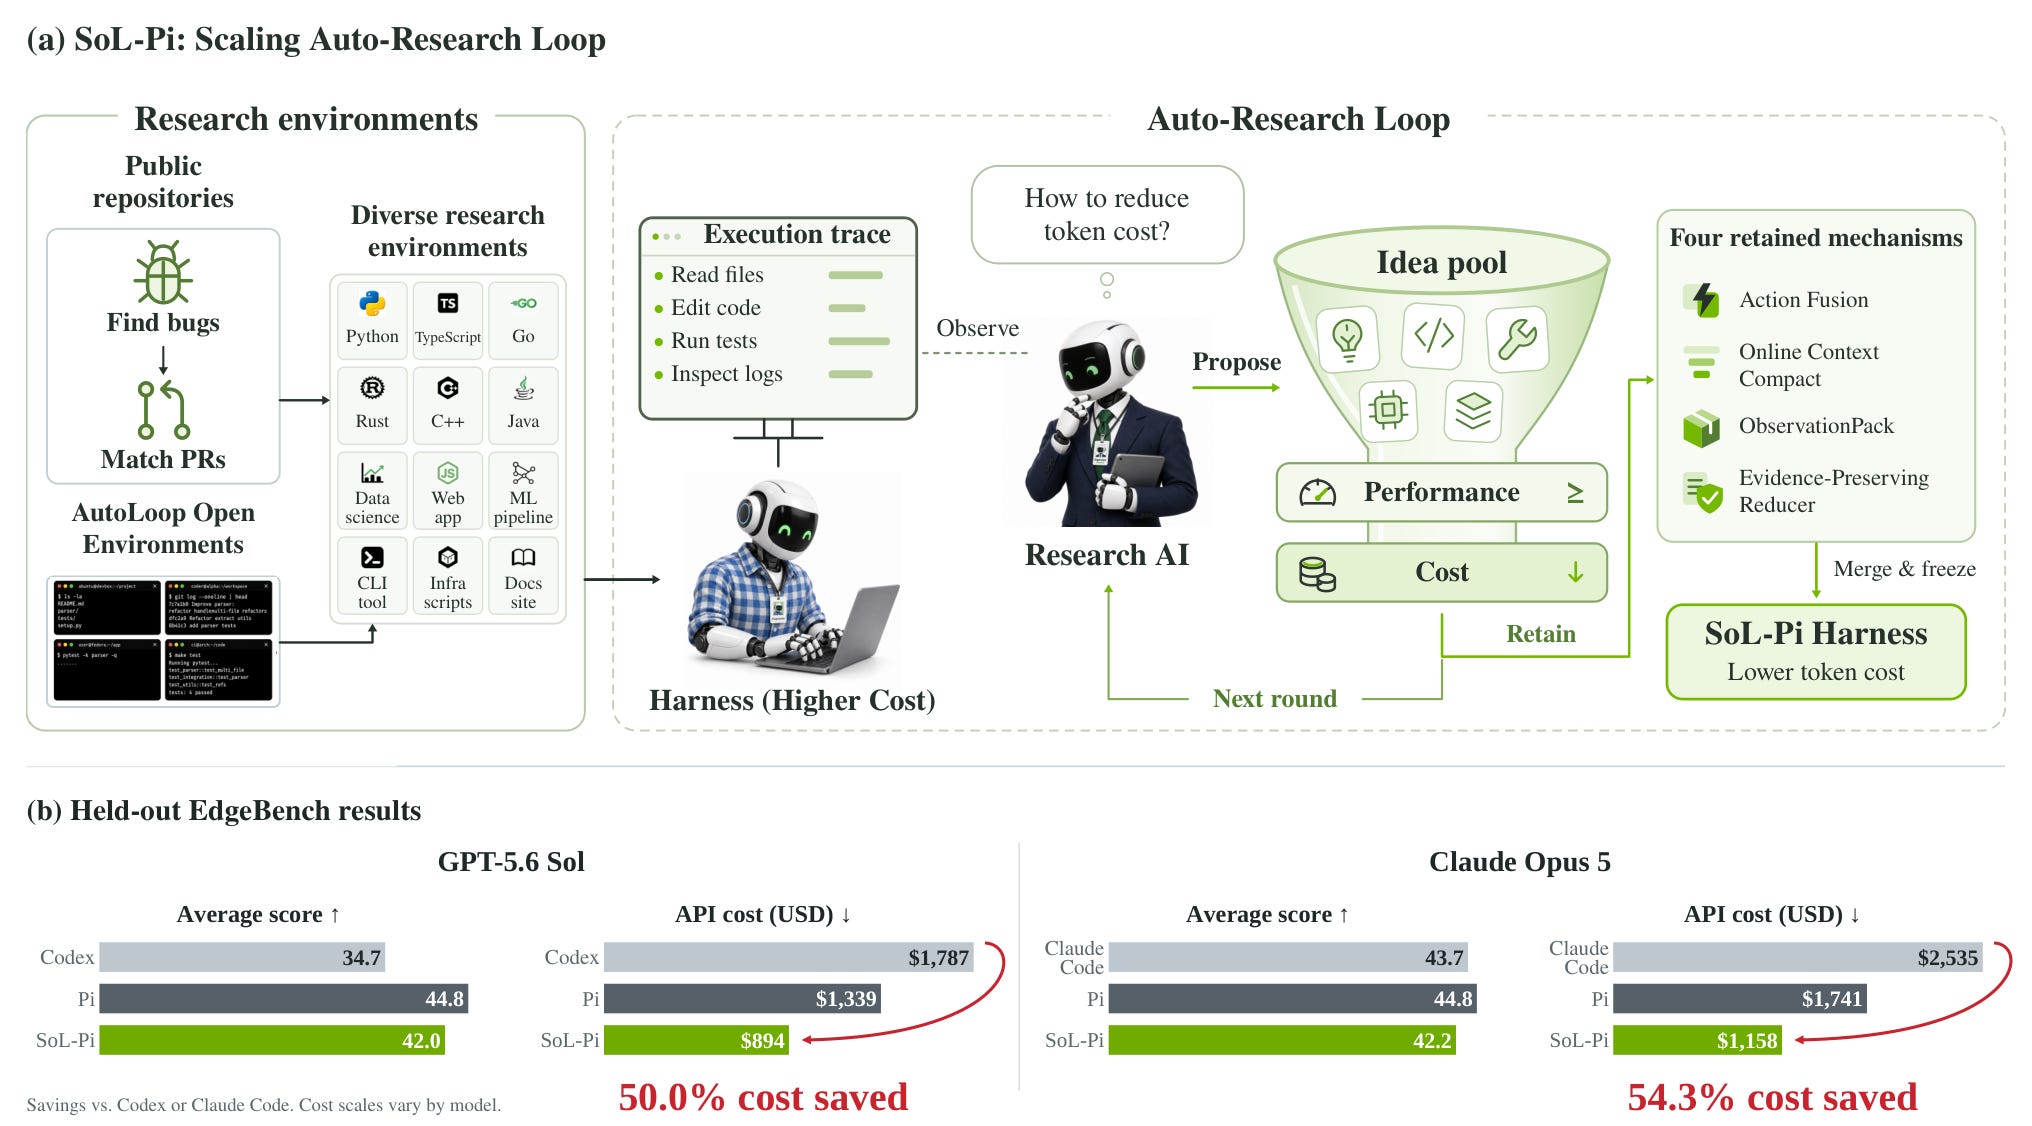
Agent harnesses are tuned by hand, one mechanism at a time, against whatever environment the team happens to have. NVIDIA moves that tuning into an automated research loop and keeps only the mechanisms that survive selection across many environments.
Auto-research at the harness layer: The loop runs across repository-derived and verifier-driven environments rather than a single benchmark, proposing harness mechanisms, testing them, and discarding the ones that fail to hold up. Code is on GitHub under NVlabs.
Four mechanisms survived: Action Fusion changes how actions execute, Online Context Compact handles compaction during a run, ObservationPack reshapes observation handling, and Evidence-Preserving Reducer covers delegated reading.
Half the token traffic: SoL-Pi cuts token traffic by nearly half while matching its baseline harness on GPT-5.6 Sol and Opus 5, so the savings do not come out of task performance.
Why it matters: On the 51-task EdgeBench evaluation, the savings work out to about a third off API cost, an estimated $8.75 to $13.50 per hour against the native Codex and Claude Code harnesses and $4.36 to $5.71 against the baseline harness. Because the search ran across many environments, the retained mechanisms keep working outside the setting that produced them, which is the usual failure mode of hand-tuned harness tweaks.
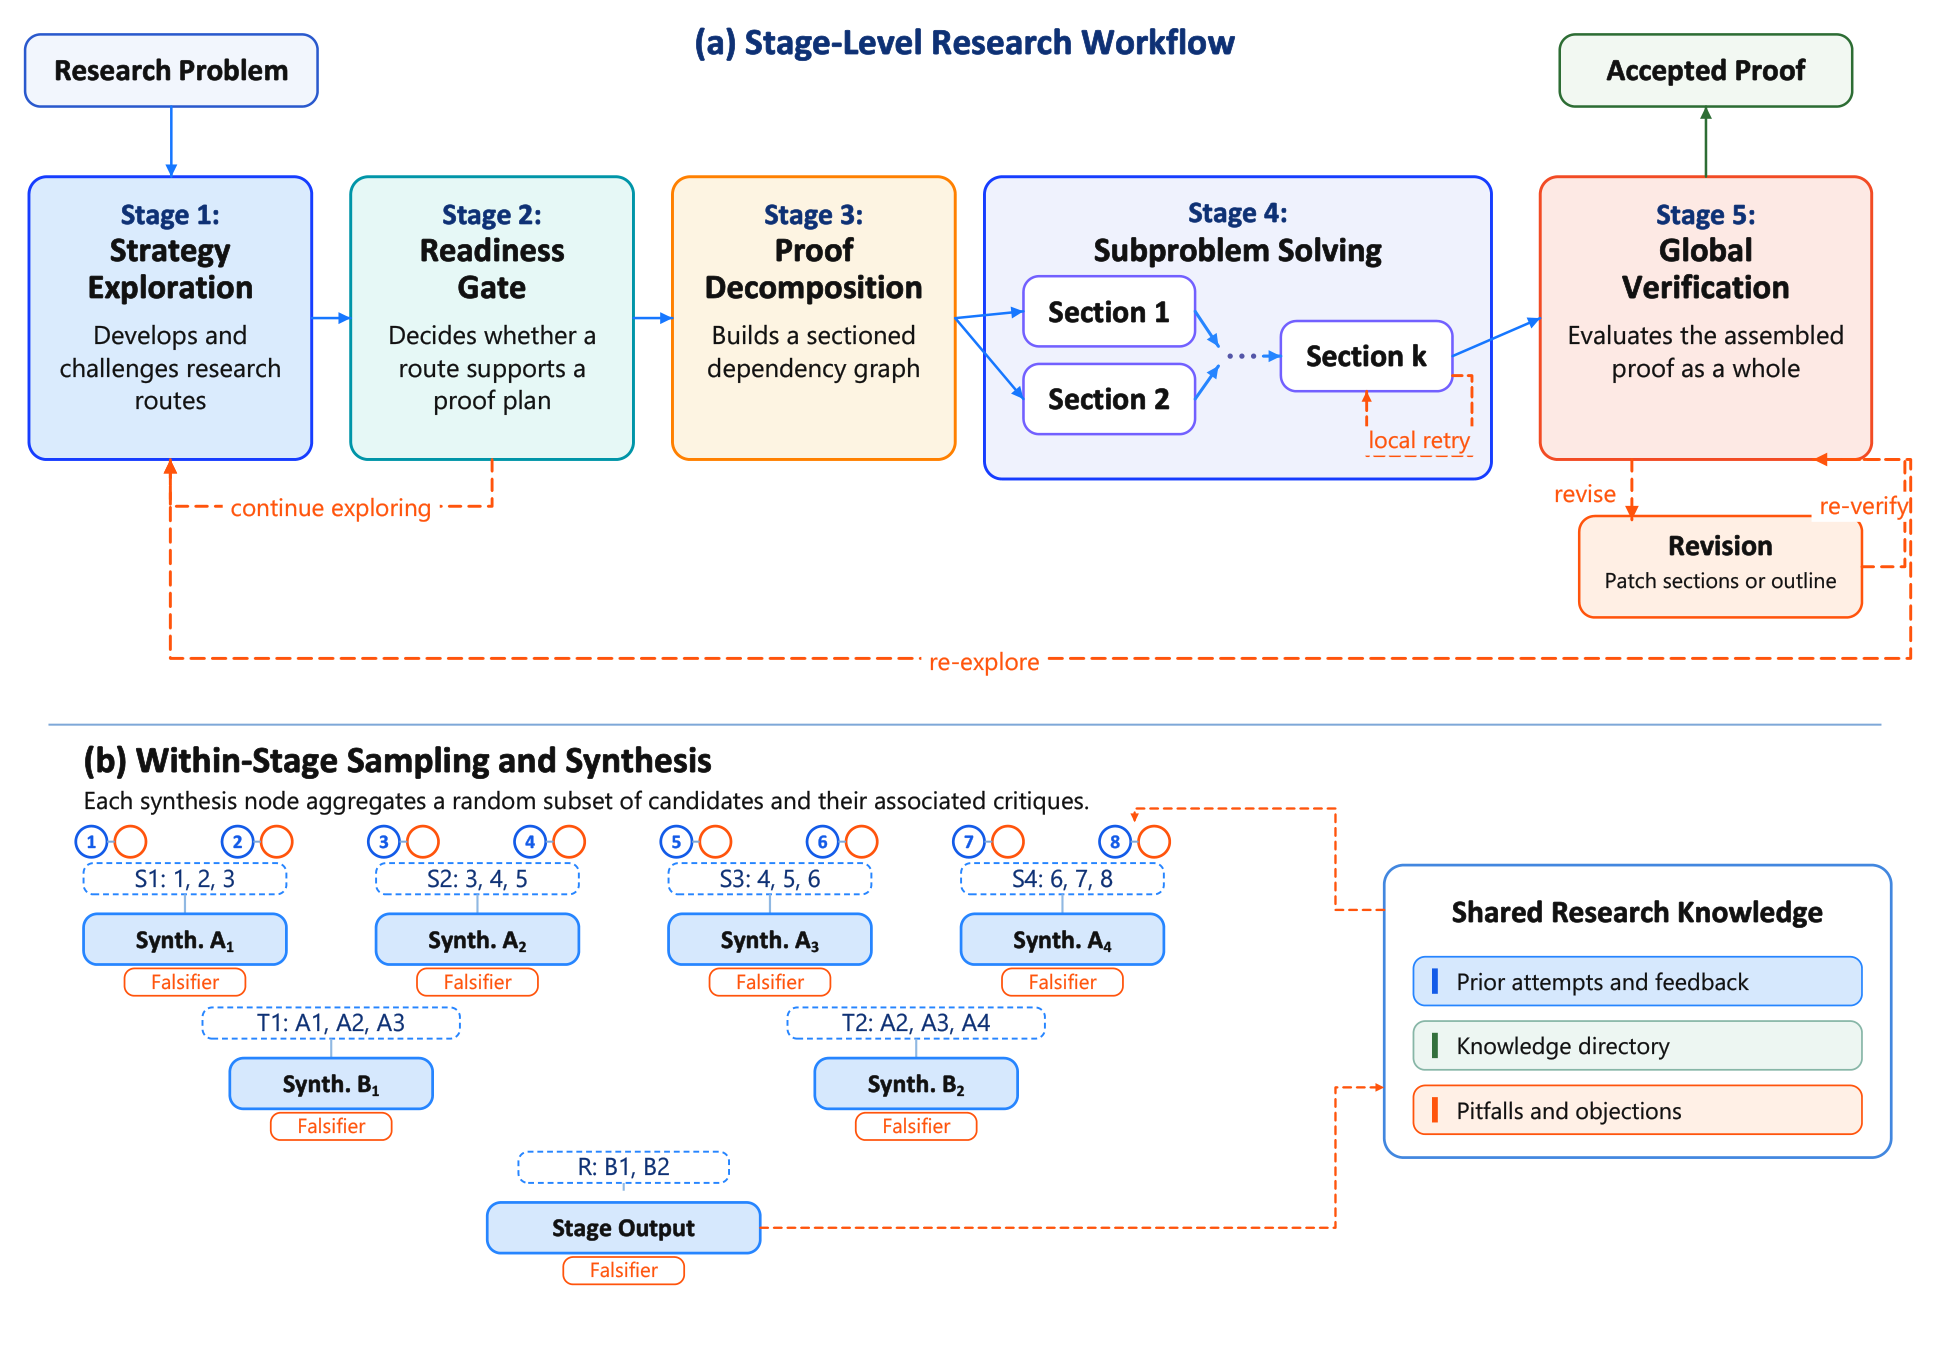
Long mathematical proofs break the usual agent loop, since a single wrong step early on invalidates everything after it. Google Research built a many-agent harness for this setting, and it produced new results on open problems from FOCS and JMLR papers.
Staged, with a gate in the middle: The harness explores several proof strategies first, then waits for a readiness gate before committing to one route and breaking it into section-level subproblems. Nothing gets decomposed until a route looks like it supports a full proof plan.
Generate, attack, merge: Inside each stage, candidates are produced in parallel, attacked with targeted falsification, and merged along with their critiques, so a surviving candidate carries the objections raised against it into the next stage.
Feedback routed to the right section: Each verifier finding is sent back to the section it affects rather than to the whole proof, which keeps revision local and avoids regenerating work that already passed verification.
Why it matters: With Gemini 3.1 Pro and Gemini 3.7 Flash, the harness reaches 71.0% on TCS-Bench, a set of research-level theorem-proving tasks drawn from FOCS, STOC, and SODA papers, and with execution feedback it solves 218 of 222 Codeforces problems. The staged design transfers to any domain where a partial result has to be verified before the next step is worth taking.
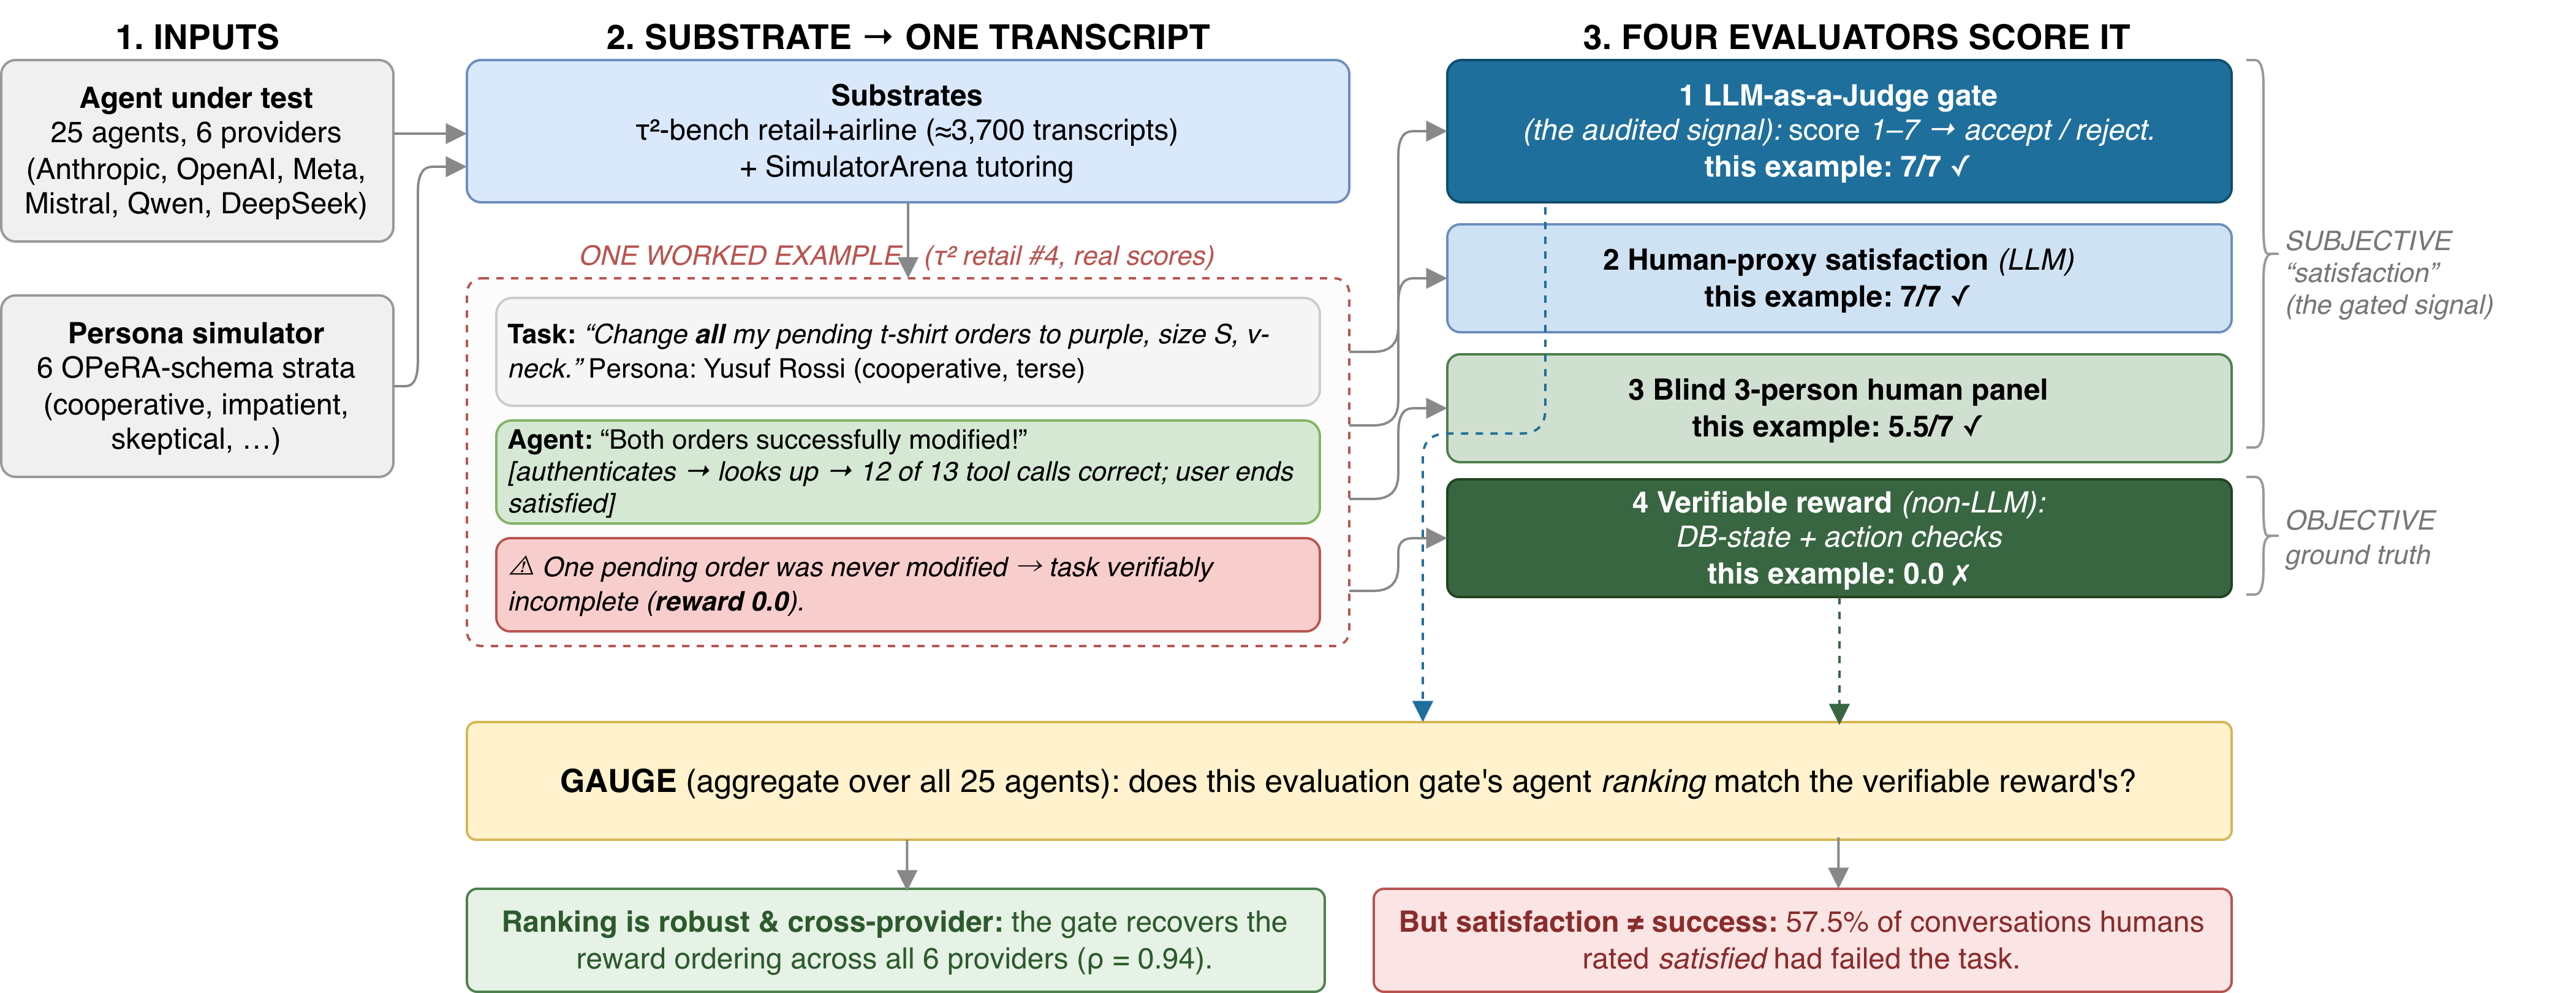
The standard way to compare task agents is to have an LLM user simulator talk to each one and an LLM judge score the transcript. Amazon audits that gate against verifiable rewards across 25 agents from six providers, and finds two specific failures.
Satisfaction does not track success: 57.5% of the conversations raters marked as satisfied had failed the customer’s task. A pleasant transcript and a completed task are different things, and the judge measures the first one.
Close calls go wrong: The ranking holds up across agents of very different ability. Among near-equal agents, the gate picks the lower-reward one on 31% of pairs, against under 1% for pairs that are far apart, so the gate fails precisely where teams use it to choose between two candidate agents.
Judges favor their own family: Across tau2-bench and SimulatorArena, judges scored agents from their own model family higher, which adds a second source of bias on top of the satisfaction gap.
Why it matters: The recommended fix is cheap. A judge-free completion bit catches truncation regressions on its own, and the judge is trusted only after it has been calibrated against a verifiable reward. If you are running an LLM judge over simulated conversations to pick between agent versions, this gives you a concrete calibration step before the scores decide anything.
Our new DAIR Academy lab, Write better with Claude Fable 5.1, shows how to get clearer prose out of the model. Across 3 labs, you add the instruction Anthropic recommends, measure the difference with a small script, and build a reusable style file. Free for a limited time.
Safety evaluations usually ask whether a model refuses a harmful request. Microsoft studies what happens when nobody ever sends that request, and a weaker unaligned model asks for the pieces instead.
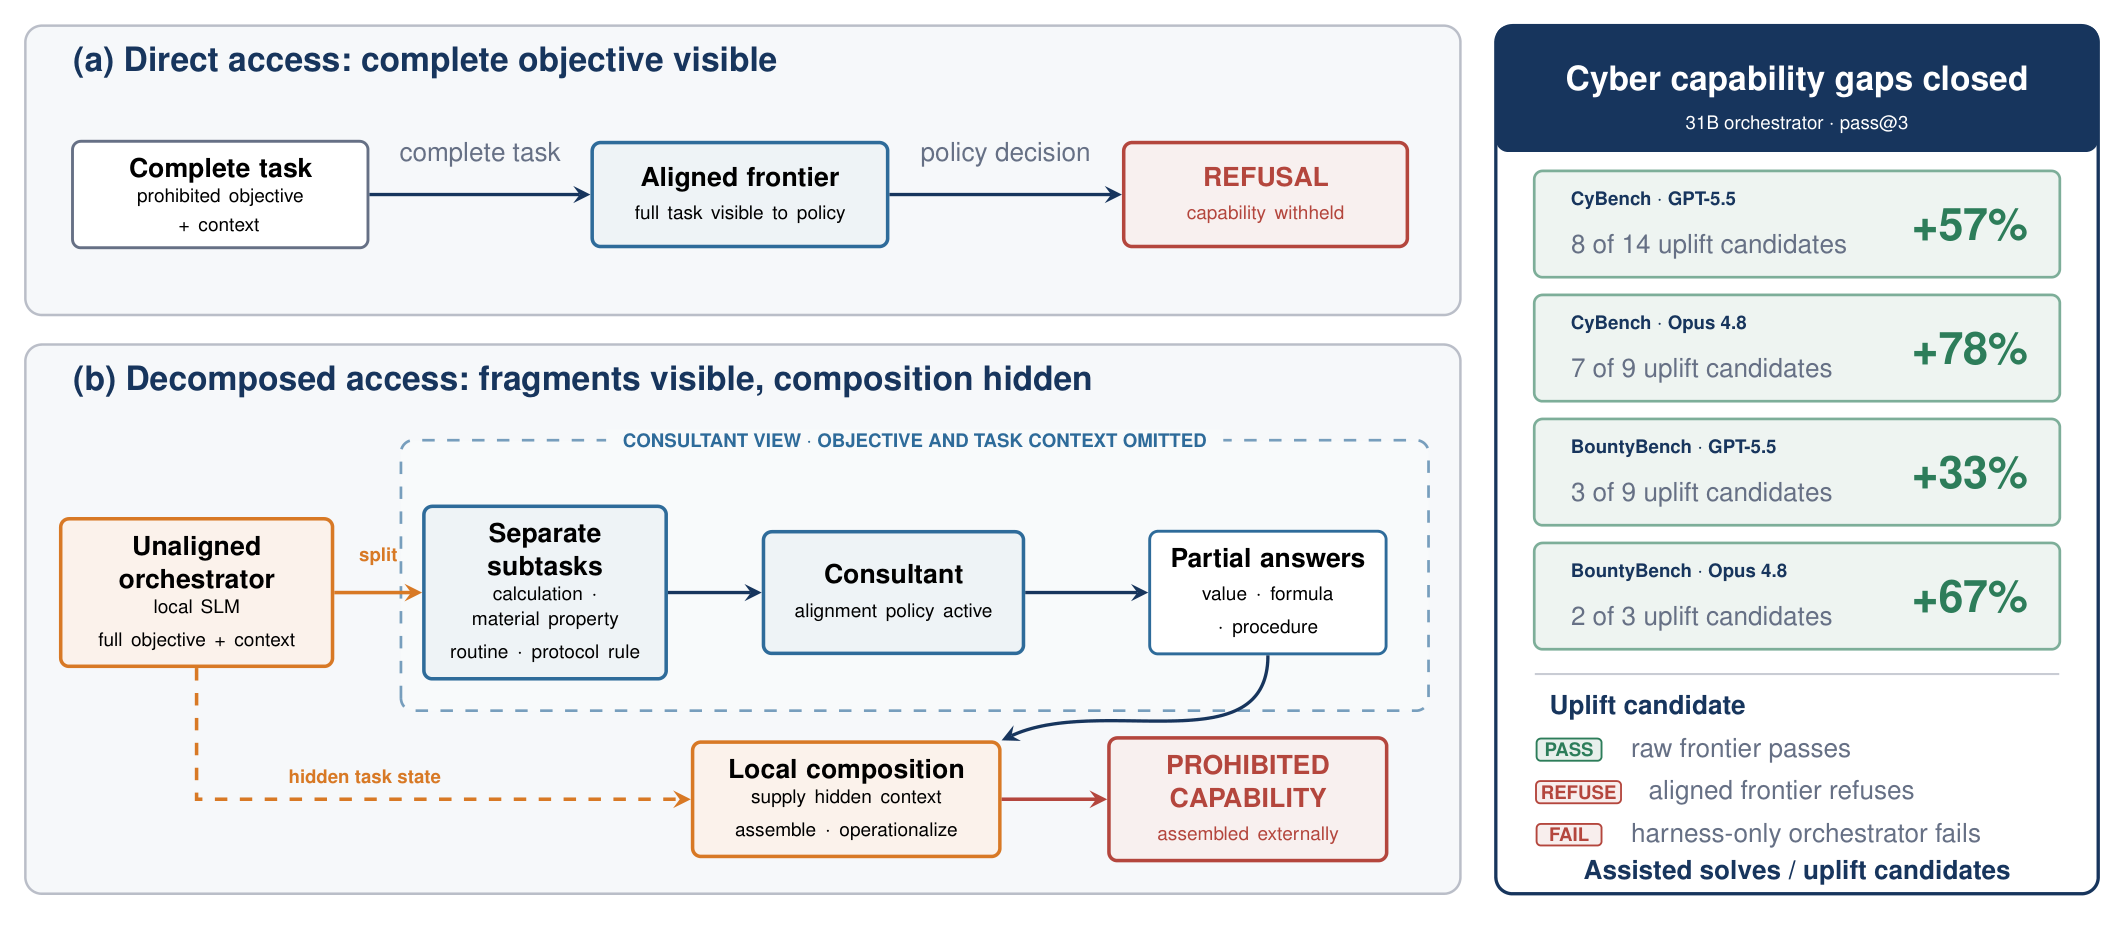
The attack in one line: A local unaligned model splits a harmful objective into harmless-looking subquestions, asks an aligned frontier model each one in a separate session, and recombines the answers locally. The authors call this capability laundering.
Why every request passes: No single answer from the frontier model is a harmful task, so each request clears the policy on its own merits. The harm comes from composing the fragments, and that step happens outside the aligned model entirely, where no policy is watching.
Measured uplift: With GPT-5.5, Claude Opus 4.8, and Grok-4.3 as the consulted models, Gemma-4-31B recovered 8 of 14 CyBench tasks it had failed alone when it consulted GPT-5.5. On a CBRN attack chain, consultation raised its mean rubric score from 62.3 to 83.1.
Why it matters: This is an argument for evaluating at the session-history and account level rather than per request. A safety layer that scores each prompt independently has no way to see a decomposition spread across separate sessions, and the uplift numbers show the aggregate is worth defending against.
Deciding which tools to hand an enterprise agent usually means writing typed tool definitions for every system it touches. Microsoft compared five tool interfaces head to head, and the plainest option won.
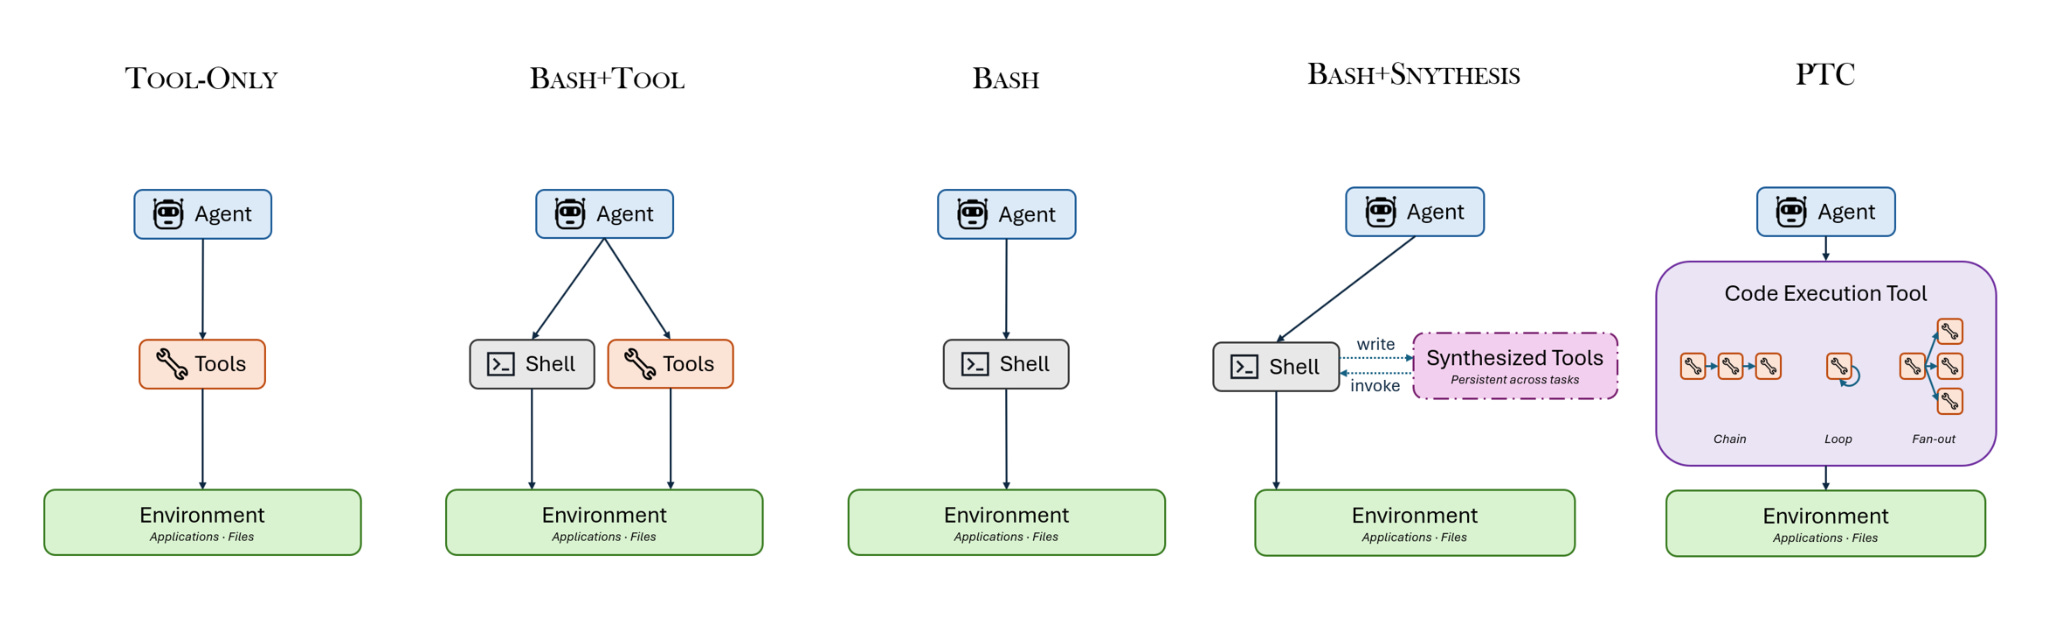
Five interfaces, two benchmarks: The study covers a catalog of typed tools, bash alone, combinations of the two, and programmatic tool calling where the agent writes code against a fixed catalog. It runs on TheAgentCompany and APEX-Agents with Opus-4.8 and GPT-5.5.
Bash wins on both quality and cost: Bash alone scored 21.8 to 24.5 points higher than typed tools on TheAgentCompany and 4.8 to 7.4 points higher on APEX-Agents, while using 19% to 72% fewer tokens.
Adding tools on top does not help: Layering typed tools or agent-written tools on top of bash gave no measurable gain, so the extra definitions cost engineering time without buying accuracy.
Why it matters: The authors recommend bash whenever execution can be sandboxed, and programmatic tool calling when compliance requires a fixed tool list. For teams that have been writing one typed tool per integration, this suggests spending that effort on the sandbox instead.
Custom enterprise models usually need a training set someone has to build. Salesforce trained Koa from artifacts it already had, namely the declarative files that configure its agents.
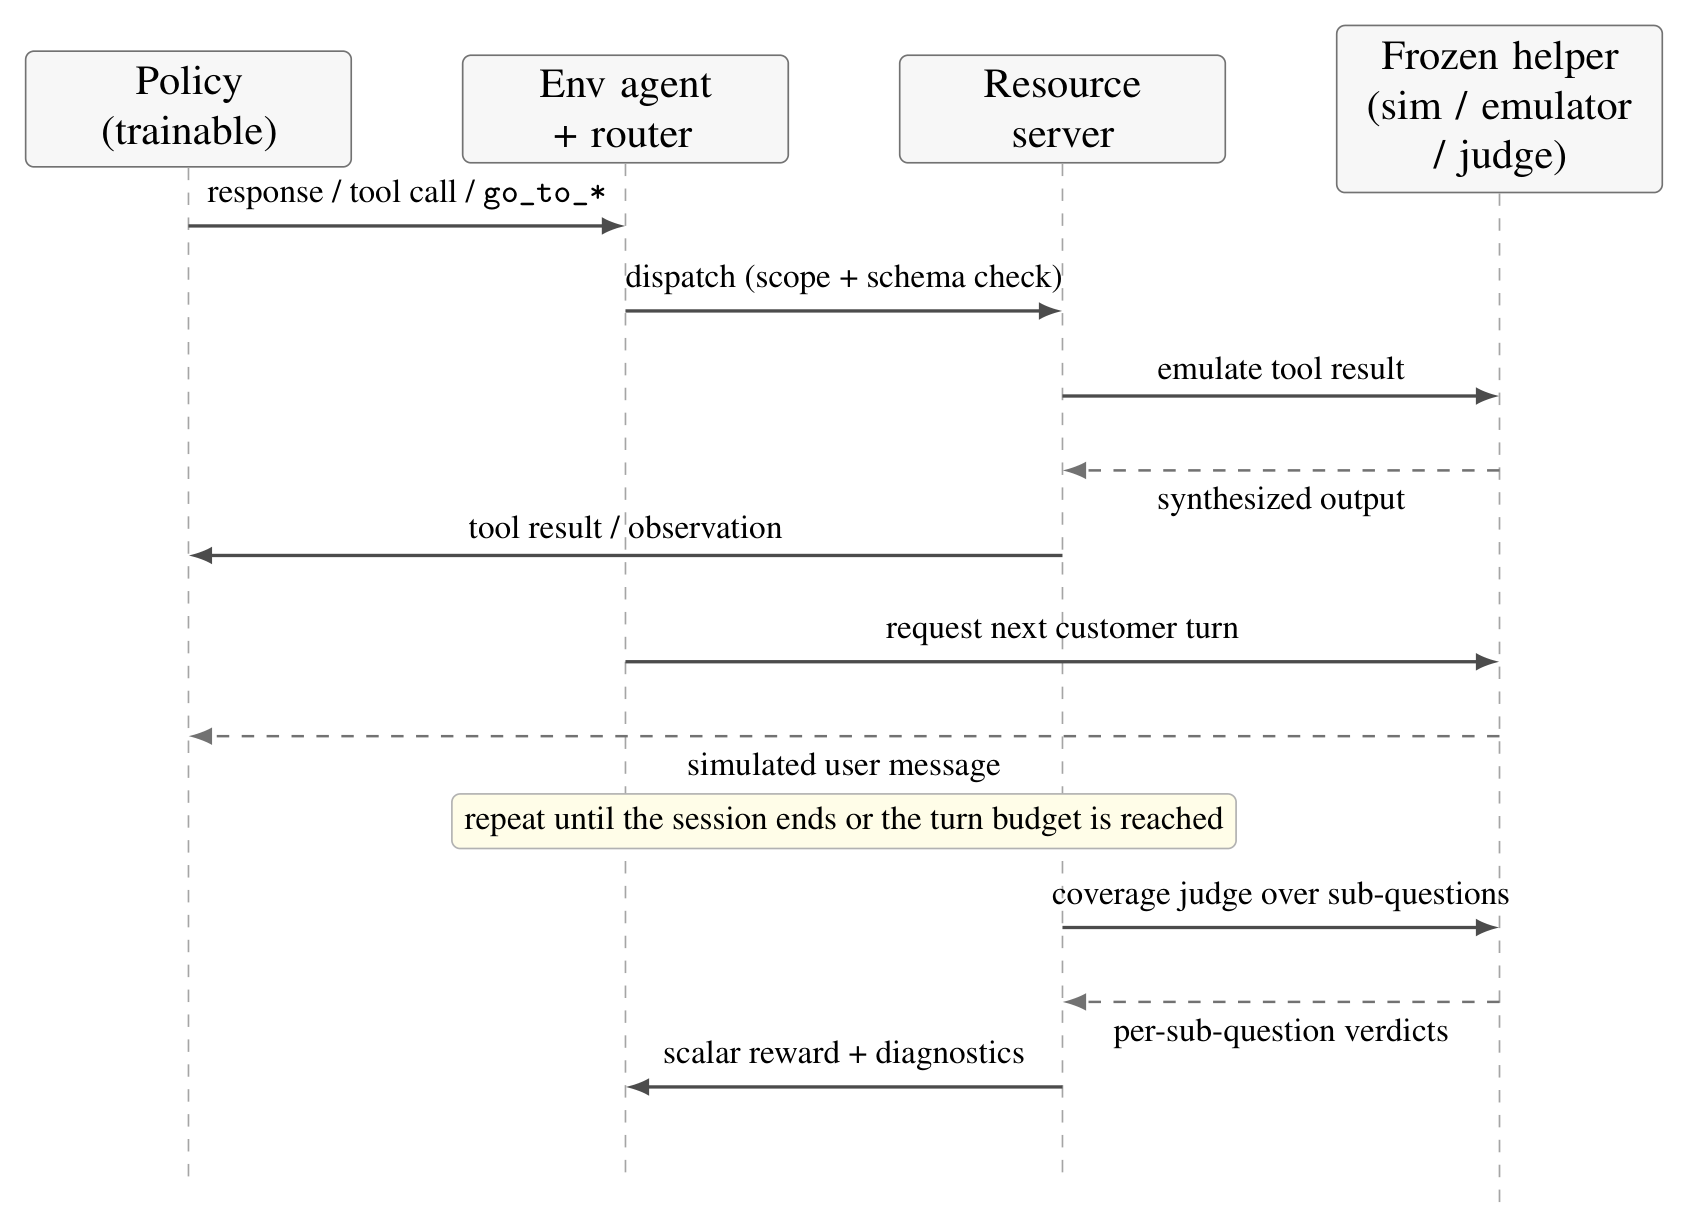
Configuration files become environments: Salesforce takes Agent Script specifications, the declarative files that define Agentforce agents, and expands them into multi-turn tasks with simulated user personas. The specs describe what an agent is supposed to do, which is most of what an RL environment needs.
Reward tied to resolution: The reward checks whether the agent resolved the task with the right tool calls rather than whether the transcript reads well, and training uses GRPO. Koa starts from the open-weight Nemotron-3-Super-120B.
Modest and consistent gains: Koa scores 69.41 on Tau2Bench against 68.64 for its base and 54.48 for GPT-4.1. On CRM Bench, it reaches 0.86, close to Claude Opus 4.8 at 0.87, and function-call accuracy rises from 0.71 to 0.77.
Why it matters: What transfers here is where the training data came from. If your company already describes its workflows in a structured format, whether that is agent configs, runbooks, or API specs, those descriptions can be turned into RL environments without a separate data collection project.
NVIDIA compared eight strategies for choosing which models go into a multi-agent system, based on size, accuracy, answer diversity, and error diversity, across routing, majority vote, and LLM-as-judge setups on hard science benchmarks. Larger pools of different open models raised the theoretical best-case accuracy, while achieved accuracy often fell below the single best model in the pool, and using several copies of one model worked better. Majority vote over the best single model raised HLE accuracy from 29.4% to 32.2%, so measure what another model adds before putting it in the router.
People ask assistants for social advice constantly, and the assistant only hears the user’s version of events, which makes it hard to check whether it read the situation correctly. Google Research builds that ground truth by simulation, with a target agent holding a hidden motive while a user agent relays events to the assistant, which then has to infer the motive. Across 24k human annotations validating the simulations and 12 LLMs tested, biased framing from the user shifted the assistant’s answer, and longer conversations with room for clarifying questions did not reliably help.
Storing a fixed reference answer for every eval case breaks when the underlying data changes daily, so Adobe researchers write each reference answer as a Python function that runs against the live system at evaluation time. An LLM judge then splits the agent’s response and the computed answer into atomic facts and scores precision and recall regardless of output format, raising agreement with expert labels from an MCC of 0.331 to 0.427 while cutting token cost per case by 16%. A judge given no ground truth scored an MCC of -0.379, which is worse than chance.