[Updated on 2018-12-20: Remove YOLO here. Part 4 will cover multiple fast object detection algorithms, including YOLO.]
[Updated on 2018-12-27: Add bbox regression and tricks sections for R-CNN.]
In the series of “Object Detection for Dummies”, we started with basic concepts in image processing, such as gradient vectors and HOG, in Part 1. Then we introduced classic convolutional neural network architecture designs for classification and pioneer models for object recognition, Overfeat and DPM, in Part 2. In the third post of this series, we are about to review a set of models in the R-CNN (“Region-based CNN”) family.
Links to all the posts in the series: [Part 1] [Part 2] [Part 3] [Part 4].
Here is a list of papers covered in this post ;)
| Model | Goal | Resources |
|---|---|---|
| R-CNN | Object recognition | [paper][code] |
| Fast R-CNN | Object recognition | [paper][code] |
| Faster R-CNN | Object recognition | [paper][code] |
| Mask R-CNN | Image segmentation | [paper][code] |
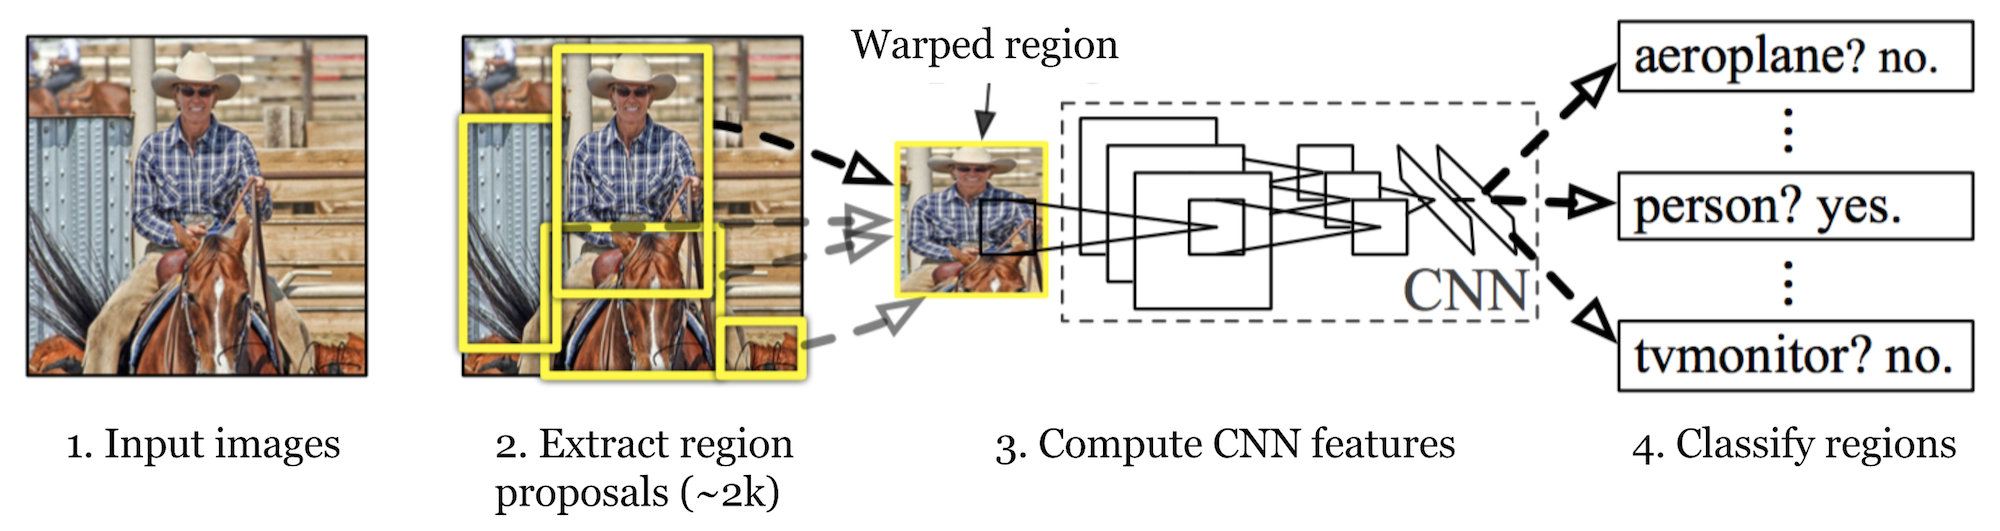
R-CNN (Girshick et al., 2014) is short for “Region-based Convolutional Neural Networks”. The main idea is composed of two steps. First, using selective search, it identifies a manageable number of bounding-box object region candidates (“region of interest” or “RoI”). And then it extracts CNN features from each region independently for classification.
How R-CNN works can be summarized as follows:
NOTE: You can find a pre-trained AlexNet in Caffe Model Zoo. I don’t think you can find it in Tensorflow, but Tensorflow-slim model library provides pre-trained ResNet, VGG, and others.
Given a predicted bounding box coordinate $\mathbf{p} = (p_x, p_y, p_w, p_h)$ (center coordinate, width, height) and its corresponding ground truth box coordinates $\mathbf{g} = (g_x, g_y, g_w, g_h)$ , the regressor is configured to learn scale-invariant transformation between two centers and log-scale transformation between widths and heights. All the transformation functions take $\mathbf{p}$ as input.
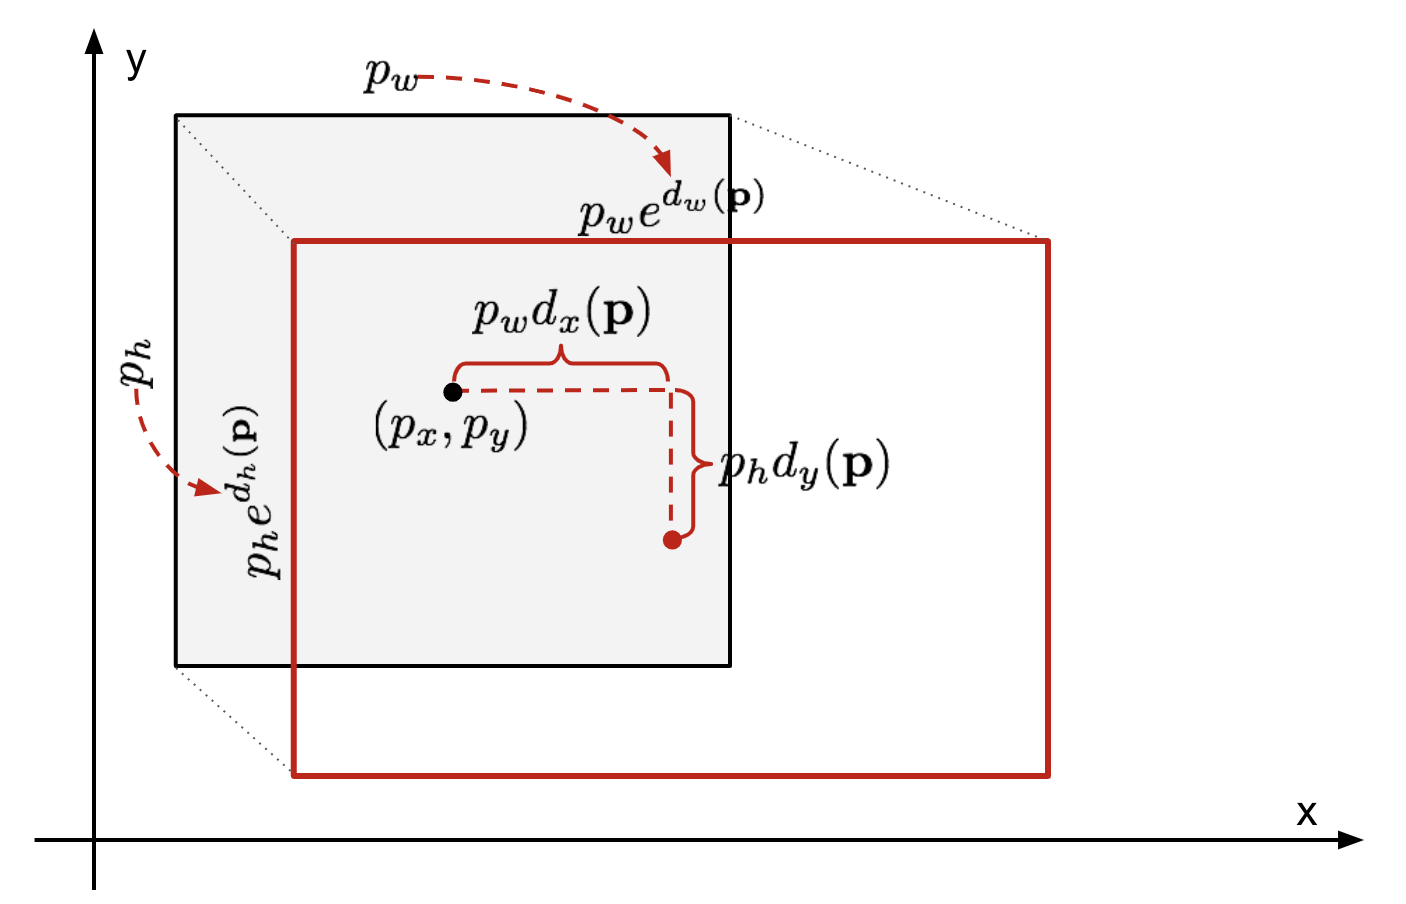
An obvious benefit of applying such transformation is that all the bounding box correction functions, $d_i(\mathbf{p})$ where $i \in \{ x, y, w, h \}$, can take any value between [-∞, +∞]. The targets for them to learn are:
A standard regression model can solve the problem by minimizing the SSE loss with regularization:
The regularization term is critical here and RCNN paper picked the best λ by cross validation. It is also noteworthy that not all the predicted bounding boxes have corresponding ground truth boxes. For example, if there is no overlap, it does not make sense to run bbox regression. Here, only a predicted box with a nearby ground truth box with at least 0.6 IoU is kept for training the bbox regression model.
Several tricks are commonly used in RCNN and other detection models.
Non-Maximum Suppression
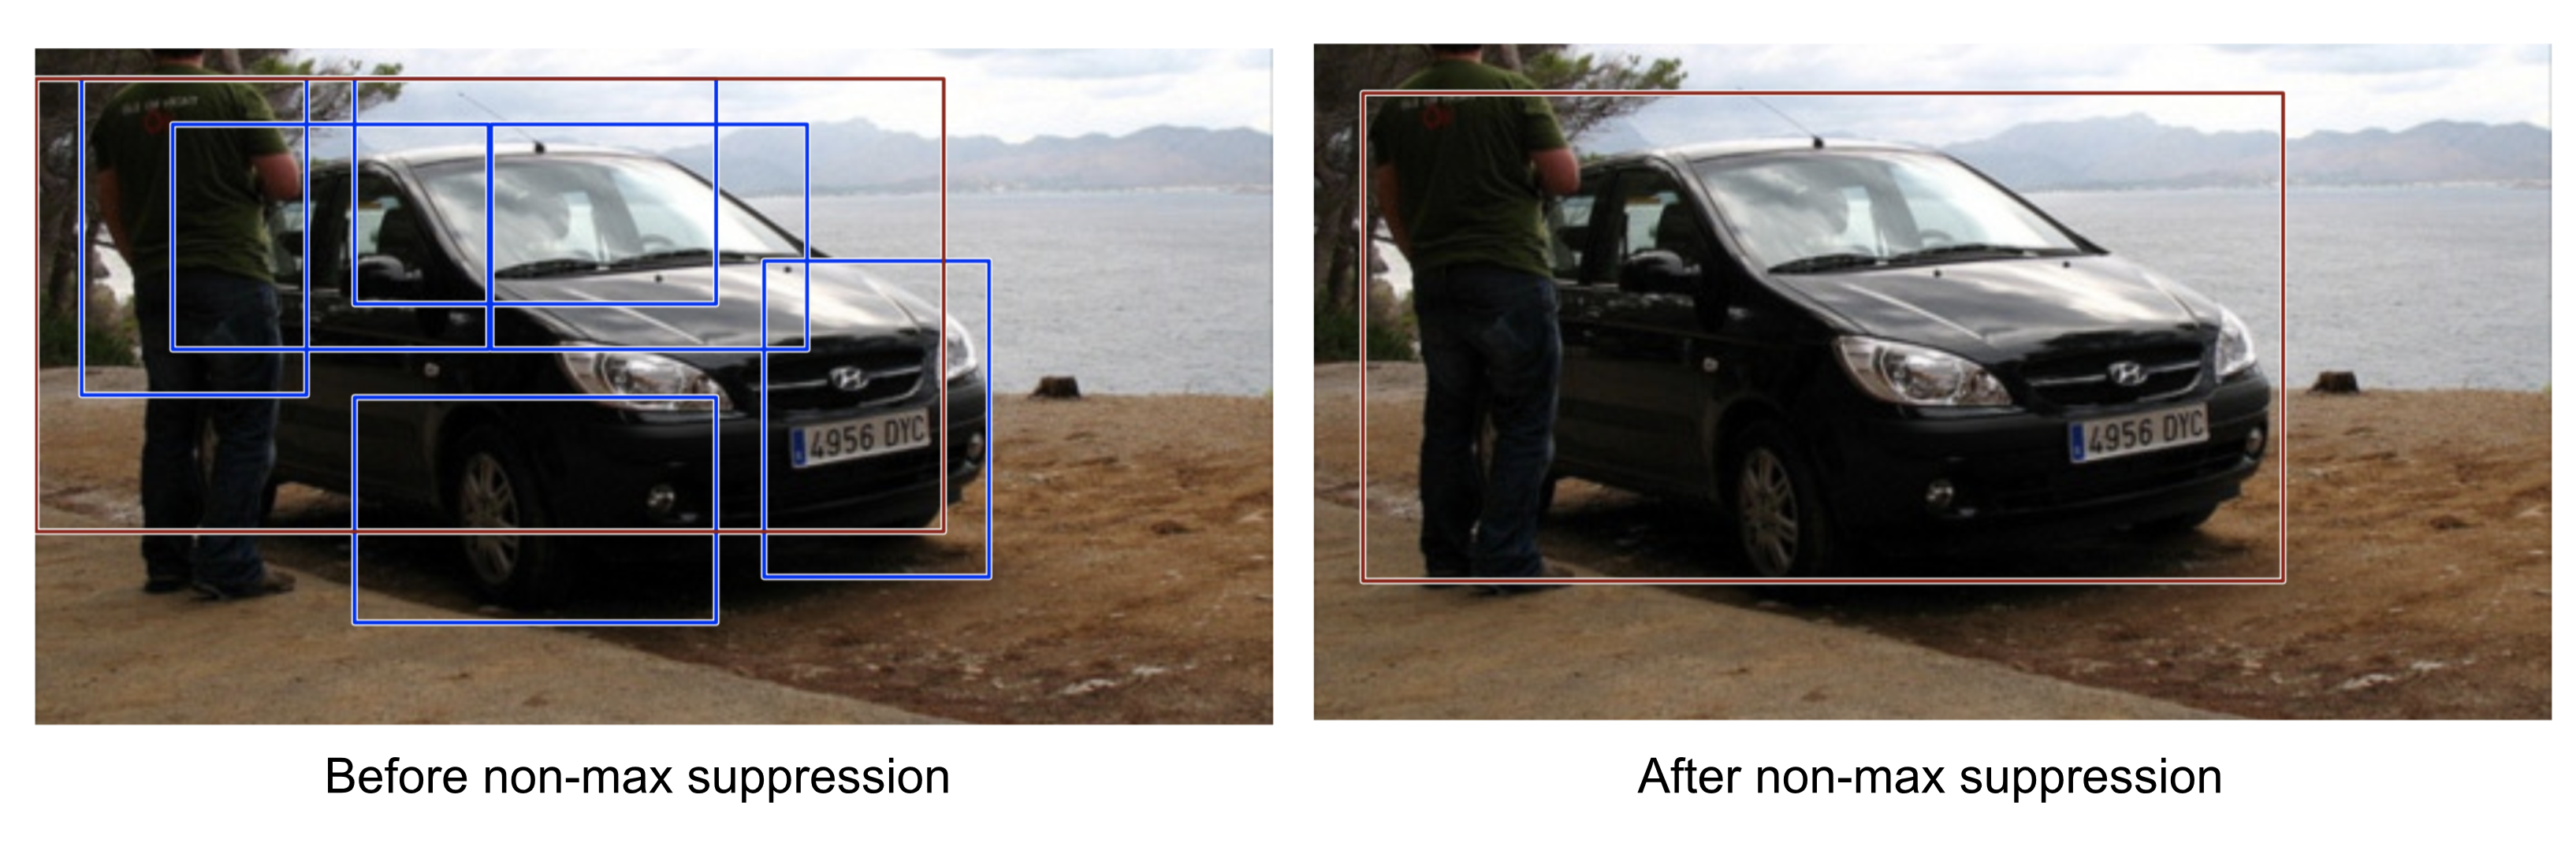
Likely the model is able to find multiple bounding boxes for the same object. Non-max suppression helps avoid repeated detection of the same instance. After we get a set of matched bounding boxes for the same object category: Sort all the bounding boxes by confidence score. Discard boxes with low confidence scores. While there is any remaining bounding box, repeat the following: Greedily select the one with the highest score. Skip the remaining boxes with high IoU (i.e. > 0.5) with previously selected one.
Hard Negative Mining
We consider bounding boxes without objects as negative examples. Not all the negative examples are equally hard to be identified. For example, if it holds pure empty background, it is likely an “easy negative”; but if the box contains weird noisy texture or partial object, it could be hard to be recognized and these are “hard negative”.
The hard negative examples are easily misclassified. We can explicitly find those false positive samples during the training loops and include them in the training data so as to improve the classifier.
Looking through the R-CNN learning steps, you could easily find out that training an R-CNN model is expensive and slow, as the following steps involve a lot of work:
To make R-CNN faster, Girshick (2015) improved the training procedure by unifying three independent models into one jointly trained framework and increasing shared computation results, named Fast R-CNN. Instead of extracting CNN feature vectors independently for each region proposal, this model aggregates them into one CNN forward pass over the entire image and the region proposals share this feature matrix. Then the same feature matrix is branched out to be used for learning the object classifier and the bounding-box regressor. In conclusion, computation sharing speeds up R-CNN.
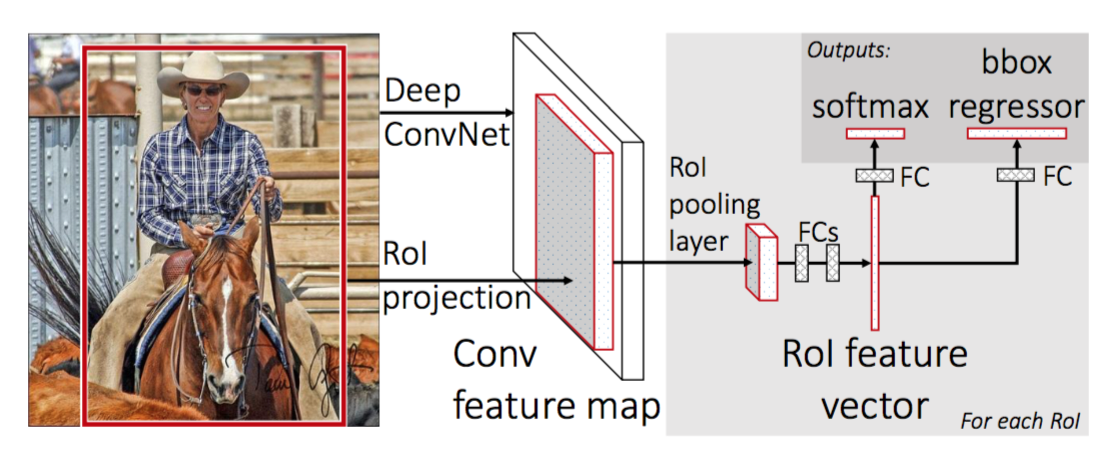
It is a type of max pooling to convert features in the projected region of the image of any size, h x w, into a small fixed window, H x W. The input region is divided into H x W grids, approximately every subwindow of size h/H x w/W. Then apply max-pooling in each grid.
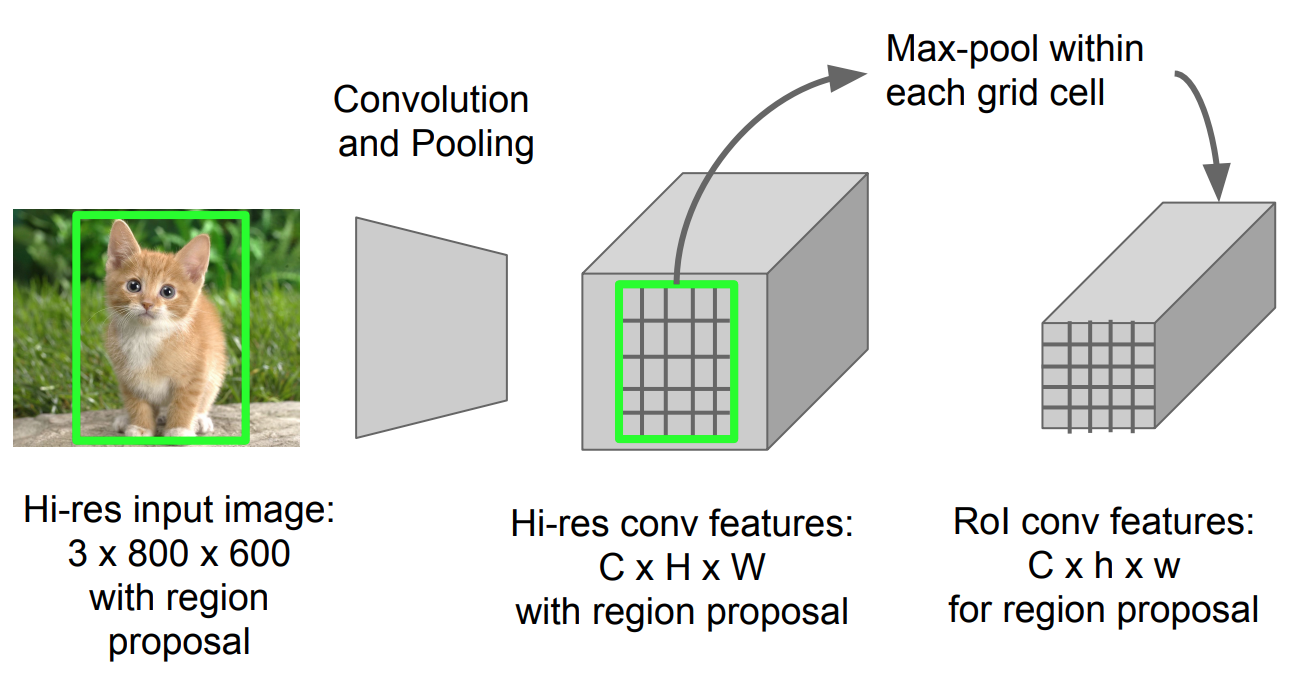
How Fast R-CNN works is summarized as follows; many steps are same as in R-CNN:
The model is optimized for a loss combining two tasks (classification + localization):
| Symbol | Explanation | | $u$ | True class label, $ u \in 0, 1, \dots, K$; by convention, the catch-all background class has $u = 0$. | | $p$ | Discrete probability distribution (per RoI) over K + 1 classes: $p = (p_0, \dots, p_K)$, computed by a softmax over the K + 1 outputs of a fully connected layer. | | $v$ | True bounding box $ v = (v_x, v_y, v_w, v_h) $. | | $t^u$ | Predicted bounding box correction, $t^u = (t^u_x, t^u_y, t^u_w, t^u_h)$. See above. | {:.info}
The loss function sums up the cost of classification and bounding box prediction: $\mathcal{L} = \mathcal{L}_\text{cls} + \mathcal{L}_\text{box}$. For “background” RoI, $\mathcal{L}_\text{box}$ is ignored by the indicator function $\mathbb{1} [u \geq 1]$, defined as:
The overall loss function is:
The bounding box loss $\mathcal{L}_{box}$ should measure the difference between $t^u_i$ and $v_i$ using a robust loss function. The smooth L1 loss is adopted here and it is claimed to be less sensitive to outliers.
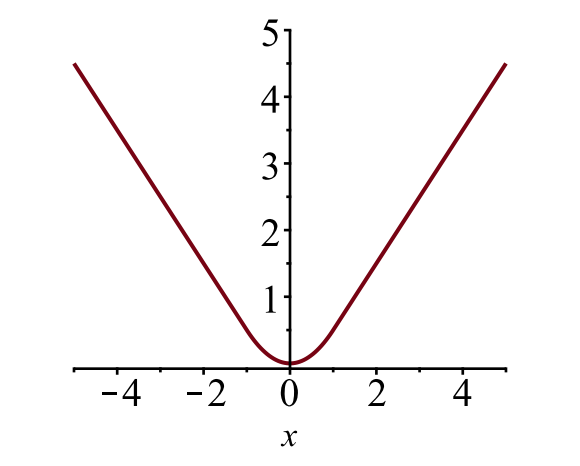
Fast R-CNN is much faster in both training and testing time. However, the improvement is not dramatic because the region proposals are generated separately by another model and that is very expensive.
An intuitive speedup solution is to integrate the region proposal algorithm into the CNN model. Faster R-CNN (Ren et al., 2016) is doing exactly this: construct a single, unified model composed of RPN (region proposal network) and fast R-CNN with shared convolutional feature layers.
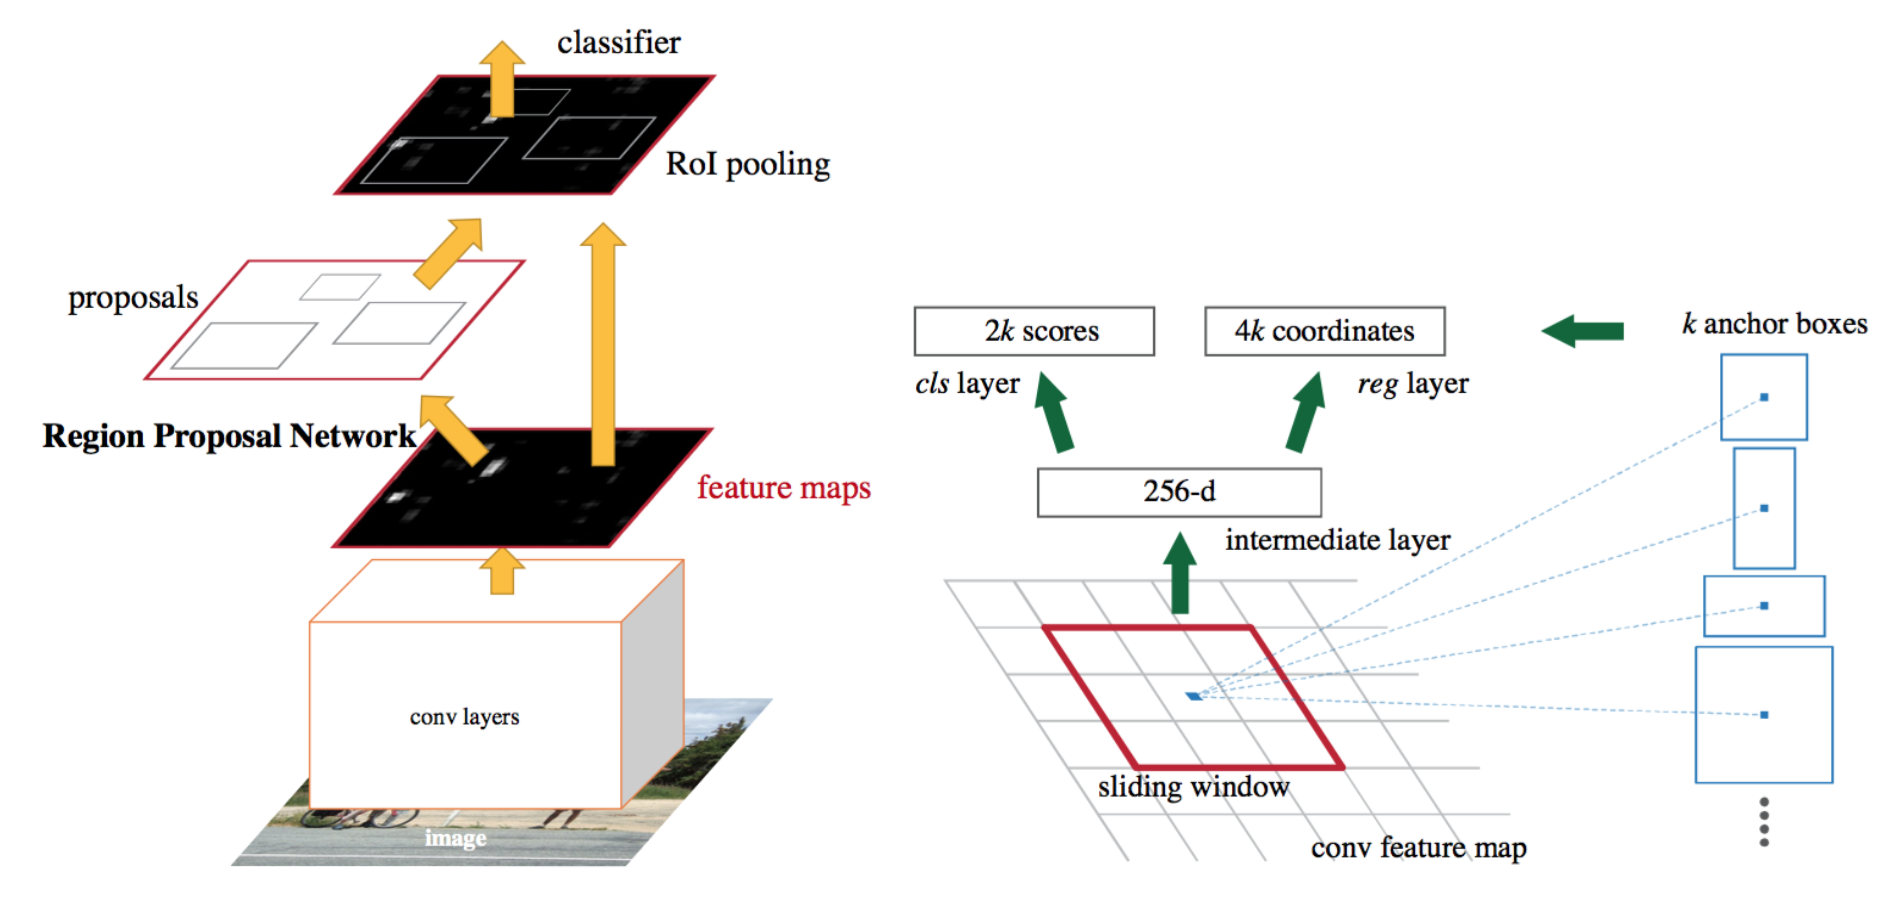
Faster R-CNN is optimized for a multi-task loss function, similar to fast R-CNN.
| Symbol | Explanation | | $p_i$ | Predicted probability of anchor i being an object. | | $p^*_i$ | Ground truth label (binary) of whether anchor i is an object. | | $t_i$ | Predicted four parameterized coordinates. | | $t^*_i$ | Ground truth coordinates. | | $N_\text{cls}$ | Normalization term, set to be mini-batch size (~256) in the paper. | | $N_\text{box}$ | Normalization term, set to the number of anchor locations (~2400) in the paper. | | $\lambda$ | A balancing parameter, set to be ~10 in the paper (so that both $\mathcal{L}_\text{cls}$ and $\mathcal{L}_\text{box}$ terms are roughly equally weighted). | {:.info}
The multi-task loss function combines the losses of classification and bounding box regression:
where $\mathcal{L}_\text{cls}$ is the log loss function over two classes, as we can easily translate a multi-class classification into a binary classification by predicting a sample being a target object versus not. $L_1^\text{smooth}$ is the smooth L1 loss.
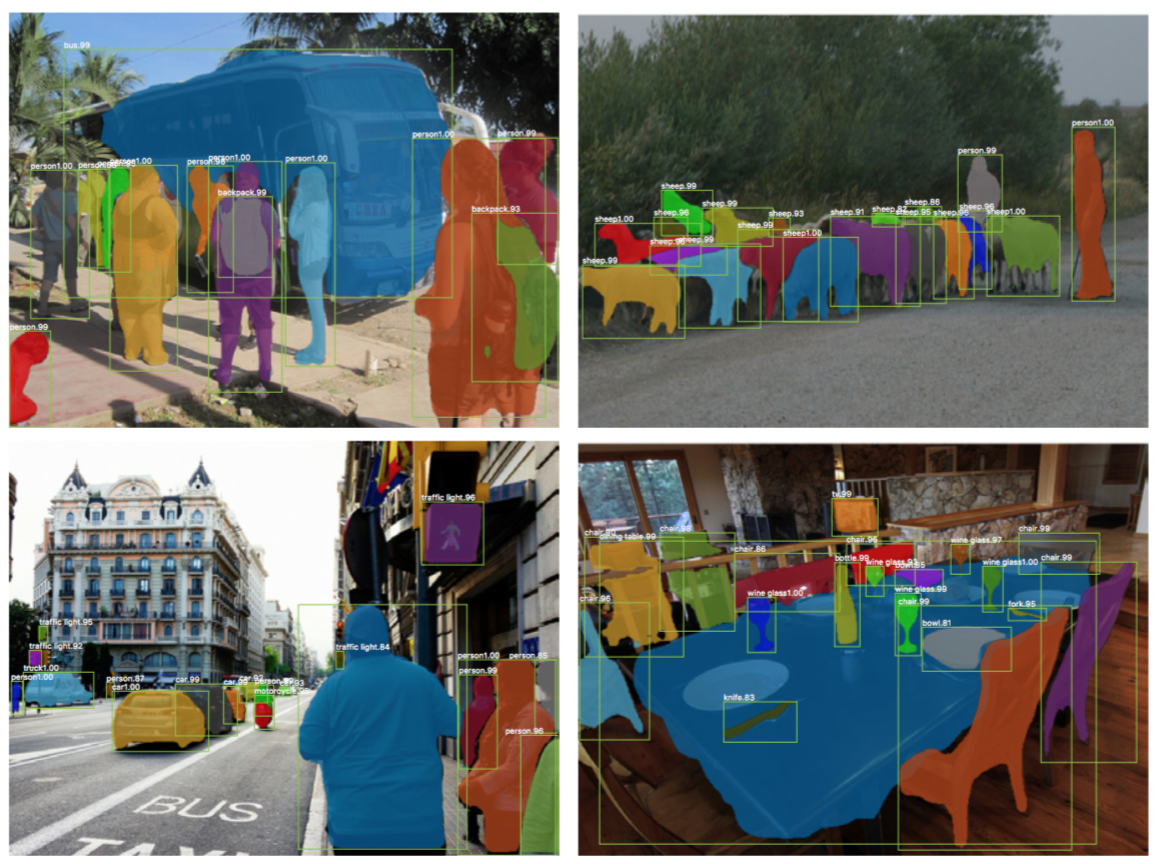
Mask R-CNN (He et al., 2017) extends Faster R-CNN to pixel-level image segmentation. The key point is to decouple the classification and the pixel-level mask prediction tasks. Based on the framework of Faster R-CNN, it added a third branch for predicting an object mask in parallel with the existing branches for classification and localization. The mask branch is a small fully-connected network applied to each RoI, predicting a segmentation mask in a pixel-to-pixel manner.
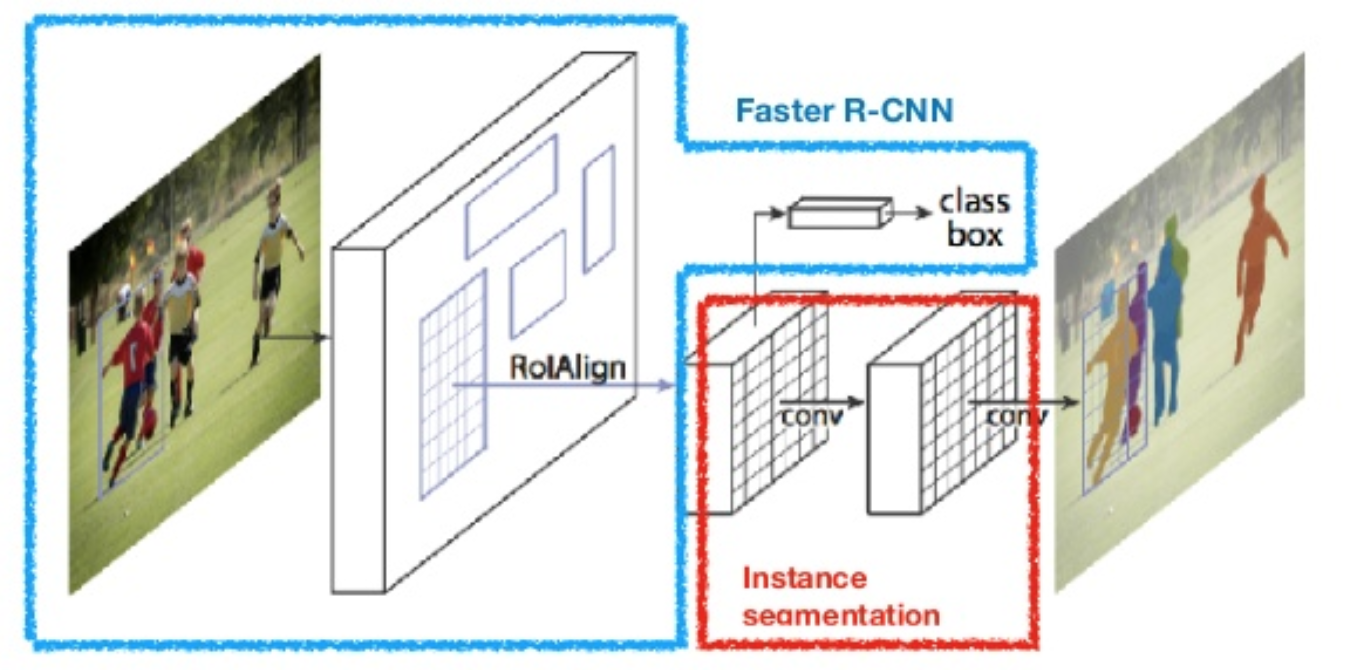
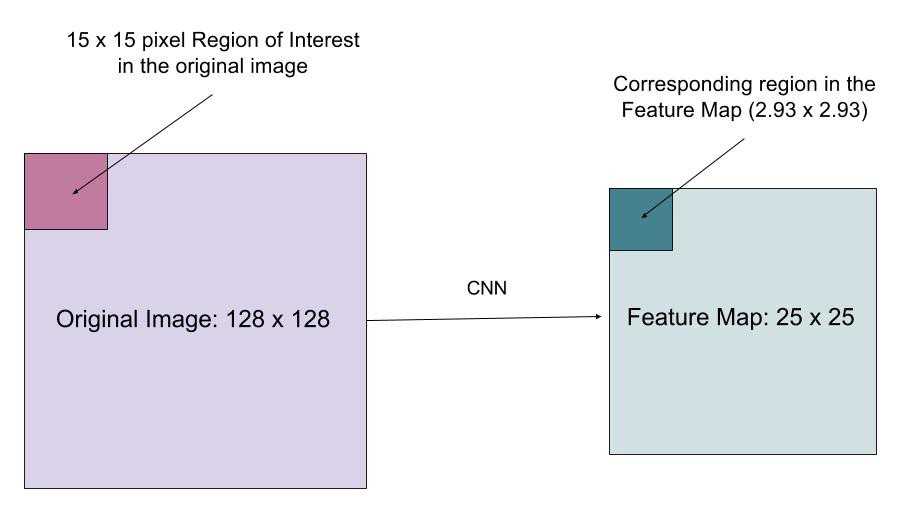
Because pixel-level segmentation requires much more fine-grained alignment than bounding boxes, mask R-CNN improves the RoI pooling layer (named “RoIAlign layer”) so that RoI can be better and more precisely mapped to the regions of the original image.
The RoIAlign layer is designed to fix the location misalignment caused by quantization in the RoI pooling. RoIAlign removes the hash quantization, for example, by using x/16 instead of [x/16], so that the extracted features can be properly aligned with the input pixels. Bilinear interpolation is used for computing the floating-point location values in the input.
The multi-task loss function of Mask R-CNN combines the loss of classification, localization and segmentation mask: $ \mathcal{L} = \mathcal{L}_\text{cls} + \mathcal{L}_\text{box} + \mathcal{L}_\text{mask}$, where $\mathcal{L}_\text{cls}$ and $\mathcal{L}_\text{box}$ are same as in Faster R-CNN.
The mask branch generates a mask of dimension m x m for each RoI and each class; K classes in total. Thus, the total output is of size $K \cdot m^2$. Because the model is trying to learn a mask for each class, there is no competition among classes for generating masks.
$\mathcal{L}_\text{mask}$ is defined as the average binary cross-entropy loss, only including k-th mask if the region is associated with the ground truth class k.
where $y_{ij}$ is the label of a cell (i, j) in the true mask for the region of size m x m; $\hat{y}_{ij}^k$ is the predicted value of the same cell in the mask learned for the ground-truth class k.
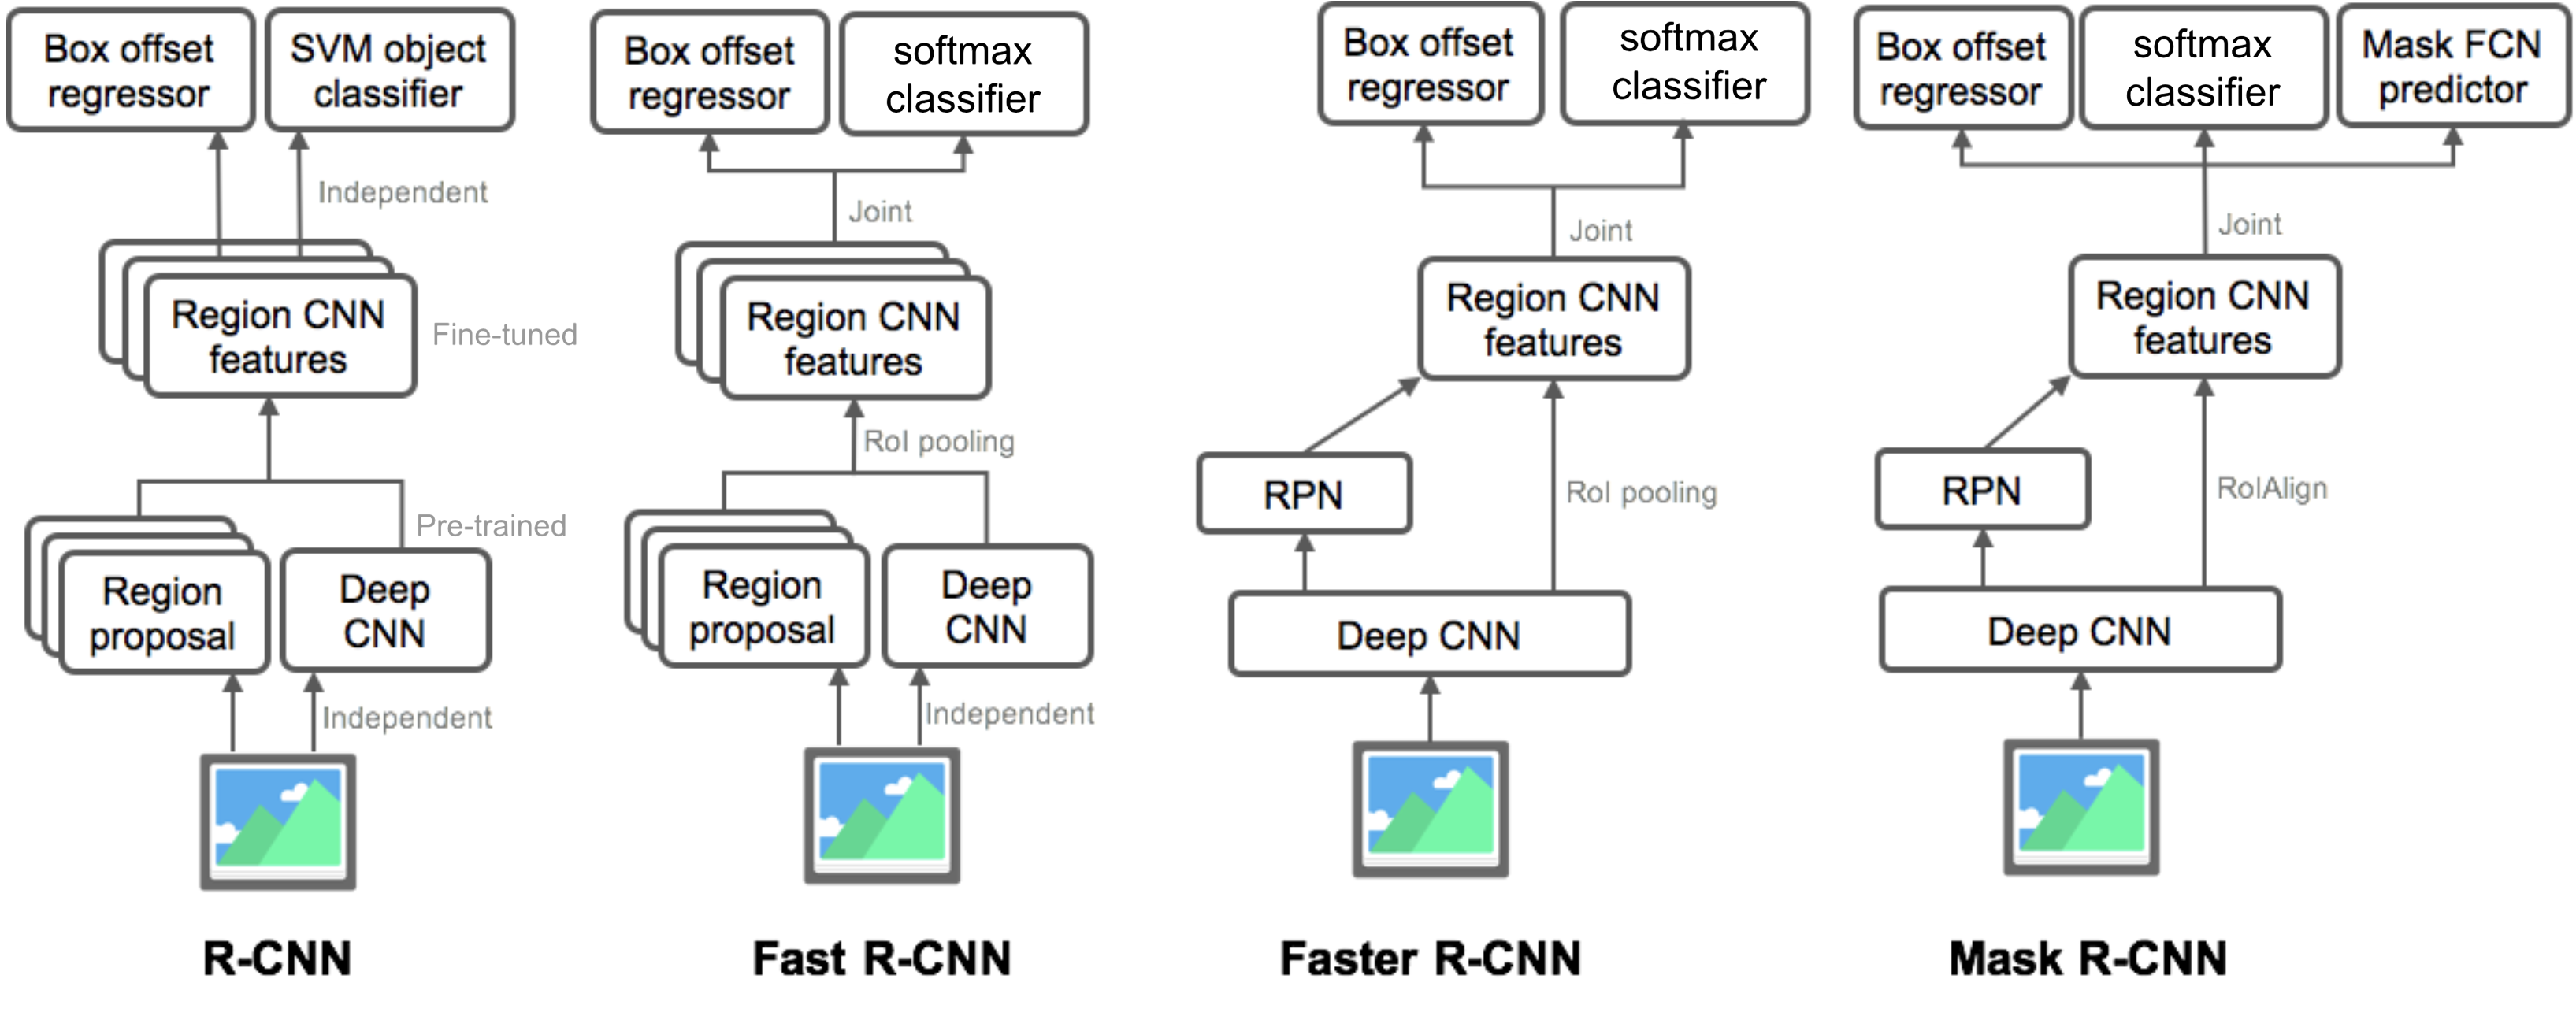
Here I illustrate model designs of R-CNN, Fast R-CNN, Faster R-CNN and Mask R-CNN. You can track how one model evolves to the next version by comparing the small differences.
Cited as:
@article{weng2017detection3,
  title   = "Object Detection for Dummies Part 3: R-CNN Family",
  author  = "Weng, Lilian",
  journal = "lilianweng.github.io",
  year    = "2017",
  url     = "https://lilianweng.github.io/posts/2017-12-31-object-recognition-part-3/"
}
[1] Ross Girshick, Jeff Donahue, Trevor Darrell, and Jitendra Malik. “Rich feature hierarchies for accurate object detection and semantic segmentation.” In Proc. IEEE Conf. on computer vision and pattern recognition (CVPR), pp. 580-587. 2014.
[2] Ross Girshick. “Fast R-CNN.” In Proc. IEEE Intl. Conf. on computer vision, pp. 1440-1448. 2015.
[3] Shaoqing Ren, Kaiming He, Ross Girshick, and Jian Sun. “Faster R-CNN: Towards real-time object detection with region proposal networks.” In Advances in neural information processing systems (NIPS), pp. 91-99. 2015.
[4] Kaiming He, Georgia Gkioxari, Piotr Dollár, and Ross Girshick. “Mask R-CNN.” arXiv preprint arXiv:1703.06870, 2017.
[5] Joseph Redmon, Santosh Divvala, Ross Girshick, and Ali Farhadi. “You only look once: Unified, real-time object detection.” In Proc. IEEE Conf. on computer vision and pattern recognition (CVPR), pp. 779-788. 2016.
[6] “A Brief History of CNNs in Image Segmentation: From R-CNN to Mask R-CNN” by Athelas.
[7] Smooth L1 Loss: https://github.com/rbgirshick/py-faster-rcnn/files/764206/SmoothL1Loss.1.pdf