保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Large Language Models
I Replaced GPT-4 with a Local SLM and My CI/CD Pipeline Stopped Failing
The hidden cost of probabilistic outputs in systems that demand reliability
Benjamin Nweke
April 21, 202611 min read
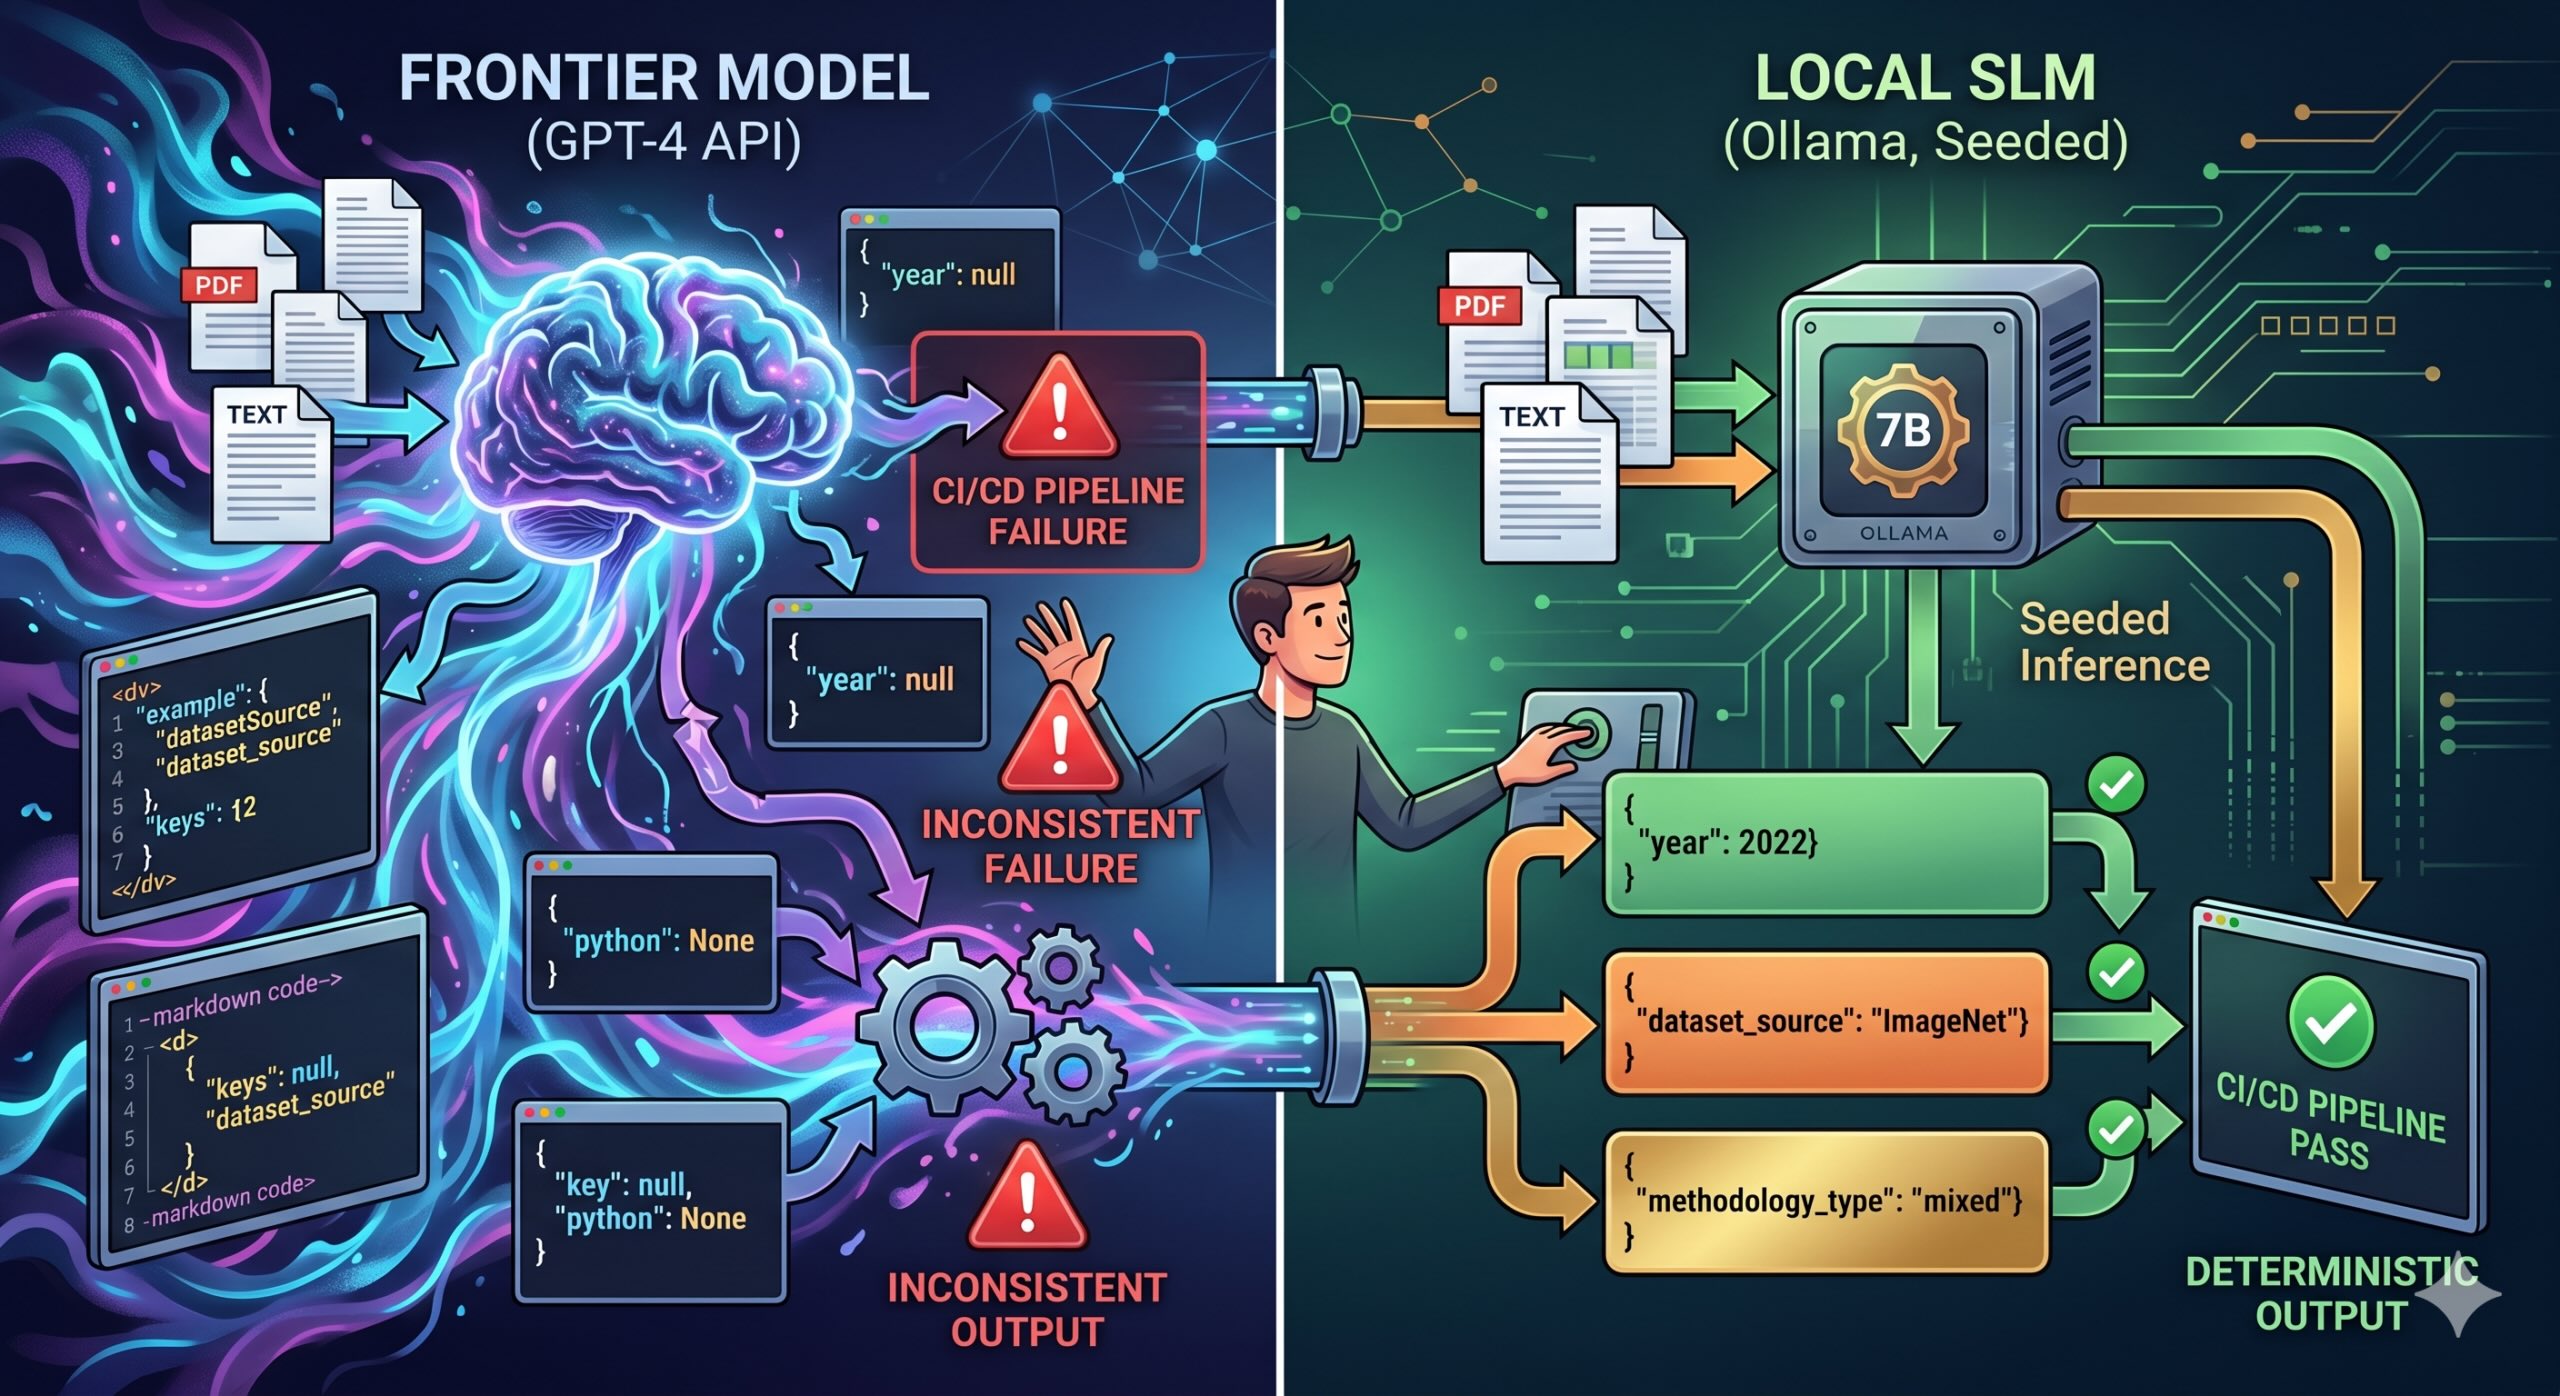 Image by author (Generated with Nano Banana Pro)
I was on my seventh rewrite of the same system prompt.
You MUST return ONLY valid JSON. No markdown. No code fences. No explanation. JUST the JSON object.
I had written MUST in all-caps. To a language model. As if emphasis would work on something that doesn't have feelings or, apparently, a consistent definition of "valid JSON."
It didn't work. Here's what did.
How GPT-4 Ended Up in a Nightly Batch Job
Our team consumes research documents, such as PDFs and plain text, and occasionally those pesky semi-structured reports that some vendor clearly exported from a spreadsheet they were very proud of. And part of that pipeline classifies them and extracts structured fields before anything touches the data warehouse. Methodology type, dataset source, key metrics.
This sounds like a solved problem. It usually is, until there are about forty types of methods listed and the documents stop looking anything like the ones you trained on.
For a while, we handled this using regex, rule-based extractors, and a fine-tuned BERT model. The good thing is, it worked, but maintaining it felt like fixing a CSS file from 2015, where you touch one rule and something unrelated breaks on a page you haven't visited in months.
So when GPT-4 came along, we tried it.
Not going to lie, it was kind of incredible. Edge cases that were driving BERT crazy for months, formats we'd never seen before, and documents with inconsistent sections were all taken care of cleanly by GPT-4.
The team demo went well. I mean, someone even said "wow" out loud.
I sent my manager a text that evening: "think we've cracked the extraction problem." Sent with confidence.
Two weeks after we deployed it, the failures started.
The Problem With "Mostly Consistent"
From my experience, GPT-4 is capable and non-deterministic.
For a lot of use cases, the non-determinism doesn't matter. For a nightly batch pipeline feeding a data warehouse, it matters a lot.
At temperature=0 you get mostly consistent outputs. In a CI/CD context, "mostly" means "it'll break on a Friday."
The failures weren't dramatic either; if not, that would've been easier to debug. GPT-4 was not hallucinating fields or returning garbage.
It was doing subtle things. "dataset_source" one night, "datasetSource" the next, "source_dataset" the night after. Markdown code fences around the JSON even though we'd told it not to, across every version of the prompt. Numbers returned as strings. JSON null returned as the Python string "None"; I spent longer than I'd like to admit staring at that one.
Each failure followed the same ritual.
Pydantic catches it downstream, pipeline fails, I confirm it's another formatting quirk, then I get to work immediately to re-run manually. It passes, then about three days later, a different quirk all over again.
So I started keeping a log. Six weeks of it:
- 23 pipeline failures from GPT-4 output inconsistency
- ~18 minutes average to diagnose and re-run
- 0 actual bugs in the pipeline code
Zero real bugs. Every single failure was the model being subtly different from what it had been the night before. That's the number that made me stop defending the setup.
What I Tried Before Admitting the Real Problem
Prompting
Seven rewrites over two days.
I didn't even realize it had gotten that much. I just wanted a good fix. And it didn't even stop there.
I tried all-caps instructions, few-shot examples, and counter-examples with a "Do NOT do this" header. I even tried adding a reminder at the very end of the user message as a last-ditch nudge, as if the model would get to that line and think oh right, JSON only, nearly forgot.
At one point, the same instruction appeared in three different places in the same prompt, and I genuinely thought that might help. Failures continued, unchanged.
A cleanup parser
When prompting failed, I wrote code to clean up any mess that GPT-4 threw back at me.
Strip markdown fences, find the JSON object if it was buried in text, and log the raw output when nothing worked.
This method actually worked for about a week, which was enough time for me to feel good about it.
And then GPT-4 began returning structurally valid JSON with wrong key names, camelCase instead of snake_case. The parser passed it through fine, and the error surfaced three steps later.
I was playing whack-a-mole with a model that had infinite moles.
**response_format**+**temperature=0**. OpenAI's response_format={"type": "json_object"} combined with temperature=0 brought failures from 23 down to about 9. Meaningful progress. Still not zero, and "nine random failures per six weeks" is not a pipeline property I could defend.
Function calling
This was the one that almost worked. Forcing output through a typed schema contract genuinely tightened things.
I stopped checking logs every morning, stopped bracing for the Slack notification. Told someone on the team it was stable. Which, if you work in software, you know is the fastest way to jinx something.
python
functions = [
    {
        "name": "extract_document_metadata",
        "parameters": {
            "type": "object",
            "properties": {
                "methodology_type": {
                    "type": "string",
                    "enum": ["experimental", "observational", "review", "simulation", "mixed"]
                },
                "dataset_source": {"type": "string"},
                "primary_metric": {"type": "string"},
                "year": {"type": "integer"},
                "confidence_score": {"type": "number", "minimum": 0, "maximum": 1}
            },
            "required": ["methodology_type", "dataset_source", "year"]
        }
    }
]

response = openai_client.chat.completions.create(
    model="gpt-4-turbo",
    messages=messages,
    functions=functions,
    function_call={"name": "extract_document_metadata"},
    temperature=0
)
Then one Tuesday, the OpenAI API had a 20-minute disruption. Pipeline failed hard; it wasn't a model issue, just a network dependency we'd never properly reckoned with.
We couldn't version-lock the model, couldn't run offline, couldn't answer "what changed between the run that worked and the run that didn't?" because the model on the other end wasn't ours.
Sitting there waiting for someone else's API to recover, I finally asked the question I should have asked months earlier: Does this specific job actually need a frontier model?
The Local Models Are Better Than I Expected
I went in fully expecting to spend a day confirming they weren't good enough. I had a conclusion ready before I'd run a single test: tried it, quality wasn't there, staying on GPT-4 with better retry logic. A story where the first decision was still defensible.
It took maybe three hours to realize I'd been thinking about this wrong.
Document extraction into a fixed schema isn't actually a hard task for a language model. Not in the way that makes a frontier model necessary. There's no reasoning involved, no synthesis, no need for the breadth of world knowledge that makes GPT-4 worth what it costs.
What it actually is: structured reading comprehension. The model reads a document and fills in fields. A well-trained 7B model does this fine. And with the right setup, specifically, seeded inference, it does it identically every single run.
I ran four models against 50 documents I'd manually annotated:
- Phi-3-mini (3.8B) : Better instruction following than I expected for a 3.8B model, but it fell apart on anything over about 3,000 tokens. I nearly picked this before I looked at the longer doc results.
- Mistral 7B Instruct : Solid everywhere, no real surprises in either direction. The Toyota Camry of local models. You'd be fine with this.
- Qwen2.5-7B-Instruct : This one won clearly. Best structured output consistency of the four by a margin wide enough that it wasn't a close call.
- Llama 3.2 3B Instruct : This is fast, but the extraction quality dropped off enough on edge cases that I wouldn't run it on production data without a lot more validation work first.
Qwen2.5 and Mistral both hit 90–95% accuracy on the annotated set, lower than GPT-4 on genuinely ambiguous documents, yes.
But I ran Qwen2.5 on the same 20 documents three times and went back to diff the results. No diffs. Same JSON, same values, same field order every run.
After six weeks of failures I couldn't predict, that felt almost too clean to be real.
Before and After
The GPT-4 extractor at its most stable, not the original prototype, the version after months of defensive code had accumulated around it:
python
# extractor_gpt4.py
import os
import json
from openai import OpenAI

client = OpenAI(api_key=os.environ["OPENAI_API_KEY"])

SYSTEM_PROMPT = """You are a research document metadata extractor.
Given the text of a research document, extract the specified metadata fields.
Be precise. If you are unsure about a field, use your best judgment based on context."""

EXTRACTION_SCHEMA = {
    "name": "extract_document_metadata",
    "parameters": {
        "type": "object",
        "properties": {
            "methodology_type": {
                "type": "string",
                "enum": ["experimental", "observational", "review", "simulation", "mixed"]
            },
            "dataset_source": {"type": "string"},
            "primary_metric": {"type": "string"},
            "year": {"type": "integer"},
            "confidence_score": {"type": "number"}
        },
        "required": ["methodology_type", "dataset_source", "year"]
    }
}

def extract_metadata_gpt4(document_text: str) -> dict:
    response = client.chat.completions.create(
        model="gpt-4-turbo",
        messages=[
            {"role": "system", "content": SYSTEM_PROMPT},
            {"role": "user", "content": f"Extract metadata from this document:\n\n{document_text[:8000]}"}
        ],
        functions=[EXTRACTION_SCHEMA],
        function_call={"name": "extract_document_metadata"},
        temperature=0,
        timeout=30
    )
    try:
        args = response.choices[0].message.function_call.arguments
        return json.loads(args)
    except (AttributeError, json.JSONDecodeError) as e:
        raise ValueError(f"Failed to parse GPT-4 response: {e}")
Latency: 3.5–5.8s per document. Cost: ~$0.04 per call. Failure rate: ~6% after all the fixes.
For the replacement, I chose Ollama. A colleague mentioned it offhandedly, and the docs looked reasonable at 11 pm, which is honestly how a lot of infrastructure decisions get made. The REST API is close enough to OpenAI's that the swap took about an hour:
python
# extractor_slm.py
import json
import logging
import os
import re

import requests

logger = logging.getLogger(__name__)

OLLAMA_URL = os.getenv("OLLAMA_URL", "http://localhost:11434")
MODEL = os.getenv("MODEL_NAME", "qwen2.5:7b-instruct-q4_K_M")

# Tested empirically: 7B q4 on a T4 takes ~8s on cold first token,
# then ~1.5s per doc chunk. 45s covers bad days.
_TIMEOUT = 45

_SYSTEM_PROMPT = """\
You are a metadata extractor for research documents.
Return ONLY a JSON object — no explanation, no markdown, no surrounding text.

Fields to extract:
- methodology_type (required): one of experimental | observational | review | simulation | mixed
- dataset_source (required): where the data came from
- year (required): integer
- primary_metric: main eval metric if present
- confidence_score: your confidence 0.0–1.0

Output example:
{"methodology_type": "experimental", "dataset_source": "ImageNet", "year": 2022, "primary_metric": "top-1 accuracy", "confidence_score": 0.95}
"""

def call_ollama(doc_text: str) -> dict:
    payload = {
        "model": MODEL,
        "messages": [
            {"role": "system", "content": _SYSTEM_PROMPT},
            {"role": "user", "content": doc_text[:6000]},
        ],
        "stream": False,
        "options": {
            "temperature": 0,
            "seed": 42,  # determinism — this is the whole point
        },
    }

    try:
        resp = requests.post(f"{OLLAMA_URL}/api/chat", json=payload, timeout=_TIMEOUT)
        resp.raise_for_status()
    except requests.exceptions.Timeout:
        raise RuntimeError(f"Ollama timed out after {_TIMEOUT}s — is the model loaded?")
    except requests.exceptions.ConnectionError:
        raise RuntimeError(f"Can't reach Ollama at {OLLAMA_URL} — is the container running?")

    raw = resp.json()["message"]["content"].strip()
    cleaned = re.sub(r"^```(?:json)?\s*|\s*```$", "", raw).strip()

    try:
        return json.loads(cleaned)
    except json.JSONDecodeError as e:
        logger.error("Failed to parse model output: %s\nRaw was: %s", e, raw[:400])
        raise
The seed: 42 in options is what actually delivers the determinism. Ollama supports seeded generation; same input, same seed, same output, every time, not approximately. temperature=0 with a hosted API implied this but never guaranteed it because you're not controlling the runtime. Locally, you are.
Getting It Into GitHub Actions
Two things that aren't obvious until they bite you. First: GitHub Actions service containers are network-isolated from the runner. You can't docker exec into them; the model pull has to go through the REST API. Second: cache the model. A cold pull is 4.7GB and adds 3–4 minutes to every job.
yaml
# The non-obvious parts — the rest is standard Actions boilerplate
- name: Cache Ollama model
  uses: actions/cache@v4
  with:
    path: ~/.ollama/models
    key: ollama-qwen2.5-7b-q4

- name: Pull SLM model
  # Can't docker exec into service containers — use the API
  run: |
    curl -s http://localhost:11434/api/pull \
      -d '{"name": "qwen2.5:7b-instruct-q4_K_M"}' \
      --max-time 300

- name: Warm up model
  run: |
    curl -s http://localhost:11434/api/generate \
      -d '{"model": "qwen2.5:7b-instruct-q4_K_M", "prompt": "hello", "stream": false}' \
      > /dev/null

- name: Run ingestion pipeline
  run: python pipeline/run_ingestion.py
  env:
    OLLAMA_URL: "http://localhost:11434"
    MODEL_NAME: "qwen2.5:7b-instruct-q4_K_M"
The Capitalization Bug I Spent Too Long On
Qwen 2.5 occasionally returns "Experimental" with a capital E despite explicit instructions not to. The Literal type check rejects it, and you get a validation failure on a document the model actually extracted correctly.
I spent an embarrassingly long time on this because the error message just said "invalid value," and my first instinct was to look at the document, then the extractor, before I finally looked at the validator and saw it.
A normalize_methodology validator with mode="before" fixes it before the type check runs:
python
# pipeline/validation.py
from typing import Literal, Optional
from pydantic import BaseModel, Field, field_validator

class DocMetadata(BaseModel):
    methodology_type: Literal["experimental", "observational", "review", "simulation", "mixed"]
    dataset_source: str = Field(min_length=3)
    year: int = Field(ge=1950, le=2030)
    primary_metric: Optional[str] = None
    confidence_score: Optional[float] = Field(default=None, ge=0.0, le=1.0)

    @field_validator("dataset_source")
    @classmethod
    def strip_whitespace(cls, v: str) -> str:
        return v.strip()

    @field_validator("methodology_type", mode="before")
    @classmethod
    def normalize_methodology(cls, v: str) -> str:
        # Qwen occasionally returns "Experimental" despite instructions
        return v.lower().strip() if isinstance(v, str) else v
···
I want to be straight about the tradeoffs because I hate articles that don't.
GPT-4 is genuinely better on ambiguous documents, non-English text, anything requiring real inference. There's a class of document in our corpus, older PDFs, reports mixing multiple languages, non-standard formats, where the SLM stumbles and GPT-4 wouldn't.
We flag those separately and route them to a review queue. That's not seamless, but it's honest. The SLM does the 90% it's good at and doesn't get asked to do the rest.
The setup is also more work than pip install openai. First-time configuration takes a real afternoon. And Ollama doesn't auto-update models, so version management is my problem now. I've genuinely made peace with that, knowing exactly what model version ran last night and the night before is the whole point.
···
What I Think Now
The morning the pipeline first ran clean, no notification, no re-run, just a log file showing 312 documents processed in 8.4 minutes, I checked it twice, then ran it manually again.
I'd spent six weeks half-expecting an alert before I'd even finished my coffee. Watching it pass quietly felt genuinely strange.
The failure wasn't using GPT-4. The failure was treating a probabilistic system like a deterministic function. temperature=0 reduces variance. It doesn't eliminate it.
I understood this in theory the whole time. It took 23 failures to understand it in a way that changed how I build things.
If you're running an LLM in an automated pipeline and things keep breaking in ways you can't reproduce, it might not be your code or your prompts. It might be the nature of what you're depending on.
A local model on hardware you control, seeded for determinism, is a genuinely different class of tool for this kind of job. Not better at everything but better at being the same thing twice. And for a pipeline that runs unattended every night, that's most of what actually matters.
···
Before you go!
If this was useful, I write more about the messy reality behind building with AI, what breaks in production, what actually works, and the tradeoffs behind the fixes.
You can subscribe to mynewsletter if you'd like more of that.
Connect With Me
···
References
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
Benjamin Nweke is a Computer Science graduate and technical writer exploring AI, machine learning, and data science. He writes about building reliable AI systems, model evaluation, agentic architectures, and the practical challenges that appear when machine learning moves beyond experiments. His work focuses on making technically complex ideas clear, useful, and grounded in real implementation.
See all from Benjamin Nweke
Deep DivesArtificial IntelligenceDocument ProcessingLlmMachine Learning
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Machine Learning
A beginner friendly use of cosine similarity
Jose Manuel Napoles-Duarte
July 8, 20213 min read
Artificial Intelligence
SQLGlot - A one-stop SQL parsing and manipulation Python Library
Christopher Tao
January 15, 202410 min read
Artificial Intelligence
Theoretical explanation and a practical example.
Soner Yıldırım
May 24, 20204 min read
Machine Learning
Learn about the key fundamentals of F1-score, one of the most important evaluation metrics in machine learning.
Zeya LT
November 23, 20219 min read
Artificial Intelligence
LangChain and LangGraph - A deep dive on key building blocks, how they handle core pieces of their functionality, and deciding between...
Sandi Besen
October 25, 202411 min read
Machine Learning
Production logging approaches for AI and data pipelines
Isaac Backus
September 22, 20208 min read
Machine Learning
I expected adding more communication pathways between agents to dramatically change network performance. It didn't. Figuring out why turned into a more useful article than the one I set out to write.
Emmimal P Alexander
August 18, 202614 min read
Machine Learning
College Statistics with Python
Luís Roque
July 1, 202113 min read
Artificial Intelligence
In a recent post I offered a few predictions on how the Biden Administration may change the AI playing field. The main takeaway is that AI...
Natalia Modjeska
March 4, 20219 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network