保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Artificial Intelligence
Can Synthetic Data Boost Machine Learning Performance?
Investigating the Capability of Synthetic Data to Enhance Model Performance on Imbalanced Datasets
John Adeojo
July 5, 20237 min read
 Image by Author: Generated with Midjourney
Background - Imbalanced Datasets
Imbalanced classification problems frequently occur in commercial machine learning use cases. You may encounter them in churn prediction, fraud detection, medical diagnosis, or spam detection. In all these scenarios, what we aim to detect belongs to the minority class, which can be highly underrepresented in our data. There are several approaches proposed for enhancing the performance of models on imbalanced datasets:
- Undersampling : Achieve a more balanced training dataset by randomly undersampling the majority class.
- Oversampling : Obtain a balanced training dataset by randomly oversampling the minority class.
- Weighted Losses : Assign weights to the loss function in relation to the minority class.
- Synthetic Data : Use generative AI to create high-fidelity synthetic data samples of the minority class.
In this article I demonstrate how training a model on synthetic data surpasses the other approaches in enhancing the performance of the classifier.
Learn this step by step with the interactive AI Engineer, AI and Data Scientist, Computer Science and Machine Learning roadmaps.
The Dataset
The data is sourced from Kaggle, consisting of 284,807 credit card transactions, 492 (0.172%) of which are labelled as fraudulent. The data is available for both commercial and non-commercial usage under the Open Data Commons license.
For interested readers, Kaggle offers more detailed information and basic descriptive statistics about the data.
From this Kaggle dataset, I create two subsets: a training set and a holdout set. The training set comprises 80% of the total data, along with synthetically generated samples when exploring that approach. The holdout set constitutes 20% of the original data, excluding any synthetic samples.
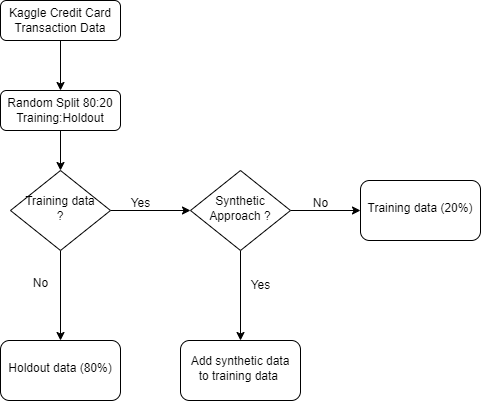 Image by Author: Data splitting process
The Model
I use Ludwig, an open-source, declarative framework for building deep learning models due to it's ease of implementation. Models are easily built and trained by declaring them in a yaml file and running a training job through Ludwig's python API. I have written an article previously that details Ludwig for those who are interested.
For each approach, I use the same baseline model, only adjusting specific parameters as necessary. For instance, Ludwig allows for weight and sampling adjustments natively - These are simply adjusted in the yaml file. I have provided links to the model configuration yaml files for each approach for your exploration.
- Baseline Model - link
- Weighted losses model - link
- Undersampling model - link
- Oversampling model - link
- Synthetic data - Utilises the same model as the baseline as the classes are balanced.
Generating Synthetic Data
I utilise Synthetic Data Vault (SDV), an open-source library for generating synthetic data samples. With SDV, I generate an additional 284k synthetic fraud samples, thereby achieving equal representation of both classes in the training dataset.
The synthetic samples are generated with variational autoencoders adapted for tabular data (TVAE). You can find more details on the theory behind TVAEs in this paper.
SDV offers diagnostic statistics, giving an indication of fit quality. You can manually explore the fit quality by comparing variable distributions in the real data versus the generated data as shown in the examples below.
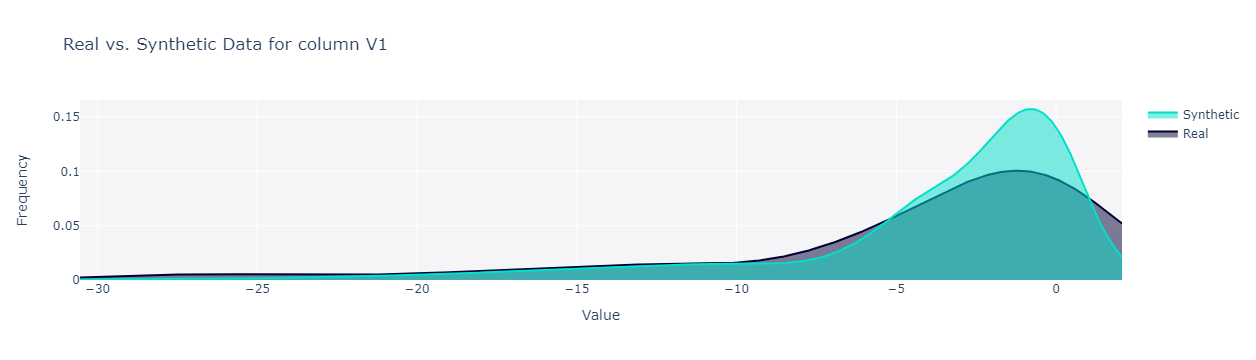 Image by Author: Real vs synthetic distribution for variable v1
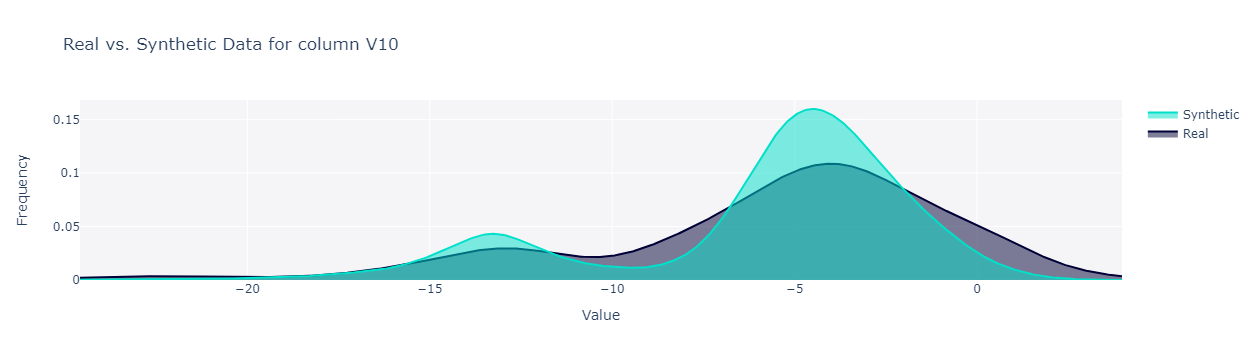 Image by Author: Real vs synthetic distribution for variable v10
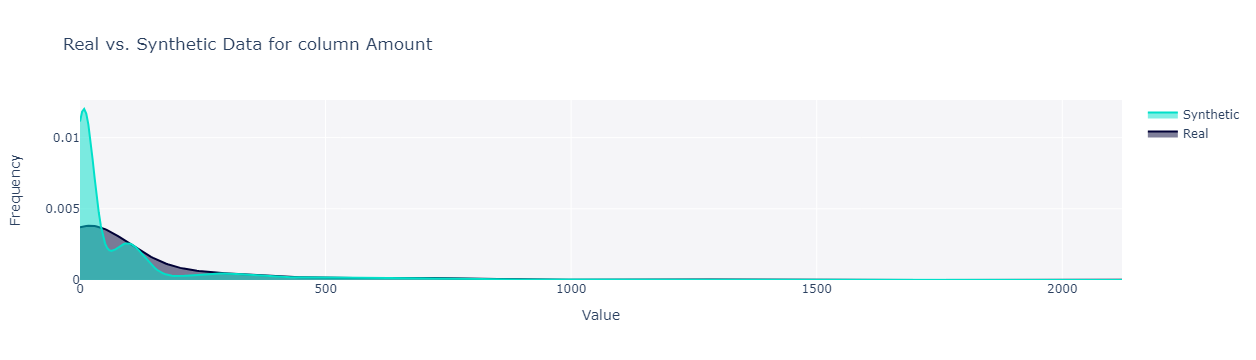 Image by Author: Real vs. synthetic distribution for variable amount
Assessing Performance with Precision Recall Charts
We assess the performance of each model by plotting the precision versus recall curves of the models against the holdout dataset.
Precision-Recall Curve
The Precision-Recall curve, a plot of Precision (on the y-axis) against Recall (on the x-axis) for varying thresholds, is akin to the ROC curve. It serves as a robust diagnostic tool for evaluating model performance in scenarios of significant class imbalance, such as our credit card fraud detection use case, a prime example.
The top-right corner of the plot represents the "ideal" point - a false positive rate of zero and a true positive rate of one. A skilled model should reach this point or come close to it, implying a larger area under the curve (AUC-PR) can suggest a superior model.
No Skill Predictor
A "no skill" predictor is a naïve model that makes predictions randomly. For imbalanced datasets, the no skill line is a horizontal line at a height equivalent to the positive class proportion. This is because if the model randomly predicts the positive class, precision would be equivalent to the positive instances proportion in the dataset.
Model Performance - Baseline
The baseline model is the deep neural network with no sample adjustments, loss function adjustments, or augmented training data. Each approach is compared to the baseline performance, which serves as a performance bench mark.
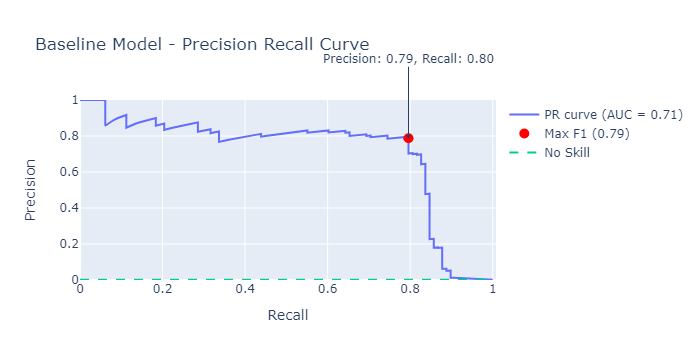 Image by Author: Precision-recall curve for baseline model
Model Performance - Weighted Losses Approach
Weighted loss adjusts the loss function based on the ratio of fraudulent to non-fraudulent transactions.
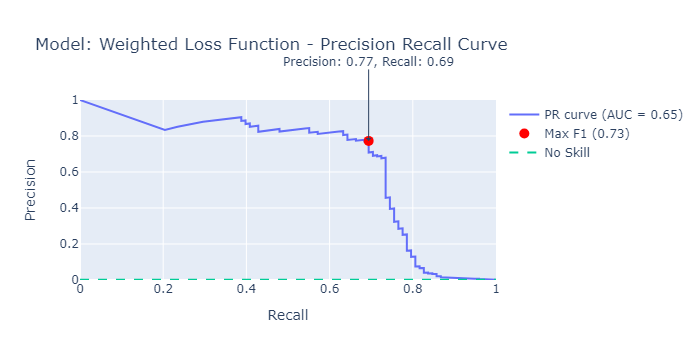 Image by Author: Precision-recall curve for loss weighted approach
Model Performance - Oversampling Approach
Oversampling randomly oversamples the fraudulent transactions until there is equal representation across the classes in the training dataset.
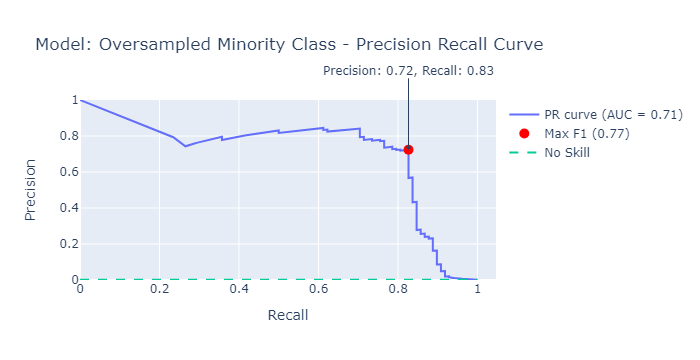 Image by Author: Precision-recall curve for oversampling approach
Model Performance - Undersampling Approach
Undersampling randomly undersamples the non-fraudulent transactions until there is equal representation across classes in the training dataset.
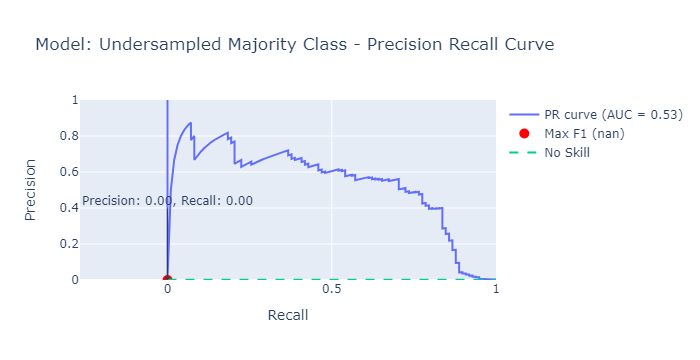 Image by Author: Precision-recall curve for undersampling approach
Model Performance - Synthetic Data Approach
Leverage the TVAEs to produce 284k synthetic, fraudulent samples to gain an equal representation across classes in the training dataset.
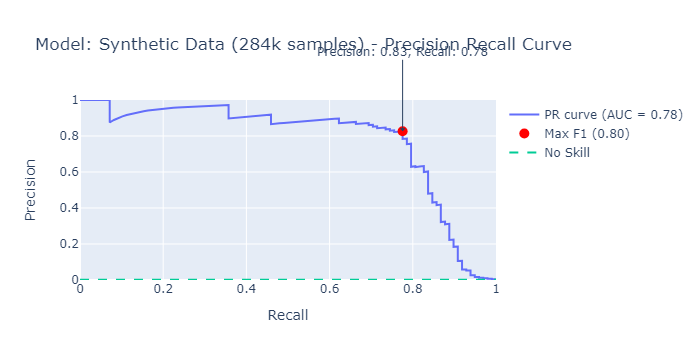 Image by Author: Precision-recall curve for synthetic data approach
Bootstrapping Holdout Dataset
To obtain a robust view of performance on the holdout set, I created fifty bootstrapped holdout sets from the original. Running the models associated with each approach across all sets provides a distribution of performance. We can then determine whether each approach is statistically significantly different from the baseline using the Kolmogorov-Smirnov test.
Weighted : The weighted approach marginally underperformed across recall and AUC relative to the baseline. In addition to this, the variance across each performance metric appears quite high relative to the other approaches.
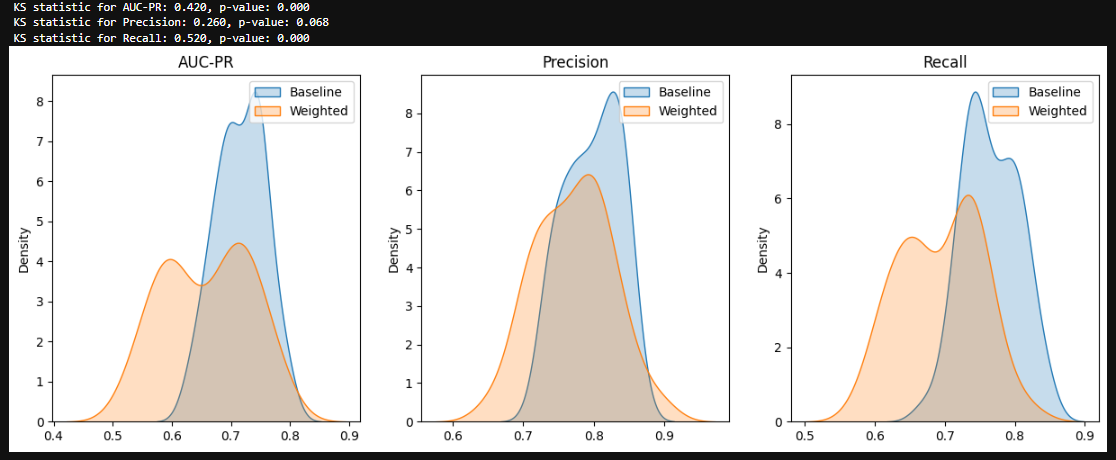 Image by Author: Model performance metrics over 50 bootstrapped holdout samples. Baseline vs Weighted Loss, KS stats - AUC 0.420 p-value < 0.000, precision 0.260 p-value 0.068, Recall 0.520 p-value < 0.000
Oversampling : The oversampling approach improves model recall relative to baseline, but results in a drastic deterioration of the precision.
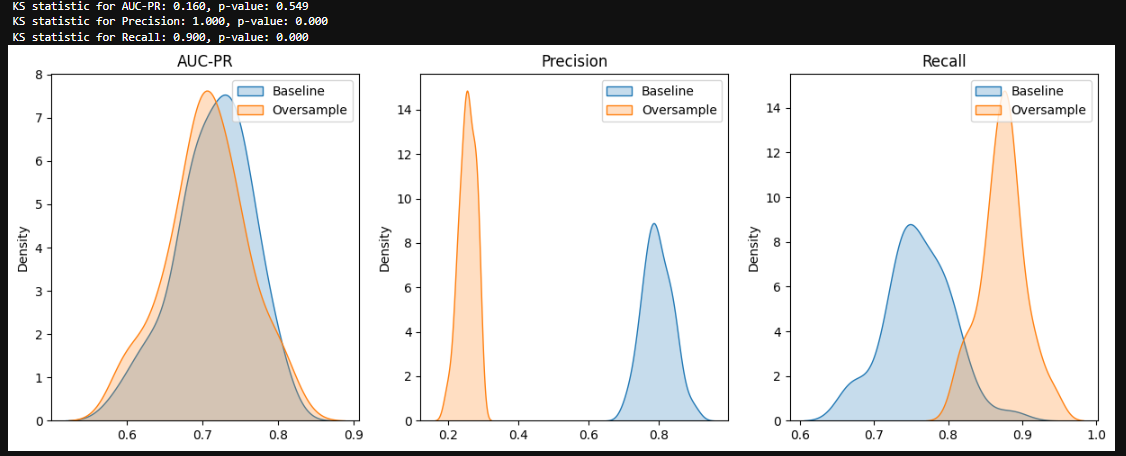 Image by Author: Model performance metrics over 50 bootstrapped holdout samples. Baseline vs Oversampling, KS stats - AUC 0.160 p-value 0.549, precision 1.0 p-value < 0.000, Recall 0.9 p-value < 0.000
Undersampling : The approach performs worse than baseline across all metrics.
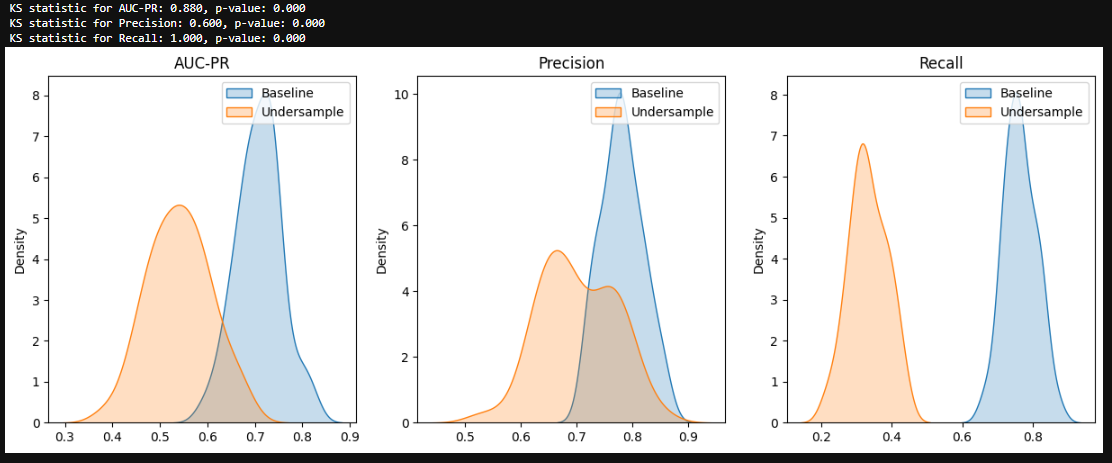 Image by Author: Model performance metrics over 50 bootstrapped holdout samples. Baseline vs Oversampling, KS stats - AUC 0.880 p-value < 0.000, precision 0.6 p-value < 0.000, Recall 1.0 p-value < 0.000
Synthetic : The synthetic method uplifts model recall, albeit at the cost of precision. While the impact on precision remains substantial, the synthetic approach provides a more resilient alternative for enhancing model recall with less of a detriment to precision when compared to the oversampling approach. The robustness of the synthetic approach is further evidenced by the uplift in AUC-PR.
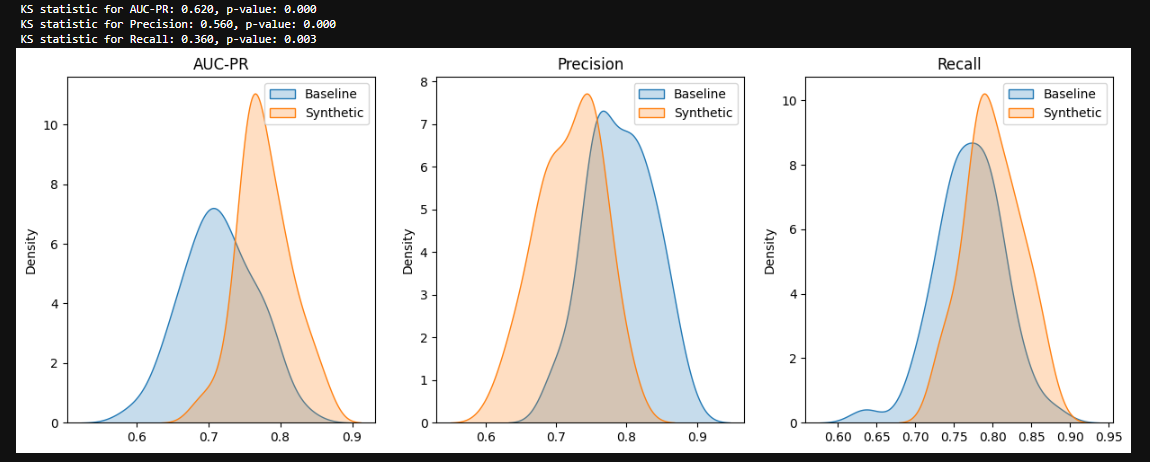 Image by Author: Model performance metrics over 50 bootstrapped holdout samples. Baseline vs Synthetic, KS stats - AUC 0.620, Precision 0.560, Recall 0.360 all p-values ≤ 0.003
Conclusion
We've noted that the synthetic data approach can boost model recall relative to the baseline at the expense of precision. Oversampling accomplishes a similar result, but model precision suffers drastically in comparison.
In our specific context of credit card fraud detection, false positives are not as costly as false negatives. Therefore, we can afford to compromise on model precision if it results in a significant boost in recall. Enriching our training data with synthetic instances seems to be an effective strategy to enhance recall while mitigating the detrimental effects on precision. This enhancement could notably affect profitability, especially when scaling the model to handle millions of transactions. Ultimately, attributing a exact cost to false positives and negatives will provide us with a clearer understanding of the most commercially viable approach, a topic beyond the scope of this article.
It would be fascinating to examine the performance across varying sample sizes of synthetic data, perhaps in conjunction with weighted losses. Similarly, experimenting with diverse oversampling ratios could potentially yield comparable effects to what we have observed with the synthetic approach.
The notebook for this project is available in my GitHub repo
Follow me on LinkedIn
Subscribe to medium to get more insights from me:
Join Medium with my referral link - John Adeojo
Should you be interested in integrating AI or data science into your business operations, we invite you to schedule a complimentary initial consultation with us:
Book Online | Data-Centric Solutions
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from John Adeojo
Editor's PicksArtificial IntelligenceData ScienceMachine LearningTechnology
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
Coding a small Flask server vs Coding a WebDNN browser model
Mostafa Ibrahim
June 12, 20217 min read
Machine Learning
Why degenerate feedback loops need to be urgently addressed when operating machine learning models
Anindya Datta
March 21, 20229 min read
Data Science
Introduction to a scale reflecting economic value of data.
Adam Votava
December 7, 20215 min read
Artificial Intelligence
Wheather you are a data analyst or a programmer
Dario Radečić
October 16, 20204 min read
Data Science
Or how I went from barely knowing how to use GitHub to 4 accepted pull requests in just a few weeks
Maria Ilie
November 3, 20204 min read
Artificial Intelligence
How to classify Arabic Text the right way
Tariq Massaoudi
October 18, 20206 min read
Introduction
Barbara Prkacin
April 12, 202111 min read
Programming
Intuition, a derivation and Jensen's Inequality The Mean Absolute Deviation (MAD) and Standard Deviation (STD)...
Mark Jamison
February 17, 20227 min read
Programming
Clean up your code by creating your own custom exceptions
Mike Huls
November 15, 20222 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close