保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Artificial Intelligence
Fine-Tune Your LLM Without Maxing Out Your GPU
How you can fine-tune your LLMs with limited hardware and a tight budget
John Adeojo
August 1, 20238 min read
 Image by Author: Generated with Midjourney
Demand for Bespoke LLMs
With the success of ChatGPT, we have witnessed a surge in demand for bespoke large language models.
However, there has been a barrier to adoption. As these models are so large, it has been challenging for businesses, researchers, or hobbyists with a modest budget to customise them for their own datasets.
Now with innovations in parameter efficient fine-tuning (PEFT) methods, it is entirely possible to fine-tune large language models at a relatively low cost. In this article, I demonstrate how to achieve this in a Google Colab.
I anticipate that this article will prove valuable for practitioners, hobbyists, learners, and even hands-on start-up founders.
So, if you need to mock up a cheap prototype, test an idea, or create a cool data science project to stand out from the crowd - keep reading.
Learn this step by step with the interactive AI Engineer, AI and Data Scientist and Machine Learning roadmaps.
Why Do We Fine-tune?
Businesses often have private datasets that drive some of their processes.
To give you an example, I worked for a bank where we logged customer complaints in an Excel spreadsheet. An analyst was responsible for categorising these complaints (manually) for reporting purposes. Dealing with thousands of complaints each month, this process was time-consuming and prone to human error.
Had we had the resources, we could have fine-tuned a large language model to carry out this categorisation for us, saving time through automation and potentially reducing the rate of incorrect categorisations.
Inspired by this example, the remainder of this article demonstrates how we can fine-tune an LLM for categorising consumer complaints about financial products and services.
The Dataset
The dataset comprises real consumer complaints data for financial services and products. It is open, publicly available data published by the Consumer Financial Protection Bureau.
There are over 120k anonymised complaints, categorised into approximately 214 "subissues".
I have a version of the dataset on my hugging face page that you can explore for yourself.
The Hardware
The hardware I used for training was a V100 GPU with 16 GB of RAM, accessed via Google Colab. This is a relatively inexpensive and accessible infrastructure, available for rent via Google Colab Pro at approximately 9.99 USD per 100 compute units.
The Large Language Model
The LLM used is RoBERTa¹ (XLM), which has approximately 563 million parameters. An overview of the model and its specification can be found here.
Though not the largest model currently available, RoBERTa still presents a demanding workload for those with access only to small-scale infrastructure. This makes it an ideal choice to demonstrate that training a relatively large model on small-scale infrastructure is feasible.
Note - RoBERTa is a pre-trained model pulled from the Hugging Face Hub .
Fine-tuning at Low Cost with LoRA
As stated in the introduction, PEFT methods have made it possible to fine-tune LLMs at a low cost. One such method is LoRA, which stands for Low-Rank Adaptations of large language models.
At a high level, LoRA accomplishes two things. First, it freezes the existing weights of the LLM (rendering them non-trainable); second, it injects trainable "lower-dimensional" layers into specified layers of the architecture.
This technique yields a model with far fewer trainable parameters while still preserving performance. LoRA has been shown to reduce GPU memory consumption by a factor of three compared to standard fine-tuning.
For further details on LoRA, please read the full paper.
Technical Details
In the past, the key challenge for training large language models on limited hardware was adapting the training parameters to prevent the process from crashing due to exceeding your GPU's memory capacity.
With LoRA, one can push the boundaries of their hardware with just a few adjustments.
Applying LoRA
Assuming you have your dataset prepared, the first thing you need to do is set your LoRA configurations.
- task_type - The task for which you're fine-tuning the model. For complaints classification, we are focusing on sequence classification.
- r - A hyperparameter named the LoRA attention dimension which affects the scaling.
- lora_alpha - Another hyperparameter that impacts the scaling.
- target_modules - Here we specify that the transformation should be applied to the attention modules in our transformer, hence we set this to "query" and "value".
- lora_dropout - The dropout probability for the LoRA layers.
- bias - The bias type for LoRA.
- modules_to_save - Excluding the LoRA layers, we declare which layers of our model we wish to make trainable and save at the final checkpoint. For our purposes, we require the classification head to be trainable.
The next part of the script sets up the model itself. Here we are simply loading the pre-trained RoBERTa model from Hugging Face. The additional model parameters are simply passing dictionaries to the classification IDs such that the returned labels are in text form rather than numerically encoded.
Finally, we want to transform the pre-trained model based on our LoRA configuration. This is done with the get_peft_model function.
After applying LoRA, we are left with a network with the following structure:
csharp
trainable params: 4,110,764
all params: 562,951,596
trainable%: 0.7302162440267778
Note: the original RoBERTa parameters are still in the network; they are simply frozen and therefore not trainable. Instead, we have the LoRA layers, which are fewer in number and trainable.
Initiate Training
Once we have our LoRA model, it's simply a matter of setting up our trainer and initiating the training process.
Most aspects in the script are standard for training deep learning models; however, we have incorporated a few additional elements to improve GPU memory efficiency. Let's briefly outline them.
- Per_device_train_batch_size - Setting this parameter to lower values maintains low RAM usage on your GPU at the expense of training speed. The lower the number, the more training steps are required to complete one epoch. Remember, one epoch is a complete run through the entire training dataset.
- Per_device_eval_batch - Setting this parameter dictates how many data samples are processed on each GPU core. Increasing this number increases the speed of evaluation and therefore the speed of training, but at the cost of GPU memory usage.
- Gradient_accumulation_steps - Usually, when updating deep learning models, there is a forward pass through the network and a loss is calculated. Following this, through a process known as backpropagation, the gradients are calculated and used to update the model parameters. With gradient accumulation, model parameters are not updated immediately after one forward pass. Instead, the gradients are stored and accumulated over the number of batches specified. Only after all the batches have passed through the network will the accumulated gradients be applied to update the parameters in the network. The effect here is to increase the effective batch size, meaning the model can effectively train on a larger batch size enabling you to reap the benefits of training on larger batches without the cost in GPU RAM usage.
- Fp16 (mixed-precision training) - Setting mixed precision training to true can help improve training speed at the cost of GPU usage. Essentially, some calculations in the network are done in 16-bit (half precision) instead of 32-bit (full precision) to speed up the calculations. However, the method requires both a 16-bit and 32-bit version of the model to be stored on your GPU device meaning 1.5 RAM usage.
Model Diagnostics
Let's see how everything performed. Since this is about training effectively with limited hardware, let's start by looking at the GPU RAM diagnostics.
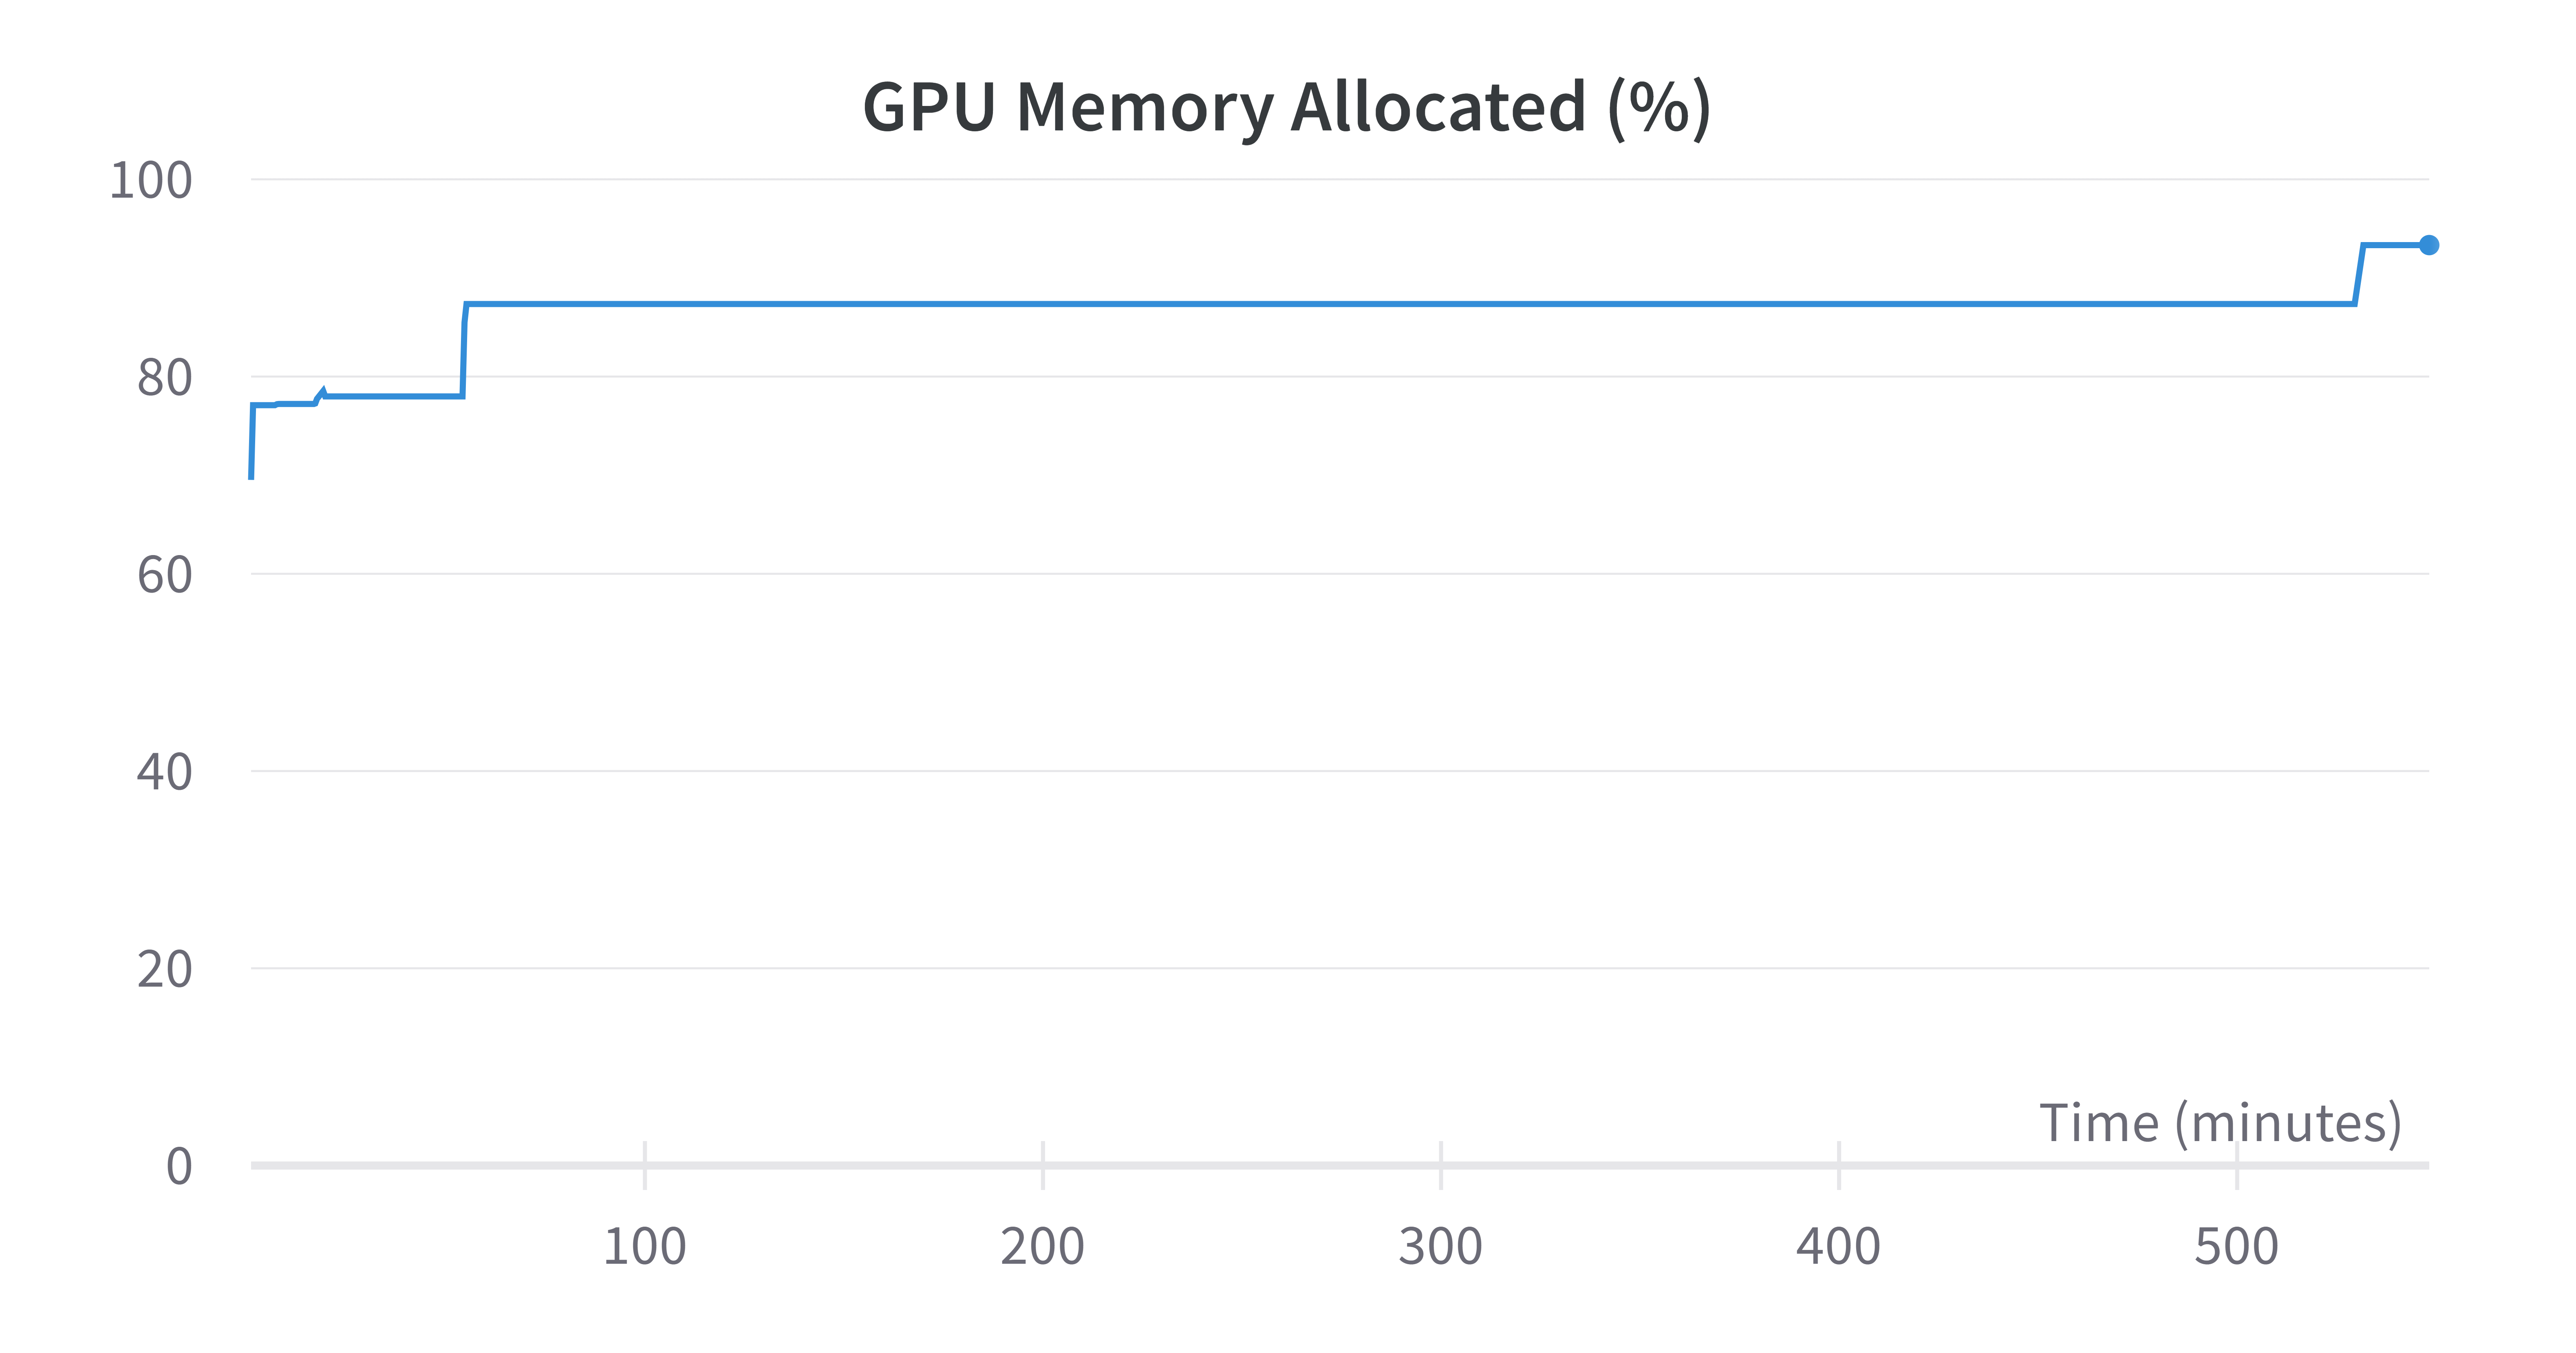 Image by Author: GPU RAM usage chart
We were able to train our model for 9 hours without exceeding the RAM on our GPU. This is a good result.
What about the model performance? Let's take a look at the validation and training loss.
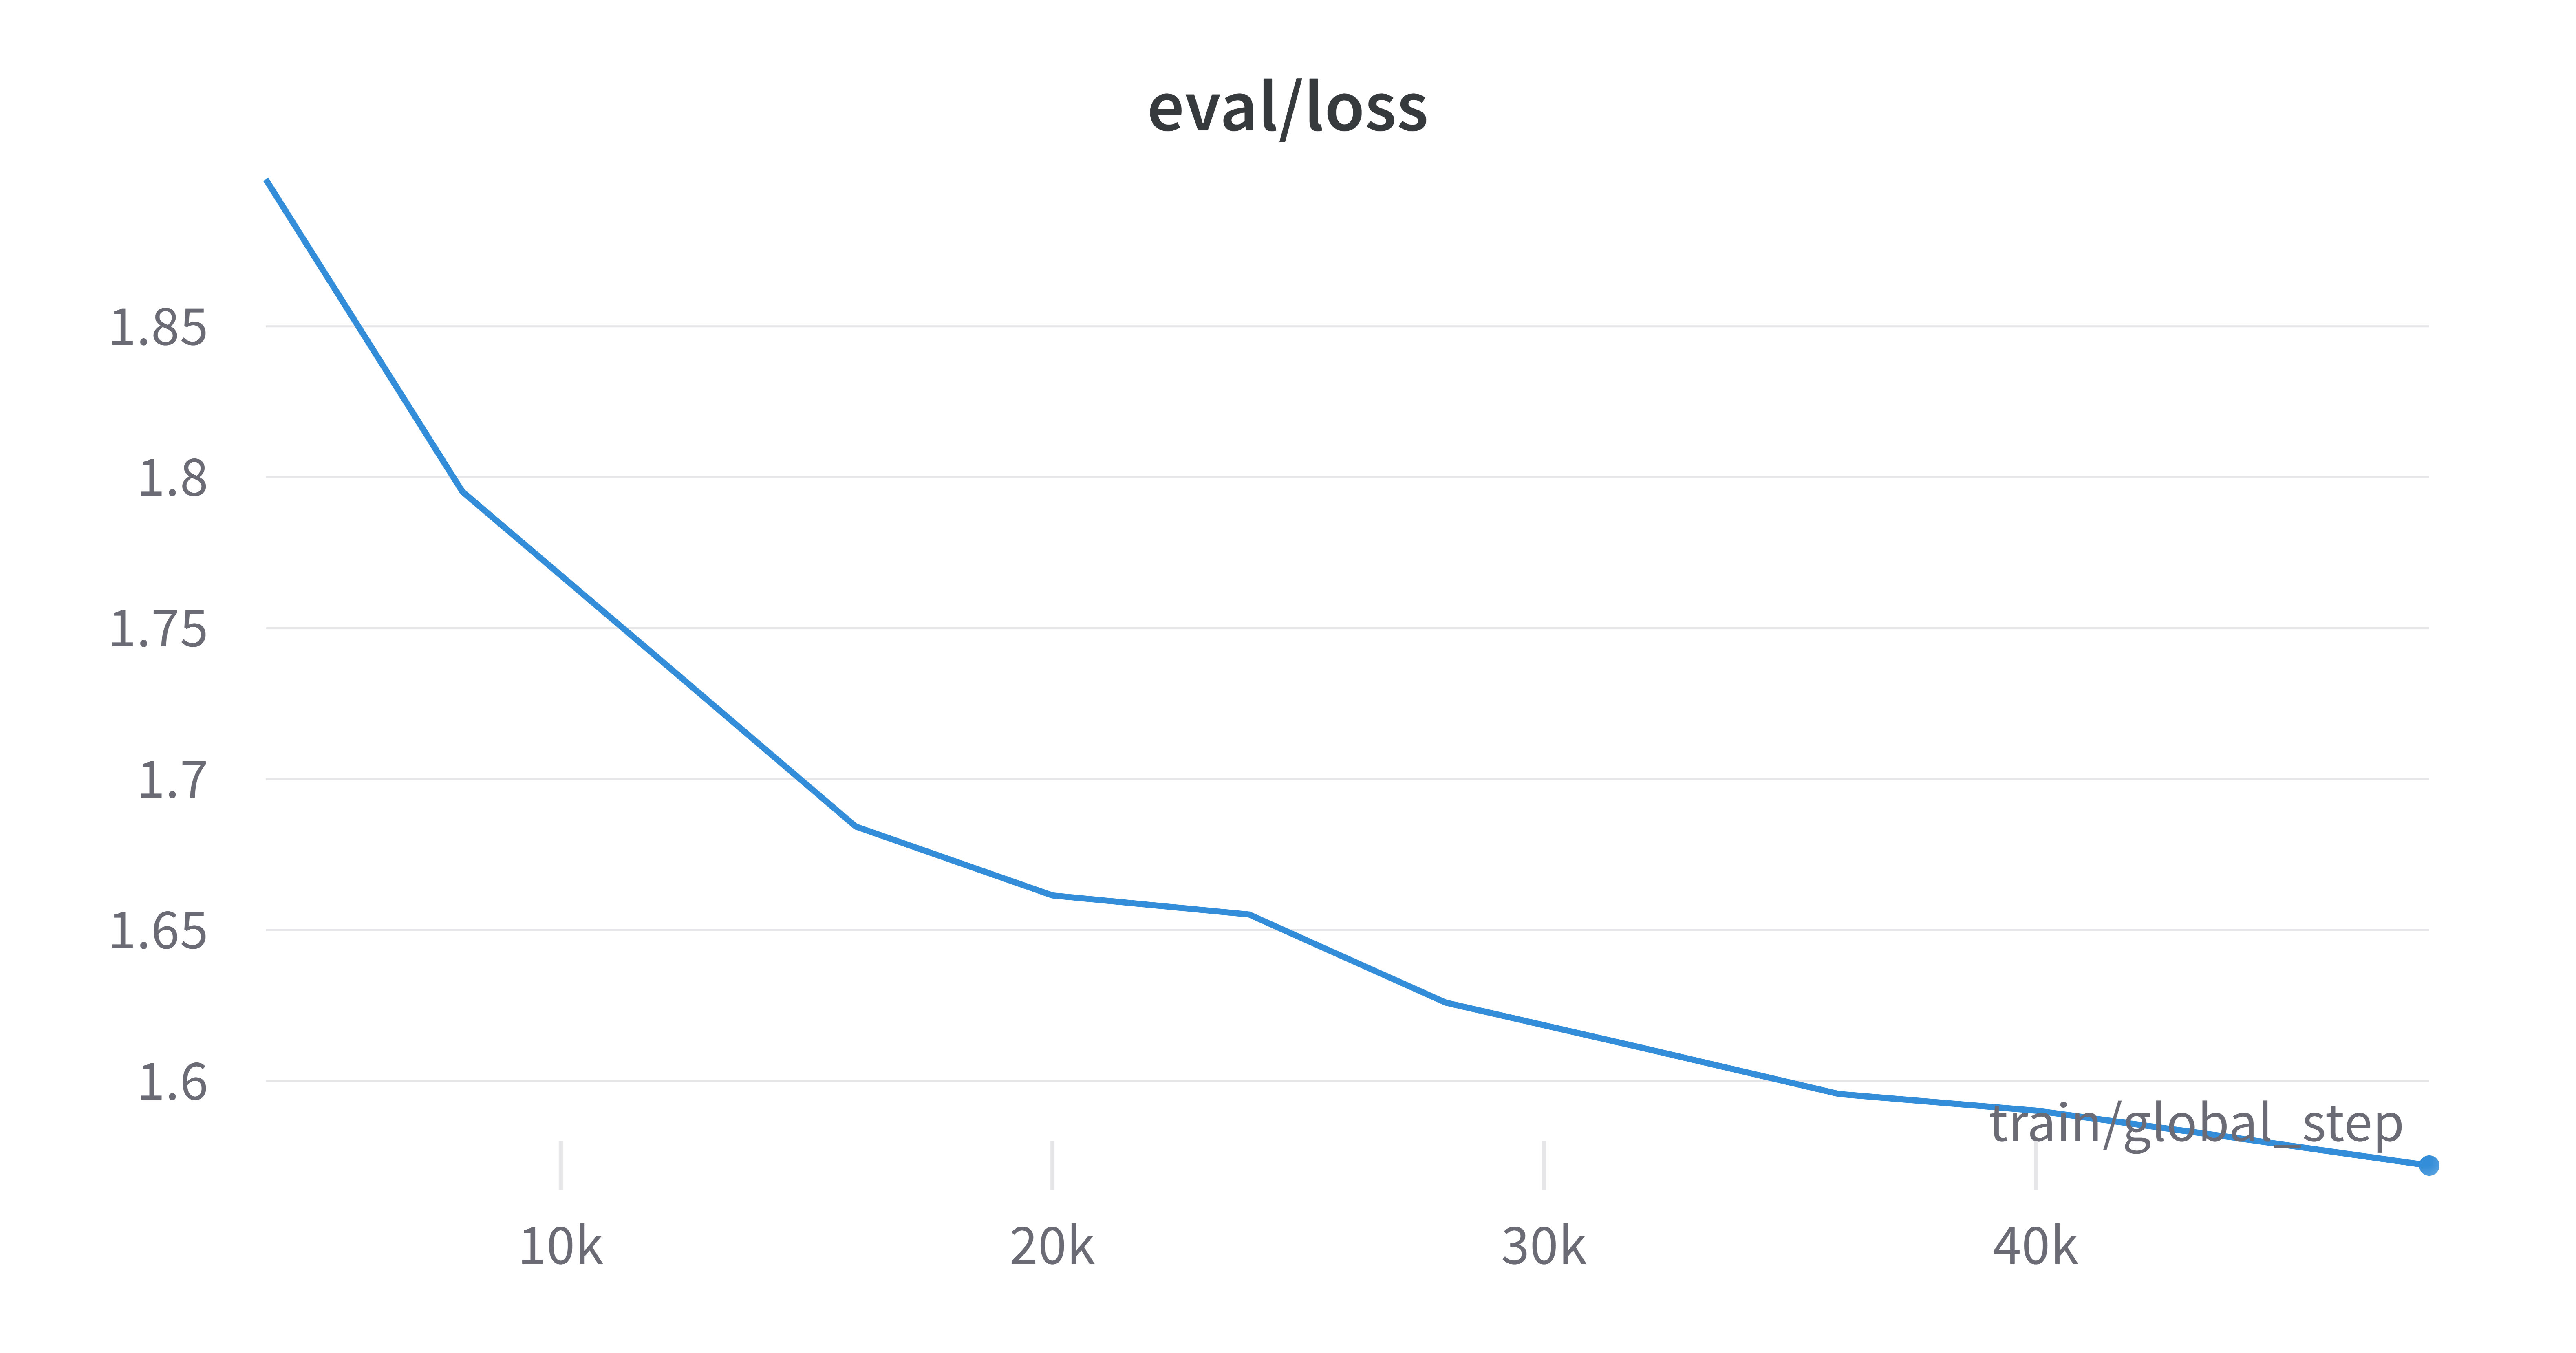
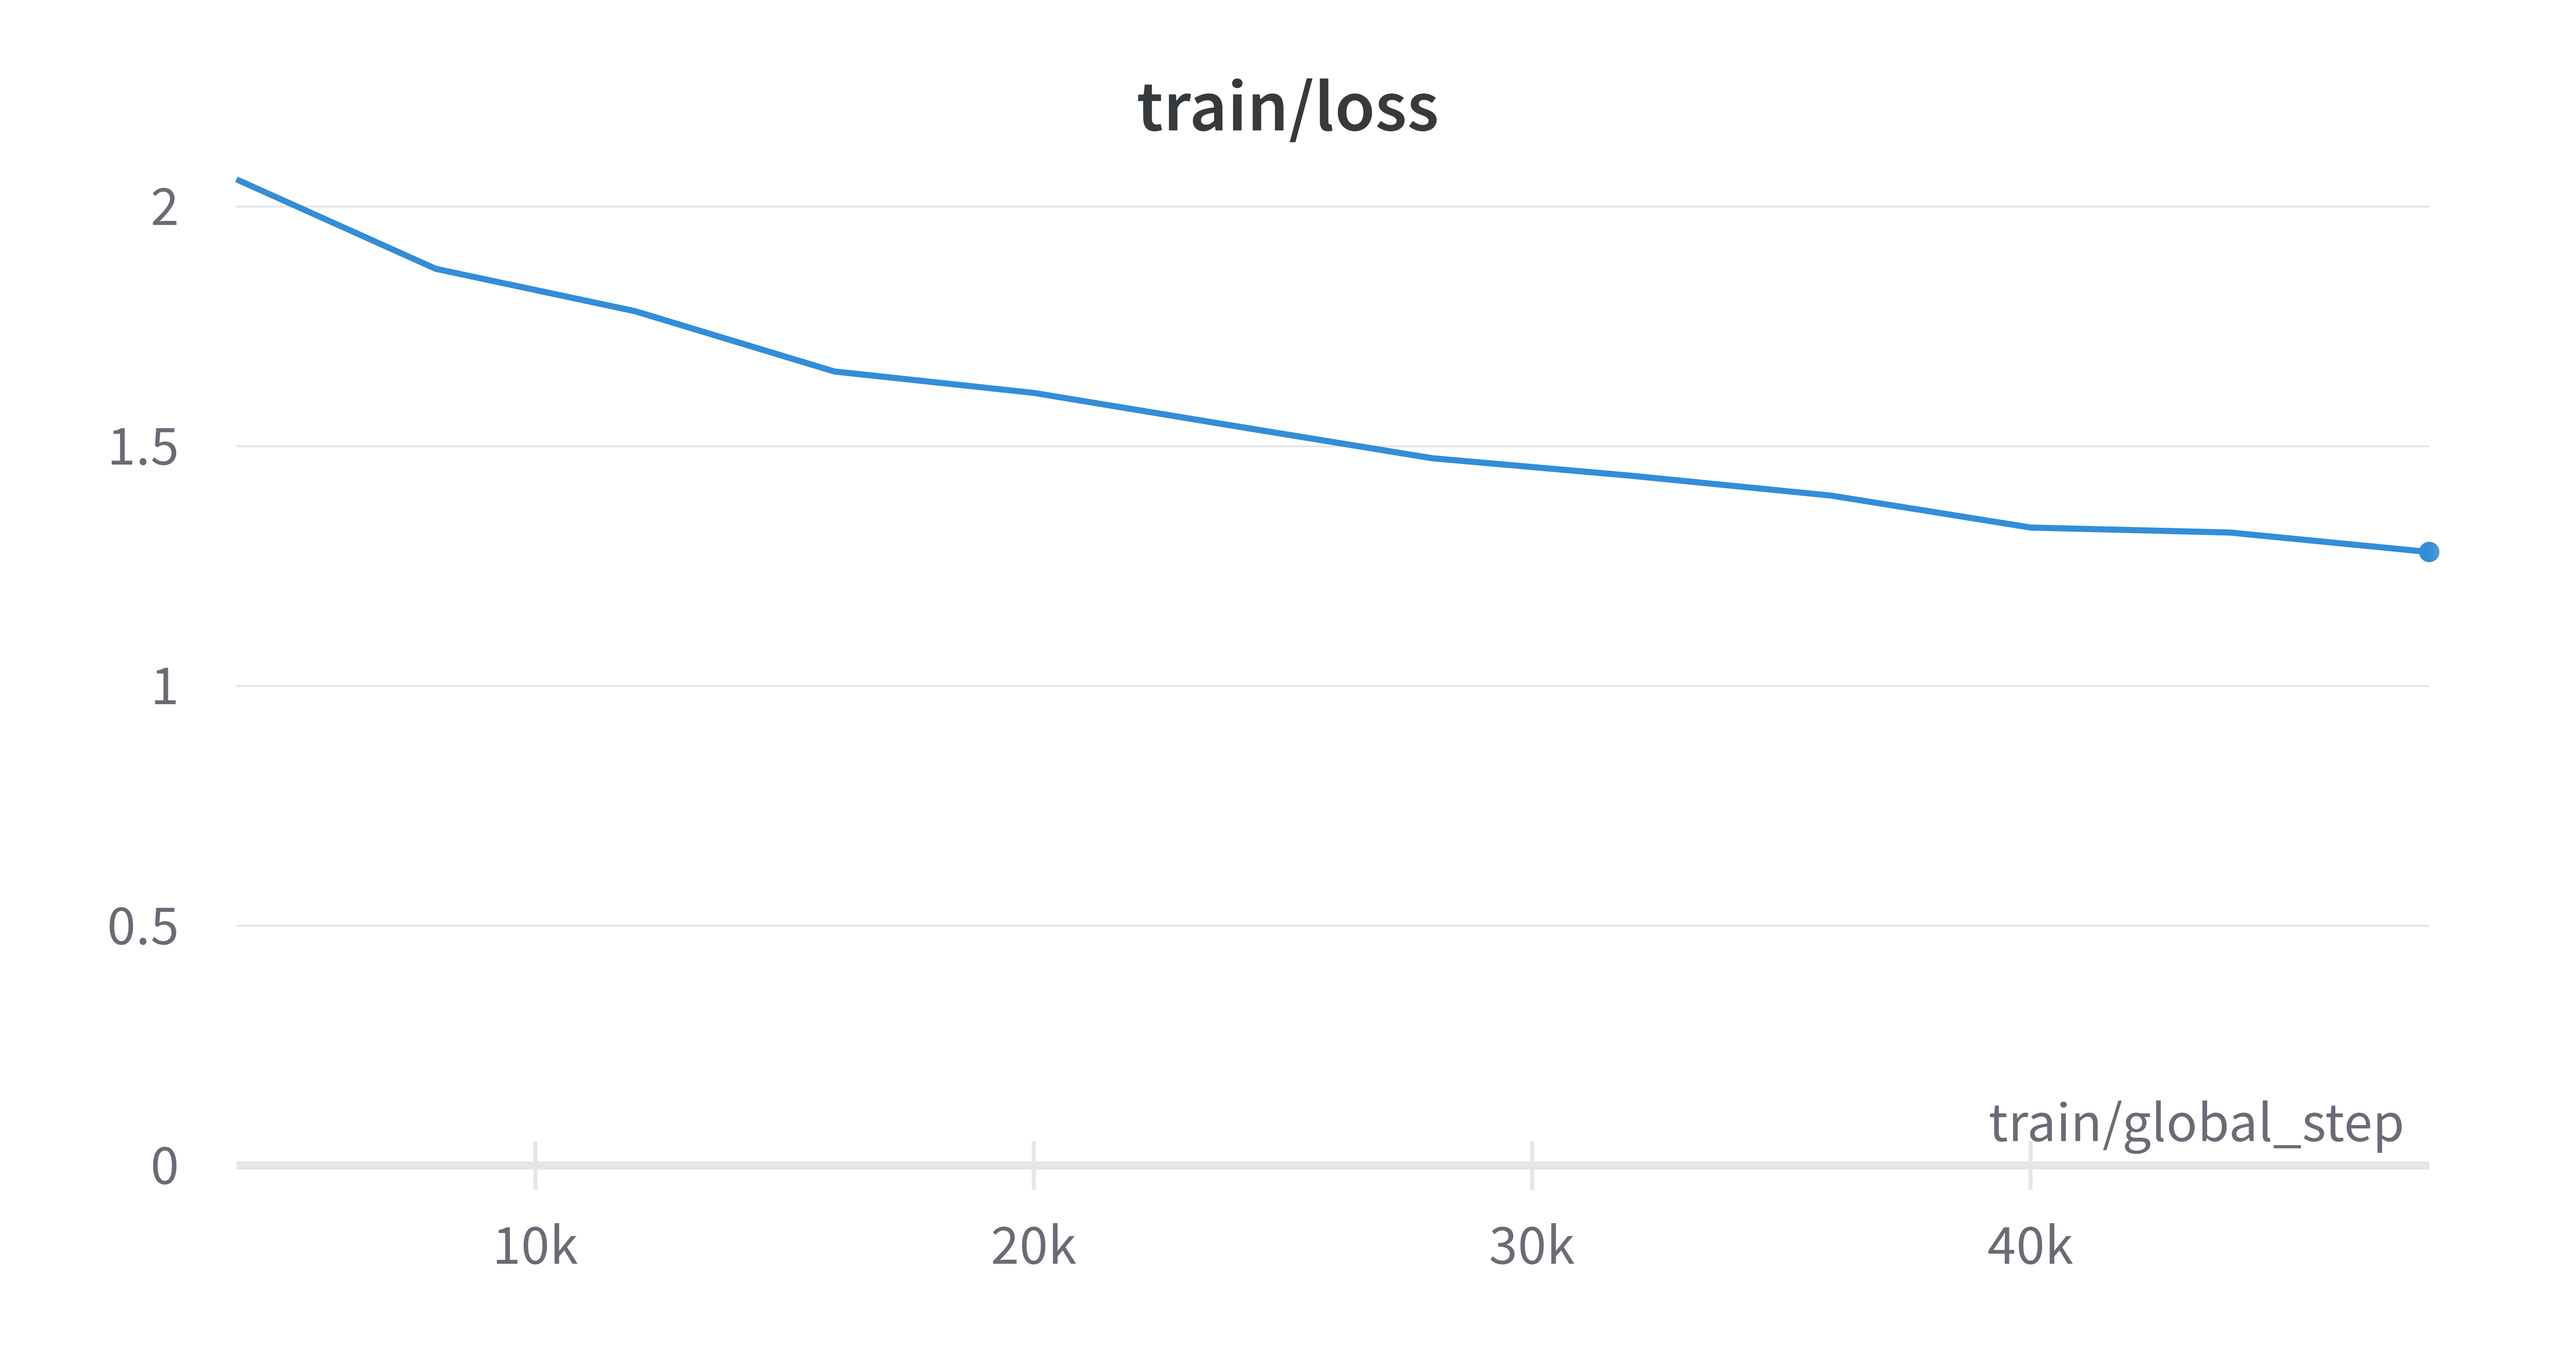 Image by Author: validation and training loss
Upon examining the loss charts, it seems that the models have yet to converge, despite the training session lasting approximately nine hours.
This might not be surprising considering the substantial model size and limited infrastructure at our disposal, alongside the fact that many of the training parameter decisions were made to prioritise memory preservation over training speed.
The model's precision, recall, and F1 show that it's prbably not ready for full production usage.
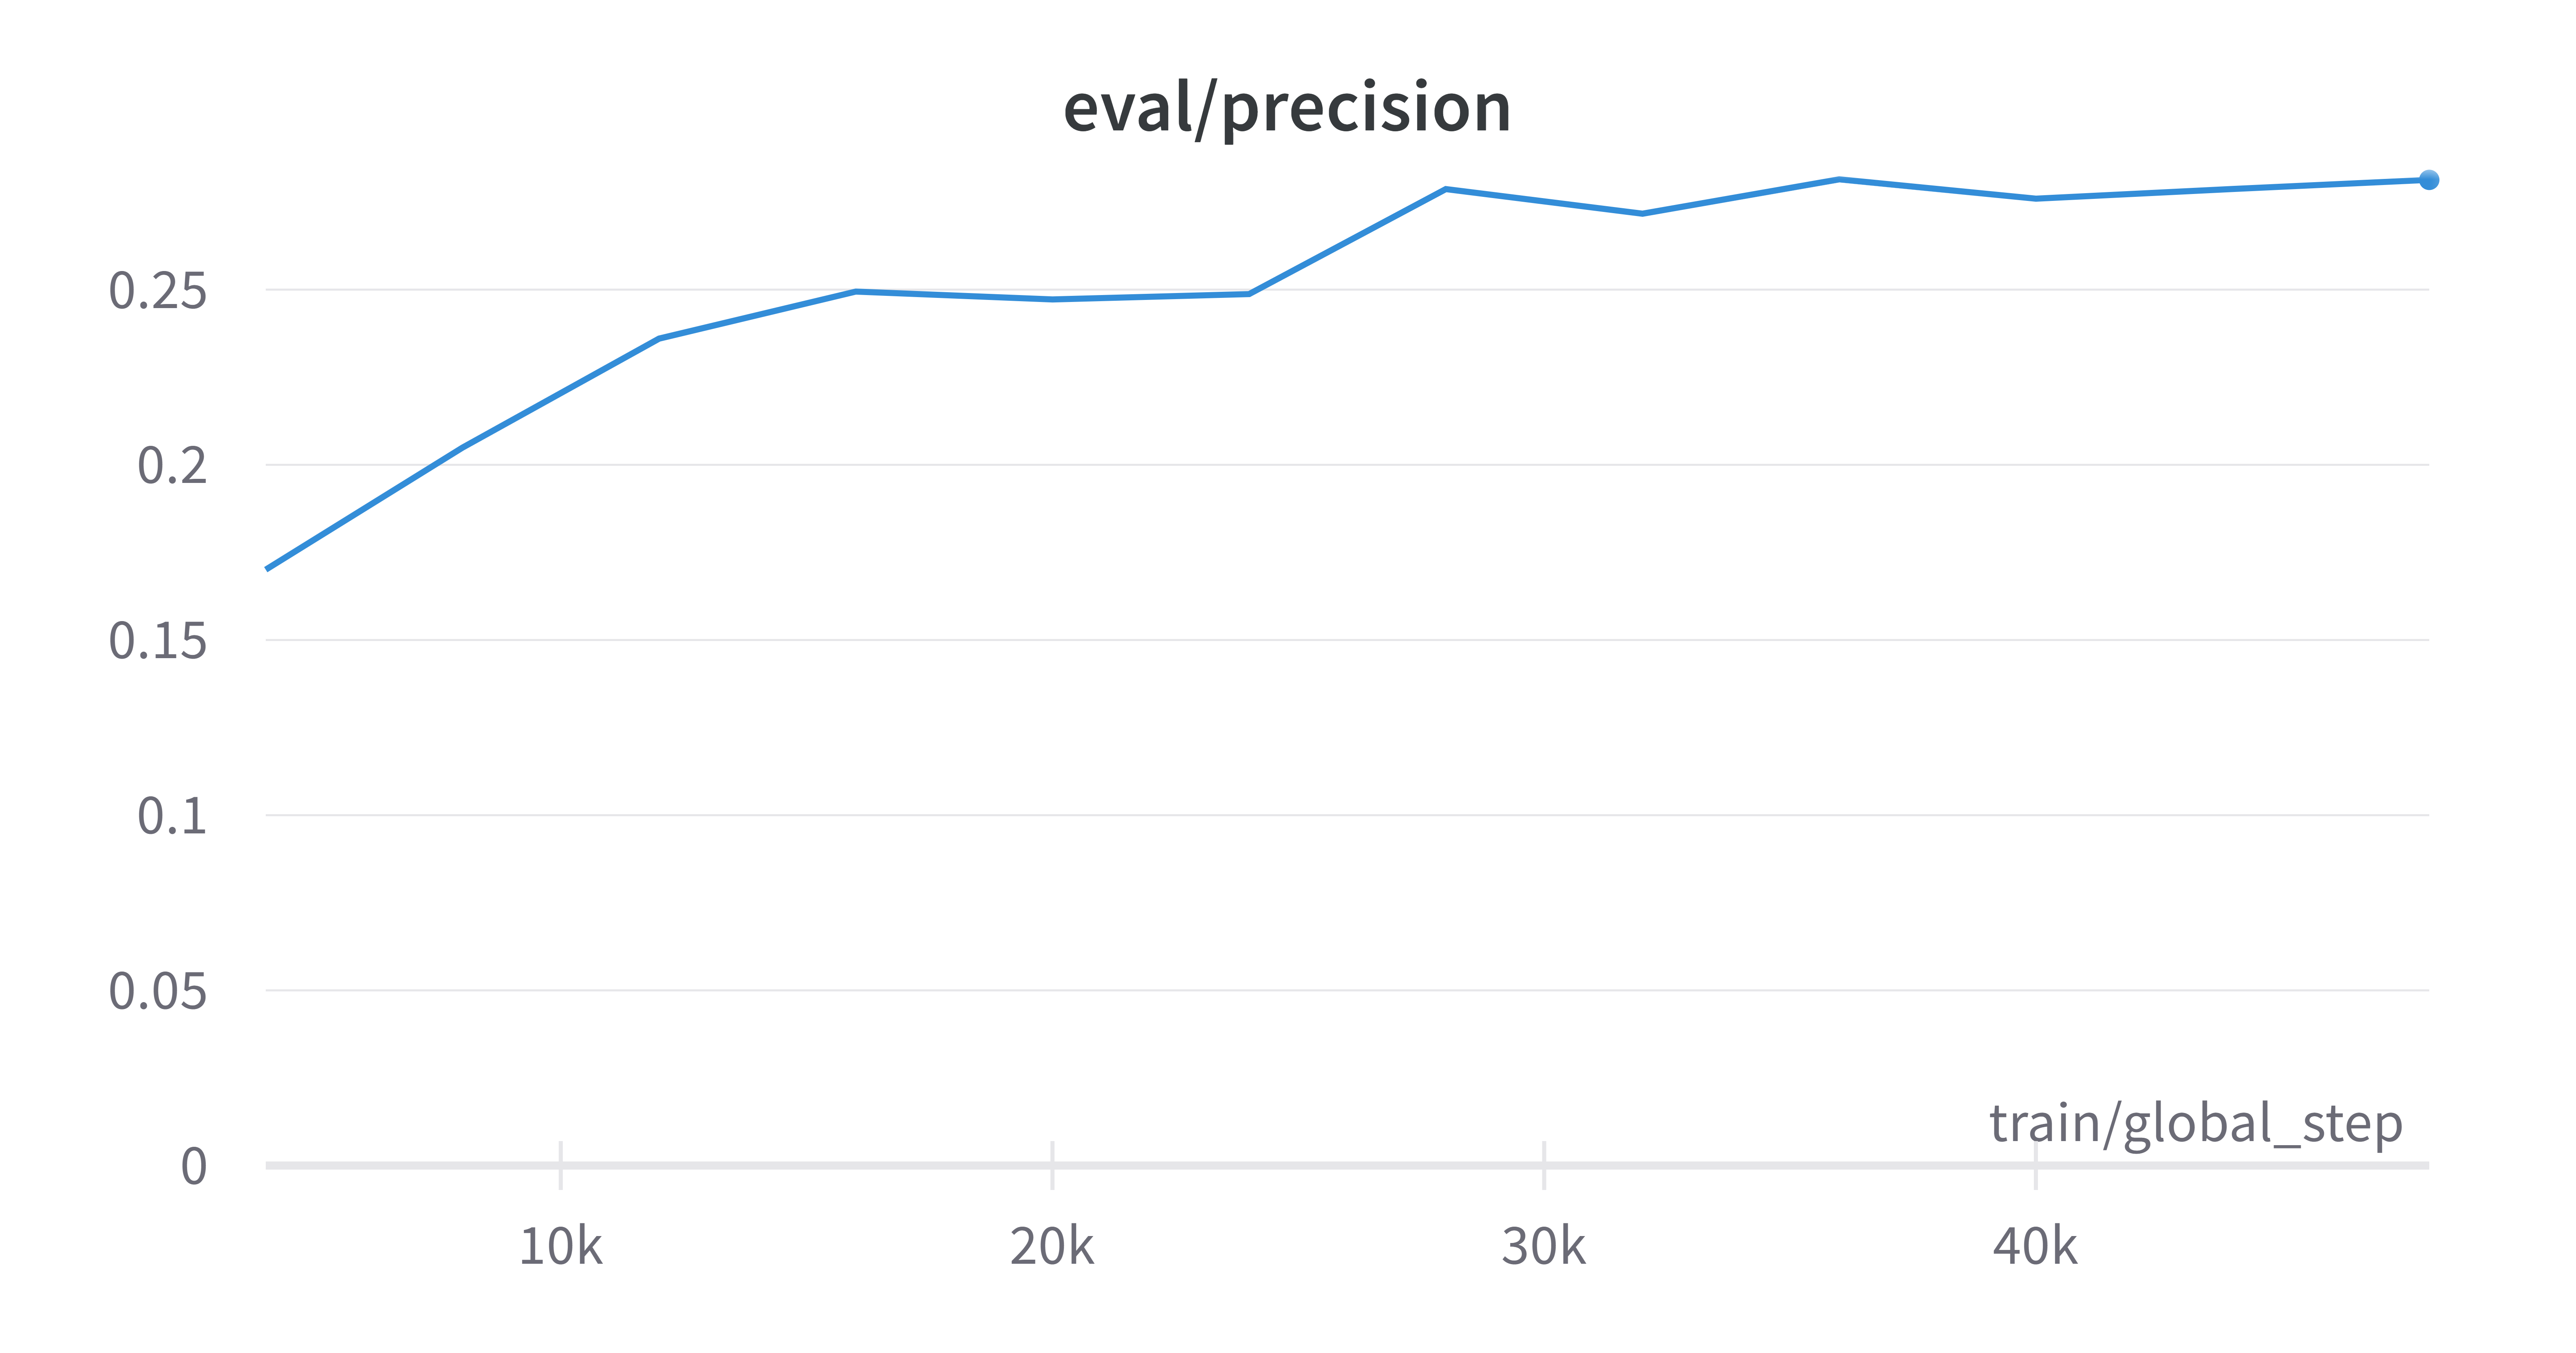
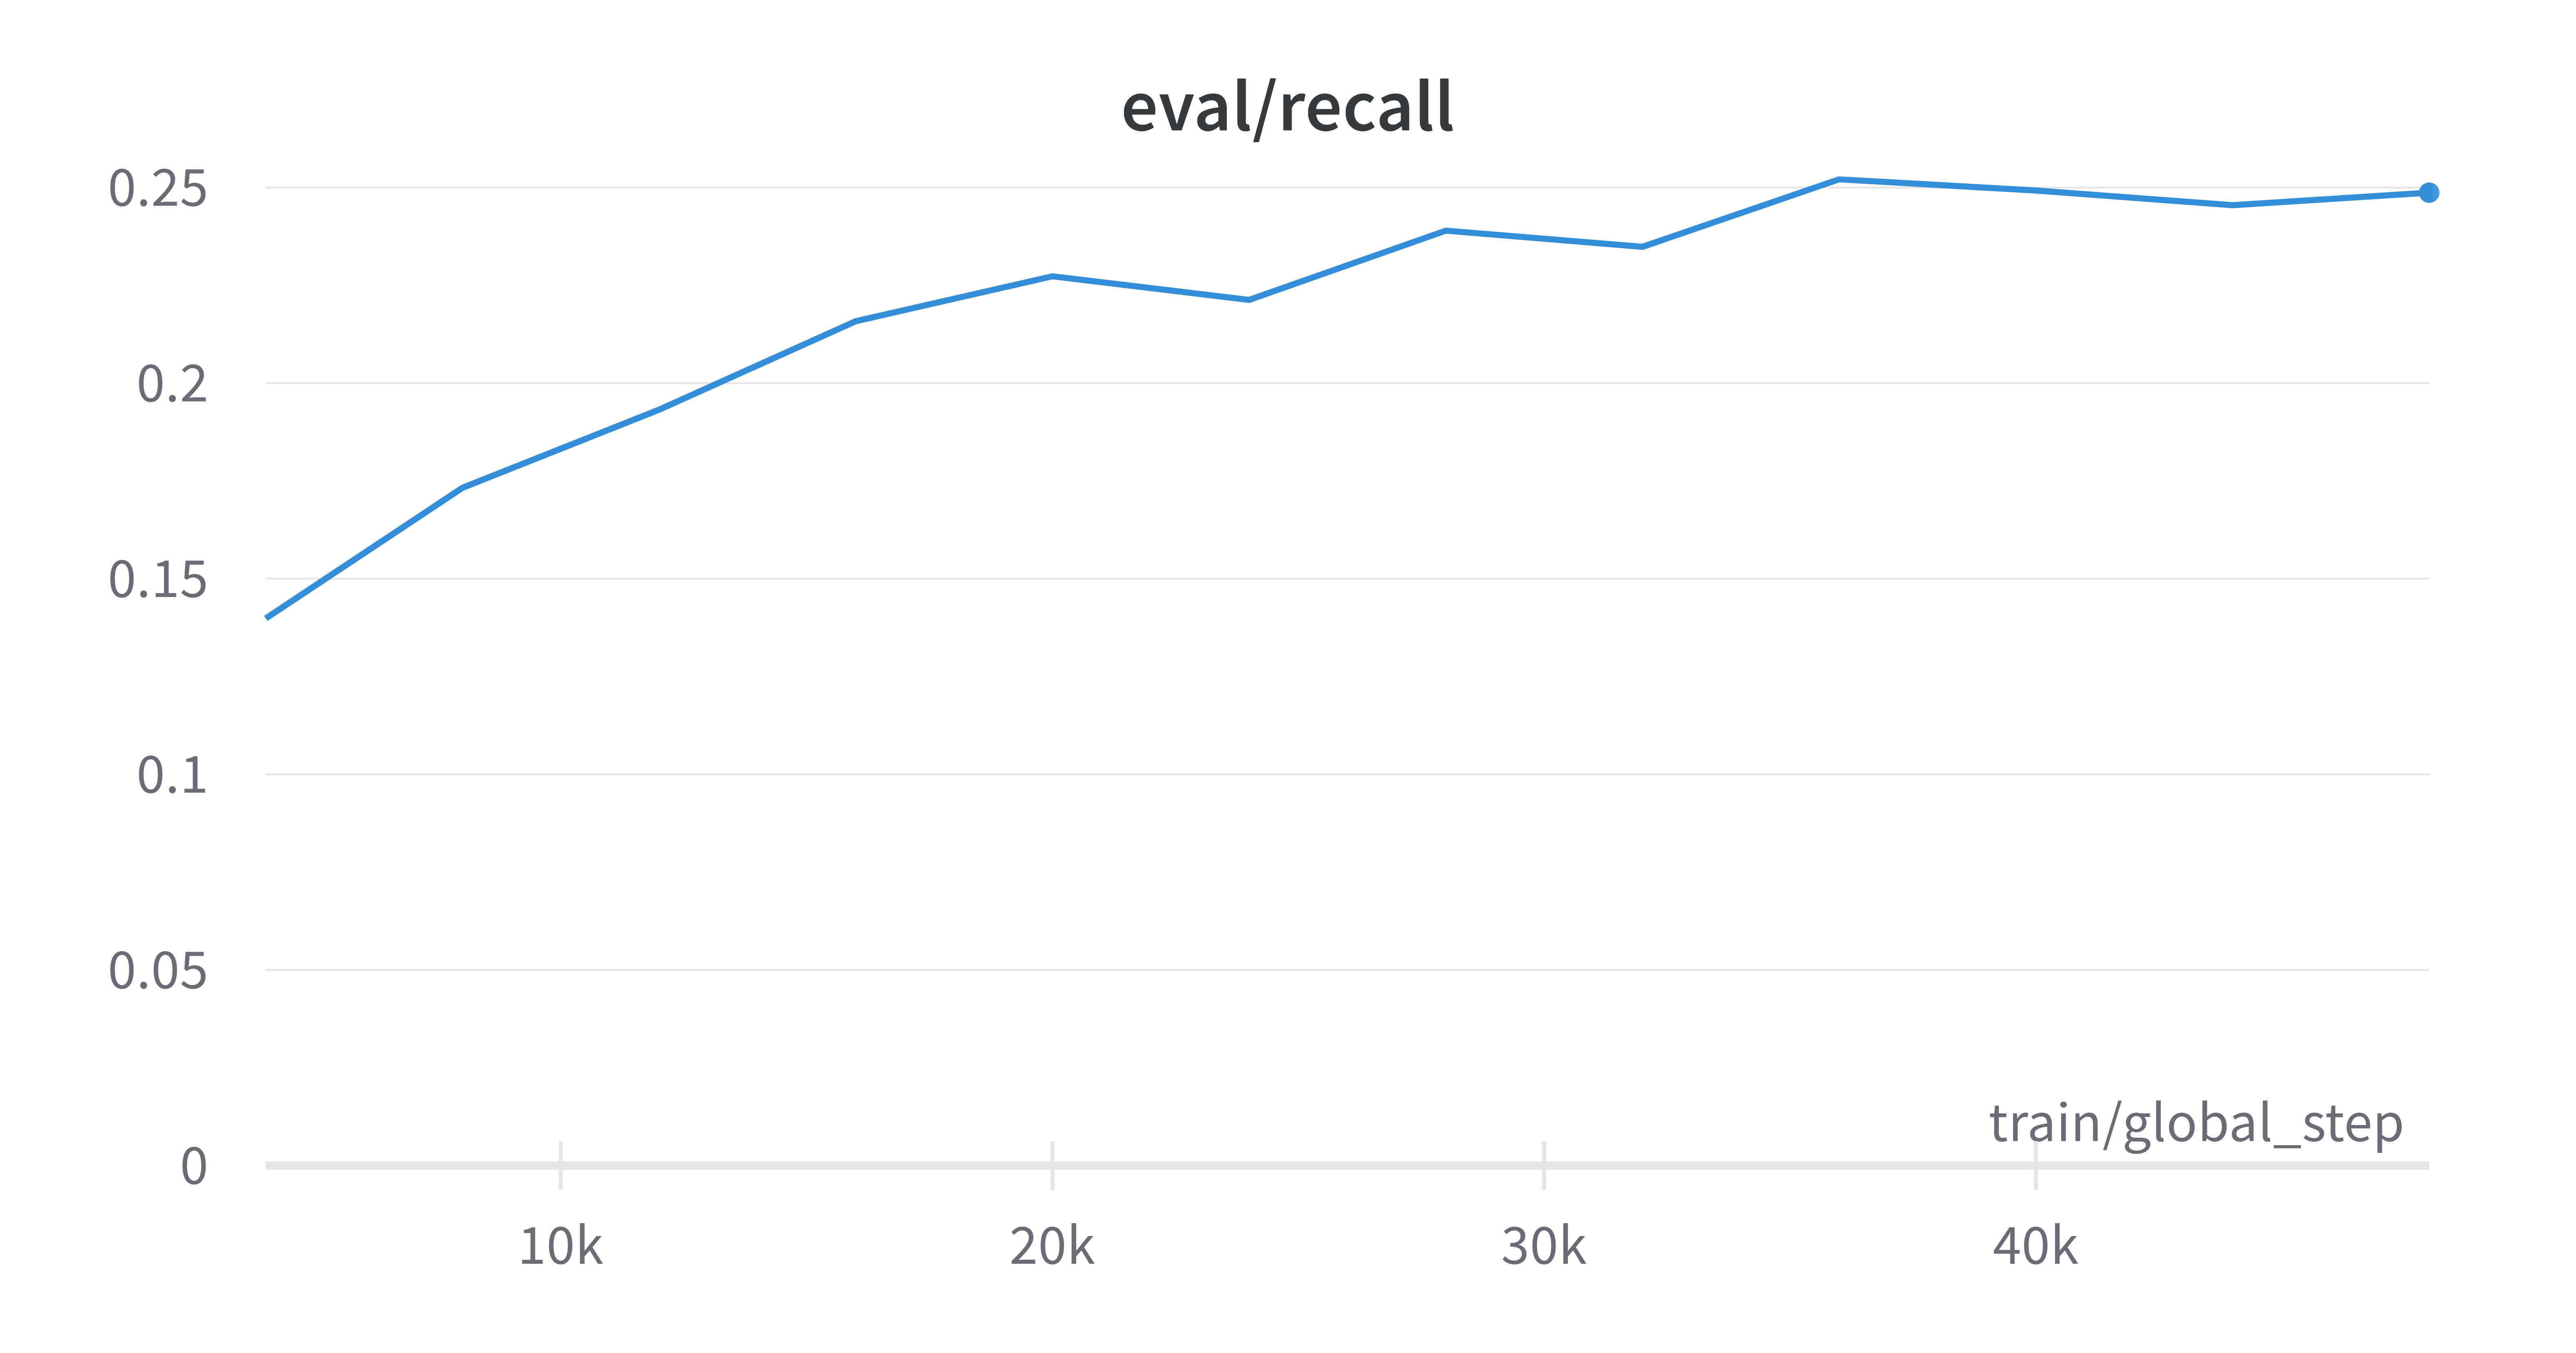 image by Author: Precision and recall tracking for the model
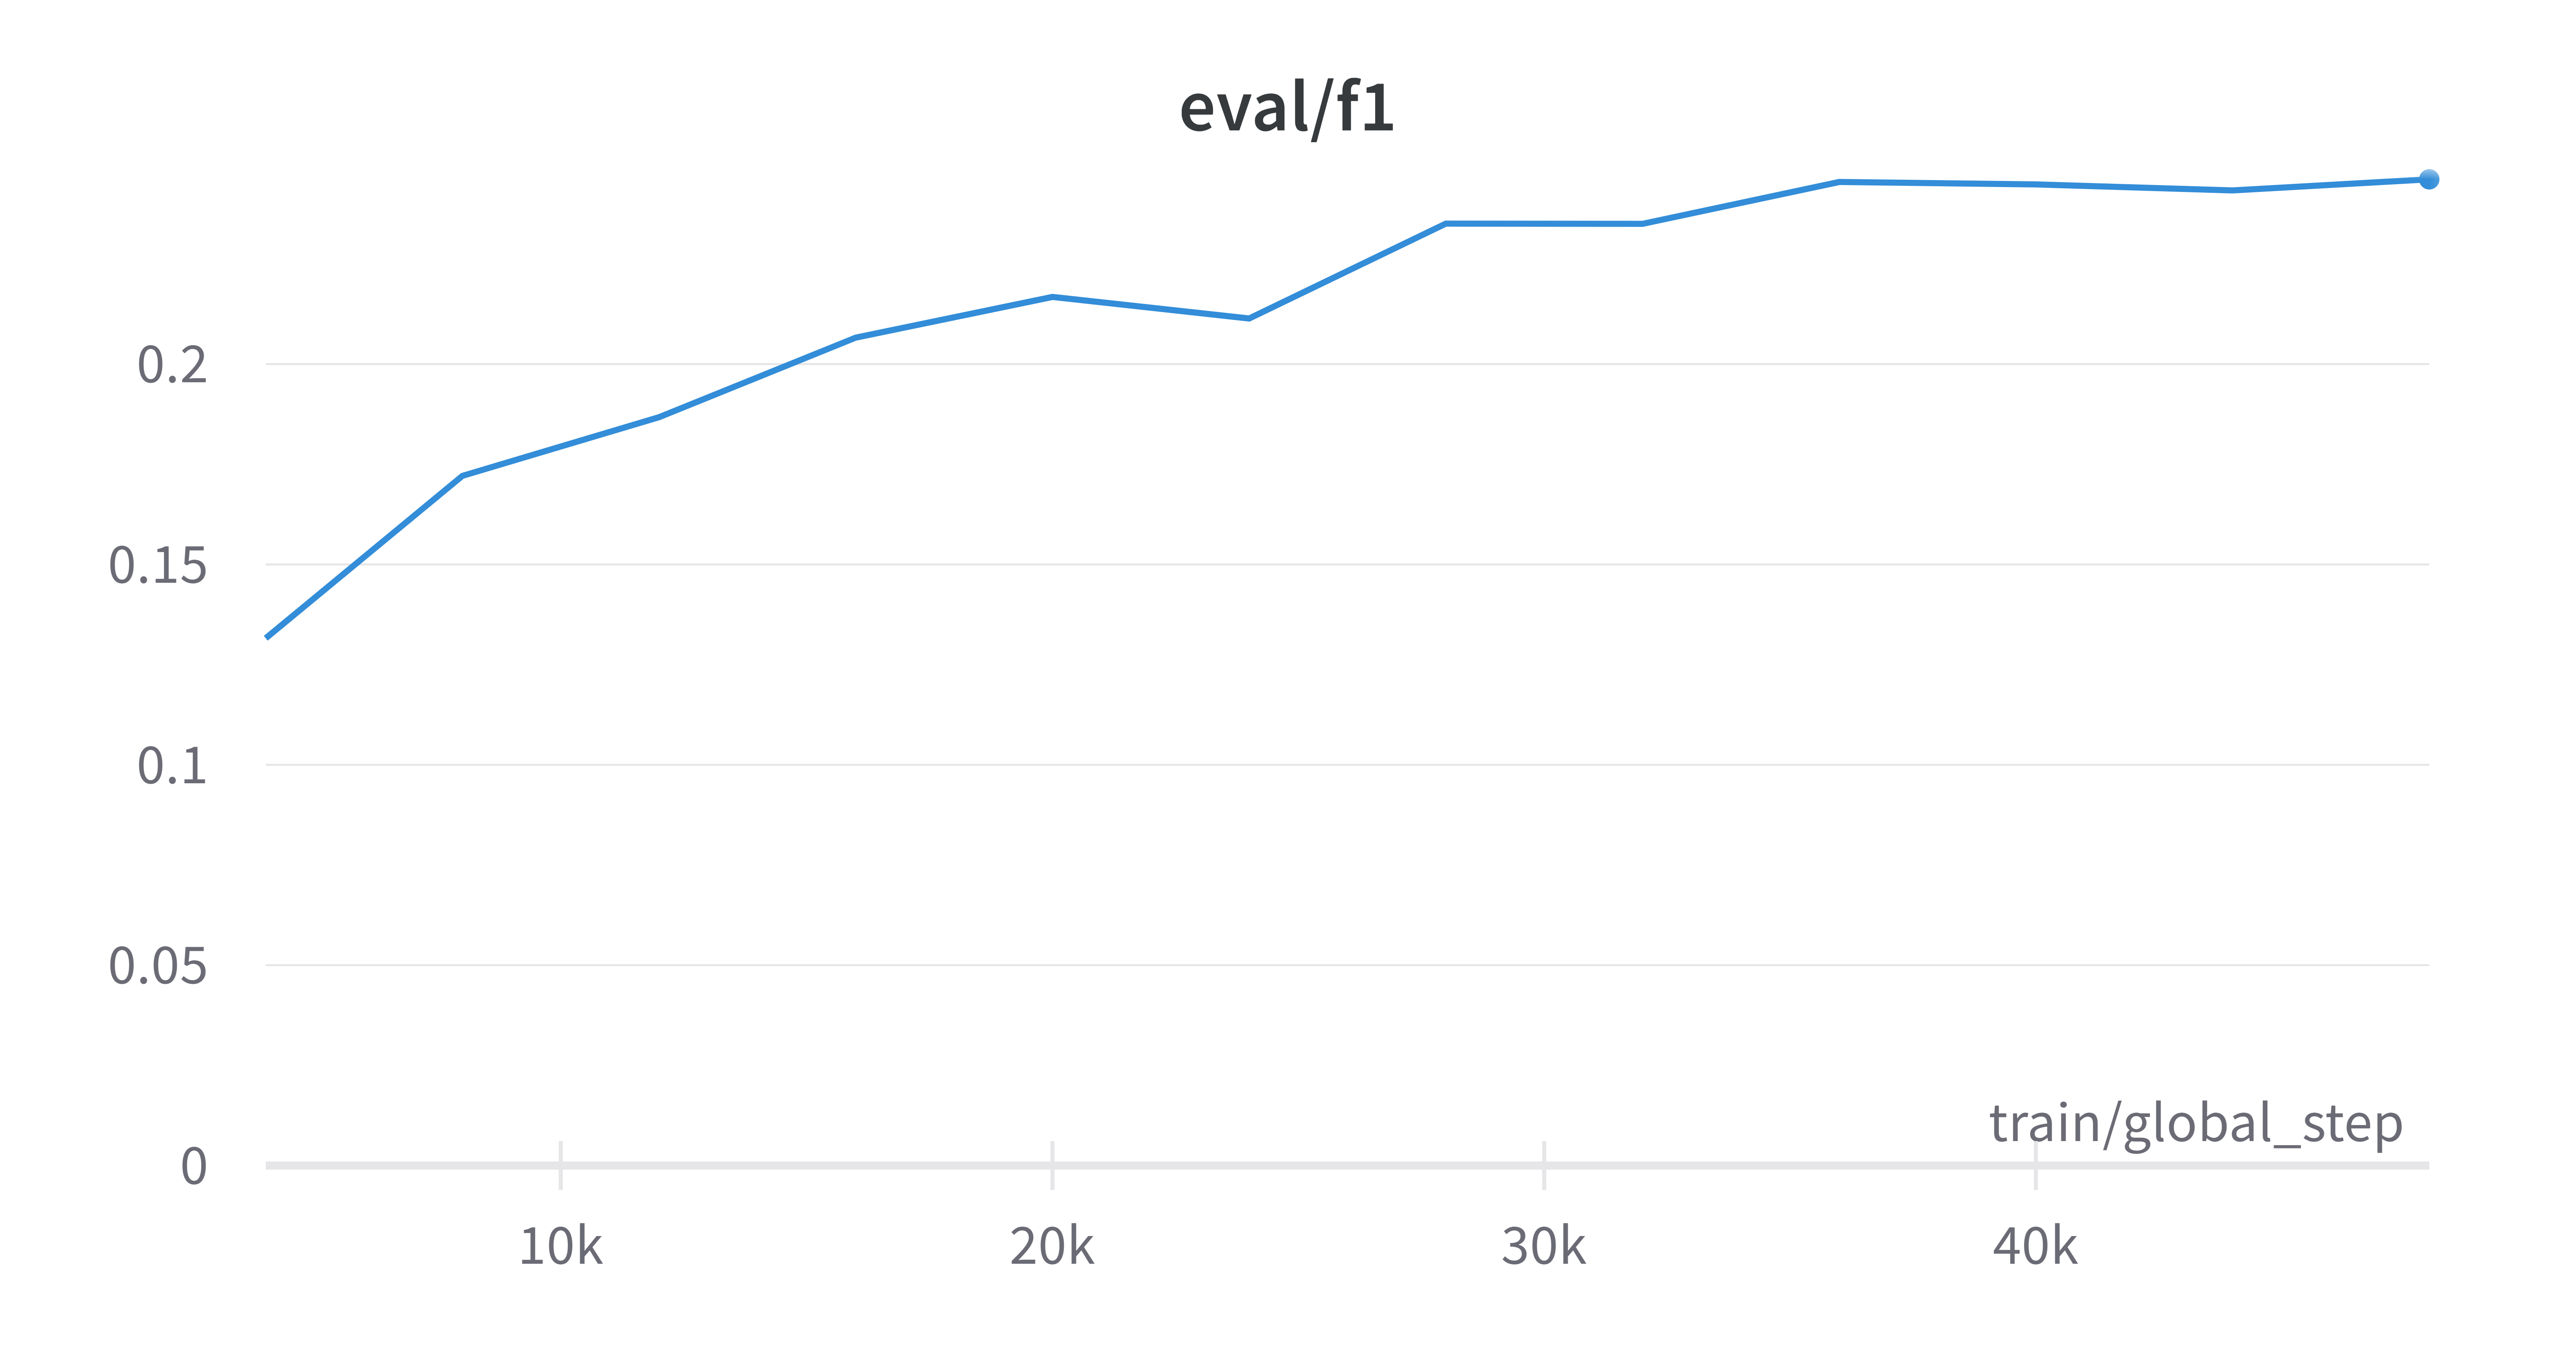 Image by Author: F1 tracking for the model
Cost
Google levies charges for renting GPUs via Colab based on compute units. Consequently, to calculate the cost of training the model for nine hours, we need to ascertain the number of compute units utilised. I was unable to locate explicit details from Google on their computation of these units, but it is suggested that a compute unit is determined as follows:
1 GB memory x 1 hour = 1 compute unit
The model was trained for approximately nine hours and utilised around 15 GB of RAM. Therefore, the training run consumed roughly 135 compute units. With a price of 9.99 USD per 100 compute units, the cost of training the model amounts to approximately 13.49 USD.
To achieve a usable state for the model, convergence may necessitate a slightly higher expenditure.
Conclusion
We have demonstrated that LoRA makes it possible for individuals with limited resources to engage in the world of LLMs. For interested readers, I recommend exploring other parameter efficient fine-tuning methods, as well as strategies for improving data efficiency in your training processes.
- The end-to-end Colab with the full model run is available here.
- I have hosted an app demonstrating the model Hugging Face for you to try for yourself.
- The full model diagnostics for the training run is available for you to review here.
- The Link to the model checkpoint is here.
- Watch a live tutorial on YouTube.
Thanks for reading.
If you're keen to enhance your skills in artificial intelligence, join the waiting list for my course, where I will guide you through the process of developing large language model powered applications.
If you're seeking AI-transformation for your business, book a discovery call today.
Brainqub3 | AI software development
For more insights on artificial intelligence, data science, and large language models you can subscribe to the YouTube channel.
Citations
[1] Conneau, A., Khandelwal, K., Goyal, N., Chaudhary, V., Wenzek, G., Guzmán, F., Grave, E., Ott, M., Zettlemoyer, L., & Stoyanov, V. (2019). Unsupervised cross-lingual representation learning at scale. CoRR. Retrieved from http://arxiv.org/abs/1911.02116
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
See all from John Adeojo
Artificial IntelligenceData ScienceDeep LearningLarge Language ModelsMachine Learning
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Programming
Securely connect multiple Databricks workspaces to 1 central ADLSgen2 account
René Bremer
May 1, 20214 min read
Data Science
Save yourself from future headaches by using Python virtual environments
David Bruce
March 12, 20214 min read
Data Science
A framework for deconstructing Data Journalism knowledge into several main silos and projecting its practice into a three dimensional...
Dror Kessler
April 6, 202111 min read
Deep Learning
No code, maths, or mention of Keys, Queries and Values
Chris Hughes
October 9, 202315 min read
Data Science
As I start my new journey as a career Data Scientist, I had to cross paths with my old hypothetical nemesis: The Monty Hall Problem. To...
Andrew Mooney
December 17, 20208 min read
Data Science
Interactive Visualizations of the PMF/CDF & Modeling Real Data
Kate Wall
February 21, 20225 min read
Machine Learning
Composite Estimators and Transformers
Amal Hasni
January 5, 20212 min read
Programming
Understand how and when to use ElasticSearch in systems, with three practical system design examples.
Sanil Khurana
November 28, 202314 min read
Deep Learning
A demo using Label Studio segmentation mask capabilities to develop a benchmark dataset for model viability testing.
Aaron Soellinger
April 21, 202110 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close