The Simple Bug That Started a Bigger Conversation: PATCH, Null Handling, and Engineering Judgment

I write technical articles that analyze real world engineering problems through the lens of production systems.
My work focuses on architectural tradeoffs, UI layer system design, performance optimization, and reliability patterns derived from shipping and maintaining scalable applications.
Sometimes discovering what you don’t need to build is more valuable than what you do.
This week, while testing a small form update before pushing to production, I discovered something that would have silently corrupted user data. A user clears their email field, hits save, refreshes the page, and the old email is still there. No error. No warning. Just wrong.
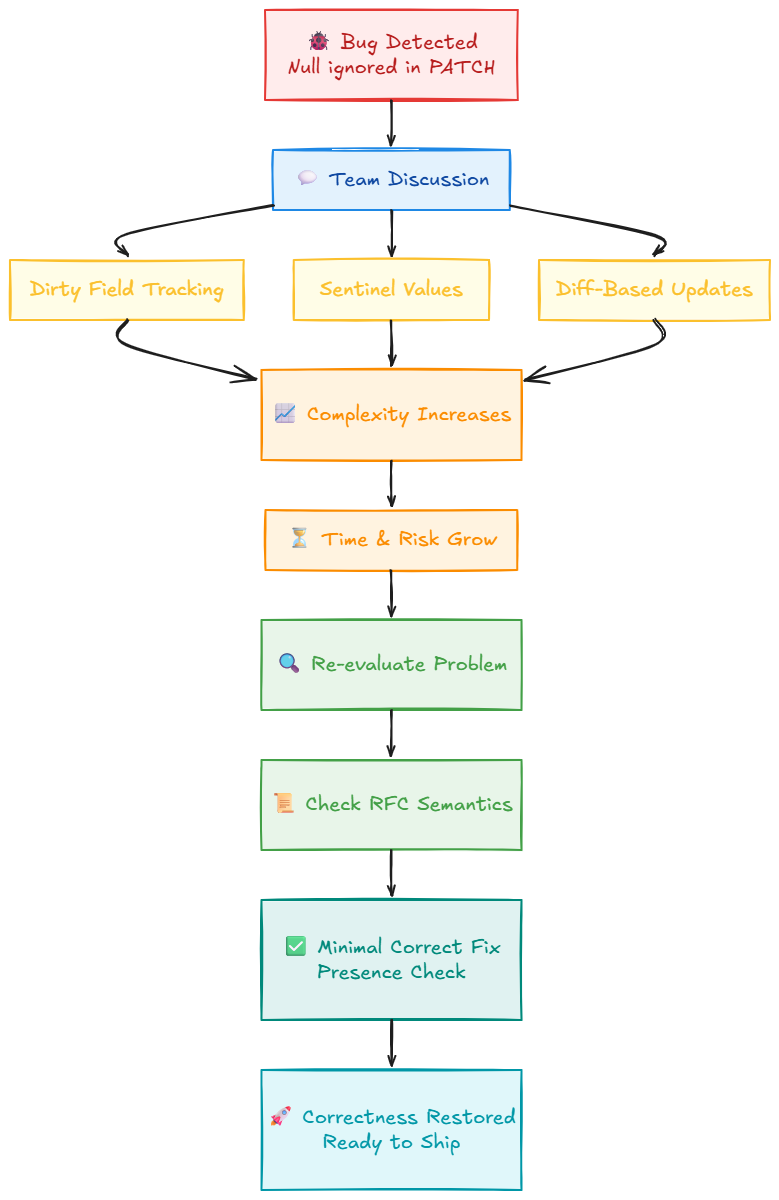
This article isn’t about that bug specifically. It’s about what happened next: a technical discussion that almost derailed a simple fix, and what it revealed about how we think about API design, best practices, and engineering tradeoffs.
The Bug: Silent Field Persistence
The issue was straightforward:
Expected behavior:
User clears any optional field (email, phone, address, or any nullable attribute across the system) → field removed from database
Actual behavior:
User clears field → old value persists silently
From the browser network tab:
PATCH /api/candidates/123
{
  "email": null,
  "contactNumber": null
}
Response: 200 OK
Database: Values unchanged
This is the dangerous kind of bug, no stack trace, no error boundary, just incorrect state. Users think they’ve removed their information, but it’s still there.
The Root Cause: A Common Pattern
The backend update handler looked like this:
function updateCandidate(id, payload) {
  const updates = {};

  for (const [key, value] of Object.entries(payload)) {
    if (value) {  // ← The issue
      updates[key] = value;
    }
  }

  return db.update('candidates', id, updates);
}
The if (value) check seems reasonable, it's defensive programming, preventing accidental overwrites with empty values.
But in JavaScript, null is falsy. So if (null) evaluates to false, the field never enters the updates object, and the database never sees the change.
This pattern appears everywhere. It reads cleanly, feels safe, and breaks silently. This bug turned out to be one instance of a broader class of failures: implementation patterns that feel defensive but subtly violate protocol semantics.
The Discussion That Followed
When I raised this issue, the conversation naturally expanded beyond the immediate fix:
“Should we implement dirty field tracking?”
“We need to send only changed fields.”
“Doesn’t this violate PATCH best practices?”
“What about using a sentinel value like CLEAR?”
These were valid suggestions, each addressing real concerns about API design, performance, and maintainability. Within minutes, we’d gone from a clear bug to a broader discussion about state management, API contracts, and optimization strategies.
The suggestions had technical merit. But as the conversation unfolded, I realized we were solving a different problem than the one we had.
The Question That Mattered
What should have been asked immediately:
“What is actually broken, and what’s the smallest fix?”
Let me be precise about what our production problems were NOT:
Payload size (requests ~2KB, traffic ~2,000/day)
Bandwidth costs (would save ~$4/year optimizing)
Network latency
Race conditions
Unclear user intent
What our actual problem WAS:
Backend ignores null in PATCH payloads
Users cannot clear optional fields
Silent data integrity issue
That’s it. Everything else was theoretical optimization.
PATCH Semantics: What the Specs Say
RFC 7396 (JSON Merge Patch) is explicit:
{
  "email": null
}
This is valid. The server MUST interpret it as “set this field to null”, not “ignore this field.”
The RFC defines three cases:
Field present with value → Update to that value
Field present with null → Clear the field
Field absent → Leave unchanged
Any implementation that doesn’t handle all three has a semantic bug.
Here’s what the RFC does NOT say:
“Clients must compute diffs”
“Sending unchanged fields is invalid”
“Dirty tracking is required”
“Only send modified fields”
Sending the full object in a PATCH is less optimal but not incorrect. The protocol supports it. Many production systems rely on it.
Real-World Examples: How Production APIs Actually Work
GitHub API
GitHub’s PATCH endpoints accept full payloads and their documentation shows examples sending complete objects including unchanged fields like name, description, homepage, private, has_issues, has_projects, and has_wiki together in single requests. Many official SDKs and community clients send complete objects even when only one field changes. GitHub’s backend processes whatever fields are present.
Stripe API
Stripe’s update customer endpoint states: “Any parameters not provided will be left unchanged,” which means you can send partial or complete objects. Their webhook update endpoints explicitly support clearing metadata. Individual keys can be unset by posting an empty value to them, and all keys can be unset by posting an empty value to metadata. This uses null or empty values as clear signals without requiring clients to compute diffs.
Salesforce API
Salesforce’s REST API uses PATCH for updates: “Provide the updated record information in your request data and use the PATCH method of the resource with a specific record ID”. Their implementation doesn’t mandate minimal payloads. It processes the fields you send.
These are high-stakes, production systems handling millions of requests daily. They all:
Accept PATCH with full or partial payloads
Process fields based on presence, not minimization
Handle null correctly as a clear instruction
Don’t require client-side dirty tracking
The common pattern: server-side logic determines semantics, client-side optimization is optional.
Why Dirty Tracking Doesn’t Fix This
Dirty field tracking is useful for:
UX improvements:
Disable “Save” when nothing changed
Show “unsaved changes” warnings
Highlight modified fields
Performance optimizations:
Reduce large payload sizes
Skip expensive validations
Minimize database writes
Correctness in specific scenarios:
Concurrent editing conflict detection
Explicit intent signaling
These are valuable. But notice what’s missing:
“Making null handling work”
Dirty tracking changes what you send. It doesn’t change how the backend processes what it receives. You can implement perfect dirty tracking and still have this exact bug if the backend ignores null.
The Premature Optimization Trap
Implementing dirty tracking would require:
Frontend:
Snapshot original state on load
Deep equality comparison on change
Handle reset/revert flows
Manage nested object diffing
Update TypeScript types
Testing:
Unit tests for diff logic
Integration tests for edge cases
Regression tests for resets
Performance tests for large forms
Documentation:
Why it exists
How to use correctly
Edge cases and limitations
Migration guide
Estimated timeline: 2–3 weeks
Estimated benefit at our scale: ~300MB bandwidth/year ($0.30), slightly better UX
Meanwhile, users still can’t clear their email.
This is how technical debt gets created in the name of “doing it right.” Every abstraction has a carrying cost. Every optimization has an opportunity cost.
The Idempotency Insight
Here’s something that emerged from thinking about the bug more deeply:
With buggy null handling, our endpoint wasn’t truly idempotent. Send this once:
PATCH /api/candidates/123
{ "email": null }
First call: Email unchanged (bug ignores null)
Second call: Email unchanged (still ignored)
Appears idempotent, but for the wrong reason: the implementation masked the violation.
After fixing:
First call: Email cleared
Second call: Email still null (correctly idempotent)
If you have retry logic, circuit breakers, or message queues that replay requests, the buggy and fixed versions have different semantics. The bug was hiding a deeper architectural property.
This is why correctness precedes optimization. Optimizations are incremental improvements. Correctness violations compound through the system.
The Sentinel Value Anti-Pattern
One suggestion was using magic strings:
{
  "email": "__CLEAR__"
}
This seems pragmatic. It avoids null handling, makes intent explicit, and works immediately.
It’s also wrong:
Type system violation:
interface Candidate {
  email: string | null;  // Type says: string or null
}
// But now this is valid?
const payload = { email: "__CLEAR__" };  // Actually a command
Our types lie. Every consumer needs special knowledge.
Leaky abstraction:
The backend’s limitation now leaks into frontend code, API docs, mobile apps, third-party integrations. Everyone must know: “Don’t send null. Send this magic string.”
Unclear semantics:
{
  "email": "__CLEAR__",
  "backup_email": ""
}
Maintenance burden:
Now you need constants, validation, documentation, migration paths, and special handling in logs and analytics, all to avoid writing:
if (payload.hasOwnProperty(key)) {
  updates[key] = payload[key];
}
If the protocol has a solution, use it. Inventing alternatives creates debt disguised as pragmatism.
The Actual Fix (What We’re Doing)
Backend (5 minutes):
function updateCandidate(id, payload) {
  const updates = {};

  for (const [key, value] of Object.entries(payload)) {
    if (payload.hasOwnProperty(key)) {  // Check presence
      updates[key] = value;  // Includes null
    }
  }

  return db.update('candidates', id, updates);
}
Frontend (2 minutes):
const payload = {
  email: form.email?.trim() || null,
  contactNumber: form.contactNumber?.trim() || null,
  address: form.address?.trim() || null
};
await api.patch(`/candidates/${id}`, payload);
Documentation (ongoing):
Update API docs to clarify null handling
Add examples showing field clearing
Document the contract explicitly
Total time: Half a day
Result: Bug fixed, contract clarified, ready to ship
We’re not implementing dirty tracking. We’re not minimizing payloads. We’re fixing what’s broken.
When Optimization Actually Matters
I’m not against dirty tracking or payload optimization. I’m against doing them now, for this problem, at our scale.
Dirty tracking makes sense when:
Forms have 50+ fields (ours: 12)
Validations are expensive (ours: <10ms)
Mobile data usage matters (we’re desktop-first)
You have data showing users abandon changes frequently
Payload optimization makes sense when:
Requests regularly exceed 100KB (ours: ~2KB)
Traffic exceeds 100K requests/day (ours: approx. 2–5K/day)
Bandwidth costs are measurable (we’d save $4/year)
Network latency is high
None of these are true for us. Building for them anyway is speculative engineering, solving hypothetical problems based on traffic we don’t have and costs we don’t pay.
This feels responsible, but it’s actually premature optimization dressed up as best practices. If those conditions change, such as higher traffic, mobile-first usage, or measurable performance degradation, optimization becomes the right move. The difference is sequencing: we’ll respond to evidence, not anticipation, with the confidence that we didn’t block delivery while waiting for problems that hadn’t materialized.
When We’ll Know We Chose Wrong
I’m watching for specific signals that would indicate the simple fix is no longer scaling:
p95 latency climbing above 200ms at 50K+ requests per day
User analytics showing more than 40% abandonment on form changes
The introduction of real-time collaboration exposing race conditions
The same category of contract violations (truthy checks, sentinel values, etc.) appearing across multiple endpoints despite documentation
These would be measured problems backed by data, not speculation. When we see them, we’ll have clear evidence that justifies additional complexity. Right now, we don’t.
A Framework for Evaluating “Best Practices”
After this experience, I now ask:
What is the actual problem?
- Not the category, the specific, measurable issue
- Current evidence, not hypothetical futureWhat’s the simplest fix?
- Minimum code change
- Minimum new abstractions
- Minimum test surfaceWhat’s the cost of being wrong?
- Data corruption > Performance
- User-facing bugs > Code elegance
- Correctness > OptimizationIs this reversible?
- Can we add optimization later? (Usually yes)
- Can we fix broken contracts later? (Usually painful)
- Which direction has lower switching costs?Do we have data?
- Actual metrics, not estimates
- Real costs, not projected
- Measured problems, not theoretical
The Deeper Lesson
The real insight wasn’t about PATCH or null handling. It was about how engineers approach problems.
When you see a bug, there are three questions:
What’s broken? (Diagnosis)
Why is it broken? (Root cause)
What systemic issues enabled this? (Prevention)
For us:
What’s broken? Null values ignored in PATCH
Why? Truthy check instead of presence check
What’s systemic? No contract tests, unclear PATCH semantics across codebase, no shared API guidelines
The last question matters most for preventing recurrence.
These changes cost a few hours, but their impact compounds. Over the next year, the checklist alone will likely prevent eight to ten similar bugs based on our current velocity. API design discussions that once took thirty to sixty minutes now take five to ten because we have shared guidelines. New engineers can reference documentation instead of asking, “How do we usually handle this?” That’s organizational leverage. It makes the next ten decisions easier, not just one problem solvable.
Treating this as a teaching moment was intentional. Rather than fixing the bug quietly, we used it to align on how we reason about API contracts, correctness, and optimization. The goal wasn’t to prevent this one failure. It was to reduce the likelihood of entire categories of similar failures appearing elsewhere.
We’re making systemic improvements:
1. Pre-PR checklist for PATCH endpoints:
□ Handles null explicitly
□ Handles absent fields correctly
□ Contract tests include null cases
□ Idempotency verified
2. Shared API guidelines:
When to use PATCH vs PUT
How to handle null vs undefined vs omitted
Required test coverage
Reference implementations
3. Documentation updates:
Clarify null semantics in API docs
Add examples of field clearing
Document the explicit contract
These changes cost a few hours but prevent entire categories of bugs. That’s the real value, not optimizing hypothetical performance but hardening actual weak points.
Final Thought: The Discipline of Simplicity
The hardest part of engineering isn’t building complex systems. It’s having the discipline to keep them simple.
Every engineer has an instinct to solve the “real” problem, the elegant, general, future-proof solution. We’re trained for edge cases, scale, and architecture.
That instinct is valuable. It’s also dangerous.
Because sometimes the real problem is simple. And solving simple problems simply requires resisting the urge to be clever.
Adding complexity is easy. Maintaining simplicity is hard.
The best engineers don’t rely on instant pattern recognition alone. They build frameworks, write things down, and think through tradeoffs explicitly. Experience speeds up the process, but the process itself is what matters.
Anyone can introduce dirty tracking, sentinel values, sophisticated state management. It takes more discipline to write:
if (payload.hasOwnProperty(key)) {
  updates[key] = payload[key];
}
…and ship it.
What This Means Practically
If you’re in a similar situation, a “simple” bug becoming an architecture debate, ask yourself:
Am I solving the problem I have, or the problem I think I should have?
The answer often determines whether you spend weeks building infrastructure or ship a fix the same day, and whether your team builds shared judgment or accumulates silent complexity.
Key Takeaways
Correctness before optimization, always
Best practices are context-dependent, not universal laws
The smallest working fix is often the right fix
Complexity has a carrying cost. Pay it deliberately
Test the contract, not just the implementation
Fix the system that created the bug, not just the bug itself
Real-world APIs (GitHub, Stripe, Salesforce) accept full PATCH payloads
Engineering judgment is knowing what not to build
This was discovered during routine testing, before production deployment. The fix is being implemented as part of normal development workflow. What matters isn’t that we found the perfect solution. It’s that we built the system to recognize when simple is sufficient and when complexity is justified. That distinction, repeated across hundreds of decisions, is what separates high-velocity teams from those drowning in their own sophistication.
Note: This article was originally published on Medium and is republished here for wider access and long-term reference.