保留正文与补采附件。源页面当前未重新核验;具体限制见交付清单。
 We value your privacy
We use cookies to enhance your browsing experience, serve personalised ads or content, and analyse our traffic. By clicking "Accept All", you consent to our use of cookies.
Customise Reject All Accept All
Customise Consent Preferences
 We use cookies to help you navigate efficiently and perform certain functions. You will find detailed information about all cookies under each consent category below.
The cookies that are categorised as "Necessary" are stored on your browser as they are essential for enabling the basic functionalities of the site. ... Show more
NecessaryAlways Active
Necessary cookies are required to enable the basic features of this site, such as providing secure log-in or adjusting your consent preferences. These cookies do not store any personally identifiable data.
-
Cookie
BCTempID
-
Duration
10 minutes
-
Description
No description available.
-
Cookie
__cf_bm
-
Duration
1 hour
-
Description
This cookie, set by Cloudflare, is used to support Cloudflare Bot Management.
-
Cookie
AWSALBCORS
-
Duration
7 days
-
Description
Amazon Web Services set this cookie for load balancing.
-
Cookie
_cfuvid
-
Duration
session
-
Description
Cloudflare sets this cookie to track users across sessions to optimize user experience by maintaining session consistency and providing personalized services
-
Cookie
li_gc
-
Duration
6 months
-
Description
Linkedin set this cookie for storing visitor's consent regarding using cookies for non-essential purposes.
-
Cookie
__hssrc
-
Duration
session
-
Description
This cookie is set by Hubspot whenever it changes the session cookie. The __hssrc cookie set to 1 indicates that the user has restarted the browser, and if the cookie does not exist, it is assumed to be a new session.
-
Cookie
__hssc
-
Duration
1 hour
-
Description
HubSpot sets this cookie to keep track of sessions and to determine if HubSpot should increment the session number and timestamps in the __hstc cookie.
-
Cookie
wpEmojiSettingsSupports
-
Duration
session
-
Description
WordPress sets this cookie when a user interacts with emojis on a WordPress site. It helps determine if the user's browser can display emojis properly.
-
Cookie
BCSessionID
-
Duration
1 year 1 month 4 days
-
Description
Blueconic sets this cookie as a unique identifier for the BlueConic profile.
-
Cookie
_octo
-
Duration
1 year
-
Description
No description available.
-
Cookie
logged_in
-
Duration
1 year
-
Description
No description available.
-
Cookie
__Secure-YEC
-
Duration
past
-
Description
YouTube sets this cookie to stores the user's video player preferences using embedded YouTube video
-
Cookie
__eoi
-
Duration
6 months
-
Description
Description is currently not available.
-
Cookie
AWSALBTGCORS
-
Duration
7 days
-
Description
No description available.
-
Cookie
login-status-p
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
AWSALBTG
-
Duration
7 days
-
Description
No description available.
-
Cookie
csrf_token
-
Duration
session
-
Description
No description available.
-
Cookie
token_v2
-
Duration
1 day
-
Description
Description is currently not available.
-
Cookie
D
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
PHPSESSID
-
Duration
session
-
Description
This cookie is native to PHP applications. The cookie stores and identifies a user's unique session ID to manage user sessions on the website. The cookie is a session cookie and will be deleted when all the browser windows are closed.
-
Cookie
VISITOR_PRIVACY_METADATA
-
Duration
6 months
-
Description
YouTube sets this cookie to store the user's cookie consent state for the current domain.
-
Cookie
cookietest
-
Duration
session
-
Description
The cookietest cookie is typically used to determine whether the user's browser accepts cookies, essential for website functionality and user experience.
-
Cookie
__Host-airtable-session
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
__Host-airtable-session.sig
-
Duration
1 year
-
Description
This cookie is used to enable us to integrate the services of Airtable.
-
Cookie
m
-
Duration
1 year 1 month 4 days
-
Description
Stripe sets this cookie for fraud prevention purposes. It identifies the device used to access the website, allowing the website to be formatted accordingly.
-
Cookie
BIGipServer*
-
Duration
session
-
Description
Marketo sets this cookie to collect information about the user's online activity and build a profile about their interests to provide advertisements relevant to the user.
-
Cookie
__cfruid
-
Duration
session
-
Description
Cloudflare sets this cookie to identify trusted web traffic.
-
Cookie
_GRECAPTCHA
-
Duration
6 months
-
Description
Google Recaptcha service sets this cookie to identify bots to protect the website against malicious spam attacks.
-
Cookie
__Secure-YNID
-
Duration
6 months
-
Description
Google cookie used to protect user security and prevent fraud, especially during the login process.
-
Cookie
cookieyes-consent
-
Duration
1 year
-
Description
CookieYes sets this cookie to remember users' consent preferences so that their preferences are respected on subsequent visits to this site. It does not collect or store any personal information about the site visitors.
Functional
Functional cookies help perform certain functionalities like sharing the content of the website on social media platforms, collecting feedback, and other third-party features.
-
Cookie
lidc
-
Duration
1 day
-
Description
LinkedIn sets the lidc cookie to facilitate data center selection.
-
Cookie
brw
-
Duration
1 year
-
Description
No description available.
-
Cookie
brwConsent
-
Duration
5 minutes
-
Description
Description is currently not available.
-
Cookie
WMF-Uniq
-
Duration
1 year
-
Description
Description is currently not available.
-
Cookie
loom_anon_comment
-
Duration
1 year
-
Description
No description available.
-
Cookie
loom_referral_video
-
Duration
session
-
Description
Description is currently not available.
-
Cookie
VISITOR_INFO1_LIVE
-
Duration
6 months
-
Description
A cookie set by YouTube to measure bandwidth that determines whether the user gets the new or old player interface.
-
Cookie
yt-remote-connected-devices
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
ytidb::LAST_RESULT_ENTRY_KEY
-
Duration
Never Expires
-
Description
The cookie ytidb::LAST_RESULT_ENTRY_KEY is used by YouTube to store the last search result entry that was clicked by the user. This information is used to improve the user experience by providing more relevant search results in the future.
-
Cookie
yt-remote-device-id
-
Duration
Never Expires
-
Description
YouTube sets this cookie to store the user's video preferences using embedded YouTube videos.
-
Cookie
yt-remote-session-name
-
Duration
session
-
Description
The yt-remote-session-name cookie is used by YouTube to store the user's video player preferences using embedded YouTube video.
-
Cookie
yt-remote-fast-check-period
-
Duration
session
-
Description
The yt-remote-fast-check-period cookie is used by YouTube to store the user's video player preferences for embedded YouTube videos.
-
Cookie
yt-remote-session-app
-
Duration
session
-
Description
The yt-remote-session-app cookie is used by YouTube to store user preferences and information about the interface of the embedded YouTube video player.
-
Cookie
yt-remote-cast-available
-
Duration
session
-
Description
The yt-remote-cast-available cookie is used to store the user's preferences regarding whether casting is available on their YouTube video player.
-
Cookie
yt-remote-cast-installed
-
Duration
session
-
Description
The yt-remote-cast-installed cookie is used to store the user's video player preferences using embedded YouTube video.
-
Cookie
cp_session
-
Duration
3 months
-
Description
Codepen sets this cookie for Help systems found in the website.
-
Cookie
loid
-
Duration
1 year 1 month 4 days
-
Description
This cookie is set by the Reddit. The cookie enables the sharing of content from the website onto the social media platform.
Analytics
Analytical cookies are used to understand how visitors interact with the website. These cookies help provide information on metrics such as the number of visitors, bounce rate, traffic source, etc.
-
Cookie
__hstc
-
Duration
6 months
-
Description
Hubspot set this main cookie for tracking visitors. It contains the domain, initial timestamp (first visit), last timestamp (last visit), current timestamp (this visit), and session number (increments for each subsequent session).
-
Cookie
hubspotutk
-
Duration
6 months
-
Description
HubSpot sets this cookie to keep track of the visitors to the website. This cookie is passed to HubSpot on form submission and used when deduplicating contacts.
-
Cookie
_ga
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to calculate visitor, session and campaign data and track site usage for the site's analytics report. The cookie stores information anonymously and assigns a randomly generated number to recognise unique visitors.
-
Cookie
ga*
-
Duration
1 year 1 month 4 days
-
Description
Google Analytics sets this cookie to store and count page views.
-
Cookie
__Host-psifi.analyticsTrace
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
__Host-psifi.analyticsTraceV2
-
Duration
6 hours
-
Description
Description is currently not available.
-
Cookie
_gh_sess
-
Duration
session
-
Description
GitHub sets this cookie for temporary application and framework state between pages like what step the user is on in a multiple step form.
-
Cookie
YSC
-
Duration
session
-
Description
YSC cookie is set by Youtube and is used to track the views of embedded videos on Youtube pages.
-
Cookie
ajs_anonymous_id
-
Duration
1 year
-
Description
This cookie is set by Segment to count the number of people who visit a certain site by tracking if they have visited before.
-
Cookie
vuid
-
Duration
1 year 1 month 4 days
-
Description
Vimeo installs this cookie to collect tracking information by setting a unique ID to embed videos on the website.
Performance
Performance cookies are used to understand and analyse the key performance indexes of the website which helps in delivering a better user experience for the visitors.
-
Cookie
AWSALB
-
Duration
7 days
-
Description
AWSALB is an application load balancer cookie set by Amazon Web Services to map the session to the target.
-
Cookie
acq
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
acq.sig
-
Duration
past
-
Description
Description is currently not available.
-
Cookie
ptc
-
Duration
2 years
-
Description
No description available.
Advertisement
Advertisement cookies are used to provide visitors with customised advertisements based on the pages you visited previously and to analyse the effectiveness of the ad campaigns.
-
Cookie
muc_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to collect user behaviour and interaction data to optimize the website.
-
Cookie
guest_id_marketing
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
guest_id_ads
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor.
-
Cookie
personalization_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to integrate and share features for social media and also store information about how the user uses the website, for tracking and targeting.
-
Cookie
guest_id
-
Duration
1 year 1 month 4 days
-
Description
Twitter sets this cookie to identify and track the website visitor. It registers if a user is signed in to the Twitter platform and collects information about ad preferences.
-
Cookie
bcookie
-
Duration
1 year
-
Description
LinkedIn sets this cookie from LinkedIn share buttons and ad tags to recognize browser IDs.
-
Cookie
__Secure-ROLLOUT_TOKEN
-
Duration
6 months
-
Description
YouTube sets this cookie to manage feature rollout and experimentation. It helps Google control which new features or interface changes are shown to users as part of testing and staged rollouts, ensuring consistent experience for a given user during an experiment.
-
Cookie
yt.innertube::nextId
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
yt.innertube::requests
-
Duration
Never Expires
-
Description
YouTube sets this cookie to register a unique ID to store data on what videos from YouTube the user has seen.
-
Cookie
session_tracker
-
Duration
session
-
Description
This cookie is set by the Reddit. This cookie is used to identify trusted web traffic. It also helps in adverstising on the website.
-
Cookie
edgebucket
-
Duration
session
-
Description
Reddit sets this cookie to save the information about a log-on Reddit user, for the purpose of advertisement recommendations and updating the content.
-
Cookie
did
-
Duration
1 year
-
Description
Arbor sets this cookie to show targeted ads to site visitors.This cookie expires after 2 months or 1 year.
Uncategorised
Other uncategorised cookies are those that are being analysed and have not been classified into a category as yet.
No cookies to display.
Reject All Save My Preferences Accept All
Toggle SearchToggle Mobile Navigation
Publish AI, ML & data-science insights to a global community of data professionals.
Sign inSubmit an Article
LatestEditor's PicksNewsletterShipAI
Write For TDS
LinkedInXToggle Search
Deep Learning
MobileNetV2 Paper Walkthrough: The Smarter Tiny Giant
Understanding and implementing MobileNetV2 with PyTorch — the next generation of MobileNetV1
Muhammad Ardi Putra
October 3, 202531 min read
 Photo by Erik Mclean on Unsplash
Introduction
MobileNetV1 was a breakthrough in the field of computer vision as it proved that deep learning models do not necessarily need to be computationally expensive to achieve high accuracy. Last month I posted an article where I explained everything about the model as well as its PyTorch implementation from scratch. Check the link at reference number [1] at the end of this article if you are interested in reading it. This first version of MobileNet was first proposed back in April 2017 in a paper titled MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications[2] by Howard et al. from Google. Not long after — in January 2018 to be precise — Sandler et al. from the same institution introduced the successor of MobileNetV1 in a paper titled MobileNetV2: Inverted Residuals and Linear Bottlenecks [3], which brings significant improvement over the previous one in terms of both accuracy and efficiency. In this article, I am going to walk you through the ideas proposed in the MobileNetV2 paper and show you how to implement the architecture from scratch.
···
Learn this step by step with the interactive Machine Learning roadmap.
The Improvements
The first version of MobileNet relies solely on the so-called depthwise separable convolution layers. It is indeed necessary to acknowledge that using these layers as a replacement of standard convolutions allows the model to be extremely lightweight. However, authors thought that this architecture could still be improved even further. They came up with an idea where instead of only using depthwise separable convolutions, they also adopted the inverted residual and linear bottleneck mechanisms — which is where the title of the MobileNetV2 paper came from.
Inverted Residual
If you’re familiar with ResNet, I believe you know the so-called bottleneck block. For those who don’t, it is essentially a mechanism where the building block of the network works by following the wide → narrow → wide pattern. Figure 1 below displays the illustration of a bottleneck block used in ResNet. Here we can see that it initially accepts a 256-channel tensor, shrink it to 64, and expands it back to 256.
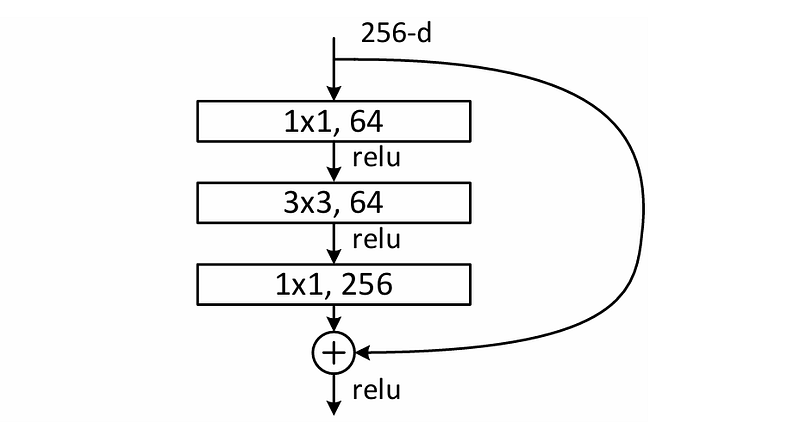 Figure 1. The building block of ResNet, commonly known as “bottleneck” [4].
The inverted version of the above block is commonly known as inverted bottleneck , which follows the narrow → wide → narrow structure. Figure 2 below shows an example from the ConvNeXt paper [5], where the number of channels in the input tensor is 96, expanded to 384, and compressed back to 96 by the last convolution layer. It is important to note that in MobileNetV2 an inverted bottleneck block is called inverted residual for some reasons. So, starting from now on, I will use the term to avoid confusion.
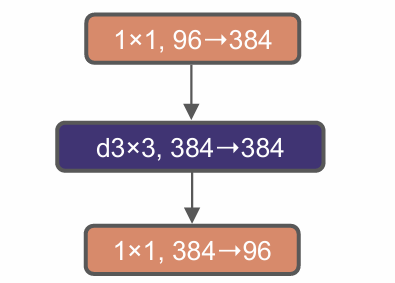 Figure 2. The inverted bottleneck block introduced in ConvNeXt [5].
At this point you might be wondering why we don’t just use the standard bottleneck for MobileNetV2. The answer lies in the original purpose of the standard bottleneck design, where it was first introduced to reduce computational complexity. This was essentially done because ResNet is computationally expensive by nature yet rich in information. For this reason, ResNet authors proposed to reduce computational cost by shrinking the tensor size in the middle of each building block, which is how the bottleneck block was born.
This reduction in the number of channels does not hurt the model capacity that much since ResNet already has a large number of channels overall. On the other hand, MobileNetV2 is intended to be as lightweight as possible in the first place, which means the model capacity is not as high as ResNet. In order to increase model capacity, authors expand the tensor size in the middle to form the inverted residual block, which allows the model to learn more patterns while only slightly increasing complexity. So in short, the middle part of a bottleneck block (narrow) is used for efficiency, while the middle part of an inverted residual block (wide) is used to learn complex patterns. If we try to apply a standard bottleneck on MobileNetV2 instead, the computation is going to be even faster, but this might cause a drop in accuracy since the model will lose a significant amount of information.
Linear Bottleneck
The next concept we need to understand is the so-called linear bottleneck. This one is actually pretty simple since what we essentially do here is just to omit the nonlinearity (i.e., the ReLU activation function) in the last layer of each inverted residual block. The use of activation functions in neural networks at the first place is to allow the network to capture complex patterns. However, it will destroy important information instead if we apply it on a low-dimensional tensor, especially in the context of MobileNetV2 where the inverted residual block projects a high dimensional tensor to a smaller one in the last convolution layer. By removing the activation function in the last convolution layer like this, we essentially prevent the model from losing important information. Figure 3 below shows what the inverted residual block used in MobileNetV2 looks like. Notice that ReLU is not applied in the last pointwise convolution, which essentially means that this layer behaves somewhat similarly to a standard linear regression layer. In addition to this figure, the variables k and k’ denote the number of input and output channels, respectively. In the intermediate process, we essentially expand the number of channels by t before eventually shrink it to k’. I’ll go into more detail on these variables in the next section.
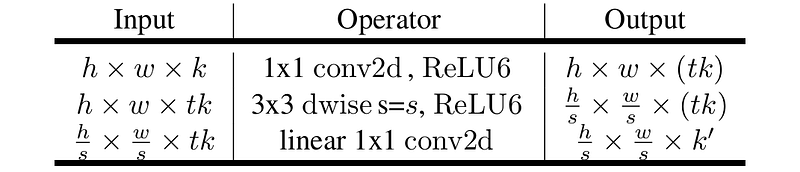 Figure 3. The inverted residual block used in MobileNetV2. Notice that we don’t apply ReLU after the last pointwise convolution layer [3].
ReLU6
So why do we use ReLU6 instead of regular ReLU? In case you’re not yet familiar with it, this activation function is actually similar to ReLU, except that the output value is capped at 6. So, any input greater than 6 will be mapped to that number. Meanwhile, the behavior for negative inputs is exactly the same. Thus, we can simply say that the output of ReLU6 will always be within the range of 0 to 6 (inclusive). Look at Figure 4 below to better understand this idea.
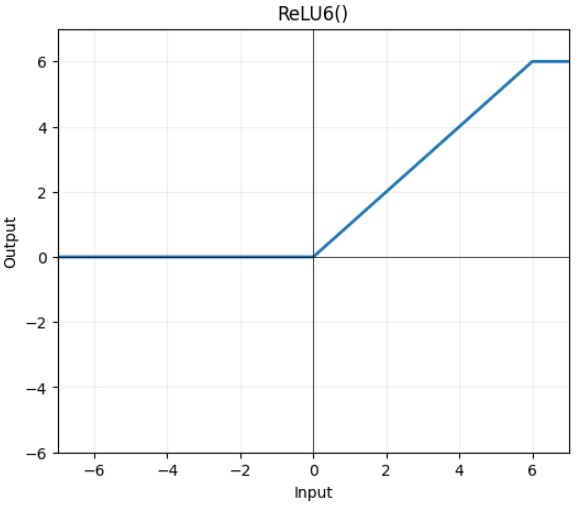 Figure 4. The ReLU6 activation function [6].
In standard ReLU, there is a possibility where the input — and therefore the output — value goes arbitrarily large, in which it potentially causes instability in low-precision environments. Remember that MobileNet is intended to be able to work on small devices, in which we know that such devices typically expect small numbers to save memory, say 8-bit integer. In this particular case, having very large activation values could lead to precision loss or clipping when quantized to low-bit representations. Thus, to keep the values small and within a manageable range, we can simply employ ReLU6 to do so.
···
The Complete MobileNetV2 Architecture
Now let’s take a look at the complete MobileNetV2 architecture in Figure 5 below. Just like the first version of MobileNet which mostly consists of depthwise separable convolutions, most of the components inside MobileNetV2 are the inverted residual blocks with linear bottlenecks we discussed earlier. Every row in the following table labeled as bottleneck corresponds to a single stage , in which each of them consists of several inverted residual blocks. Talking about the columns in the table, t represents expansion factor used in the middle part of each block, c denotes the number of output channels of each block, n is the number of repeats of the block within that stage, and s indicates the stride of the first block within the stage.
To better understand this idea, let’s take a closer look at the stage which the input shape is 56×56×24. Here you can see that the corresponding parameters of this stage are t =6, c =32, n =3, and s =2. This essentially means that the inverted residual stage consists of 3 blocks. All these blocks are identical except that the first one uses stride 2, reducing the spatial dimension by half from 56×56 to 28×28. Next, c =32 is pretty straightforward as it basically says that the number of output channel of each block within the stage is 32. Meanwhile, t =6 indicates that the intermediate layer inside the blocks is 6 times wider than the input, forming the inverted bottleneck structure. So, in this case the number of channels in the process is going to be 32 → 192 → 32. However, it is important to note that the first block within that stage is different, where it uses 24 → 144 → 32 structure thanks to the 24-channel input tensor. If we refer back to Figure 3, these two structures essentially follow the k → kt → k’ pattern.
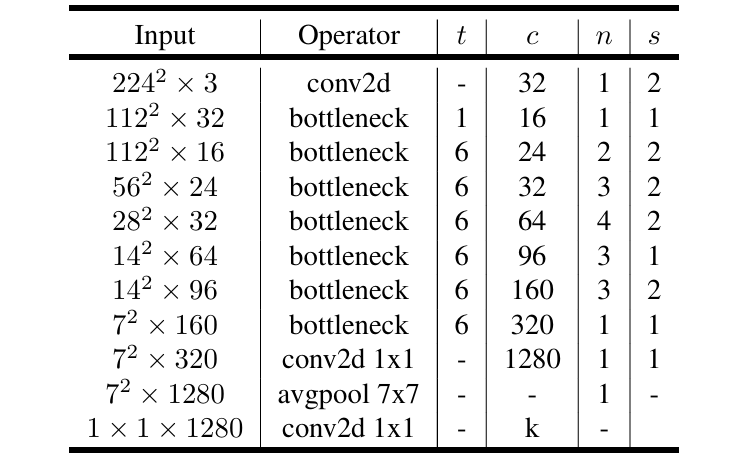 Figure 5. The MobileNetV2 architecture we are about to implement [3].
In addition to the above architecture, here we also have skip-connections placed within the inverted residual blocks. This skip-connection will only be applied whenever the stride of the block is set to 1. This is essentially because the spatial dimension of the image will change whenever we use stride 2, causing the output tensor to have different shape to that of the input. Such a difference in tensor shapes will effectively prevent us from performing element-wise summation between the original flow and the skip-connection. See Figure 6 below for the details. Note that the two illustrations in this figure are basically just the visualization of the table in Figure 3.
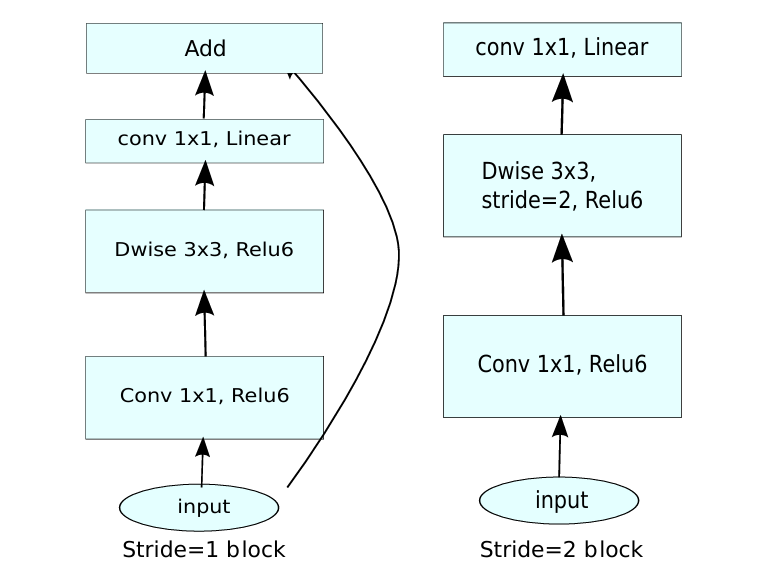 Figure 6. We don’t implement skip-connection when the stride is set to 2 (i.e., when the layer performs spatial downsampling) [3].
Parameter Tuning
Similar to MobileNetV1, MobileNetV2 also has two adjustable parameters called width multiplier and input resolution. The former is used to adjust the width of the network, while the latter is for changing the resolution of the input image. The architecture you see in Figure 5 is the base configuration, where we set the width multiplier to 1 and the input resolution to 224×224. With these two parameters, we can tune the model to find a sweet spot that balances accuracy and efficiency based on our needs.
We can technically choose arbitrary numbers for the two parameters, but authors already provided several predetermined numbers for their experiments. To the width multiplier, we can use 0.75, 0.5 or 0.35, in which all of them will make the model smaller. For instance, if we use 0.5 then all numbers in column c in Figure 5 will be reduced to half of their defaults. To the input resolution, we can choose either 192×192, 160×160, 128×128 or 96×96 as a replacement for 224×224 if you want to lower the number of operations during inference.
Some Experimental Results
Figure 7 below shows what the experimental results done by the authors look like. Even though MobileNetV1 is considered lightweight already, MobileNetV2 proved that its performance is even better in terms of all metrics compared to its predecessor. However, it is necessary to acknowledge that the base MobileNetV2 is not completely superior to other lightweight models especially when taking into account all aspects at once.
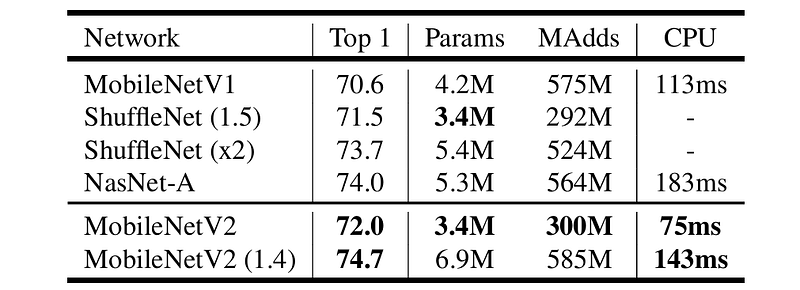 Figure 7. The performance of MobileNetV2 compared to other lightweight models on ImageNet dataset [3].
In order to achieve even better accuracy, authors also tried to enlarge the model instead by changing the width multiplier to 1.4 for the 224×224 input resolution, which in the above figure corresponds to the result in the last row. Doing this definitely causes the model complexity as well as the computation time to get higher, but in return it allows the model to obtain the highest accuracy. The results in Figure 8 also show the similar thing, where all MobileNetV2 variants completely outperform the MobileNetV1 counterpart, with the largest MobileNetV2 obtaining the highest accuracy among all models.
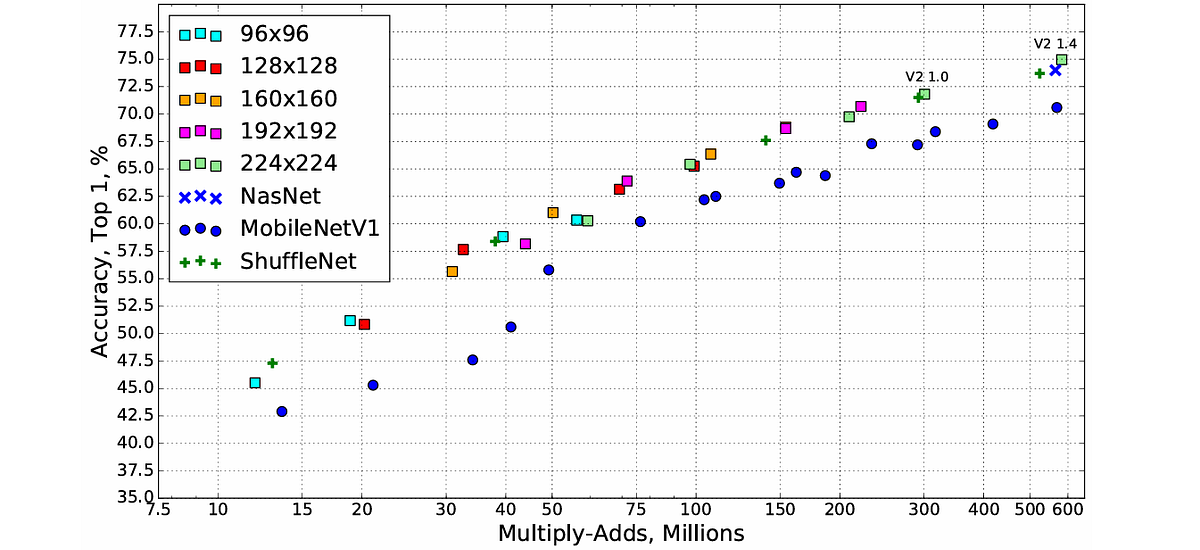 Figure 8. More results showing the superiority of MobileNetV2 over the existing models and how input resolution affects accuracy [3].
···
MobileNetV2 Implementation
Every time I finished learning something, I always wonder if I really understand what I just learned. In the case of deep learning, I (almost) always try to implement the architecture on my own right after reading the paper just to prove to myself that I understand. And here’s the quote that drives me that way:
What I cannot create, I do not understand.
Richard Feynman
This is essentially the reason why I always include the code implementation of the paper I am explaining in my post.
···
What an intermezzo that was. — Now let’s get back our focus to MobileNetV2. In this section I am going to show you how we can implement the architecture from scratch. As always, the very first thing we need to do is to import the required modules.
python
# Codeblock 1
import torch
import torch.nn as nn
from torchinfo import summary
Next, we also need to initialize some configuration variables so that we can easily rescale our model if we want to. The two variables I want to highlight in the Codeblock 2 below are the WIDTH_MULTIPLIER and IMAGE_SIZE, where these two essentially correspond to the width multiplier and input resolution parameters we discussed earlier. Here I set the two to 1.0 and 224 because I want to implement the base MobileNetV2 architecture.
python
# Codeblock 2
BATCH_SIZE        = 1
IMAGE_SIZE        = 224
IN_CHANNELS       = 3
NUM_CLASSES       = 1000
WIDTH_MULTIPLIER  = 1.0
If we take a look at the architectural details in Figure 5, we can see that the rows labeled as bottleneck is a group of blocks, which we previously refer to as stage. Meanwhile, each row labeled as conv2d is basically just a standard convolution layer. I’ll start with the latter first because that one is easier to implement.
The Standard Convolution Layer
Talking about the rows labeled with conv2d , you might be asking why we really need to wrap this single convolution layer in a separate class. Can’t we just directly use nn.Conv2d in the main class? — In fact, it is mentioned in the paper that every conv layer is always followed by a batch normalization layer before eventually being processed by the ReLU6 activation function. This is actually in accordance with MobileNetV1, where it uses the conv-BN-ReLU structure. In order to make the code cleaner, we can just wrap these layers within a single class so that we don’t necessarily need to define all of them repeatedly. Take a look at the Codeblock 3 below to see how I create the Conv class.
python
# Codeblock 3
class Conv(nn.Module):
    def __init__(self, first=False):      #(1)
        super().__init__()

        if first:
            in_channels = 3               #(2)
            out_channels = int(32*WIDTH_MULTIPLIER)          #(3)
            kernel_size = 3               #(4)
            stride = 2                    #(5)
            padding = 1                   #(6)
        else:
            in_channels  = int(320*WIDTH_MULTIPLIER)         #(7)
            out_channels = int(1280*WIDTH_MULTIPLIER)        #(8)
            kernel_size = 1               #(9)
            stride = 1                    #(10)
            padding = 0                   #(11)

        self.conv = nn.Conv2d(in_channels=in_channels,       #(12)
                              out_channels=out_channels,
                              kernel_size=kernel_size,
                              stride=stride,
                              padding=padding,
                              bias=False)
        self.bn = nn.BatchNorm2d(num_features=out_channels)  #(13)
        self.relu6 = nn.ReLU6()           #(14)

    def forward(self, x):
        x = self.relu6(self.bn(self.conv(x)))                #(15)
        return x
Every time we want to instantiate a Conv instance, we need to pass a value for the first parameter as shown at the line marked with #(1) in the above code. If you take a look at the architecture, you will notice that this Conv layer will be used either before the sequence of inverted residuals or right after the sequence. The Figure 9 below displays the architecture again with the two convolutions highlighted in pink and green, respectively. Later in the main class, if we want to instantiate the pink layer, we can simply set the first flag to True, and if we want to instantiate the green one, we can run it without passing any arguments since I’ve set the flag to False by default.
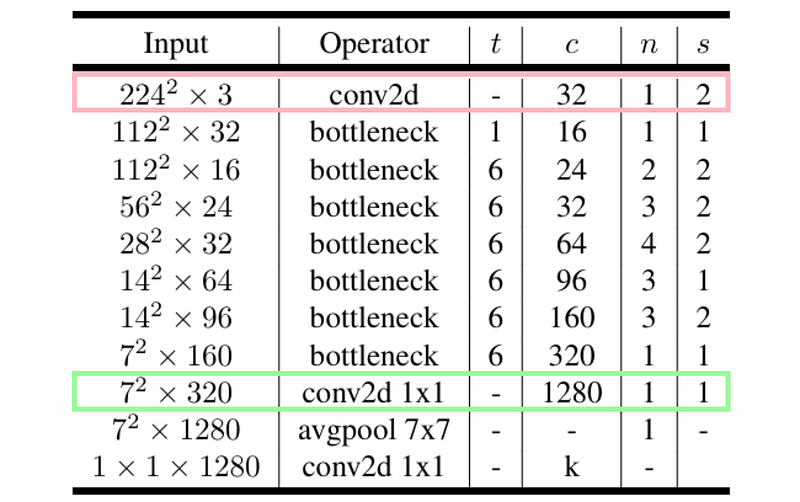 Figure 9. The Conv class will be used to instantiate these two convolution layers [3][6].
Using a flag like this helps us to apply different configurations for the two convolutions. When we use
first=True, we set the convolution layer to accept 3 input channels (#(2)) and produce a 32-channel tensor (#(3)). The kernel size used will be 3×3 (#(4)) with a stride of 2 (#(5)), effectively downsampling the spatial dimension by half. With this kernel size, we need to set the padding to 1 (#(6)) to prevent the convolution process from reducing the spatial dimension even further. All these configurations are essentially taken from the conv layer highlighted in pink.
Meanwhile, when we use first=False, this convolution layer will take a tensor of 320 channels for the input (#(7)) and produce another one having 1280 channels (#(8)). This green-highlighted layer is a pointwise convolution, hence we need to set the kernel size to 1 (#(9)). Since here we won’t perform spatial downsampling, the stride parameter must be set to 1 as shown at line #(10) (notice that the input size of this layer and the next one are both 7×7 spatially). Lastly, we set the padding to 0 (#(11)) because by nature a 1×1 kernel cannot reduce spatial dimensions on its own.
As the parameters for the convolution layer have been defined, the next thing we do in the Conv class above is to initialize the convolution layer itself using nn.Conv2d (#(12)) as well as the batch normalization layer (#(13)) and the ReLU6 activation function (#(14)). Lastly, we assemble these layers to form the conv-BN-ReLU structure in the forward() method (#(15)). In addition to the above code, don’t forget to apply WIDTH_MULTIPLIER when specifying the number of input and output channels, i.e., at line #(3), #(7), and #(8), so that we can adjust the model size simply by changing the value of the variable.
Now let’s check if we have implemented the Conv class correctly by running the two test cases below. The one in Codeblock 4 demonstrates the pink layer while the Codeblock 5 shows the green one. The shape of the dummy tensor x used in both tests are set according to the input shapes required by each of the two layers. Based on the resulting outputs, we can confirm that our implementation is correct since the output tensor shapes match exactly with the expected input shapes of the corresponding subsequent layers.
python
# Codeblock 4
conv = Conv(first=True)
x = torch.randn(1, 3, 224, 224)

out = conv(x)
out.shape
http
# Codeblock 4 Output
torch.Size([1, 32, 112, 112])
python
# Codeblock 5
conv = Conv(first=False)
x = torch.randn(1, int(320*WIDTH_MULTIPLIER), 7, 7)

out = conv(x)
out.shape
http
# Codeblock 5 Output
torch.Size([1, 1280, 7, 7])
···
Inverted Residual Block for Stride 2
As we have completed the class for standard convolution layers, we will now talk about the one for the inverted residual blocks. Keep in mind that there are cases where we use either stride 1 or 2, which results in a slight difference in the block structure (see Figure 6). In this case I decided to implement them in two separate classes. In terms of practicality, it might indeed be cleaner if we just put them within the same class. However, for the sake of this tutorial I feel like breaking them down into two will make things easier to follow. I am going to implement the one with stride 2 first since this one is simpler thanks to the absence of the skip-connection. See the InvResidualS2 class in Codeblock 6 below for the details.
python
# Codeblock 6
class InvResidualS2(nn.Module):
    def __init__(self, in_channels, out_channels, t):         #(1)
        super().__init__()

        in_channels  = int(in_channels*WIDTH_MULTIPLIER)      #(2)
        out_channels = int(out_channels*WIDTH_MULTIPLIER)     #(3)

        self.pwconv0 = nn.Conv2d(in_channels=in_channels,     #(4)
                                 out_channels=in_channels*t,
                                 kernel_size=1,
                                 stride=1,
                                 bias=False)

        self.bn_pwconv0 = nn.BatchNorm2d(num_features=in_channels*t)

        self.dwconv = nn.Conv2d(in_channels=in_channels*t,    #(5)
                                out_channels=in_channels*t,
                                kernel_size=3,                #(6)
                                stride=2,
                                padding=1,
                                groups=in_channels*t,         #(7)
                                bias=False)

        self.bn_dwconv = nn.BatchNorm2d(num_features=in_channels*t)

        self.pwconv1 = nn.Conv2d(in_channels=in_channels*t,   #(8)
                                 out_channels=out_channels,
                                 kernel_size=1,
                                 stride=1,
                                 bias=False)

        self.bn_pwconv1 = nn.BatchNorm2d(num_features=out_channels)

        self.relu6 = nn.ReLU6()

    def forward(self, x):
        print('original\t\t:', x.shape)

        x = self.pwconv0(x)
        print('after pwconv0\t\t:', x.shape)
        x = self.bn_pwconv0(x)
        print('after bn0_pwconv0\t:', x.shape)
        x = self.relu6(x)
        print('after relu\t\t:', x.shape)

        x = self.dwconv(x)
        print('after dwconv\t\t:', x.shape)
        x = self.bn_dwconv(x)
        print('after bn_dwconv\t\t:', x.shape)
        x = self.relu6(x)
        print('after relu\t\t:', x.shape)

        x = self.pwconv1(x)
        print('after pwconv1\t\t:', x.shape)
        x = self.bn_pwconv1(x)
        print('after bn_pwconv1\t:', x.shape)

        return x
The above class takes three parameters in order to work: in_channels, out_channels, and t, as written at line #(1). The first two corresponds to the number of input and output channels of the inverted residual block, whereas t is the expansion factor for determining the channel count of the wide part of the block. So, what we basically do here is just to make the middle tensors to have t times more channels than the input. The number of input and output channels themselves are adjustable via the WIDTH_MULTIPLIER variable we initialized earlier as shown at line #(2) and #(3).
What we need to do next is to initialize the layers within the inverted residual block according to the structure in Figure 3 and 6. Notice in the two figures that we have a depthwise convolution layer placed between two pointwise convolutions. The first pointwise convolution (#(4)) is used to expand the channel dimension from in_channels to in_channels*t. Subsequently, the depthwise convolution at line #(5) is responsible to capture information along the spatial dimension. Here we set the kernel size to 3×3 (#(6)), which allows the layer to capture spatial information from its neighboring pixels. Don’t forget to set the groups parameter to be the same as the number of input channels to this layer (#(7)) since we want the convolution operation to be performed independently of each channel. Next, we process the resulting tensor with the second pointwise convolution (#(8)), in which this layer is used to project the tensor to the expected number of output channels of the block.
In the forward() method, we place the layers one after another. Remember that we use the conv-BN-ReLU structure except for the last convolution, following the convention of linear bottleneck we discussed earlier. Additionally, here I also print out the output shape after each layer so that you can clearly see how the tensor transforms during the process.
Next, we are going to test whether the InvResidualS2 class works properly. The following testing code simulates the first inverted residual block (n=1) of the third row in the architecture (i.e., the one having 16×112×112 input shape).
python
# Codeblock 7
inv_residual_s2 = InvResidualS2(in_channels=16, out_channels=24, t=6)
x = torch.randn(1, int(16*WIDTH_MULTIPLIER), 112, 112)

out = inv_residual_s2(x)
You can see at the line marked with #(1) in the following output that the first pointwise convolution successfully expands the channel axis from 16 to 96. The spatial dimension shrinks from 112×112 to 56×56 after the tensor being processed by the depthwise convolution layer in the middle (#(2)). Lastly, our second pointwise convolution compresses the number of channels to 24 as written at line #(3). This final tensor dimension is now ready to be passed through the next inverted residual block within the same stage.
http
# Codeblock 7 Output
original          : torch.Size([1, 16, 112, 112])
after pwconv0     : torch.Size([1, 96, 112, 112])  #(1)
after bn0_pwconv0 : torch.Size([1, 96, 112, 112])
after relu        : torch.Size([1, 96, 112, 112])
after dwconv      : torch.Size([1, 96, 56, 56])    #(2)
after bn_dwconv   : torch.Size([1, 96, 56, 56])
after relu        : torch.Size([1, 96, 56, 56])
after pwconv1     : torch.Size([1, 24, 56, 56])    #(3)
after bn_pwconv1  : torch.Size([1, 24, 56, 56])
···
Inverted Residual Block for Stride 1
The code used for implementing the inverted residual block with stride 1 is mostly similar to the one with stride 2. See the InvResidualS1 class in Codeblock 8 below.
python
# Codeblock 8
class InvResidualS1(nn.Module):
    def __init__(self, in_channels, out_channels, t):
        super().__init__()

        in_channels  = int(in_channels*WIDTH_MULTIPLIER)    #(1)
        out_channels = int(out_channels*WIDTH_MULTIPLIER)   #(2)

        self.in_channels  = in_channels
        self.out_channels = out_channels

        self.pwconv0 = nn.Conv2d(in_channels=in_channels,
                                 out_channels=in_channels*t,
                                 kernel_size=1,
                                 stride=1,
                                 bias=False)

        self.bn_pwconv0 = nn.BatchNorm2d(num_features=in_channels*t)

        self.dwconv = nn.Conv2d(in_channels=in_channels*t,
                                out_channels=in_channels*t,
                                kernel_size=3,
                                stride=1,            #(3)
                                padding=1,
                                groups=in_channels*t,
                                bias=False)

        self.bn_dwconv = nn.BatchNorm2d(num_features=in_channels*t)

        self.pwconv1 = nn.Conv2d(in_channels=in_channels*t,
                                 out_channels=out_channels,
                                 kernel_size=1,
                                 stride=1,
                                 bias=False)

        self.bn_pwconv1 = nn.BatchNorm2d(num_features=out_channels)

        self.relu6 = nn.ReLU6()

    def forward(self, x):

        if self.in_channels == self.out_channels:    #(4)
            residual = x          #(5)
            print(f'residual\t\t: {residual.size()}')

        x = self.pwconv0(x)
        print('after pwconv0\t\t:', x.shape)
        x = self.bn_pwconv0(x)
        print('after bn_pwconv0\t:', x.shape)
        x = self.relu6(x)
        print('after relu\t\t:', x.shape)

        x = self.dwconv(x)
        print('after dwconv\t\t:', x.shape)
        x = self.bn_dwconv(x)
        print('after bn_dwconv\t\t:', x.shape)
        x = self.relu6(x)
        print('after relu\t\t:', x.shape)

        x = self.pwconv1(x)
        print('after pwconv1\t\t:', x.shape)
        x = self.bn_pwconv1(x)
        print('after bn_pwconv1\t:', x.shape)

        if self.in_channels == self.out_channels:
            x = x + residual      #(6)
            print('after summation\t\t:', x.shape)

        return x
The first difference we have here is definitely the stride parameter itself, especially the one belongs to the depthwise convolution layer at line #(3). By setting the stride parameter to 1 like this, the spatial output dimension of this inverted residual block is going to be the same as the input.
Another thing that we didn’t do previously is creating instance attributes for in_channels and out_channels as shown at lines #(1) and #(2). We do this now because later on we will need to access these values from the forward() method. This is actually just a basic OOP concept, where if we don’t assign them to self, then they will only exist locally within the __init__() method and won’t be available to other methods in the class.
Inside the forward() method itself, what we need to do first is to check whether the number of input and output channels are the same (#(4)). If so, we will keep the original input tensor (#(5)) to implement the skip-connection, in which this tensor will be element-wise summed with the one from the main flow (#(6)). This tensor dimensionality checking is performed because we need to ensure that the two tensors to be summed have the exact same size. We indeed have guaranteed the spatial dimension to remain unchanged since we have set all the three convolution layers to use stride 1. However, there is still a possibility that the number of output channels differs from the input, just like the first block within the stages highlighted in purple, blue and orange in Figure 10 below. In such cases, skip-connection will not be applied because it’s just impossible to perform element-wise summation on tensors with different shapes.
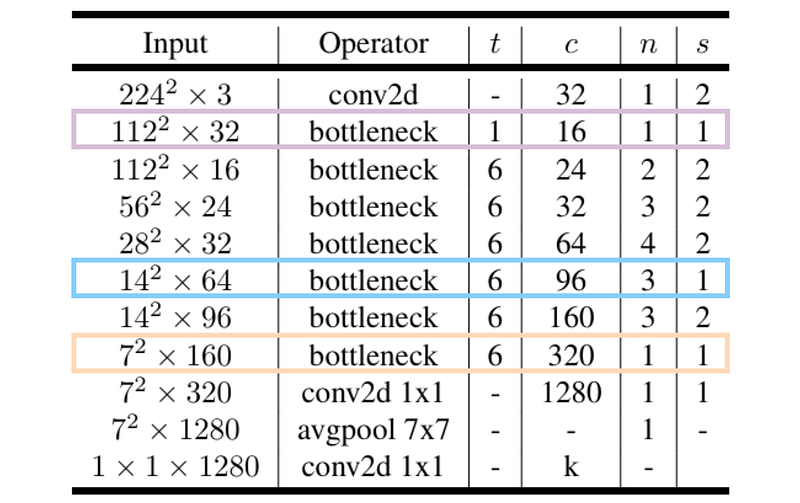 Figure 10. Despite not performing spatial downsampling, there is no skip-connection within the first block in the three highlighted stages since the number of input and output channels are different [3][6].
Now let’s test the
InvResidualS1 class by running the Codeblock 9 below. Here I am going to simulate the second inverted residual block (n =2) of the third row in the architecture, in which this is actually just the continuation of the previous test case. Here you can see that the dummy tensor we use has the exact same shape as the one we obtained from Codeblock 7, i.e., 24×56×56.
python
# Codeblock 9
inv_residual_s1 = InvResidualS1(in_channels=24, out_channels=24, t=6)
x = torch.randn(1, int(24*WIDTH_MULTIPLIER), 56, 56)

out = inv_residual_s1(x)
And below is what the resulting output looks like. It is clearly seen here that the network indeed follows the narrow → wide → narrow structure, which in this case is 24 → 144 → 24. In addition to this, since the spatial dimensions of the input and the output tensors are the same, we can technically stack this inverted residual block as many times as we want.
http
# Codeblock 9 Output
residual          : torch.Size([1, 24, 56, 56])
after pwconv0     : torch.Size([1, 144, 56, 56])
after bn_pwconv0  : torch.Size([1, 144, 56, 56])
after relu        : torch.Size([1, 144, 56, 56])
after dwconv      : torch.Size([1, 144, 56, 56])
after bn_dwconv   : torch.Size([1, 144, 56, 56])
after relu        : torch.Size([1, 144, 56, 56])
after pwconv1     : torch.Size([1, 24, 56, 56])
after bn_pwconv1  : torch.Size([1, 24, 56, 56])
after summation   : torch.Size([1, 24, 56, 56])
···
The Entire MobileNetV2 Architecture
As we have completed defining the Conv, InvResidualS2 and InvResidualS1 classes, we can now assemble them all to construct the entire MobileNetV2 architecture. Look at the Codeblock 10 below to see how I do that.
python
# Codeblock 10
class MobileNetV2(nn.Module):
    def __init__(self):
        super().__init__()

        # Input shape: 3x224x224
        self.first_conv = Conv(first=True)

        # Input shape: 32x112x112
        self.inv_residual0 = InvResidualS1(in_channels=32,
                                           out_channels=16,
                                           t=1)

        # Input shape: 16x112x112
        self.inv_residual1 = nn.ModuleList([InvResidualS2(in_channels=16,
                                                          out_channels=24,
                                                          t=6)])

        self.inv_residual1.append(InvResidualS1(in_channels=24,
                                                out_channels=24,
                                                t=6))

        # Input shape: 24x56x56
        self.inv_residual2 = nn.ModuleList([InvResidualS2(in_channels=24,
                                                          out_channels=32,
                                                          t=6)])

        for _ in range(2):
            self.inv_residual2.append(InvResidualS1(in_channels=32,
                                                    out_channels=32,
                                                    t=6))

        # Input shape: 32x28x28
        self.inv_residual3 = nn.ModuleList([InvResidualS2(in_channels=32,
                                                          out_channels=64,
                                                          t=6)])

        for _ in range(3):
            self.inv_residual3.append(InvResidualS1(in_channels=64,
                                                    out_channels=64,
                                                    t=6))

        # Input shape: 64x14x14
        self.inv_residual4 = nn.ModuleList([InvResidualS1(in_channels=64,
                                                          out_channels=96,
                                                          t=6)])

        for _ in range(2):
            self.inv_residual4.append(InvResidualS1(in_channels=96,
                                                    out_channels=96,
                                                    t=6))


        # Input shape: 96x14x14
        self.inv_residual5 = nn.ModuleList([InvResidualS2(in_channels=96,
                                                          out_channels=160,
                                                          t=6)])

        for _ in range(2):
            self.inv_residual5.append(InvResidualS1(in_channels=160,
                                                    out_channels=160,
                                                    t=6))

        # Input shape: 160x7x7
        self.inv_residual6 = InvResidualS1(in_channels=160,
                                           out_channels=320,
                                           t=6)

        # Input shape: 320x7x7
        self.last_conv = Conv(first=False)

        self.avgpool = nn.AdaptiveAvgPool2d(output_size=(1,1))        #(1)
        self.dropout = nn.Dropout(p=0.2)                              #(2)
        self.fc = nn.Linear(in_features=int(1280*WIDTH_MULTIPLIER),   #(3)
                            out_features=1000)

    def forward(self, x):
        x = self.first_conv(x)
        print(f"after first_conv\t: {x.shape}")

        x = self.inv_residual0(x)
        print(f"after inv_residual0\t: {x.shape}")

        for i, layer in enumerate(self.inv_residual1):
            x = layer(x)
            print(f"after inv_residual1 #{i}\t: {x.shape}")

        for i, layer in enumerate(self.inv_residual2):
            x = layer(x)
            print(f"after inv_residual2 #{i}\t: {x.shape}")

        for i, layer in enumerate(self.inv_residual3):
            x = layer(x)
            print(f"after inv_residual3 #{i}\t: {x.shape}")

        for i, layer in enumerate(self.inv_residual4):
            x = layer(x)
            print(f"after inv_residual4 #{i}\t: {x.shape}")

        for i, layer in enumerate(self.inv_residual5):
            x = layer(x)
            print(f"after inv_residual5 #{i}\t: {x.shape}")

        x = self.inv_residual6(x)
        print(f"after inv_residual6\t: {x.shape}")

        x = self.last_conv(x)
        print(f"after last_conv\t\t: {x.shape}")

        x = self.avgpool(x)
        print(f"after avgpool\t\t: {x.shape}")

        x = torch.flatten(x, start_dim=1)
        print(f"after flatten\t\t: {x.shape}")

        x = self.dropout(x)
        print(f"after dropout\t\t: {x.shape}")

        x = self.fc(x)
        print(f"after fc\t\t: {x.shape}")

        return x
Despite being quite long, I think the above code is pretty straightforward since what we basically do here is just to place the blocks according to the given architectural details. However, I really want you to pay attention to the number of block repeats within a single stage (n) as well as whether or not the first block in a stage performs downsampling (s). This is because the architecture doesn’t seem to follow a specific pattern. There is a case where the block is repeated four times, there are other cases where the repeats is done two or three times, and there is even a stage that consists of a single block only. Not only that, it is also unclear under what conditions authors decided to use stride 1 or 2 for the first block in the stage. However, I believe that this final architecture was obtained based on their internal design iterations and experiments that are not discussed in the paper.
Going back to the code, after the stages have been initialized, what we need to do next is to initialize the remaining layers, namely an average pooling layer (#(1)), a dropout layer (#(2)) and a linear layer (#(3)) for the classification head. If you go back to the architectural details, you will notice that the final layer should be a pointwise convolution, not a linear layer like this. In fact, in the case when the spatial dimension of the input tensor is 1×1, a pointwise convolution and a linear layer are equivalent. So, it’s basically fine to use either one.
To ensure our MobileNetV2 is working properly, we can run the Codeblock 11 below. Here we can see that this class instance runs without any errors. More importantly, the output shape also matches exactly with the architecture specified in the paper. This confirms that our implementation is correct, and thus ready for training — just don’t forget to adjust the output size of the final layer to match the number of classes in your dataset.
python
# Codeblock 11
mobilenetv2 = MobileNetV2()
x = torch.randn(BATCH_SIZE, IN_CHANNELS, IMAGE_SIZE, IMAGE_SIZE)

out = mobilenetv2(x)
http
# Codeblock 11 Output
after first_conv       : torch.Size([1, 32, 112, 112])
after inv_residual1    : torch.Size([1, 16, 112, 112])
after inv_residual1 #0 : torch.Size([1, 24, 56, 56])
after inv_residual1 #1 : torch.Size([1, 24, 56, 56])
after inv_residual2 #0 : torch.Size([1, 32, 28, 28])
after inv_residual2 #1 : torch.Size([1, 32, 28, 28])
after inv_residual2 #2 : torch.Size([1, 32, 28, 28])
after inv_residual3 #0 : torch.Size([1, 64, 14, 14])
after inv_residual3 #1 : torch.Size([1, 64, 14, 14])
after inv_residual3 #2 : torch.Size([1, 64, 14, 14])
after inv_residual3 #3 : torch.Size([1, 64, 14, 14])
after inv_residual4 #0 : torch.Size([1, 96, 14, 14])
after inv_residual4 #1 : torch.Size([1, 96, 14, 14])
after inv_residual4 #2 : torch.Size([1, 96, 14, 14])
after inv_residual5 #0 : torch.Size([1, 160, 7, 7])
after inv_residual5 #1 : torch.Size([1, 160, 7, 7])
after inv_residual5 #2 : torch.Size([1, 160, 7, 7])
after inv_residual6    : torch.Size([1, 320, 7, 7])
after last_conv        : torch.Size([1, 1280, 7, 7])
after avgpool          : torch.Size([1, 1280, 1, 1])
after flatten          : torch.Size([1, 1280])
after dropout          : torch.Size([1, 1280])
after fc               : torch.Size([1, 1000])
Alternatively, it is also possible to test our MobileNetV2 model using the summary() function from torchinfo, which will also show us the number of parameters contained within each layer. If you scroll down all the way to the end of the output, you’ll see that this model with default width multiplier has 3,505,960 trainable params. This number is different from the one disclosed in the paper, where according to Figure 7 it should be 3.4 million. However, if we go to the official PyTorch documentation [7], it says that the parameter count of this model is 3,504,872, which is very close to our implementation. Let me know in the comments if you know which parts of the code I should change to make this number match exactly with the one from PyTorch.
python
# Codeblock 12
mobilenetv2 = MobileNetV2()
summary(mobilenetv2, input_size=(BATCH_SIZE, IN_CHANNELS, IMAGE_SIZE, IMAGE_SIZE))
http
# Codeblock 12 Output
==========================================================================================
Layer (type:depth-idx) Output Shape Param #
==========================================================================================
MobileNetV2 [1, 1000] --
├─Conv: 1-1 [1, 32, 112, 112] --
│ └─Conv2d: 2-1 [1, 32, 112, 112] 864
│ └─BatchNorm2d: 2-2 [1, 32, 112, 112] 64
│ └─ReLU6: 2-3 [1, 32, 112, 112] --
├─InvResidualS1: 1-2 [1, 16, 112, 112] --
│ └─Conv2d: 2-4 [1, 32, 112, 112] 1,024
│ └─BatchNorm2d: 2-5 [1, 32, 112, 112] 64
│ └─ReLU6: 2-6 [1, 32, 112, 112] --
│ └─Conv2d: 2-7 [1, 32, 112, 112] 288
│ └─BatchNorm2d: 2-8 [1, 32, 112, 112] 64
│ └─ReLU6: 2-9 [1, 32, 112, 112] --
│ └─Conv2d: 2-10 [1, 16, 112, 112] 512
│ └─BatchNorm2d: 2-11 [1, 16, 112, 112] 32
├─ModuleList: 1-3 -- --
│ └─InvResidualS2: 2-12 [1, 24, 56, 56] --
│ │ └─Conv2d: 3-1 [1, 96, 112, 112] 1,536
│ │ └─BatchNorm2d: 3-2 [1, 96, 112, 112] 192
│ │ └─ReLU6: 3-3 [1, 96, 112, 112] --
│ │ └─Conv2d: 3-4 [1, 96, 56, 56] 864
│ │ └─BatchNorm2d: 3-5 [1, 96, 56, 56] 192
│ │ └─ReLU6: 3-6 [1, 96, 56, 56] --
│ │ └─Conv2d: 3-7 [1, 24, 56, 56] 2,304
│ │ └─BatchNorm2d: 3-8 [1, 24, 56, 56] 48
│ └─InvResidualS1: 2-13 [1, 24, 56, 56] --
│ │ └─Conv2d: 3-9 [1, 144, 56, 56] 3,456
│ │ └─BatchNorm2d: 3-10 [1, 144, 56, 56] 288
│ │ └─ReLU6: 3-11 [1, 144, 56, 56] --
│ │ └─Conv2d: 3-12 [1, 144, 56, 56] 1,296
│ │ └─BatchNorm2d: 3-13 [1, 144, 56, 56] 288
│ │ └─ReLU6: 3-14 [1, 144, 56, 56] --
│ │ └─Conv2d: 3-15 [1, 24, 56, 56] 3,456
│ │ └─BatchNorm2d: 3-16 [1, 24, 56, 56] 48
├─ModuleList: 1-4 -- --
│ └─InvResidualS2: 2-14 [1, 32, 28, 28] --
│ │ └─Conv2d: 3-17 [1, 144, 56, 56] 3,456
│ │ └─BatchNorm2d: 3-18 [1, 144, 56, 56] 288
│ │ └─ReLU6: 3-19 [1, 144, 56, 56] --
│ │ └─Conv2d: 3-20 [1, 144, 28, 28] 1,296
│ │ └─BatchNorm2d: 3-21 [1, 144, 28, 28] 288
│ │ └─ReLU6: 3-22 [1, 144, 28, 28] --
│ │ └─Conv2d: 3-23 [1, 32, 28, 28] 4,608
│ │ └─BatchNorm2d: 3-24 [1, 32, 28, 28] 64
│ └─InvResidualS1: 2-15 [1, 32, 28, 28] --
│ │ └─Conv2d: 3-25 [1, 192, 28, 28] 6,144
│ │ └─BatchNorm2d: 3-26 [1, 192, 28, 28] 384
│ │ └─ReLU6: 3-27 [1, 192, 28, 28] --
│ │ └─Conv2d: 3-28 [1, 192, 28, 28] 1,728
│ │ └─BatchNorm2d: 3-29 [1, 192, 28, 28] 384
│ │ └─ReLU6: 3-30 [1, 192, 28, 28] --
│ │ └─Conv2d: 3-31 [1, 32, 28, 28] 6,144
│ │ └─BatchNorm2d: 3-32 [1, 32, 28, 28] 64
│ └─InvResidualS1: 2-16 [1, 32, 28, 28] --
│ │ └─Conv2d: 3-33 [1, 192, 28, 28] 6,144
│ │ └─BatchNorm2d: 3-34 [1, 192, 28, 28] 384
│ │ └─ReLU6: 3-35 [1, 192, 28, 28] --
│ │ └─Conv2d: 3-36 [1, 192, 28, 28] 1,728
│ │ └─BatchNorm2d: 3-37 [1, 192, 28, 28] 384
│ │ └─ReLU6: 3-38 [1, 192, 28, 28] --
│ │ └─Conv2d: 3-39 [1, 32, 28, 28] 6,144
│ │ └─BatchNorm2d: 3-40 [1, 32, 28, 28] 64
├─ModuleList: 1-5 -- --
│ └─InvResidualS2: 2-17 [1, 64, 14, 14] --
│ │ └─Conv2d: 3-41 [1, 192, 28, 28] 6,144
│ │ └─BatchNorm2d: 3-42 [1, 192, 28, 28] 384
│ │ └─ReLU6: 3-43 [1, 192, 28, 28] --
│ │ └─Conv2d: 3-44 [1, 192, 14, 14] 1,728
│ │ └─BatchNorm2d: 3-45 [1, 192, 14, 14] 384
│ │ └─ReLU6: 3-46 [1, 192, 14, 14] --
│ │ └─Conv2d: 3-47 [1, 64, 14, 14] 12,288
│ │ └─BatchNorm2d: 3-48 [1, 64, 14, 14] 128
│ └─InvResidualS1: 2-18 [1, 64, 14, 14] --
│ │ └─Conv2d: 3-49 [1, 384, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-50 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-51 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-52 [1, 384, 14, 14] 3,456
│ │ └─BatchNorm2d: 3-53 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-54 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-55 [1, 64, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-56 [1, 64, 14, 14] 128
│ └─InvResidualS1: 2-19 [1, 64, 14, 14] --
│ │ └─Conv2d: 3-57 [1, 384, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-58 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-59 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-60 [1, 384, 14, 14] 3,456
│ │ └─BatchNorm2d: 3-61 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-62 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-63 [1, 64, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-64 [1, 64, 14, 14] 128
│ └─InvResidualS1: 2-20 [1, 64, 14, 14] --
│ │ └─Conv2d: 3-65 [1, 384, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-66 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-67 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-68 [1, 384, 14, 14] 3,456
│ │ └─BatchNorm2d: 3-69 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-70 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-71 [1, 64, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-72 [1, 64, 14, 14] 128
├─ModuleList: 1-6 -- --
│ └─InvResidualS1: 2-21 [1, 96, 14, 14] --
│ │ └─Conv2d: 3-73 [1, 384, 14, 14] 24,576
│ │ └─BatchNorm2d: 3-74 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-75 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-76 [1, 384, 14, 14] 3,456
│ │ └─BatchNorm2d: 3-77 [1, 384, 14, 14] 768
│ │ └─ReLU6: 3-78 [1, 384, 14, 14] --
│ │ └─Conv2d: 3-79 [1, 96, 14, 14] 36,864
│ │ └─BatchNorm2d: 3-80 [1, 96, 14, 14] 192
│ └─InvResidualS1: 2-22 [1, 96, 14, 14] --
│ │ └─Conv2d: 3-81 [1, 576, 14, 14] 55,296
│ │ └─BatchNorm2d: 3-82 [1, 576, 14, 14] 1,152
│ │ └─ReLU6: 3-83 [1, 576, 14, 14] --
│ │ └─Conv2d: 3-84 [1, 576, 14, 14] 5,184
│ │ └─BatchNorm2d: 3-85 [1, 576, 14, 14] 1,152
│ │ └─ReLU6: 3-86 [1, 576, 14, 14] --
│ │ └─Conv2d: 3-87 [1, 96, 14, 14] 55,296
│ │ └─BatchNorm2d: 3-88 [1, 96, 14, 14] 192
│ └─InvResidualS1: 2-23 [1, 96, 14, 14] --
│ │ └─Conv2d: 3-89 [1, 576, 14, 14] 55,296
│ │ └─BatchNorm2d: 3-90 [1, 576, 14, 14] 1,152
│ │ └─ReLU6: 3-91 [1, 576, 14, 14] --
│ │ └─Conv2d: 3-92 [1, 576, 14, 14] 5,184
│ │ └─BatchNorm2d: 3-93 [1, 576, 14, 14] 1,152
│ │ └─ReLU6: 3-94 [1, 576, 14, 14] --
│ │ └─Conv2d: 3-95 [1, 96, 14, 14] 55,296
│ │ └─BatchNorm2d: 3-96 [1, 96, 14, 14] 192
├─ModuleList: 1-7 -- --
│ └─InvResidualS2: 2-24 [1, 160, 7, 7] --
│ │ └─Conv2d: 3-97 [1, 576, 14, 14] 55,296
│ │ └─BatchNorm2d: 3-98 [1, 576, 14, 14] 1,152
│ │ └─ReLU6: 3-99 [1, 576, 14, 14] --
│ │ └─Conv2d: 3-100 [1, 576, 7, 7] 5,184
│ │ └─BatchNorm2d: 3-101 [1, 576, 7, 7] 1,152
│ │ └─ReLU6: 3-102 [1, 576, 7, 7] --
│ │ └─Conv2d: 3-103 [1, 160, 7, 7] 92,160
│ │ └─BatchNorm2d: 3-104 [1, 160, 7, 7] 320
│ └─InvResidualS1: 2-25 [1, 160, 7, 7] --
│ │ └─Conv2d: 3-105 [1, 960, 7, 7] 153,600
│ │ └─BatchNorm2d: 3-106 [1, 960, 7, 7] 1,920
│ │ └─ReLU6: 3-107 [1, 960, 7, 7] --
│ │ └─Conv2d: 3-108 [1, 960, 7, 7] 8,640
│ │ └─BatchNorm2d: 3-109 [1, 960, 7, 7] 1,920
│ │ └─ReLU6: 3-110 [1, 960, 7, 7] --
│ │ └─Conv2d: 3-111 [1, 160, 7, 7] 153,600
│ │ └─BatchNorm2d: 3-112 [1, 160, 7, 7] 320
│ └─InvResidualS1: 2-26 [1, 160, 7, 7] --
│ │ └─Conv2d: 3-113 [1, 960, 7, 7] 153,600
│ │ └─BatchNorm2d: 3-114 [1, 960, 7, 7] 1,920
│ │ └─ReLU6: 3-115 [1, 960, 7, 7] --
│ │ └─Conv2d: 3-116 [1, 960, 7, 7] 8,640
│ │ └─BatchNorm2d: 3-117 [1, 960, 7, 7] 1,920
│ │ └─ReLU6: 3-118 [1, 960, 7, 7] --
│ │ └─Conv2d: 3-119 [1, 160, 7, 7] 153,600
│ │ └─BatchNorm2d: 3-120 [1, 160, 7, 7] 320
├─InvResidualS1: 1-8 [1, 320, 7, 7] --
│ └─Conv2d: 2-27 [1, 960, 7, 7] 153,600
│ └─BatchNorm2d: 2-28 [1, 960, 7, 7] 1,920
│ └─ReLU6: 2-29 [1, 960, 7, 7] --
│ └─Conv2d: 2-30 [1, 960, 7, 7] 8,640
│ └─BatchNorm2d: 2-31 [1, 960, 7, 7] 1,920
│ └─ReLU6: 2-32 [1, 960, 7, 7] --
│ └─Conv2d: 2-33 [1, 320, 7, 7] 307,200
│ └─BatchNorm2d: 2-34 [1, 320, 7, 7] 640
├─Conv: 1-9 [1, 1280, 7, 7] --
│ └─Conv2d: 2-35 [1, 1280, 7, 7] 409,600
│ └─BatchNorm2d: 2-36 [1, 1280, 7, 7] 2,560
│ └─ReLU6: 2-37 [1, 1280, 7, 7] --
├─AdaptiveAvgPool2d: 1-10 [1, 1280, 1, 1] --
├─Dropout: 1-11 [1, 1280] --
├─Linear: 1-12 [1, 1000] 1,281,000
==========================================================================================
Total params: 3,505,960
Trainable params: 3,505,960
Non-trainable params: 0
Total mult-adds (Units.MEGABYTES): 313.65
==========================================================================================
Input size (MB): 0.60
Forward/backward pass size (MB): 113.28
Params size (MB): 14.02
Estimated Total Size (MB): 127.91
==========================================================================================
···
Ending
And that’s pretty much everything about MobileNetV2. I do encourage you to explore this architecture on your own — at least by actually training it on an image classification dataset. Don’t forget to play around with the width multiplier and the input resolution parameters to find the right balance between prediction accuracy and computational efficiency. You can also find the code used in this article in my GitHub repository [8] by the way.
I hope you learned something new today. Thanks for reading!
···
References
[1] Muhammad Ardi. MobileNetV1 Paper Walkthrough: The Tiny Giant. Towards Data Science. https://towardsdatascience.com/the-tiny-giant-mobilenetv1/ [Accessed September 25, 2025].
[2] Andrew G. Howard et al. MobileNets: Efficient Convolutional Neural Networks for Mobile Vision Applications. Arxiv. https://arxiv.org/abs/1704.04861 [Accessed April 7, 2025].
[3] Mark Sandler et al. MobileNetV2: Inverted Residuals and Linear Bottlenecks. Arxiv. https://arxiv.org/abs/1801.04381 [Accessed April 12, 2025].
[4] Kaiming He et al. Deep Residual Learning for Image Recognition. Arxiv. https://arxiv.org/abs/1512.03385 [Accessed April 12, 2025].
[5] Zhuang Liu et al. A ConvNet for the 2020s. Arxiv. https://arxiv.org/abs/2201.03545 [Accessed April 12, 2025].
[6] Image created originally by author.
[7] mobilenet_v2. PyTorch. https://pytorch.org/vision/main/models/generated/torchvision.models.mobilenet_v2.html#mobilenet-v2 [Accessed April 12, 2025].
[8] MuhammadArdiPutra. The Smarter Tiny Giant — MobileNetV2. GitHub. medium_articles/The Smarter Tiny Giant — MobileNetV2.ipynb at main · MuhammadArdiPutra/medium_articles [Accessed April 12, 2025].
Register Now to Continue Reading
Unlock Towards Data Science with a Free Account
All articles on Towards Data Science are available to registered users. Create a free account today to access this article and thousands more.
Register for freeSign in to your account
 Written By
Deep learning storyteller
See all from Muhammad Ardi Putra
Deep DivesArtificial IntelligenceComputer VisionMachine LearningNeural Network
Share This Article
Towards Data Science is a community publication. Submit your insights to reach our global audience and earn through the TDS Author Payment Program.
Write for TDS
Related Articles
Artificial Intelligence
A step-by-step code and intuition guide to generating album covers.
Alex Lin
July 30, 20216 min read
Artificial Intelligence
Data, creativity, and tactic will make you climb the leaderboard
Pranay Dave
June 9, 20226 min read
Artificial Intelligence
Explore the practices with implementation codes for sustainably mitigating the cost of speedy delivery
John Leung
September 26, 202310 min read
Deep Learning
I will take a closer look at the differences in the obtained representations between CNN and Transformers
Akihiro FUJII
October 9, 202116 min read
Deep Learning
Serving large neural networks can be expensive.
Ziheng Wang
September 8, 20205 min read
Deep Learning
Theory and Code
Alexey Kravets
February 21, 20224 min read
Deep Learning
The purpose of this guide is to explore PyTorch Image Models (timm) from a practitioner's point of view, for use in custom scripts.
Chris Hughes
February 1, 202240 min read
Data Science
Using OpenCV to Detect the Foreground
Andrew Udell
February 23, 20218 min read
Artificial Intelligence
Identify the evidence to mine the legal reasoning
Vern Walker
January 19, 20228 min read
Your home for data science and AI. The world's leading publication for data science, data analytics, data engineering, machine learning, and artificial intelligence professionals.
Subscribe to Our NewsletterWrite For TDS•About•Advertise•Privacy Policy•Terms of Use
© Insight Media Group, LLC 2026•The New Stack•roadmap.sh•Creator Network
Recommended Articles
Close