I want to get back into writing more regularly this year, so in light of that, here’s my last year in review.
Evaluating LLMs
Like many of us in tech, I spent a large portion of 2024 thinking about and working with LLMs, but I was lucky enough to do it for work. I spent the year designing, building, open-sourcing, (and naming! 🐊) an application to evaluate LLMs, Lumigator.
In support of that work, I did open-source work in the LLM ecosystemand learned a ton of stuff along the way. Just when I thought I had reached machine learning enlightenment, I learned a ton about the weird nondeterministic properties of LLMs, their evaluation methods, Ray + Ray Serve, vLLM, Llamafile, GGUF, FastAPI, OpenAPI-compatible APIs, and much, much, much more. I am hoping to translate some of these into blog posts as well.
There is always more to learn in machine learning, particularly in the fast-moving world at the bleeding edge. Lucikly, the fundamentals always remain the same.
My biggest takeaways from this year are that:
- Machine learning in industry is mostly still made up of good engineering, and in order to work with LLMs, you need to have both machine learning context and engineering discipline. There’s some debate whether the “old” machine learning skills (gradient boosted trees anyone? 👵) still apply in this Brave New World of NonTabular Scraped Internet, and I am of the opinion that these skills are more valuable than ever, particularly as engineers without ML context enter the frustrating world of building with non-deterministic experimental loops.
But what’s even more valuable is being able to ship things that hold engineering rigor. Even if you are deep in academic research, taking an engineering approach will make your life significantly easier.
As part of this, I spent a significant amount of the year widening my own context window about engineering best practices: Over the summer, I learned C and this fall, I learned JavaScript and Go and built my first working project, Gitfeed. I am particularly enamored with Go: it’s so boring, so clean, and so easy to build things that are simple and move quickly out of the box compared to the Python ecosystem.
This is not to say that the Python world, which is my first love, is not changing and evolving. I moved to uv from pyenv for both work and personal projects in 2024 and have never looked back, particularly as uv continues to work to gain support for PyTorch and all of its cuda-related install issues.
- There is too much going on in the model landscape: too many models, too much choice, too many platforms, too much money, too much drama. My main strategy is to follow what’s going on on a daily basis to keep my finger on the pulse and then basically ignore it. If people mention it again over the course of 2-3 months, continue to pay attention.
In light of this, some contradictary advice if you’re in the space is that you should also always be playing around with stuff, trying it out, building it and breakign it. There are some classic papers and books for understanding the context and theory, but most of the stuff I read is still in r/LocalLLaMA or in various tweets/skeets and blog posts. We are not at the level yet for this stuff where cannon exists, although I have noticed that there are technical books being published about AI engineering this year, which means we are starting to solidify.
Some LLM tools I tried out and loved this year were llamafile, for getting started with GGUF transformer and embedding models with a server extremely quickly, and ollama + openwebui for an experience that is nearly identical to using Claude. In fact, I’ve switched over from Claude to using mistral:latest locally for most of my LLM usage, which is basically code search. Mistral is a model that has consistently worked well for me both at work and for my own purposes, and I’ve enjoyed the chance to pit it against newer models like Qwen2.5 Coder, Llama2, and phi.
I am still having a hard time wrapping my mind around what LLM models are useful for, in general, and for me personally. I spend a lot of time reading blog posts about how other (smarter) people use LLMS and against academic papers that study the success of these models at machin learning tasks stemming in their roots as NLP models focusing on problems like text completion, classification, translation, and summarization.
A very cool and fun related thing I did while reviewing the “classics” was edit this wonderful series of posts by Katharine about model memorization which you should read if you’re interested in their internals.
- I also spent a significant part of the year working on web development. I wrote earlier in the year that there is a bifurcation in how we consume LLMs:
The LLM ecosystem is currently bifurcated between HuggingFace and OpenAI compatibility: An interesting pattern has developed in my development work on open-source in LLMs. It’s become clear to me that, in this new space of developer tooling around transformer-style language models at an industrial scale, you are generally conforming to be downstream of one of two interfaces: models that are trained and hosted using HuggingFace libraries and particularly the HuggingFace hub as infrastructure - in practicality, this means dependence on PyTorch’s programming paradigm, which HuggingFace tools wrap (although they now also provide interop between Tensorflow and JAX)
Models that are available via API endpoints, particularly as hosted by OpenAI. Given that OpenAI was a first mover in the product LLM space, they currently have the API advantage, and many tools that have developed have developed OpenAI-compatible endpoints which don’t always mean using OpenAI, but conform to the same set of patterns that the Chat Completions API v1/chat/completions offers. For example, adding OpenAI-style interop chat completions allowed us to stand up our own vLLM OpenAI-compatible server that works against models we’ve started with on HuggingFace and fine-tuned locally.
If you want to be successful in this space today and you’d like to cater to a broad audience, you as a library or service provider have to be able to interface with both of these.
I still believe this is true and it will be interesting to see how this develops over the course of the next year as APIs and their model ecosystems become even broader.
- These models will integrate with, not replace traditional machine learning systems. In the beginning, everyone thought that we could replace whole classes of engineering and machine learning problems with LLMs. It’s becoming increasingly clearer that one big-ass model is not as a good as many smaller models for specific tasks performed in industry, which makes complete sense because LLMs as a concept rose out of academic labs whose goals are to generalize on out-of-sample problems, whereas the task of industry is to specialize in healthcare or OCR document scanning for legal, or sentiment analysis for social media. Even if fine-tuning did decline as a practice this year, people are making models specialized in a lot of deifferent ways, which I think the rise of agents at the end of this year really makes clear.
An area that has particularly interested me is the integration of LLMs into recommender systems, my favorite area of applied machine learning. Earlier last year, I, along with James and Ravi, started a position paper on what will change in recommender systems in the light of LLMs based on a joke tweet I had made,
personalized recommendations based on implicit matrix factorization from data acquired through large log streaming architectures were a low interest rate phenomenon
My hypothesis was that companies used to collect a lot of streaming user data, particularly in social and other B2C settings, that were then used for personalization. Now, all the data collection happens publicly at the level of the interet, where it is re-compressed into LLMs. What does this mean for personalization, now?
Unfortunately we didn’t finish the post (maybe someday?), but our main hypothesis was that traditional recsys will not be replaced with, but instead augmented with LLMs, that LLMs could help fill the cold-start gap because they’re so good at zero-shot retrieval and general topic classification and can serve as places to augment cold-start problems and in onboarding, and that LLMs could offer more explainability in recommendations. This has so far proven to be true.
Italy + Learning Italian
I had the extreme pleasure of being invited to give a keynote at PyCon Italia in Florence in May. I took all these learnings that had been running on crazed hamster wheels in my brain and threw them into a talk based loosely on the Decameron.
In addition to subjecting my poor audience to jokes about the Medicis, I also gave the intro in Italian to an audience of +100, which was extremely nervewracking. I’ve been wanting to study Italian since I was 18 and the stars aligned two years ago for me to seriously start. and I’ve been learning ever singe. This year, I also managed to read my first (Level A1/A2) books in Italian.
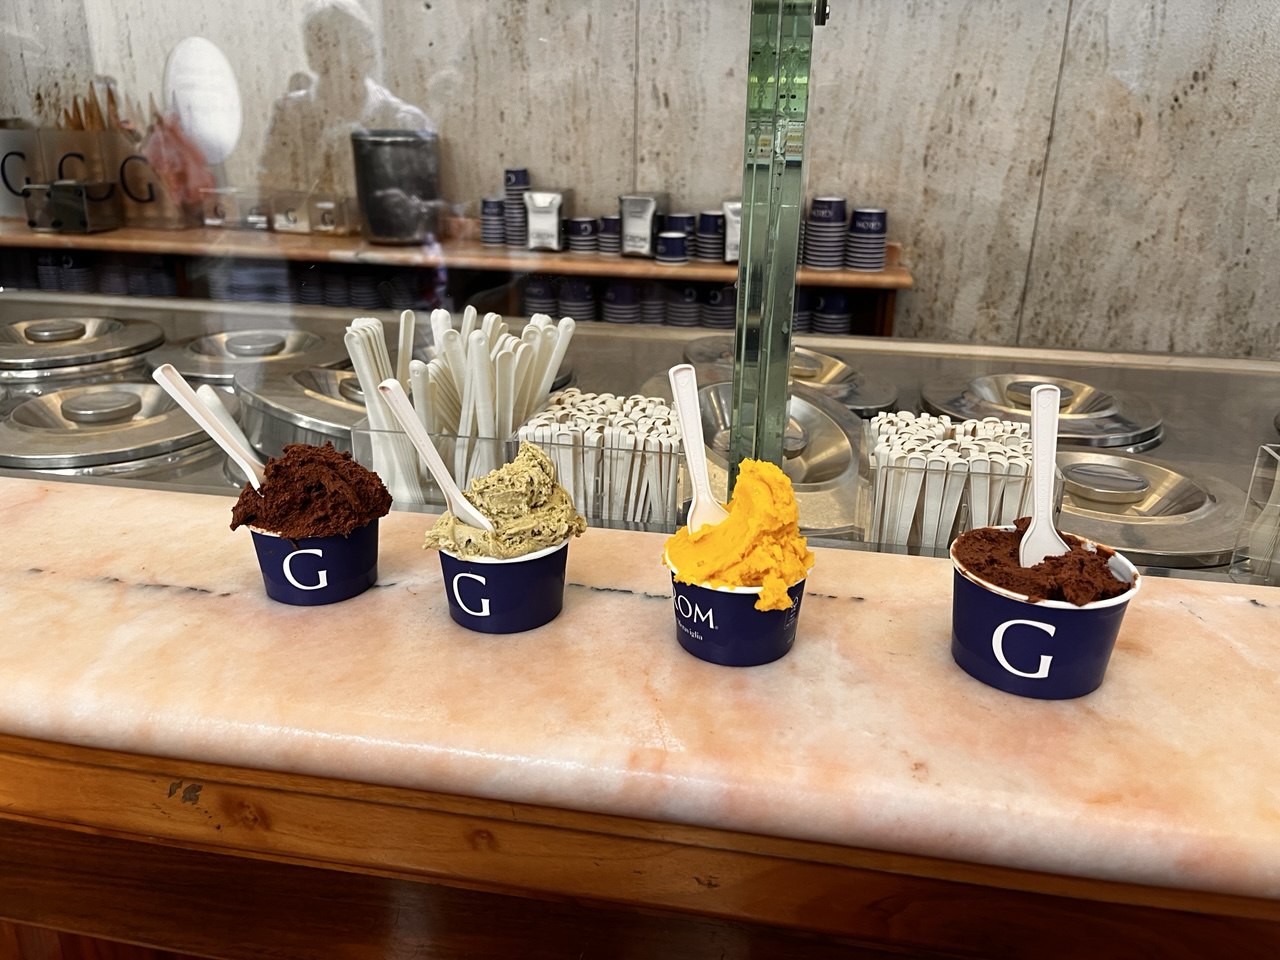
My family also came to Italy. It was the kids’ first trip to Europe. Everyone had an amazing time (at least after my talk was over), ate a lot of gelato, and experienced Rome and Florence in the spring. One of my favorite moments of the trip (and of my year) was listening to a Ricchi e Poveri cover band playing at a disco outside our hotel at 11:30 at night in Florence.
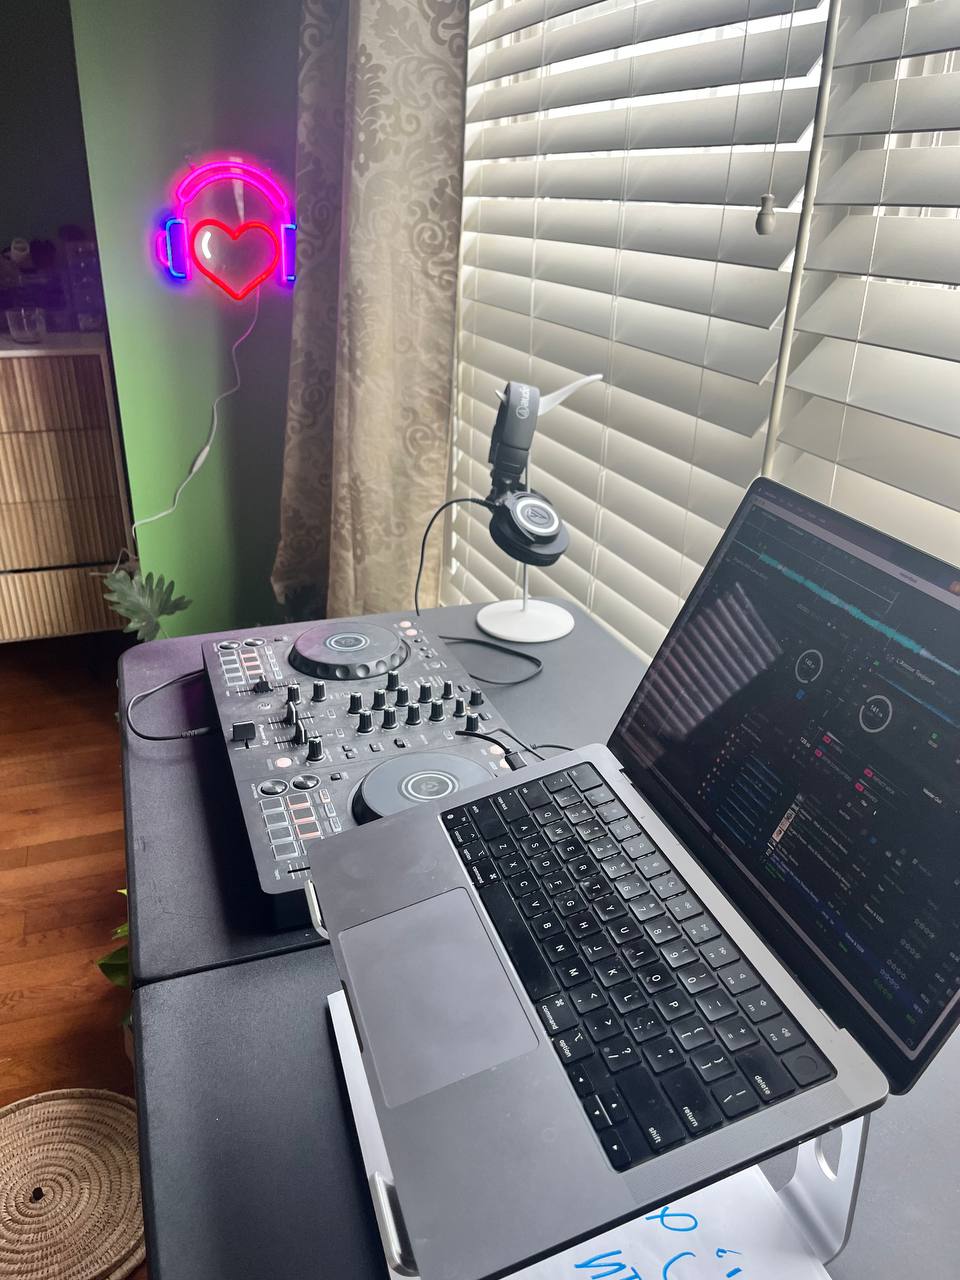
Inspired by all of this, and to take a break from LLMs, I also started learning how to mix music, and hopefully will have something more concrete to write/share about DJing this year.
I also managed to read some books.
Shift in Social Strategy
As I spent the year trying my best to keep up with the wild, unruly, and growing LLM landscape, another part of my ecosystem was wilting. It’s clear for all intents and purposes that Twitter as we knew her is dead. It doesn’t have the juice anymore, as the kids say. I’m surprised that it died from human intervention rather than engineering failure, but as anyone who’s read my newsletter knows, this is by far the most likely outcome for techno-social systems. I have been wanting to write a long eulogy on my personal experinece and what Twitter meant to me: it was a place where I made friends, learned to be a serious programmer, worked out my best ideas, got leads for jobs, started a newsletter, organized Normconf, and most importantly, had fun. But in the end, it all died with a whimper, and I, like many others, just quietly left.
I’ve always been a firm believer in owning your own internet space, and I continued to do that by blogging, and moving from Substack to Buttondown, but I also need micro social interaction because I get energy and ideas from it. So, I engaged more on Bluesky, where I’ve been since last year, and was pleasantly surprised to see the machine learning community start to migrate there. Amost immediately as soon as I came back to the platform, I had a conversation that led to an idea for a post.
A lot of people have (rightfully so) sworn off agglomerated social in favor of group chats. This makes complete sense to me, yet as a creator and someone who thrives on community, I was sorely missing this space until I came back to Bluesky. There is a lot of conversation around protocol versus platform and what it means for Bluesky the app versus Bluesky the protocol to succeed.
In particular, I encourage anyone interested in the space to read this series of exchanges on the question but I remain hopeful that that space grows and remains a place where users can choose and experiment. It allowed me, at the end of the year, to hack on gitfeed, which is very, very very cool.
2025
What next? Who knows, who can even predict the future? Not machine learning models, and certainly not me. I’m just excited to keep learning and building and making and dreaming, and, hopefully writing more about it all.